mirror of
https://github.com/unslothai/unsloth.git
synced 2026-10-23 23:11:17 +00:00
192 commits
| Author | SHA1 | Message | Date | |
|---|---|---|---|---|
 Daniel Han |
d33e77e540
|
Studio setup: keep the extension-free mamba-ssm in the stale kernel check (#14687)
Studio's Triton route for Mamba-2 hybrids installs the extension-free mamba_ssm wheel (no `selective_scan_cuda`). Setup's `_remove_stale_ssm_kernels` probes `import selective_scan_cuda`, reads the missing module as a build for another torch, and uninstalls mamba_ssm on every install or `unsloth studio update`, printing `mamba_ssm does not load with this torch; removed it`. Online the next load downloads it again; offline, Nemotron-H / Falcon-H1 / Granite-4.0-H / Bamba / Zamba2 / Mamba2 loads then drop to the slower torch path. ## Changes For mamba_ssm only, the probe exits 0 when `selective_scan_cuda` does not exist at all: nothing in that install was built against torch, and the runtime already accepts that layout (`ssm_runtime.py`, `MAMBA_SSM_EXTENSION`). causal-conv1d has no extension-free wheel, so a missing `causal_conv1d_cuda` is still broken, and a compiled module that is present and fails to import is still removed. ## Tests `tests/python/test_ssm_kernels_install_python_stack.py`: - `test_the_probe_passes_an_extension_free_mamba_ssm_only` runs the real probe in a subprocess: a missing `selective_scan_cuda` exits 0, a missing `causal_conv1d_cuda` exits 87, and a `selective_scan_cuda` raising ImportError exits 87. - `test_setup_keeps_the_extension_free_mamba_ssm` runs `_remove_stale_ssm_kernels` with mamba-ssm installed and no `selective_scan_cuda`; nothing is uninstalled. Both fail on main and pass here (20 passed). |
||
|
Daniel Han
|
a47bcbb081
|
Studio and Core: certifi 2026.10.19 and pip 26.2.2 floors (drop the compromised emSign root) (#14887)
The eMudhra/emSign intermediates were issued with trivially weak private keys (https://discuss.python.org/t/information-for-python-users-regarding-emudhra-emsign-ca-certificate-security-incident/109576, https://emudhra.we-have-a-problem.com/), so anyone can mint a certificate that chains to the emSign ECC Root CA - G3. certifi 2026.10.19 drops that root, and pip 26.2.2 ships it as its vendored bundle (pip always verifies with its own copy, whatever the environment's certifi or `REQUESTS_CA_BUNDLE` say). Studio's torch installs leave certifi to the resolver, and the update path skips a pip it considers usable (major 23 or newer), so an existing install keeps whatever certifi and pip it had. Core (`pip install unsloth`) declares no certifi floor at all. truststore, which Studio injects on macOS, Windows and the Linux desktop, adds the OS anchors to certifi's rather than replacing them, so an old certifi stays exploitable there too. **Change.** - `studio/install_python_stack.py`: one trust-floor step right after the pip bootstrap, outside every skip path, so it runs on setup, update and repair in torch and no-torch mode. It installs only the floors the venv does not meet (`certifi>=2026.10.19`, plus `pip>=26.2.2` on Python 3.10+), through the existing installer helper. A satisfied venv runs nothing; nothing is ever downgraded; offline it warns and carries on. No new step line (the helper prints its label only in verbose mode). `_venv_pip_is_usable` treats a pip below 26.2.2 as stale on 3.10+, so the existing bootstrap upgrades it. - `pyproject.toml`: `certifi>=2026.10.19` in the base dependencies, so `pip install -U unsloth` (Colab, Kaggle, notebooks) upgrades certifi in place. - `docker/Dockerfile`, `docker/Dockerfile.rocm`: `pip>=26.2.2`, `uv>=0.13.4`, `certifi>=2026.10.19` floors on the venv bootstrap lines (takes effect on the next image build). - `no-torch-runtime.txt`: comment only; its `certifi==2026.10.19` pin is unchanged. **Before / after.** `requests` against the disclosure's test hosts: | host | certifi 2026.7.22 | certifi 2026.10.19 | |---|---|---| | pypi.org | HTTP 200 | HTTP 200 | | dv-g3b-emudhra.we-have-a-problem.com | HTTP 200 (accepted) | rejected | | dv-g3b-noct-emudhra.we-have-a-problem.com | HTTP 200 (accepted) | rejected | pip against `--index-url https://dv-g3b-emudhra.we-have-a-problem.com/simple/`: pip 24.0 gets past TLS to the page, pip 26.2.2 with its vendored bundle fails with `CERTIFICATE_VERIFY_FAILED`. The new step on a real venv (Python 3.12, against the live index): | point | certifi | pip | installs | |---|---|---|---| | before | 2026.7.22 | 24.3.1 | | | base run | 2026.7.22 | 24.3.1 | step absent | | head run 1 | 2026.10.19 | 26.2.2 | 1 | | head run 2 | 2026.10.19 | 26.2.2 | 0, no subprocess | **Testing.** New `tests/studio/install/test_ca_trust_floor.py` (spec selection per installed version and Python, satisfied venv runs nothing, offline warns, a full `install_python_stack()` run in torch / no-torch and with / without an installer handoff issues the floor install before the first `-r` install, the pyproject and no-torch floors). `test_dependency_pass_skips.py` updated for the 26.2.2 pip floor. 186 passed. Removing the `_ensure_trust_floor()` call fails the four full-pass cases. Not in this PR: the vLLM/SGLang engine locks still pin `certifi==2026.7.22`. Changing a lock changes its digest, and Studio then refuses to launch an installed engine until the user presses Update in Settings, so that bump is left for the next engine refresh. |
||
|
Daniel Han
|
7ca9ad85c4
|
Format two files merged without the repo formatter in #14834 and #14819 (#14878)
Two files merged at 02:46 UTC without the repo formatter, so pre-commit.ci's `ruff-format-with-kwargs` hook (which runs on all files) will rewrite them on every PR queued after that: - `studio/install_python_stack.py` from #14834 - `studio/backend/tests/test_diffusion_prequant_cache.py` from #14819 Same class as #14817 and #14852. `python scripts/run_ruff_format.py` (the hook's entry point, `ruff==0.6.9`) applied to those two files. Both parse to identical ASTs before and after, `ruff check` passes, and a full run of the hook over every tracked Python file on this branch changes nothing else. |
||
|
Daniel Han
|
3cf161740f
|
Studio updater: install a matched unsloth + unsloth-zoo pair when the index lags (#14834)
The Desktop backend floor in install_python_stack.py only checked that unsloth>=X exists on the index, without checking that the index also has the unsloth-zoo that release requires. When the fallback lowered the floor it returned only an unsloth pin, so the no-torch update (which installs --no-deps) took whatever unsloth-zoo the resolver picked. Effects on a lagging index: - zoo behind the requested unsloth: the default update fails as unsatisfiable, and the no-torch update silently installs unsloth X with an older zoo below its floor - lowered fallback under UV_RESOLUTION=lowest: the no-torch update installs the oldest zoo Changes: - probe the requested floor together with unsloth-zoo, with dependencies, on a fixed linux platform so hosts without torch wheels can still resolve it - otherwise lower to the newest unsloth + unsloth-zoo pair that resolves, and install both pins, matching install.sh / install.ps1 - unchanged when the index has the requested release and its zoo: same single probe, same specs Tests: TestDesktopBackendVersionConstraint now models zoo floors; 5 new cases fail on main and pass here. tests/python/test_install_python_stack.py: 310 passed (305 on main); tests/studio/install unchanged (same 4 failures and 8 collection errors as main). Not run: a real Desktop update on Windows, macOS or an Intel Mac. --------- Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com> |
||
|
Daniel Han
|
1b598dbeb0
|
Studio: cap Pillow below 13 for the MLX image engine (#14802)
## Problem

Pillow 13.0.0 breaks the opt-in MLX image engine (mflux) on every Python
it currently runs on.

- `PIL/_typing.py` in Pillow 13.0.0 does `from numbers import
_IntegralLike as IntegralLike`. CPython 3.11, 3.12, 3.13 and 3.14 have
no `numbers._IntegralLike`, so `import PIL._typing` raises
`ImportError`. `PIL.Image`, `ImageOps` and the other public modules
import it only for type checking, so they still work.
- mflux 0.22.0 imports `from PIL._typing import StrOrBytesPath` in
`mflux/utils/exif_orientation.py` and `mflux/utils/image_util.py`. Every
mflux import goes through one of them, so the engine cannot load.
- The no-torch path pins `pillow==12.3.0` in
`requirements/no-torch-runtime.txt`, but the torch path that macOS uses
(MPS) leaves Pillow unpinned. A fresh Mac install can therefore resolve
13.0.0. Pillow 13 declares `requires-python >=3.11`, so pip will pick it
on Python 3.12.

Checked on CPython 3.12.13, 3.13.12 and 3.14.3 with the Pillow 13.0.0
wheel: `import PIL._typing` fails on all three, and `from PIL import
Image, ImageOps` passes.

## Fix

- `install_python_stack.py`: the MLX engine install adds
`pillow>=12.3.0,<13` to its `--no-deps` set (12.3.0 is mflux's own
floor). `_mlx_diffusion_engine_is_current` already checks every entry in
that list, so an existing install that drifted to Pillow 13 is
reinstalled on the next update.
- `diffusion_engine_router.py`: `_MLX_RUNTIME_REQUIREMENTS` gains the
same range. A Pillow 13 environment now falls back to the diffusers
engine at selection time, with `the MLX engine needs pillow>=12.3.0,<13
(found 13.0.0)` as the fallback reason, rather than failing when the
model loads.

The existing test that keeps the installer list and the router list in
sync covers both edits.

## Tests

- `test_diffusion_mlx_engine_router.py`: new case `{"pillow": "13.0.0"}`
in `test_an_incompatible_installed_runtime_falls_back`.
- `tests/studio/install/test_mlx_install.py`: the engine's package set
now includes `pillow`.
- Result: `tests/studio/install/test_mlx_install.py` and
`test_install_manifest.py` pass, 121 passed. The backend MLX test files
fail on the same 34 test IDs at the merge base as at this head; those
failures come from a dependency (`fastmcp`) missing on this host and are
unrelated to this change.

## Not covered

No real Mac ran this. The change only narrows which versions are
accepted, and the import failure was reproduced with the Linux wheels of
the same Pillow release.
|
||
|
Daniel Han
|
f1f283a24e
|
Installers: do not install generic aarch64 CUDA torch on Jetson before CUDA 13 (#14363)
## Summary On Jetson (Tegra) with JetPack 5 or 6, the aarch64 CUDA wheels on download.pytorch.org and PyPI are SBSA server builds that do not see the GPU, so installs ended with `torch.cuda.is_available() == False` (#4856). The installers now detect Tegra and, below CUDA 13, take the same CPU index a GPU-less host gets, with a warning that explains the CPU-only limit and NVIDIA's JetPack PyTorch route. ## What changes - `install.sh` `get_torch_index_url`: Tegra is detected via `/etc/nv_tegra_release` or `nvidia,tegra` in `/proc/device-tree/compatible` (the convention in `studio/backend/utils/tegra.py`). On Tegra with CUDA below 13, or an unreadable version, the CPU index is selected and NVIDIA's Jetson PyTorch route is printed (https://docs.nvidia.com/deeplearning/frameworks/install-pytorch-jetson-platform/). The cu126 default for an unreadable version is unchanged everywhere else. - `studio/install_python_stack.py` `_detect_cuda_torch_index_family`: the same gate, so `studio update` no longer replaces a Jetson's torch with the SBSA cu126 wheel. A JetPack torch already in the venv is kept. - The CPU wheel note at the end of `install.sh` keeps the Jetson diagnosis (not "No GPU detected" plus AMD guidance) on the same CUDA-below-13 rule, so a Thor on CUDA 13 is not told it is a Jetson CPU case. - The messages say training runs on the CPU, and that a JetPack torch is kept only when it is built for the venv's Python (NVIDIA's own wheels target JetPack's system Python). - Studio's `_expected_cpu_flavor_was_chosen()` treats an automatic cpu record on a Jetson as chosen, so the UI does not offer a GPU repair that would only reinstall cpu. - `UNSLOTH_TORCH_INDEX_URL` / `UNSLOTH_TORCH_INDEX_FAMILY` still win over everything. ## Hosts affected - Jetson Orin / Xavier on JetPack 5 and 6: CPU torch plus a warning, instead of a GPU-blind CUDA wheel. - Unchanged: Jetson Thor (CUDA 13, JetPack 7, SBSA), GH200, GB200, DGX Spark, every x86 host, and every pinned install. ## Tests - `tests/studio/install/test_jetson_tegra_torch_route_4856.py`: extracted `install.sh` functions against a fake host root (release file, device tree, fake nvidia-smi), plus mocked `install_python_stack` family and repair cells. Covers JetPack 5/6, Thor, pins, no GPU, GH200, SBSA aarch64 and x86. 15 cells fail on main, all 43 pass here. - Cells: `install.sh` index 15 (10 identical, 5 Tegra below CUDA 13 changed to cpu); Python family 12 (8 identical, 4 changed); repair 4 (3 identical, 1 changed: no SBSA repair on a Jetson). - Related installer suites (1803 tests) and `tests/sh/test_get_torch_index_url.sh` (109 checks): identical results before and after. --------- Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com> |
||
 oobabooga |
6ba60c0a19
|
Studio: download prebuilt kernel wheels once (#14051)
Addresses the Windows update hang reported on Reddit ([Reddit r/unsloth: "Update install failing"](https://www.reddit.com/r/unsloth/comments/1x7n5jq/update_install_failing/)): it halves the prebuilt-wheel download and shows that the install is still running. A slow connection can still take a while. ## Problem Since #13262, Studio setup on Windows installs a 427 MB prebuilt flash-attn wheel at step `6/17 flash-attn`. Users reported that the step hangs, and one killed it after 30 minutes. Reporters blamed the torchao fallback warning printed just before the step, but that warning is unrelated: it prints on every Windows CUDA install. Our reproduction completed, but slowly and silently. To install a wheel from a URL, uv normally fetches only the wheel's metadata, using HTTP range requests. For GitHub release assets those range requests fail, so uv downloads the whole wheel just to read its metadata, discards it, and downloads it again to install (related: astral-sh/uv#18998). `install_wheel` captures uv's output, so the progress bar shows nothing for the whole 2 x 427 MB. At 256 KiB/s on `windows-latest`, step 6/17 took about 60 minutes ([job](https://github.com/oobabooga/unsloth/actions/runs/38959270916/job/117169940368)). ## Fix - `install_wheel` (`studio/backend/utils/wheel_utils.py`) supplies the wheel's metadata to uv up front, so uv skips the metadata fetch and downloads the wheel once. It writes the package name and version, taken from the wheel filename, into a `uv.toml` (`[[dependency-metadata]]`) in a temp dir, and points uv at it with `--project`. uv still installs from the URL into its own cache, so a later reinstall reuses the cached copy. The user's and system uv configs still apply, and relative paths such as `UV_CACHE_DIR` still resolve against the working directory. - `_ensure_flash_attn` (`studio/install_python_stack.py`) shows that the install is still running. On a terminal the progress bar shows the elapsed time; when output is captured, a `still installing flash-attn (N min)` note is printed each minute. Every caller of `install_wheel` gets the single download: setup, `unsloth install-kernels`, the on-demand causal-conv1d / mamba-ssm installs, and the training worker. ## What the user sees In a terminal, the progress line now counts up in place, once a second, until the install finishes: ``` deps [=======-------------] 6/17 flash-attn 0:03 ``` When output is captured, from the Windows A/B below at 1 MiB/s. The `[ Ns]` prefix is the CI wrapper's elapsed-time stamp. Before, nothing for 21 minutes: ``` [ 18s] deps [======--------------] 6/18 dependency overrides [ 22s] torch 2.13.0+cu130 detected -- installing torchao==0.18.0 from [ 22s] https://download.pytorch.org/whl/cu130 [ 22s] https://download.pytorch.org/whl/cu130 did not serve torchao==0.18.0 -- retrying [ 22s] from the default index; its kernels may be skipped [ 1,289s] deps [=======-------------] 7/18 flash-attn [ 1,289s] deps [========------------] 8/18 Unsloth Studio deps ``` After: ``` [ 16s] deps [======--------------] 6/18 dependency overrides [ 18s] torch 2.13.0+cu130 detected -- installing torchao==0.18.0 from [ 18s] https://download.pytorch.org/whl/cu130 [ 18s] https://download.pytorch.org/whl/cu130 did not serve torchao==0.18.0 -- retrying [ 18s] from the default index; its kernels may be skipped [ 81s] deps [=======-------------] 7/18 flash-attn [ 81s] still installing flash-attn (1 min) [ 141s] still installing flash-attn (2 min) [ 201s] still installing flash-attn (3 min) [...] [ 621s] still installing flash-attn (10 min) [ 644s] deps [========------------] 8/18 Unsloth Studio deps ``` (The update has 18 steps instead of 17 because it adds a base-packages step. Captured output is block-buffered, so the `7/18` line appears with the first note.) ## Behavior boundaries - uv runs as before when a project config would apply from the working directory (`uv.toml`, or `pyproject.toml` with `[tool.uv`), or when `UV_PROJECT` selects a project, because pointing `--project` elsewhere would make uv ignore that config. It also runs as before when `UV_CONFIG_FILE` or `UV_NO_CONFIG` is set, or when the URL has no parseable wheel filename. - The pip fallback is unchanged; pip already downloads once. ## Verification Windows A/B on `windows-latest`: arm A ([run](https://github.com/oobabooga/unsloth/actions/runs/38972789221)) and two copies of arm B ([run](https://github.com/oobabooga/unsloth/actions/runs/38980373037)). Each installs with the public one-liner, then runs `unsloth studio update` twice, with GitHub downloads throttled to 1 MiB/s. Arm B applies this diff first. - Cold update: flash-attn and the Studio uv cache are deleted first, so the update starts like a fresh install. - Warm update: flash-attn is deleted again but the cache is kept, to check that a reinstall still reuses uv's cached copy. | | Cold update | Warm update | |---|---|---| | A, before ([job](https://github.com/oobabooga/unsloth/actions/runs/38972789221/job/117214948654)) | 856,182,074 B (2 downloads), 1,314 s, silent | 13,105 B, 44 s | | B1, this PR ([job](https://github.com/oobabooga/unsloth/actions/runs/38980373037/job/117239567781)) | 428,140,611 B (1 download), 698 s, a note each minute | 6,938 B, 30 s | | B2, this PR ([job](https://github.com/oobabooga/unsloth/actions/runs/38980373037/job/117239567498)) | 428,192,144 B (1 download), 667 s, a note each minute | 6,938 B, 40 s | In arm B a single `uv --project <temp dir> pip install` process held the wheel URL. One earlier arm B run of the same code ([job](https://github.com/oobabooga/unsloth/actions/runs/38977254602/job/117229573031)) moved 357 MB and then 428 MB: the download was cut off partway and uv retried it from the start. It was not the metadata pass, because the wheel's `METADATA` sits in its last 20 KB. flash-attn imports afterwards in both arms. Tests: - New `studio/backend/tests/test_wheel_download.py` covers when the metadata file is written and how uv and pip are invoked. It also runs real uv against a local server that, like GitHub, does not answer range requests: 2 downloads before, 1 after, none on reinstall, with a relative `UV_CACHE_DIR` that must stay in the working directory. Another checks that a project chosen with `UV_PROJECT` still applies its config. Both pass with uv 0.11.16 and 0.13.1. - `tests/python/test_install_python_stack.py` covers the progress output on a terminal and when captured. - The installer and `wheel_utils` suites pass, and `ruff check` and `scripts/run_ruff_format.py` are clean. --------- Co-authored-by: Daniel Han <danielhanchen@gmail.com> Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com> Co-authored-by: Daniel Han <23090290+danielhanchen@users.noreply.github.com> |
||
 Long Yixing |
3511e95ca3
|
Move the Unsloth Studio MLX pins to mlx-vlm 0.7.9 (#14307)
Moves the Unsloth Studio MLX install and self-heal pins to mlx-vlm 0.7.9, alongside unsloth-zoo's ceiling raise (unslothai/unsloth-zoo#1887). The installer and the self-heal cap mlx-vlm at what the installed unsloth-zoo declares, so this takes effect once that zoo is installed. ## What changed - `install_python_stack.py` `_MLX_VLM_SPEC` and `mlx_repair.py` `_MLX_INSTALL_SPECS`: `mlx-vlm>=0.4.4,<=0.7.9`; tests and comments that carry the range follow. ## Why it is safe - 0.7.9's only requirement change is `mlx>=0.32.4`, which the MLX pins already install. Resolving the installer's requirement set (with the single-env constraints and darwin-arm64 overrides, Python 3.10 to 3.13) moves mlx-vlm alone, 0.7.8 -> 0.7.9; mlx-audio, transformers, datasets and the rest resolve as before. The self-heal dry run likewise moves only mlx-vlm. - Every mlx_vlm symbol Unsloth Studio uses resolves on 0.7.9, and the functions it calls are unchanged or changed compatibly. 0.7.9 makes generation honour checkpoint sampling defaults when a value is missing (#2545); Unsloth Studio always passes temperature, top_p and top_k, so its generation is unchanged. The rotating-cache sink / absolute-position fix (#2548) only corrects prefill past a context cap. ## Validation Unsloth Studio MLX backend and install tests, one process per file, on mlx-vlm 0.7.8 vs 0.7.9: ```text 2269 passed, 21 failed, 3 errors on both (the failures are pre-existing on main: offline model cache, memory-estimate and pip-probe tests) ``` The pin tests fail with the production specs reverted. |
||
 Michael Han |
d9aded3801
|
Point Unsloth docs links at unsloth.ai/docs instead of docs.unsloth.ai (#14333)
Some checks are pending
Mac Unsloth Install Matrix CI / Install + load (macos-15-intel) (push) Waiting to run
Mac Unsloth Install Matrix CI / Install + load (macos-26-intel) (push) Waiting to run
Mac Unsloth UI + API + Update + Inference CI / Chat UI, API, Update and GGUF inference (push) Waiting to run
Unsloth Tauri CI / Tauri Linux debug build (no codesign) (push) Waiting to run
Unsloth Tauri CI / Rust unit tests (windows) (push) Waiting to run
Unsloth Tauri CI / Rust unit tests (macos) (push) Waiting to run
Unsloth UI CI / Chat UI Tests (extra) (push) Waiting to run
Unsloth UI CI / Chat UI Tests (chat) (push) Waiting to run
Unsloth UI CI / Loaded-models indicator (cross-browser) (push) Waiting to run
Unsloth Update CI / Unsloth Updating Tests (push) Waiting to run
Unsloth Update CI / Unsloth Updating Tests (macOS) (push) Waiting to run
Unsloth Update CI / Unsloth Updating Tests (Windows) (push) Waiting to run
Studio VAE seam guard / seam-guard (push) Waiting to run
Windows Unsloth API CI / Unsloth API & Auth Tests (push) Waiting to run
Windows Unsloth GGUF CI / GGUF inference smoke (API, tools, vision) (push) Waiting to run
Windows Unsloth GGUF CI / Unsloth install + inference without Visual Studio (push) Waiting to run
Windows Unsloth GGUF CI / real-VS detection (VS 2022) (push) Waiting to run
Windows Unsloth GGUF CI / real-VS detection + VC++ round-trip (VS 2026) (push) Waiting to run
Windows Unsloth GGUF CI / setup.ps1 units, no-VS resolve, VC++ round-trip (windows-latest) (push) Waiting to run
Windows Unsloth UI CI / Chat UI Tests (push) Waiting to run
Windows Unsloth Update CI / Unsloth Updating Tests (push) Waiting to run
studiobench CI / Selftests, lint and the single-file build (push) Waiting to run
studiobench CI / Real-path session, every action ran (push) Waiting to run
Wheel CI / Wheel build + content sanity + import smoke (push) Waiting to run
Windows Application Control CI / installer survives a denied unsloth.exe (push) Waiting to run
Windows ARM64 CI / woa (pwsh-7) (push) Waiting to run
Windows ARM64 CI / woa (windows-powershell-5.1) (push) Waiting to run
Windows No Compiler CI / the installer spawns no C# compiler (push) Waiting to run
Workflow trigger lint / workflow-trigger lint (pull_request_target / cache-poisoning) (push) Waiting to run
Workflow trigger lint / security suites (torch-dependent) (push) Waiting to run
## What changed Unsloth docs links now go to `unsloth.ai/docs` instead of `docs.unsloth.ai`, which only 301-redirects there. - **Studio browser new tab page:** the "Unsloth Docs" suggestion opens `https://unsloth.ai/docs` in both the native and the proxied view. Suggestions used to be grouped by host, and the docs and the Unsloth home page now share `unsloth.ai`, so the docs tile would have been dropped. Suggestions are now grouped per site, with `unsloth.ai/docs` as its own entry. If you hid the old `docs.unsloth.ai` tile, it stays hidden. - **Installer messages** (`install.sh`, `studio/install_python_stack.py`): the AMD ROCm hints now link `https://unsloth.ai/docs/get-started/install/amd`. That is where the old `install-and-update/amd` path ends up after the redirects. The short `docs.unsloth.ai/amd` link redirected to `unsloth.ai/docs/amd`, which returns 404, so it now points at the AMD guide too. - **Docker Hub READMEs and CONTRIBUTING.md:** the docs and Docker guide links point at `unsloth.ai/docs`. Every new URL returns 200. Left as is: test fixtures that use `docs.unsloth.ai` as a sample host for address and link parsing, and a markdown security comment that uses it as an example string. The No GPU message in `unsloth/tokenizer_utils.py` also still uses the old link. It belongs to the core library, so it should be changed separately. ## Verification - `npm run typecheck`, `npm run build`, full `npm test` (12895 pass). The new `tests/browser-docs-link.test.ts` covers the suggestion URL and the per-site keys. - `pytest tests/python/test_install_python_stack.py tests/studio/install/test_rocm_support.py` (988 passed), `bash -n install.sh`. Not exercised here: the Desktop native browser view, and an AMD install that prints these messages. |
||
|
Daniel Han
|
7729c37fd0
|
Studio: restore Qwen causal-conv1d on demand, narrow fatal mamba-ssm, provision SSM kernels in export (#13971)
Follow up to #13861 and #13808. An audit of the merged on demand SSM
kernel change plus a T4 benchmark found a few gaps, fixed here.
## Why
- On a Kaggle T4 (sm75, torch 2.11 cu130, fp16, Qwen3.5-0.8B), Studio
chat decode was 4.4% slower without causal-conv1d (19.10 vs 19.95 tok/s,
6 alternating repeats, slower in all 9 pairs). Training speed, losses
and peak memory were unchanged. The zoo Triton conv covers
`causal_conv1d_fn` only, so single token decode fell back to the torch
update path. Training with trainable conv weights also allocates an fp32
dW scratch in the Triton backward, and packed `seq_idx` is not accepted
by the zoo dispatcher under transformers 5.20.
- Mamba-family models that have a working transformers torch path
(mamba, mamba2, falcon_mamba, jamba, zamba, zamba2, bamba) were made
fatal when mamba-ssm could not be installed.
- Export, local LoRA continuation, and inference model switching did not
provision or pick up kernels correctly once setup stopped installing
them.
- Setup on pre-Ampere GPUs (T4) downloaded flash-attn even though
Unsloth only enables FA2 at sm80+.
## Changes
1. Qwen3.5 / Qwen3.6 / Qwen3-Next request causal-conv1d on demand again
in training, inference and Clef (same as before #13861, minus the setup
time install). The zoo Triton platform probe is removed.
2. A missing mamba-ssm is fatal only for `nemotron_h`, `falcon_h1`,
`granitemoehybrid`. Other Mamba families install best effort and
continue on the torch path with a status message.
3. Local LoRA folders (`adapter_config.json`, no `config.json`) resolve
kernel needs from `base_model_name_or_path`; the training
`adapter_base_pin` wins when set.
4. The export worker provisions SSM kernels before importing Unsloth /
the export backend, with the same required vs optional split.
5. Inference re-enables the modeling source scan by reading
`transformers/models/<type>/modeling_*.py` as text, without importing
transformers.
6. If a kernel is newly installed after the model's
`transformers.models.<type>` module was already imported, the inference
worker asks for a restart and the orchestrator respawns it once.
7. Torch repair removes causal-conv1d / mamba-ssm whose compiled
extension no longer imports (never installs anything new). A hung import
check keeps the package.
8. Setup and the long context runtime install skip flash-attn below sm80
(and remove a stale copy at setup). No visible GPU and ROCm keep current
behavior.
## Tests
New and updated tests fail on main and pass here (`test_ssm_runtime.py`,
`test_ssm_restart_respawn.py`, `test_export_ssm_kernels.py`,
`test_clef_fast_paths.py`, `test_kernel_install.py`,
`test_training_worker_flash_attn.py`,
`test_ssm_kernels_install_python_stack.py`,
`test_flash_attn_install_python_stack.py`,
`test_windows_torch_flavor_invariant.py`). With
`test_install_python_stack.py` and `test_cuda_repair.py`: 966 passed
after merging current main.
## Hardening (second commit)
- Stale SSM kernel removal after torch repair needs proof: torch must
import first, and only an ImportError / OSError from the extension
itself removes the package. Signals, hangs, launch errors and a broken
torch keep it.
- `unsloth install-kernels --without-gpu` (or
`UNSLOTH_INSTALL_KERNELS_WITHOUT_GPU=1`) installs GPU gated kernels on a
GPU-less image builder. An already working kernel counts as success
before any skip, skipped kernels are listed, and the exit code is
unchanged (0) unless `--strict` is passed. The CLI respects `UV_OFFLINE`
/ HF offline variables and never falls back from uv to pip offline.
- Inference respawn refuses to spawn while the old worker survives
shutdown. SSM restart and the Xet fallback each get their own one-use
retry (3 spawns max).
- Restart detection only counts native `modeling_*` modules and the
selected checkpoint's remote code modules from its `auto_map`, matched
on the exact `transformers_modules` namespace.
- Export provisions SSM kernels inside the existing transformers
activation window (no extra Hub reachability probe), and skips
provisioning on macOS and for the MLX / CPU export backends.
- `UV_OFFLINE` counts as offline for on-demand installs (no URL probes,
source builds, or uv to pip fallback).
- Long context flash-attn install returns early when flash_attn already
imports, reuses the worker's own torch for the capability check, and
never applies the sm80 floor on ROCm.
## Install robustness (platform matrix review)
- A wheel is downloaded whenever its HEAD check is not a definite 404
(proxies that refuse HEAD no longer push required hybrids into a
failure), then import-verified; fallback only after a real failure.
- A failed install is remembered for the worker process (keyed by
kernel, torch, toolchain), so preflight and load share one attempt.
Optional Mamba families get mamba-ssm only as a prebuilt wheel, never a
source build. ROCm source builds get an 1800 s deadline and CUDA source
builds 7200 s (`UNSLOTH_SOURCE_BUILD_TIMEOUT` overrides); a timeout
kills the whole build tree.
- A runtime install whose extension does not import is uninstalled, so
transformers never finds a broken package.
- One cross-process lock per kernel and environment covers check,
install, verify and cleanup (training and runtime), with a recheck after
acquiring it.
- Only a CUDA or ROCm torch provisions anything; CPU, XPU, MPS and
unknown torch builds skip (export included).
- Optional mamba-ssm follows setup's sm80 floor (sm75 with Triton 3.4+);
the required hybrids keep the previous behavior.
- The resolver only returns URLs for cells that are actually published
(Unsloth release: torch 2.13/2.14 cp313, win_amd64 torch 2.10 to 2.12
cp311 to cp313; upstream causal-conv1d / mamba-ssm release cells), and
there is no source build of the pinned 1.6.1 / 2.3.1 sources on torch
2.13+, which need C++20.
- Training stays best effort for mamba-ssm, as before #13861.
- Export runs the malware and remote code consent gates before any
kernel provisioning.
- The extension is probed again after the install lock is acquired, so a
concurrent replacement is not treated as broken.
- The automatic HF offline window (Hub unreachable) no longer blocks
package installs; only user set offline variables do.
- `unsloth install-kernels --dry-run` prints the resolved URL while
offline.
- A Mamba model whose code needs mamba-ssm fails with a clear error on a
torch build without CUDA or ROCm.
## GPU checks (merge base vs head
|
||
|
Daniel Han
|
6069a27a0b
|
AMD install follow-ups: installable inferred target, gfx1153 lspci peer, override health hint (#14117)
## Problem #13931 taught the inferred-arch install path (no ROCm runtime visible, arch read from KFD / cpuinfo) to follow `_runtime_gfx_target`, so a Strix APU listed ahead of a discrete card hands torch to that card. The switch was unconditional, so it also fired when the target moved for another reason (KFD order, an iGPU preference) on a host where nothing can install for the new target. On a versionless host (no readable ROCm version) whose KFD pick has no AMD per-arch index (gfx942), the install switched to that arch, found no index and no generic tag, and left CPU torch, where main before #13931 installed the inferred arch's own wheels: | KFD devices | inferred | before #13931 | after #13931 | |---|---|---|---| | gfx942, gfx1151 | gfx1151 | `rocm/whl/gfx1151/` | nothing (CPU torch) | | gfx1103, gfx942 | gfx1103 | `rocm/whl/gfx110X-all/` | nothing (CPU torch) | | gfx942, gfx1103 | gfx1103 | `rocm/whl/gfx110X-all/` | nothing (CPU torch) | ## Also in this PR Two gfx1153 (Krackan Point 2) gaps in the same feature, found while re-verifying #13931 / #14022: - `studio/setup.sh` treated a lone Krackan Point 2 APU's own lspci line as a covered gfx1152 peer when lspci prints the Krackan die name the two share. It then forwarded no `--rocm-gfx gfx1153`, so llama.cpp took the CPU build and the gfx1153 warning was skipped. Both lspci scans now skip a gfx1152 answer beside a Krackan Point 2 CPU, as install.sh and install_python_stack.py already do. - With `HSA_OVERRIDE_GFX_VERSION` naming a covered arch (for example 11.0.0) on a lone gfx1153 with CPU torch, the installers install generic ROCm torch, but Studio's health gate exempted the card and dropped the "reinstall torch" hint main showed before. The gate keeps the card eligible when a readable override names another arch. ## Fix The inferred path takes the runtime target only when something installs for it: the target has an AMD per-arch index, or the ROCm version is readable and maps to a generic tag. Otherwise it keeps the inferred arch, as before #13931. The intended Strix handoffs (to a per-arch dGPU, or to a generic-only dGPU with a readable version) are unchanged. ## Tests - `tests/studio/install/test_setup_sh_gfx1153_lspci_peer.py` (3 of 7 fail on main) and `studio/backend/tests/test_krackan2_health_gate_hsa_override.py` (1 fails on main): pass here. Related Studio backend suites show no new failure against main. - `test_python_versionless_inferred_install_keeps_an_installable_arch` (3 cases): fail on main, pass here. - The Strix / gfx1153 / ROCm routing suites under `tests/studio/install`: 1683 passed, 1 skipped. - A wider routing simulation (5667 host cells over OS, arch, GPU sets, masks and tool availability): against main, this patch changes only these three cells. --------- Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com> |
||
|
Daniel Han
|
888ccc54df
|
Studio: install from a package index that lags PyPI (#14133)
Fixes https://github.com/unslothai/unsloth/issues/14031 ## Problem Every release raises the installer floors to itself (`unsloth>=2026.10.6`, `unsloth-zoo>=2026.10.6`), and Desktop asks for its own shipped backend (`UNSLOTH_DESKTOP_BACKEND_VERSION`). A package index that lags PyPI (a delayed corporate feed, a mirror, an upload cutoff) never has that release yet, so with releases every two or three days and a 7 day feed delay the install is unsatisfiable on every run: ``` × No solution found when resolving dependencies: ╰─▶ Because only unsloth<=2026.10.3 is available and you require unsloth>=2026.10.6, we can conclude that your requirements are unsatisfiable. ``` Desktop then cannot launch either: even when the backend is installed by hand, preflight sees it below the shipped version (`desktop_backend_version_outdated`) and starts a repair, which hits the same wall. ## Change - `install.sh` / `install.ps1`: one dependency-free `uv pip compile` (about 0.05 s warm) checks the floors against whatever index configuration uv reads (env, `uv.toml`, cutoffs). On PyPI it passes and nothing else changes. When the index cannot satisfy them, the installer takes that index's newest `unsloth-zoo`, then the newest `unsloth` not above it, pins that pair (`==`) and prints a warning naming both versions. The probes force `--resolution highest` and write to their own scratch file, so neither `UV_RESOLUTION=lowest` nor a configured `output-file` changes the result or touches user files. - `studio/install_python_stack.py`: the same fallback on the `studio update` path Desktop runs, for Desktop's backend floor. - When Desktop asked for the backend, the installer writes `unsloth_feed_ceiling.json` (`{"requested": ..., "available": ...}`) next to `pyvenv.cfg`, and removes it on every run where it is not needed. - Desktop preflight: an `outdated` backend counts as ready only when that marker names this build's expected version and the installed backend is at or above the marker's version. A newer Desktop, or any other stale reason, is graded as before. - The zoo floor literal moves into one variable per installer; `tests/test_installer_zoo_floor_parity.py` reads it from there. ## Tests - `tests/sh/test_relax_unsloth_floors_to_index.sh`, `tests/studio/test_relax_unsloth_floors_to_index.ps1` and `TestDesktopBackendVersionConstraint` (uv stubbed): floors kept when the index has the release or is unreachable, lowered and pinned when it lags (env index, uv.toml index, cutoff), zoo lagging unsloth, hashed resolver output, the marker written only for Desktop and cleared once the feed catches up, the probe scratch file removed. - Rust: `a_feed_ceiling_marker_covers_only_the_release_it_names`; the full `cargo test` suite passes. - Base vs head installer on a local mirror that serves only unsloth / unsloth-zoo 2026.10.3 ahead of PyPI, `--no-torch`, Desktop floor set: on ubuntu-latest, windows-latest and macos-15, main fails with the error above, this branch installs 2026.10.3, warns, writes the marker and the backend reports itself ready. - Same comparison with the full CUDA install on a Colab A100 and T4: main fails, this branch installs 2026.10.3 with a working CUDA torch; a plain PyPI install on this branch still gets 2026.10.6 and writes no marker. |
||
|
Daniel Han
|
5019141cf5
|
Studio: FLUX.3 Image Klein (distilled and base), with INT8 / FP8 / GGUF support (#13933)
## Problem
FLUX.3 Image Klein (black-forest-labs/flux-3-image-klein and -base)
cannot be loaded in Studio. Diffusers ships it only as Modular Diffusers
blocks (`Flux3DistilledAutoBlocks`, `Flux3AutoBlocks`), the repos carry
`modular_model_index.json` instead of `model_index.json`, and the
support is not in any Diffusers release yet
(huggingface/diffusers#15046).
## Change
- New `core/inference/diffusion_flux3.py`: loads the transformer, the
Qwen3-VL-4B text encoder and processor, and the FLUX.2 VAE per
subfolder, and puts a `DiffusionPipeline` face over the modular blocks.
Placement, model and group offload, the step callback (progress,
cancel), the decode phase hook and the scheduler swap all work through
the same component objects the blocks run.
- Two families: `flux.3-klein` (distilled, 16 steps, CFG 1, Euler) and
`flux.3-klein-base` (50 steps, CFG 3.5, negative prompt). Defaults
follow ComfyUI's current FLUX.3 templates (workflow templates 0.11.87):
the base text to image and edit templates run 50 steps at CFG 3.5 (euler
/ simple), raised from the launch templates' 25, which is also the BFL
reference setting (diffusers' FLUX.3 defaults: 50 steps, guidance 3.5);
both distilled templates run 16 steps at CFG 1. On hand-heavy prompts (6
prompts, short and long, 2 seeds, same reference noise) 50 steps fixed a
malformed handshake the 25-step render had and otherwise left the image
nearly unchanged. Both take up to 10 images through the existing
reference workflow. The `-pup` prompt upsampler repo is not matched as
an image model.
- Reference images are scaled to 1 megapixel (Lanczos, aspect kept)
before encoding, as ComfyUI's `ReferenceMultiLatent ["resize", 1]` does
in the FLUX.3 templates. Diffusers alone only downsizes above 16
megapixels.
- A seeded request starts from the BFL reference noise layout, so a
Studio seed renders what the BFL reference CLI renders for that seed.
The VAE stays in bf16, as ComfyUI runs the FLUX.2 VAE on NVIDIA (the BFL
reference decodes in fp32).
- Download plan: the modular index is the manifest and only
`transformer/`, `text_encoder/` and `vae/` are fetched, for full
pipelines and as the companions of a GGUF or single file (which take
only `transformer/config.json` from `transformer/`); the root BFL single
file, `ae.safetensors`, `variants/` and the prompt upsampler repo are
not. The plan also reports a pick of the other variant before anything
is staged.
- BFL added the optional prompt upsampler (`prompt_upsampler` /
`prompt_upsampler_processor`, from the separate ~19 GB
`black-forest-labs/flux-3-image-klein-pup` repo) to both official
manifests on 2026-10-16. Image loads ignore it: validation and the
locality check require only the components FLUX.3 loads (text encoder
and its processor, transformer, VAE). Checked on the current revision
through the real load path for a bf16 pipeline, a GGUF with staged
companions and the INT8 prequant: renders are pixel-identical to before
and the pup repo is never downloaded.
- Memory plan: bf16 size table entries, and the load-dtype sizing now
prices only `<component>/<file>` weights. The cached `variants/fp8r` and
`variants/nvfp4` packages were inflating the plan from 19.8 GB to 31.7
GB.
- Version gate: minimum 0.42.0, marked unreleased. Diffusers main and
the FLUX.3 branch both report `0.41.0.dev0`, which reads the same as the
0.41.0 release without FLUX.3, so the picker checks for the FLUX.3
module file in the installed package instead (no import).
- Quantisation: a new `FamilyProfile.quant_exclude_tokens` leaves named
layers dense for every transformer-quant scheme (int8, fp8, mxfp8,
nvfp4). It is empty by default, so other families are unchanged. FLUX.3
keeps the per-token modulations, timestep embedders, `norm_out`, the
text-stream per-mode blocks and the 20480-wide text projection in bf16,
which leaves 228 of 273 Linears quantised. Without it, mxfp8 and nvfp4
crash at the first step: the modulation inputs are a stride-0 `expand`,
and those kernels need contiguous inputs. int8 and fp8 also lose more
quality without it.
- nvfp4 is denied for FLUX.3: every keep-set measured 0.09 to 0.12
LPIPS, and so did BFL's own nvfp4 package.
- MX and NVFP4 Linears in every family now get a contiguous activation
through a forward pre-hook, installed by the shared post-quantisation
hook. torchao's activation quantisers assert contiguity, and a stride-0
broadcast such as `temb.expand(B, S, D)` otherwise crashes at the first
step; for contiguous inputs the hook does nothing. This is a
cross-family change. FLUX.2 klein 4B with mxfp8 (106 MX Linears,
compiled with CUDA graphs, the only way Studio runs a quantised
denoiser), checked in one process: 2 prompts at 1024x1024 rendered
without the hook, then again with it, give `torch.equal` decoded images,
and so does the denoiser output on a captured step. Two renders without
the hook are also `torch.equal` in that process. Across separate
processes the same renders differ by up to 2 of 255 with or without the
hook (before vs after this commit, and between two runs of the same
commit), so that comparison cannot show a difference either way. The
hook returns the arguments unchanged for any contiguous input. The
scheme smoke probe is unchanged from main, so no family's `auto` choice
moves.
- Regional compile and CUDA graphs are on for FLUX.3. With compile
available, `auto` resolves to int8 on sm80 and newer, as it does for the
other families.
- Single file and GGUF denoisers assemble around the base repo's
components, and the block graph follows the loaded denoiser. A GGUF
FLUX.3 reports `uint8` as `transformer.dtype`, because its only float
tensors are the fp32-kept QK norms. The denoise block casts the latents
to that dtype, so the loader pins the compute dtype with an empty
buffer. A checkpoint or pipeline of the other variant (distilled vs
base) is refused with the family to use, before the loaded model is
unloaded. BFL's own `variants/fp8r` and `variants/nvfp4` packages are
refused too: the nvfp4 one has the same tensor sizes as a ComfyUI NVFP4
file with a different scale layout, so it would decode silently wrong.
- Memory: measured activation rows for the distilled checkpoint. Each
reference is charged at 0.11 of the flat 8192 MiB per megapixel (about
900 MiB per 1 MP reference, the int8 / fp8 figure; bf16 measures about
700). Before this, FLUX.3 references were not charged at all. The
placement planner uses those rows too (denoise 1081, decode 2924 MiB at
bf16 instead of the flat 8192 headroom), so a 32 GiB card keeps a bf16
FLUX.3 resident instead of streaming the text encoder: measured peaks
21.2 GiB text to image and 21.9 GiB with 4 references, 5.7 s vs 7.0 s
per 1024x1024 text to image. 20 and 24 GiB still pick group offload. The
base checkpoint keeps the flat estimate (no measured rows).
- Auto-switch: a FLUX.3 cache snapshot downloaded around the hosted
INT8/FP8 file (no dense transformer shards) counts as downloaded when
that file is cached, and the switch loads it by repo id from the cache.
- LoRAs: the pipeline face uses the pinned build's
`Flux3LoraLoaderMixin` (transformer only). Checked on real weights with
a random rank-4 adapter on 215 attention and feed-forward Linears: bf16
eager, the adapter changes the render, weight 0 and removing it give the
base render bit for bit; int8 with the adapter baked in at load changes
the render too.
- Hosted artifacts: `flux.3-klein` lists
`unsloth/flux-3-image-klein-FP8` for int8 and fp8 (files
`flux-3-image-klein-INT8.safetensors` / `-FP8.safetensors`), the same
layout as `flux.2-klein`. `flux.3-klein-base` lists
`unsloth/flux-3-image-klein-base-FP8` the same way: its INT8 file is
BFL's own ComfyUI `int8_convrot` denoiser from
black-forest-labs/flux-3-image-klein-comfy, mirrored byte for byte and
read through the ComfyUI quant loader, and its FP8 file is ours. Checked
on real weights through the API load (50 steps, CFG 3.5, 2 prompts): the
seeded INT8 renders match BFL's single file loaded directly (LPIPS
0.0001 and 0.004), the seeded FP8 renders match our FP8 file loaded by
path (LPIPS 0.0001 and 0.0000). Without access to the repo the load logs
`prequant_repo_unavailable` and quantises on the fly.
- Ungated base files: `black-forest-labs/flux-3-image-klein` and `-base`
are gated, so a GGUF or FP8 pick (which carries only the denoiser)
fetched its text encoder and VAE through the gate. The upstream
Diffusers folders Studio loads (`modular_model_index.json`,
`text_encoder/`, `transformer/`, `vae/`) are now copied byte for byte
(21 files each, sha256 checked against the pinned upstream revision)
into `unsloth/flux-3-image-klein-FP8` and
`unsloth/flux-3-image-klein-base-FP8` beside the pre-quantized files,
and both are in the gated mirror table, so no separate mirror repo is
needed. Companion listings and the manifest check read those repos too,
so no request reaches the gated upstream. The picker and status still
show the BFL id.
- Hosted text encoders: both FP8 repos also carry the Qwen3-VL-4B text
encoder, the same bytes in each (the distilled and base `text_encoder/`
shards are identical), as
`flux-3-image-klein[-base]-text_encoder-INT8-ConvRot.safetensors` (5.25
GB, int8 ConvRot weight-only, built by
`scripts/build_te_int8_convrot_checkpoint.py`) and
`...-text_encoder-FP8.safetensors` (5.61 GB on disk, 4.83 GB resident:
layerwise fp8, bit-identical to the runtime cast), the same pattern as
Qwen-Image-2.1. An int8 request that cannot load the int8 file falls
back to the fp8 file, then to the dense encoder with the runtime fp8
cast, as on Qwen-Image-2.1. Unset requests get the int8 ConvRot encoder
(`te_quant_auto = "int8"`), as BFL's ComfyUI templates load
`qwen3vl_4b_int8_convrot` (4 of 5 workflows in
black-forest-labs/flux-3-image-klein-comfy); `none` still pins the bf16
encoder. Checked through Studio's load path: an unset request loads the
int8 file on both families and renders pixel-identical to the explicit
int8 render. Real weights, bf16 DiT, 19 cases against the bf16 encoder
on one B200 (A/A repeat bit-identical): int8 LPIPS-alex 0.017 mean /
0.098 max, SSIM 0.974 at 16 steps; 0.023 / 0.121, SSIM 0.973 for the
base at 25 steps, CFG 3.5. fp8 scores 0.038 / 0.220 and 0.035 / 0.132.
The encoder goes from 8.27 to 4.89 GiB resident and from 18.4 to 1.8 s
to load (warm page cache). Peak memory drops from 21.2 to 17.8 GiB. INT8
DiT with the int8 encoder: 0.033 / 0.134 (distilled) and 0.034 / 0.142
(base), 13.9 GiB peak. BFL's `qwen3vl_4b_int8_convrot` has the same int8
projections byte for byte but also quantises `embed_tokens`, which
Studio's loader cannot read. Repacked with that table dequantised, it
scored 0.018 / 0.150 and 0.027 / 0.113, a tie within per-image spread,
so the hosted file is our own build. Planner estimate for the encoder:
8487 MiB for bf16, 5517 MiB for fp8 or int8. Studio's own load of the
mirrored files (int8 distilled and base, fp8 distilled) renders bit for
bit what the harness renders.
- A GGUF pick with a transformer quant builds through `_assemble_pipe`,
which called `from_pretrained` on the modular pipeline class and
returned a pipeline with no transformer. It now assembles FLUX.3 through
the same per-component loader.
- Base checkpoint, checked on real weights (19 cases, 50 steps, CFG
3.5): Studio vs the BFL reference code LPIPS 0.038 mean, the diffusers
harness 0.037 against the same reference; 25 steps, text to image,
single and multi-reference edits and negative prompts render; every
distilled / base mismatch is refused before loading and in the loader.
Fixes this needed: a base single file on distilled companions takes
`flow_map` from the family instead of the companion config (it crashed
on meta tensors); BFL's own ComfyUI `int8_convrot` and `nvfp4` files
(black-forest-labs/flux-3-image-klein-comfy) now go to the ComfyUI quant
loader instead of being refused as `variants/` packages, with the fused
q/k/v split for FLUX.3; and the family, not the file name, picks the
base vs distilled recipe (BFL's base ComfyUI files have no "base" in
their names, so they were seeded 16 steps / CFG 1).
- Diffusers pin: `diffusers-main.txt` is re-enabled at Diffusers main
d42ebf9c (archive digest included), which carries the FLUX.3 merge
(huggingface/diffusers#15046) and the prompt upsampler block
(huggingface/diffusers#15058), the same route Qwen-Image-2.1 used before
0.41.0. Studio never loads the upsampler, so `flux3_blocks()` drops that
step from both FLUX.3 block graphs; a render at d42ebf9c matches the
merge commit pixel for pixel. A host that cannot fetch the pin keeps
0.41.0 and only FLUX.3 is refused. The pin tests check release mode on a
commented-out copy, so they pass with the pin on or off.
- Diffusers main now requires Python 3.11 (huggingface/diffusers#15030),
so the installer and the startup repair skip the pinned build below 3.11
instead of cloning something that cannot install. Python 3.10 keeps
0.41.0 and gets a FLUX.3 refusal that names the Python requirement; 3.9
keeps 0.36.0 as before.
## Results
Real weights, distilled, 16 steps, B200 shared lease. The 11 cases are
the BFL example prompts and seeds (8 text to image at 832x1248 to
1248x832, 3 edits with 1 or 2 references), scored with LPIPS (alex) and
SSIM.
| Comparison | LPIPS mean | LPIPS max | SSIM mean | Identical images |
|---|---|---|---|---|
| Studio vs Diffusers ModularPipeline given the same noise and
references | 0.0073 | 0.080 (edit_figurine) | 0.986 | 10 of 11 bitwise |
| Studio vs the BFL reference implementation | 0.0115 | 0.083
(edit_figurine) | 0.979 | 0 |
| Diffusers vs the BFL reference (same inputs, for scale) | 0.0046 |
0.026 | 0.991 | 0 |
Text to image cases against the BFL reference: LPIPS 0.0008 to 0.0018,
except riso_lido at 0.026 (the most chaotic prompt, which also moves
between two runs of the reference on different hosts). The one edit that
differs is edit_figurine: its 896x1120 input is just under 1 megapixel,
so the ComfyUI sizing scales it up to 912x1136 where the reference keeps
it as is. Same composition, different detail (LPIPS 0.08).
Tiny random models, distilled and base, text to image and edit,
resident, model offload and group offload: bitwise identical to the
Diffusers pipeline given the same inputs.
Speed features, the same 11 cases, against Studio bf16 eager:
| Arm | Quantised Linears | LPIPS mean | LPIPS max | SSIM mean |
|---|---|---|---|---|
| bf16, regional compile + CUDA graphs | 0 | 0.004 | 0.027 | 0.992 |
| auto (resolves to int8, compiled) | 228 | 0.024 | 0.056 | 0.958 |
| fp8, compiled | 228 | 0.039 | 0.215 (riso_lido) | 0.946 |
| mxfp8, compiled | 228 | 0.042 | 0.185 (riso_lido) | 0.939 |
Every case except riso_lido is at or below 0.048 for all three schemes.
For scale, compiled vs eager bf16 measured 0.0035 in the separate
quantisation survey.
Dependency check for the pinned build (`uv pip compile`, the installer's
requirement line):
| Python | Stack | Result |
|---|---|---|
| 3.11, 3.12, 3.13 | Studio pins: transformers 5.5.0, huggingface-hub
>=1.32,<2 | resolves; huggingface-hub 1.33.0, transformers 5.5.0 and
tokenizers 0.22.2 unchanged |
| 3.10 | same | no solution (the build needs Python 3.11), so the
installer skips it and keeps 0.41.0 |
| 3.11 | transformers 4.57.6 | no solution (it needs huggingface-hub
<1.0); the released 0.41.0 conflicts the same way, and Studio pins
4.57.6 only on Python 3.9, where it installs Diffusers 0.36.0 |
A dry run of the installer's install against an existing Python 3.12
stack swaps only the diffusers package.
Edits at 1024x1024, 16 steps, with 1 and 4 references (B200, 160 GB
free):
| Load | Placement | Peak allocated, t2i / 1 ref / 4 refs |
|---|---|---|
| bf16 | resident, no offload | 21.2 / 21.2 / 21.9 GiB |
| auto (int8) | resident, no offload | 16.8 / 15.9 / 18.0 GiB |
| auto (int8), capped at 16 GB | group offload, int8 denoiser and
encoders streamed | 3.2 / 3.6 / 5.7 GiB |
The 16 GB cap is simulated: the allocator fraction and `mem_get_info`
are both capped at 16 GiB. All three loads render all three requests.
GGUF and pre-quantised files, real weights, loaded through Studio's load
API (`begin_load`) from local copies of the hosted files. The same 11
cases, 16 steps, against Studio bf16 eager:
| Artifact | Quantised Linears | LPIPS mean | LPIPS max | SSIM mean |
Builder's gate (19 cases) |
|---|---|---|---|---|---|
| GGUF Q8_0 | 273 (GGUF) | 0.010 | 0.035 (edit_figurine) | 0.983 | 0.006
|
| GGUF UD-Q4_K_XL | 273 (GGUF) | 0.038 | 0.139 (riso_lido) | 0.947 |
0.038 |
| INT8 safetensors (seeded) | 228 | 0.024 | 0.056 (riso_lido) | 0.958 |
0.035 |
| FP8 safetensors (seeded) | 228 | 0.039 | 0.215 (riso_lido) | 0.946 |
0.036 |
A 3-case spot check (fox, man_dog, edit_coffee) also ran Q4_K_M: LPIPS
0.033 mean against 0.021 for UD-Q4_K_XL.
- All 273 Linears of the GGUF denoisers stay GGUF weights; the 1-D QK
norms are dequantized like other GGUF families. The real GGUF files hit
the `uint8` compute dtype problem described above, and render with the
pin.
- The INT8 and FP8 files quantise exactly the 228 Linears that
on-the-fly quantisation picks under the keep-list, and the seeded
renders are pixel identical to the on-the-fly int8 and fp8 renders.
- A GGUF pick that asks for int8 seeds the INT8 file and renders pixel
identical to the pipeline pick. Before the `_assemble_pipe` change the
same load came back with no transformer.
- CUDA graph capture fails on the K-quant GGUFs (a host-to-device copy
inside the dequant). The load logs the reason as a warning and runs
eager; every render completed and no error reaches the request.
Tiny Q8_0 GGUFs with BFL tensor names load for both variants and render
text to image and edit. Pairing the base GGUF with the distilled family
is refused.
Timing at 1024x1024, resident bf16, no compile: 1.3 to 2.5 s per text to
image, 2.8 to 3.9 s per edit.
## Tests
- `studio/backend/tests/test_diffusion_flux3.py`: 84 CPU tests covering
the download plan scope and variant verdict, the prompt upsampler
entries in the current official manifests, the modular manifest in the
gated-base probe, shard restore and staging, the pre-eviction variant
check (single files and pipelines), the local folder validation, the
FLUX.3 LoRA loader, per-image generation chunks, per-image negative
prompts, a local modular base for GGUF loads, the refusal of separate
encoder / VAE files, the hosted artifact rows and filenames, the
operator mirror, the quantized GGUF pick assembly, the nvfp4 deny, the
contiguous-input guard, the per-scheme keep-list (and that other
families are unchanged), the variant and BFL-package refusals, the GGUF
compute dtype pin, memory rows, detection, the `-pup` exclusion, modular
index detection, defaults, size table, the unreleased gate and
module-file probe, the modular download plan, plan sizing, reference
sizing, the reference noise layout, and the pipeline face (prompt and
generator splitting, step callback, interrupt).
- Frontend `model-catalog.check.ts`: passes with the new GGUF row.
- Family data freeze and autoopt parity fixtures updated for the two new
families (new rows only).
- Diffusion, image, inventory, quantisation and Diffusers-pin suites
(10,470 passed): no new failing test IDs against the base commit.
- Whole backend suite after the hosted-artifact commit: 74,977 passed,
and the failing test IDs (all present before it, environment related)
are the same set as on the previous commit.
- `tests/sh/test_clean_machine_notools_pinned_git.sh`: 44 passed.
## Not covered
- A dense bf16 cold load (`transformer_quant=none`). Cold anonymous
loads (fresh cache, no token) of a GGUF UD-Q4_K_XL pick, a base FP8 pick
and a bf16 pipeline pick (which auto-selects int8) each requested only
`unsloth/flux-3-image-klein[-base]-FP8` / `-GGUF` and rendered at
1024x1024; the GGUF pick downloads 9.53 GB with the int8 encoder.
- fp8r and nvfp4 variant files: they use Diffusers' new BFL quantizer
format, which no Studio prequant path loads yet.
- Upstream: Diffusers reports `uint8` as the dtype of a GGUF FLUX.3
transformer, and a plain ModularPipeline fails the same way. Studio pins
the compute dtype; the upstream fix is still to be filed.
- A script that exits while Studio's deferred background compile is
still running dies at interpreter shutdown (exit 245 or 250). This
reproduced on a bf16 FLUX.3 run after all renders had finished, and the
same way on FLUX.2 klein 4B (bf16, 3 renders, exit 245), so it is not in
the FLUX.3 code. Calling `unload()` first exits cleanly. The background
compile is shared by every family and is not changed here. I did not
check whether a Studio server shut down mid-compile hits the same thing.
- Follow-up: a smoke probe that also feeds a stride-0 activation, so a
scheme missing the contiguous guard fails the probe instead of the first
render. Left out of this PR.
- MLX, Windows and AMD paths for FLUX.3 were not run. The native sd.cpp
route is #14144, stacked on this PR.
- Hosted repos (public, ungated): `unsloth/flux-3-image-klein-FP8`,
`unsloth/flux-3-image-klein-base-FP8`, `unsloth/flux-3-image-klein-GGUF`
and `unsloth/flux-3-image-klein-base-GGUF`. The two GGUF repos are
picker rows (shown under their repo names); `model-catalog.check.ts
--network` checks every declared file against the Hub. If a FP8 repo
cannot be reached, an int8 or auto load logs `prequant_repo_unavailable`
and quantises on the fly (checked on real weights, same output as the
file).
- GGUF CUDA graphs on K-quants (falls back to eager).
- nvfp4 quality (excluded from `auto`) and step caching.
- Python 3.10 hosts cannot run FLUX.3 until a Diffusers release carries
it (the refusal says so).
- Timings: the runs above were on shared GPUs, so they are accuracy
checks, not benchmarks.
- A real 16 GB card (the cap was simulated in-process).
- Measured memory rows for the base checkpoint (it uses the flat
estimate).
- Trained FLUX.3 LoRAs (and their key formats); only a random adapter
was tried.
- Separate text encoder / VAE files beside a FLUX.3 GGUF or single file:
refused with a clear message for now (the supplied-component loader
reads a model_index.json, which FLUX.3 does not ship).
- Prompt upsampler integration: #14137, stacked on this PR.
- ComfyUI seeds do not reproduce (ComfyUI draws its own noise layout);
BFL seeds do.
- The single reference path differs from the BFL reference by design (1
megapixel resize instead of pad to 4 megapixels), following ComfyUI.
- Text encoder length cap: 8192 tokens (Diffusers) against 4096 in the
BFL reference; only prompts past 4096 tokens differ.
## Another GPU generation
On a Colab RTX PRO 6000 Blackwell (sm120, torch 2.14.1+cu130), Studio's
own `DiffusionBackend` from this branch loaded
`unsloth/flux-3-image-klein-FP8` with every setting left at its default
and rendered 1024x1024 images. It picked an int8 transformer (int8 GEMM
engaged), the hosted int8 ConvRot text encoder, compile with CUDA graphs
and no offload, and the load took 84 s. The merge base does not detect
the repo as FLUX.3 at all.
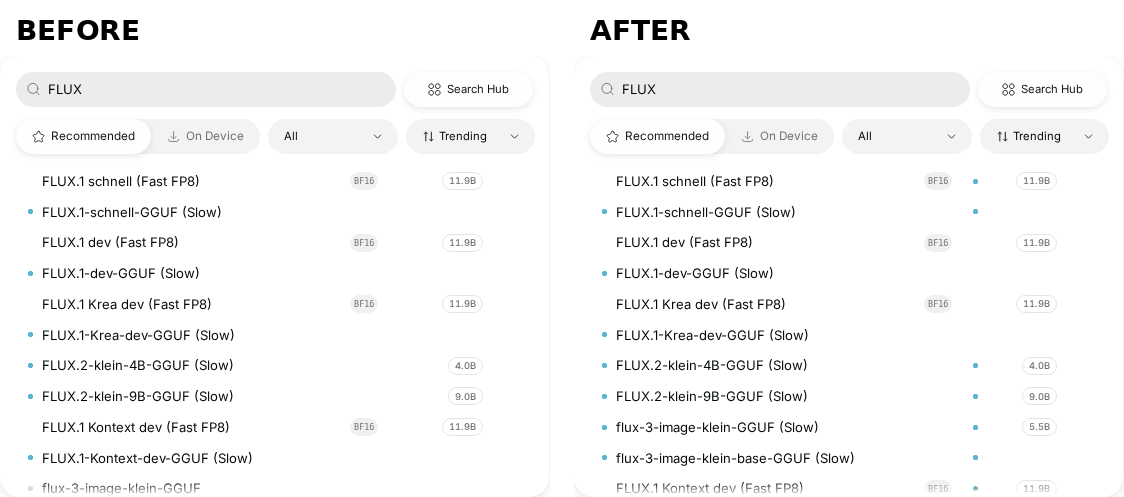
## UI
Images model picker searched for "FLUX", before (merge base
|
||
|
Daniel Han
|
6a31011f2e
|
Studio: default to the Vulkan llama.cpp bundle when a CPU-bound host has a Vulkan GPU (#13599)
Uses the Vulkan llama.cpp bundle on hosts that would otherwise get the CPU bundle (macOS excepted), whenever the Vulkan loader enumerates a GPU llama.cpp can run on, and lets Windows on ARM (Snapdragon X, Adreno) install the Vulkan bundle at all. The unslothai/llama.cpp release now ships a Vulkan bundle for each of `linux-x64`, `linux-arm64`, `windows-x64` and `windows-arm64` (`b11696-mix-7baeb9a`), so a Snapdragon laptop, a Linux arm64 board with a Mali / Adreno / Asahi GPU, or a box whose GPU none of our vendor checks recognise no longer runs GGUF on the CPU. Related: #11674 ### What changes - New automatic route in `_route_to_vulkan_prebuilt`. A host that is not macOS, has no physical NVIDIA GPU and no ROCm, was not already routed to Vulkan (Intel, AMD without ROCm), asked for no specific backend (unset or `auto`), and has no `GGML_VK_VISIBLE_DEVICES` mask is probed for a Vulkan GPU. If one is found it gets the Vulkan bundle first and the CPU bundle second; otherwise nothing changes. The marker records it as detected (like the Intel route), so updates re-detect and the existing "auto-selected Vulkan crashed, retry on CPU" recovery covers it. - The probe (`_vulkan_gpu_devices`) applies llama.cpp's own device checks from `ggml_vk_instance_init` / `ggml_vk_device_is_supported`: a Vulkan 1.2 loader, then a discrete or integrated GPU with Vulkan 1.2 and 16-bit storage buffers. It skips llvmpipe, SwiftShader and Dozen (Vulkan over D3D12, WSL), and any NVIDIA or AMD device the caller hid with `CUDA_VISIBLE_DEVICES` / `ROCR_VISIBLE_DEVICES` (HIP masks on Windows), since Vulkan ignores those masks. It runs in a child Python process with a 30 s timeout, because a broken driver can crash whatever loads it. Any failure (no loader, non-zero exit, bad output) counts as "no GPU", which leaves the host on the CPU bundle as today. `UNSLOTH_VULKAN_DEVICE_PROBE=0` turns it off; both test conftests set that so a fake CPU host never sees the test machine's GPUs. - Second check after download: for a probe-routed host the installer runs the installed bundle's own `llama-server --list-devices` and keeps the Vulkan bundle only if it lists a `VulkanN:` device. Otherwise (no device, non-zero exit, 180 s timeout) the attempt fails and the CPU bundle is installed instead. Without this, a bundle whose `ggml-vulkan` finds nothing would still pass, since it then runs on the CPU. Explicit Vulkan requests and the existing Intel / AMD routes are not gated by it. - Vulkan stays the last GPU choice: the route only applies once NVIDIA (CUDA), ROCm, and the existing Intel / AMD Vulkan routes have all been ruled out, and its only fallback is the CPU bundle. - Windows ARM64: new install kind `windows-arm64-vulkan` -> `vulkan` in the shared backend vocabulary, picked from the fork's `windows-arm64-vulkan` bundle (arch-filtered) or upstream's `llama-<tag>-bin-win-vulkan-arm64.zip`, with the ARM64 CPU bundle after it. It is reached through the probe above or an explicit `UNSLOTH_LLAMA_CPP_BACKEND=vulkan`. A `HostInfo.vulkan_routed` flag, set only by `_vulkan_only_host`, is what the ARM64 branches read, so a stale Intel adapter entry in the registry does not route an ARM64 box on its own. `_has_no_vulkan_prebuilt` is removed. - The new kind is added where `windows-vulkan` is listed: runtime copy patterns, the server validation GPU set, the payload health groups (`ggml-vulkan.dll`), and `setup.ps1`'s existing-install kind check on an ARM64 venv (otherwise every update would delete and refetch a working Vulkan install). `setup.ps1` no longer throws on a Vulkan request on Windows ARM64. - The "GGUF chat would need Vulkan ... no Windows ARM64 Vulkan bundle is published" hint for an unsupported AMD GPU on Windows ARM64 (`install.ps1`, `setup.ps1`, `install_python_stack.py`) is gone; ARM64 now gets the same Vulkan advice as x64. - `install_whisper_prebuilt.py`: the libomp comment for Windows arm64 GPU bundles is updated (the new bundle is built with `GGML_OPENMP=OFF`). ### Who is unaffected The probe only runs on hosts headed for the CPU bundle, so NVIDIA, ROCm, Intel, x86_64 AMD-without-ROCm and macOS hosts select exactly what they did before and pay nothing. `UNSLOTH_LLAMA_CPP_BACKEND=cpu` (or `cuda` / `rocm`), `--force-cpu` and `--cpu-fallback` still win. A CPU-only machine (cloud VM, container without a GPU) sees only llvmpipe or no loader, so it keeps the CPU bundle. ### Tests - `studio/backend/tests/test_install_resolve_prebuilt.py`: - Auto route on Windows x64, Linux x64, Linux arm64 (with and without the AMD flag) and Windows arm64 (with and without a stale Intel flag), each with a stubbed Vulkan GPU. - With no Vulkan GPU, Windows arm64 stays on its CPU bundle. - Nine host kinds that must never run the probe (stub raises): macOS, NVIDIA, ROCm, ARM64 NVIDIA, x86_64 AMD without ROCm, `--force-cpu`, backend `cpu`, backend `cuda`, and a `GGML_VK_VISIBLE_DEVICES` mask. - Device filtering: keeps a GPU and drops a CPU type, Dozen, Vulkan 1.1, no 16-bit storage and virtual GPUs; honours the CUDA / ROCR masks; bad output, empty output and a non-zero exit all mean no GPU; the off switch skips the child. - The real probe script, run against a missing driver file, lists nothing. - Published selection: an auto-routed Windows arm64 host picks `windows-arm64-vulkan` then the ARM64 CPU bundle; Linux arm64 picks the arm64 Vulkan bundle (never the x64 one) then `linux-arm64`. - The forced-Vulkan and upstream ARM64 tests from the first round are kept. - `tests/studio/install/test_llama_kind_gate_matches_selector.py`: the real `setup.ps1` block under pwsh keeps a `windows-arm64-vulkan` install on an ARM64 venv and never accepts it on x64. - `tests/studio/install/test_rdna1_unsupported_message_8529.py`: ARM64 and x64 both get the Vulkan setter. - `tests/studio/install/test_install_llama_prebuilt_logic.py`: a probe-routed Vulkan bundle that lists no GPU raises `PrebuiltFallback` (so the CPU attempt runs), one that lists a GPU is kept, and the listing is never run for a non-probe Vulkan install or a CPU bundle. `--list-devices` parsing: a `Vulkan0:` line counts; `(none)`, an RPC-only device, a non-zero exit and a missing binary do not. - Mutation: with the probe term replaced by `False`, 10 of the new routing / selection tests fail; with the device listing gate removed, both gate tests fail. - The real fork bundle `app-b11696-mix-7baeb9a-linux-x64-vulkan.tar.gz` on this host: `--list-devices` prints `Vulkan0..7: NVIDIA B200` and the gate keeps it; with only the llvmpipe ICD, or with no driver file, it prints `(none)` and the gate falls back. - The probe on a real host (Linux, 8x B200 + Mesa): it lists the eight `NVIDIA B200` devices and `llvmpipe`, and keeps only the B200s (none when `CUDA_VISIBLE_DEVICES` is set). With only the llvmpipe ICD it keeps nothing. ### Not covered Nothing here ran on a Snapdragon / Adreno machine or a Linux arm64 GPU board; GitHub's ARM64 runners have no GPU. ggml-org/llama.cpp#28290 is an open report of wrong MUL_MAT results on the Snapdragon X Elite Vulkan driver, and the Studio CPU recovery only catches crashes, not wrong output. Weak integrated GPUs (for example a Raspberry Pi's V3D) pass the same checks llama.cpp applies and can be slower than the CPU; `UNSLOTH_LLAMA_CPP_BACKEND=cpu` opts out. |
||
|
Daniel Han
|
983226fa73
|
AMD: Strix defers only to an installable generic tag; gfx1153 health gate classified at inventory refresh (#14022)
## Problem Follow-up to #13931. - A Strix APU (gfx1150 to gfx1152) listed ahead of a discrete card now defers the torch install to that card when `_detect_rocm_version()` returns a version. A version with no generic pytorch.org tag, for example ROCm 5.7, still passed that check. The installer then printed "No PyTorch wheel for ROCm 5.7 -- skipping torch reinstall" and left CPU torch, where before #13931 it installed from AMD's gfx1151 index. - The Linux Krackan Point 2 (gfx1153) health gate exemption matched on the marketing name. Linux sysfs records have no name, and without rocminfo or amd-smi they have no gfx candidates, so a lone gfx1153 on intentional CPU torch was still reported as a broken install. - That name check also ran `platform.system()` and a regex on every health poll for a candidate-less AMD record, even when the inventory was cached. ## Fix - `install_python_stack.py`: Strix defers only when `_generic_pytorch_rocm_tag()` resolves a tag for the detected ROCm version. Otherwise it keeps its own per-arch index, as before #13931. `install.sh` needs no change: its deferral runs only inside the `rocm*` index-leaf branch, so a generic tag has already been resolved there. - `hardware.py`: the gfx1153 classification moves into the inventory refresh. When ROCm tools report nothing, the KFD topology (`amd_kfd_gpu_gfx_targets()`) is read, and its targets are cached in `gfx_candidates` only if they include gfx1153. A named Krackan Point 2 record with no candidates is tagged `gfx1153` at the same point. Other arches keep the no-candidates answer they had before. The per-poll name check in `_amd_device_can_establish_a_mismatch` is removed, so a poll does the same work as before #13931. ## Tests - `tests/studio/install/test_linux_amd_strix_dgpu_gfx1153.py`: gfx1151 with gfx1100 and gfx1151 with gfx942 on ROCm 5.7 keep the gfx1151 index. These fail on main and pass here. - `studio/backend/tests/test_krackan2_health_gate.py` now goes through the real inventory refresh, using KFD fixtures. It covers a nameless gfx1153 resolved from KFD, gfx1153 beside gfx1100, gfx1100 and gfx1151 left unchanged, ROCm tools taking precedence, named records, Windows unchanged, and a poll that makes no `platform.system()` call. Three of these fail on main and pass here. - Base vs head, failing test IDs compared: `tests/studio/install/` and the backend AMD, GPU, ROCm and health suites show no new failures. The only differences are the new tests. --------- Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com> |
||
|
Long Yixing
|
5021249ccc
|
Move the Unsloth Studio MLX stack to mlx 0.32.4 and mlx-lm 0.32.2 (#13992)
## Summary Moves the MLX stack that the Unsloth Studio installer and the MLX self-heal install to mlx 0.32.4 and mlx-lm 0.32.2, matching unsloth-zoo ([unslothai/unsloth-zoo#1835](https://github.com/unslothai/unsloth-zoo/pull/1835)), and fixes what mlx-lm 0.32 breaks in Unsloth Studio's MLX inference backend: batched text generation fails, and the KV memory estimate under-counts the cache. | | before | after | |---|---|---| | `mlx` / `mlx-metal` | `==0.32.3` | `==0.32.4` | | `mlx-lm` | `==0.31.3` | `>=0.31.3,<=0.32.2` | | `mlx-vlm` | `>=0.4.4,<=0.7.8` | unchanged | | MLX Python floor | 3.10 | unchanged | ## mlx-lm as a range, narrowed to the installed unsloth-zoo mlx-lm 0.32 requires Python 3.11, while mlx 0.32.4 still ships cp310 wheels. mlx-lm is now installed from a range, as mlx-vlm already is, in both the installer and the self-heal, so Python 3.10 resolves 0.31.3 and 3.11+ resolves 0.32.2. Like mlx-vlm, the range is intersected with what the installed unsloth-zoo declares, so an older unsloth-zoo that pins `mlx-lm==0.31.3` keeps 0.31.3 instead of being put next to 0.32.2. Every mlx-lm requirement unsloth-zoo has shipped intersects the range, so the intersection is never empty. The "stack is current" check, the closure audit, the re-resolve after the core phase upgrades unsloth-zoo, and the recorded MLX verdict all follow the narrowed spec and the installed mlx-lm version. mlx and mlx-metal stay exact pins. ## mlx-lm 0.32 in the inference backend - **Batched generation.** mlx-lm 0.32 drops `BatchGenerator.insert`'s `state_machines` argument, so batched text generation raised `TypeError: BatchGenerator.insert() got an unexpected keyword argument 'state_machines'`. It is no longer passed. - **KV memory estimate.** mlx-lm 0.32's KV caches report the whole preallocated buffer as `state`, so the estimate priced the wrong arrays (gemma-3-270m at 8192 tokens: 40.1 MB of KV instead of 65.3 MB). It now reads `keys_and_values()` where a cache has it. - **Recurrent-layer convolution width.** mlx-lm 0.32's `ArraysCache.state` nests the arrays one level down (`(arrays, left_padding, lengths)`), which hid the convolution allowance of linear-attention layers. One level of nesting is now read, as for the KV entries. - Test fakes follow 0.32's detokenizer probe and merged EOS set. ## What a real install resolves With the installer's constraints and macOS arm64 overrides (transformers 5.5.0): ``` Python 3.13 mlx==0.32.4 mlx-metal==0.32.4 mlx-lm==0.32.2 mlx-vlm==0.7.8 mlx-audio==0.5.9 Python 3.10 mlx==0.32.4 mlx-metal==0.32.4 mlx-lm==0.31.3 mlx-vlm==0.7.8 ``` mlx-lm 0.32 declares `transformers>=5.7`; under the 5.5.0 override the only effect found is BPE streaming spacing for tokenizers with `clean_up_tokenization_spaces`. ## Ordering As with the previous bumps, this should merge after an unsloth-zoo release carries [unslothai/unsloth-zoo#1835](https://github.com/unslothai/unsloth-zoo/pull/1835). mlx is an exact pin, and on mlx 0.32.4 an older unsloth-zoo hits a training attention backward that raises for short sequences and sinks, and a compiled training step crash. mlx-lm is narrowed to the installed unsloth-zoo, so an older unsloth-zoo keeps mlx-lm 0.31.3. ## Validation ``` Unsloth Studio MLX test files, mlx 0.32.3 + mlx-lm 0.31.3 vs mlx 0.32.4 + mlx-lm 0.32.2: 2231 passed vs 2230 passed, same pre-existing failures; the one difference is a test that inspects local checkpoints on disk (DFlash drafter snapshots now build on mlx-lm 0.32) mlx 0.32.4 + mlx-lm 0.31.3 (Python 3.10 resolution) vs 0.32.2: no regressions installer, self-heal, memory-estimate and inference-backend tests: pass apart from 2 pip-probe tests and environment-dependent memory-estimate cases that fail on main too ``` Every added or changed test fails with its production change reverted (installer and self-heal range logic: 15 reverts, each caught). |
||
|
Daniel Han
|
4a8b727dfd
|
Installers (AMD, Linux): a Strix APU defers torch to a discrete card, and a lone gfx1153 warns instead of getting kernel-less wheels (#13931)
## Problem Two Linux AMD torch routing gaps (#11815, #9932): - **Strix APU beside a discrete card:** when a Strix APU (gfx1150 / gfx1151 / gfx1152) was listed first, torch was installed from that APU's per-arch index. Those wheels carry no other arch. - With a gfx1151 and an RX 7900 (gfx1100), or an RX 9070 (gfx1201), the discrete card got no torch kernels. - This contradicts the installer's own rule for integrated GPUs listed first (#7776), which installs for the discrete card. Strix was left out of that rule because it is also the right llama.cpp target when it is alone. - **gfx1153 alone:** on Linux it was in no table, so it silently got the generic ROCm wheel. That wheel has no gfx1153 kernels; AMD publishes gfx1153 only as an opt-in device pack on its multi-arch index. The "no wheels for this GPU" warning never showed. ## Fix - **Strix:** - `_amd_prefer_discrete_gfx` takes a `torch` mode. For the torch install, a Strix pick defers to the first discrete card that has a wheel route, skipping integrated GPUs and gfx906. `_runtime_gfx_target` in `install_python_stack.py` applies the same rule. - A warning names the card torch is installed for and how to target the APU instead (`HIP_VISIBLE_DEVICES` or `UNSLOTH_ROCM_GFX_ARCH`). The install summary uses the same pick. - The deferral needs a readable ROCm version (otherwise there is no generic tag for the discrete card, so the Strix index is kept, as before) and no `HSA_OVERRIDE_GFX_VERSION` (an override spoofs every agent, so the discrete card's wheels would never load). - When the runtime is not visible yet, the inferred install also uses the deferred card, and the Radeon repo flag set by the APU's name is cleared on the handoff. - **Unchanged:** a lone Strix, any HIP/CUDA/ROCR mask, `UNSLOTH_ROCM_GFX_ARCH`, Strix + gfx906, Strix + an RDNA 1 card, and llama.cpp's target. - **gfx1153:** - Joins RDNA 1 and Polaris in the "no Linux wheels" list (`install.sh`, `studio/setup.sh`, `install_python_stack.py`). A lone gfx1153 gets CPU torch with the explicit warning, plus the opt-in `UNSLOTH_TORCH_EXTRA=device-gfx1153` hint for AMD's multi-arch index, as RDNA 1 already has. - An `HSA_OVERRIDE_GFX_VERSION` to a covered arch still gets ROCm torch. gfx1153 beside a covered card still installs for that card. - With no rocminfo or amd-smi, both installers recognise Krackan Point 2 names (Radeon 820M, Ryzen AI 5 330) before the broader gfx1152 patterns, so a lone gfx1153 is not treated as gfx1152. A Krackan Point 2 CPU or lspci line is only a fallback: a covered discrete card found by the lspci scan still wins. The final install summary and `setup.sh`'s summary keep that inferred gfx1153, and `setup.sh` forwards it to the llama.cpp installer so the HIP bundle is kept; the guidance no longer points gfx1153 at Vulkan. - llama.cpp's HIP route for gfx1153 is not changed. Studio's health check on Linux recognises the same Krackan Point 2 names, so a lone gfx1153's CPU torch is not reported as a broken install. The KFD-only CPU-index reroute (no rocminfo or amd-smi, readable ROCm version) is unchanged: there a leading Strix still picks its own index, as on main, because that single arch export also feeds llama.cpp's target. Splitting it is a follow-up. Likewise, the "every probed arch is uncovered" check judges the unmasked inventory, as it already does for RDNA 1 and Polaris, so a mask that pins gfx1153 beside a covered card still gets the generic wheel, as on main. Routing gfx1153 and RDNA 1 to AMD's multi-arch index automatically on Linux would need the Windows multi-arch handling (device pack detection, repair, bitsandbytes) ported first. That is left for a follow-up. ## Tests - **New `tests/studio/install/test_linux_amd_strix_dgpu_gfx1153.py`**, covering: - gfx1151 + gfx1100 and gfx1151 + gfx1201, in both installers; - lone gfx1151, masks and the override; - lone gfx1153, the HSA override, and gfx1153 beside a covered card; - Krackan Point 2 cpuinfo and lspci names, an unreadable ROCm version, an HSA override with a Strix and a discrete card, and the Radeon flag on the handoff. - **Base vs head:** the new routing tests fail on main and pass here. The rest guard the unchanged cases. - `install.sh` is checked with `bash --posix -n` and `dash -n`, and the macOS staging leg (bash 3.2) runs it. - **Full suites:** `tests/studio/install/` (102 files), the `tests/sh` checks for these helpers and `test_install_resolve_prebuilt.py` all pass. --------- Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com> |
||
|
Daniel Han
|
90ac3b7734
|
Studio: install causal-conv1d and mamba-ssm only when a model needs them (#13861)
Some checks are pending
Mac Unsloth Install Matrix CI / Install + load (macos-15-intel) (push) Waiting to run
Mac Unsloth Install Matrix CI / Install + load (macos-26-intel) (push) Waiting to run
Mac Unsloth UI + API + Update + Inference CI / Chat UI, API, Update and GGUF inference (push) Waiting to run
Unsloth Tauri CI / Tauri Linux debug build (no codesign) (push) Waiting to run
Unsloth Tauri CI / Rust unit tests (windows) (push) Waiting to run
Unsloth Tauri CI / Rust unit tests (macos) (push) Waiting to run
Unsloth UI CI / Chat UI Tests (extra) (push) Waiting to run
Unsloth UI CI / Chat UI Tests (chat) (push) Waiting to run
Unsloth UI CI / Loaded-models indicator (cross-browser) (push) Waiting to run
Unsloth Update CI / Unsloth Updating Tests (push) Waiting to run
Unsloth Update CI / Unsloth Updating Tests (macOS) (push) Waiting to run
Unsloth Update CI / Unsloth Updating Tests (Windows) (push) Waiting to run
Studio VAE seam guard / seam-guard (push) Waiting to run
Windows Unsloth API CI / Unsloth API & Auth Tests (push) Waiting to run
Windows Unsloth GGUF CI / GGUF inference smoke (API, tools, vision) (push) Waiting to run
Windows Unsloth GGUF CI / Unsloth install + inference without Visual Studio (push) Waiting to run
Windows Unsloth GGUF CI / real-VS detection (VS 2022) (push) Waiting to run
Windows Unsloth GGUF CI / real-VS detection + VC++ round-trip (VS 2026) (push) Waiting to run
Windows Unsloth GGUF CI / setup.ps1 units, no-VS resolve, VC++ round-trip (windows-latest) (push) Waiting to run
Windows Unsloth UI CI / Chat UI Tests (push) Waiting to run
Windows Unsloth Update CI / Unsloth Updating Tests (push) Waiting to run
studiobench CI / Selftests, lint and the single-file build (push) Waiting to run
studiobench CI / Real-path session, every action ran (push) Waiting to run
Wheel CI / Wheel build + content sanity + import smoke (push) Waiting to run
Windows Application Control CI / installer survives a denied unsloth.exe (push) Waiting to run
Windows ARM64 CI / woa (pwsh-7) (push) Waiting to run
Windows ARM64 CI / woa (windows-powershell-5.1) (push) Waiting to run
Windows No Compiler CI / the installer spawns no C# compiler (push) Waiting to run
Workflow trigger lint / workflow-trigger lint (pull_request_target / cache-poisoning) (push) Waiting to run
Workflow trigger lint / security suites (torch-dependent) (push) Waiting to run
Studio setup stops downloading causal-conv1d and mamba-ssm. They are installed when a model that needs them is first trained or loaded, and Qwen3.5 / Qwen3.6 / Qwen3-Next no longer request causal-conv1d at all. ## Why #13396 added both kernels to every NVIDIA Linux / Windows setup next to flash-attn: about 555 MB of downloads (~620 MB installed) for every user, while only a few model families use them. Studio already installs them on demand when such a model is trained (`core/training/worker.py`) or loaded for chat (`core/inference/worker.py` through `utils/ssm_runtime.ensure_ssm_runtime`), so the setup step only duplicated that. Qwen3.5 / 3.6 / Qwen3-Next do not need causal-conv1d with Unsloth: unsloth-zoo runs their GatedDeltaNet with its vendored FLA kernels and its own Triton causal conv (`unsloth_zoo/temporary_patches/gdn_causal_conv1d.py`, model types `qwen3_5`, `qwen3_5_moe`, `qwen3_next`). Studio still downloaded the CUDA package for them because their transformers modeling files mention `causal_conv1d`. ## What changes - `studio/install_python_stack.py`: the setup-time SSM install is gone from all three places (initial setup, Linux torch repair, Windows torch flavor repair), with its progress step. flash-attn stays where it was. `unsloth install-kernels` still installs every kernel, for offline images. - `studio/backend/utils/ssm_runtime.py`: `ZOO_GDN_MODEL_TYPES` (equal to zoo's list; a test reads zoo's source to keep them equal). Names and configs of those models, including `_text` / `_vision` sub-configs, resolve to no causal-conv1d request, checked before the modeling-source scan. A config that mixes in another model type that needs it still asks for it. Zoo's own kill switch `UNSLOTH_DISABLE_TRITON_CAUSAL_CONV1D=1` brings the old request back. - `core/training/worker.py` and `core/systemone/clef_runtime.py` use the same predicate, so the eager install, the `is_causal_conv1d_available` hook and Clef (a Qwen3.5 backbone) all agree. - Only where zoo's Triton conv can run: a CUDA torch (not ROCm, not CPU), Triton importable, not macOS. This is read from torch's distribution version (`+rocm` / `+cpu` / `+cu`), so no load imports torch to decide. On ROCm, macOS or Windows without triton-windows, Qwen keeps getting causal-conv1d as before. - With setup no longer covering for it, the on-demand install now decides from the model's config, not only its name: `resolved_model_is_ssm` maps `nemotron_h`, `falcon_h1`, `granitemoehybrid`, `bamba`, `jamba`, `zamba`, `zamba2`, `mamba`, `mamba2`, `falcon_mamba` (and their `_text` sub-configs) to mamba-ssm + causal-conv1d, for training and for the inference load of the resolved base. Previously `NVIDIA-Nemotron-Nano-9B-v2`, `granite-4.0-tiny-preview`, renamed local checkpoints, Jamba, Zamba and Bamba never got mamba-ssm on demand. - After an install inside an inference worker that already imported transformers, the cached `is_causal_conv1d_available` / `is_mamba_ssm_available` / `is_mamba_2_ssm_available` and cached hub-kernel misses are cleared, so switching from Qwen3.5 to Nemotron-H in one session gets the fast path. - The mamba-ssm error raised when it cannot be installed (e.g. offline) says to run `unsloth install-kernels` once while online. - `install_kernel(install_without_gpu=)` is gone; setup was its only caller. - Clef still applies the FLA TileLang guard when it skips the install. Unchanged: LFM2, Mamba / Jamba / Zamba / Bamba still get causal-conv1d on demand; Nemotron-H, Falcon-H1 and Granite-4.0-H still get causal-conv1d then mamba-ssm on demand; nothing already installed is removed, and a usable causal_conv1d still wins inside zoo. ## Tests - `tests/python/test_ssm_kernels_install_python_stack.py`: setup has no SSM step; flash-attn is still installed at all three sites; the CLI kernels are still there. - `test_windows_torch_flavor_invariant.py`: the torch progress totals drop by one on Windows and Linux. - `studio/backend/tests/test_ssm_runtime.py`: Qwen3.5 / 3.6 / Next names and configs install nothing, the kill switch restores the request, a mixed config still asks, the Mamba2 hybrids still install both kernels in order, and the model-type list equals zoo's. - 21 of the new cases fail against main, and the follow-up cases (config-based SSM detection, platform check, cache refresh, offline message) fail against this PR's first commit; all pass here. The touched test files and the setup / resolver suites pass (test_ssm_runtime 84, test_training_worker_flash_attn 67, test_install_python_stack 295, test_cuda_repair 284, test_windows_torch_flavor_invariant 54, among others). ## Accuracy and speed without causal-conv1d (Qwen3.5) Tiny Qwen3.5 / Qwen3-Next through Unsloth, bf16: zoo's Triton conv is bit-identical to torch's reference conv (logits, loss, LoRA grads, 5 optimizer steps); the CUDA package differs from both at bf16 rounding (5.9e-3 logits, grads cos 0.99993). Prefill plus cached token-by-token decode matches a full forward equally with and without the package (4.0e-3 vs 3.9e-3). The profiler shows which kernels ran in every arm. Qwen3.5-0.8B bf16 on a Colab L4, torch 2.14.1+cu130, 3 alternating repeats per arm: | | Without causal-conv1d (zoo Triton) | With causal-conv1d (CUDA) | |---|---|---| | LoRA training, batch 4 x 1024, 30 timed steps | 911.5 ms/step (spread 11.2) | 917.5 ms/step (spread 15.9) | | Greedy decode, 256 new tokens, batch 1 | 19.3 tok/s (spread 0.6) | 19.0 tok/s (spread 0.2) | Both differences are inside the run-to-run spread. Without the package, single-token decode uses torch's `conv_depthwise2d`; with it, `causal_conv1d_update`. A tiny NemotronH also runs identically with a pure-Python mamba-ssm (the Mamba2 path never calls `selective_scan_cuda`), and a merged 16-bit export of a NemotronH LoRA works with neither kernel installed. ## Not covered here - `test_decision_native.py` / `test_decision_serving.py` were not collected locally (missing `fastmcp`). |
||
 Lee Jackson |
5c17163f41
|
Fix installer warning colors on light backgrounds (#13572)
* fix: align Python installer warnings with amber palette * Test installer warnings use the shell installer warning color --------- Co-authored-by: Daniel Han <23090290+danielhanchen@users.noreply.github.com> |
||
|
Long Yixing
|
48b4ca249d
|
Move the Unsloth Studio MLX pins to mlx-vlm 0.7.8 (#13699)
* chore(studio): raise the mlx-vlm ceiling to 0.7.8 mlx-vlm 0.7.8 adds a `datasets>=4.0.0` dependency with no upper bound, which brings datasets and its dependencies (pandas, pyarrow, aiohttp, ...) into the MLX self-heal's install. The self-heal installed with a bare `uv pip install --upgrade`, which re-resolves every transitive dependency to its newest release: on 0.7.8 that moved datasets 4.3.0 to 5.1.0 (past unsloth's `datasets<5.0.0`), pandas 2.3.3 to 3.0.6 and pyarrow 23 to 26, on top of the numpy and huggingface-hub upgrades it already made on 0.7.4. The self-heal now upgrades only the MLX packages by name, as the installer's MLX step does, so other dependencies move only when the MLX packages require it. The constraint file also holds the running datasets version beside transformers, so a resolve that has to move datasets fails instead of picking 5.x. * Cap datasets below 5 in the MLX self-heal when its metadata is missing * Tighten the MLX self-heal comments --------- Co-authored-by: Daniel Han <23090290+danielhanchen@users.noreply.github.com> |
||
|
Daniel Han
|
53199eaa1b
|
Studio installer (AMD, Linux): no generic ROCm torch for RDNA 1 / Polaris when the arch is readable (#13419)
* Studio installer (AMD, Linux): no generic ROCm torch for RDNA 1 / Polaris when the arch is readable * Tests: count the new install.sh advisory arm and the reshaped setup.sh report site * Report the uncovered arch in the install summary, and route setup.sh's report on a declared arch alone * Keep the old route under an HSA_OVERRIDE_GFX_VERSION spoof or a ROCR mask; real-probe shell cases * Judge a readable HSA_OVERRIDE_GFX_VERSION by the arch it names, not by being set * setup.sh: a kept ROCm torch is not reported as CPU-only |
||
|
Daniel Han
|
9f4a868d43
|
Studio setup: install causal-conv1d and mamba-ssm prebuilt wheels next to flash-attn (#13396)
* Studio setup: install causal-conv1d and mamba-ssm prebuilt wheels next to flash-attn Setup already installed flash-attn from prebuilt-wheels-cu13 but left causal-conv1d and mamba-ssm to the first Mamba / hybrid model load. Install both at setup through the same wheel-only install_kernel the CLI and SSM runtime use: never a source build, never a torch change, skipped where no wheel is published, GPU-gated for mamba-ssm, and resynced wherever flash-attn is after a torch repair. UNSLOTH_STUDIO_SKIP_SSM_KERNELS_INSTALL=1 opts out. * SSM kernel setup step: local check first, bounded probes, fresh runner, no-GPU install, stale removal Skip the wheel lookup when the resident kernel already loads, so an offline re-run does not wait on two HEAD requests. Each call gets its own runner, which bounds the import probes and resets install_kernel's per-runner GPU and Triton cache after a torch repair. Setup installs mamba-ssm where no GPU is visible yet (an image build); a visible pre-Ampere GPU still skips it. A resident build that no longer loads and has nothing replacing it is removed, as flash-attn's resync does. * SSM kernel setup step: honour UV_OFFLINE No wheel lookup and no install when uv is told to stay offline: the pip fallback in install_wheel does not read UV_OFFLINE. A kernel that already loads is still reported. * SSM kernel setup step: offline still removes a stale build; a probe that cannot launch is inconclusive * SSM kernel setup step: bound the torch probe on every platform and skip on a launch failure * SSM kernel setup step: an uninstall that cannot launch warns instead of aborting * Trim comments * SSM kernel setup step: redact captured install output before printing it install_kernel only replaces the wheel URL; uv / pip failure text or an exception can name another index carrying credentials. * Tests: pin the no-GPU mamba-ssm case to Linux so Windows' Triton gate does not answer first |
||
 Rudra Bhaskar |
135dca33cd
|
Studio: document the intentional torch and torchcodec floor gap (#10635)
* Studio: document the intentional torch and torchcodec floor gap * Test both shell floors and patch-version constraints * Tighten torch 2.4 torchcodec notes and check every install.sh floor --------- Co-authored-by: Daniel Han <23090290+danielhanchen@users.noreply.github.com> |
||
|
Daniel Han
|
10bddef22e
|
Studio: opt-in MLX image engine for Apple Silicon (Z-Image) (#13379) | ||
|
Daniel Han
|
55ff88ac00
|
Studio: torch 2.13 for new Linux aarch64 cu130 Python 3.13 installs, existing installs keep their torch (#13380)
* Take the cu130 torch 2.13 route on new Linux aarch64 installs too * cu130 2.13 route: needs glibc 2.35 and a GIL-enabled 3.13; aarch64 repairs keep only 2.10+ New installs on a host whose glibc is older than the kernel wheels' floor, or on a free-threaded interpreter (no cp313t torch 2.13), stay on the default range. Existing installs keep their release as before. A repair on aarch64 no longer pins a resident torch 2.9, which has no matching torchvision / torchaudio on the cu130 index. * Trim comments |
||
|
Daniel Han
|
3a1b694882
|
Studio: pair torch <= 2.8 with torchao 0.15 and gate torchao export on 0.15 (#13329)
* Studio: pair torch <= 2.8 with torchao 0.15.0 and gate torchao export on 0.15 transformers 5 and diffusers 0.41 refuse TorchAoConfig below torchao 0.15, so the portable FP8/INT8 export failed on torch <= 2.8 installs with a misleading "requires torchao to be installed". torchao 0.14.0 never loaded its C++ extensions on torch 2.6-2.8 either, so the older pin bought nothing. - install_python_stack: _TORCHAO_DEFAULT_SPEC 0.14.0 -> 0.15.0; existing installs are force-reinstalled on their next dependency pass. - torchao_export_loadable now rejects torchao < 0.15 on every platform (metadata only, no torchao import); export_capability asks it everywhere and the export backend names the installed version instead. * Studio torchao gate tests: drive the version through package metadata * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Studio torchao: keep 0.14 for torch <= 2.5 and compare export versions per PEP 440 * Studio torchao export gate: take the floor from the installed transformers * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci --------- Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com> |
||
|
Daniel Han
|
9c4c4a1cee
|
Studio: torch 2.13 for new Windows x64 cu130 Python 3.13 installs, existing installs keep their torch (#13263)
* Studio: torch 2.13 for new Windows x64 cu130 Python 3.13 installs, existing installs keep their torch Windows port of #12150. install.ps1 gives a new install torch 2.13 when the torch index is cu130, the machine and the venv interpreter are both x64, the venv is CPython 3.13, and the newest unsloth on PyPI admits torch 2.13 (no on UV_OFFLINE, UV_EXCLUDE_NEWER*, a configured uv index, or any fetch/parse failure; UNSLOTH_PYPI_JSON_URL points the check elsewhere). That is the only Windows route the prebuilt-wheels-cu13 kernel wheels can serve. Existing installs keep their release: on that route the preservation window widens to <2.15, every earlier layout (occupied venv, legacy .venv with or without a working interpreter, CWD-relative venv) counts as an existing home, and UNSLOTH_TORCH_UPGRADE=1 opts in. An upgrade with the route closed keeps a resident release above the default range instead of moving it down. A kept torch 2.12+ now pairs with torchaudio 2.11 (the last release) in install.ps1 and in setup.ps1's kept-release paths. setup.ps1 picks the triton-windows minor from the installed torch (2.13 -> 3.7, 2.14 -> 3.8, otherwise <3.7; Windows on ARM unchanged). install_python_stack.py's repair specs and core-update torch freeze cover native Windows x64 as well as Linux. * install.ps1: keep an occupied venv's torch from version.py when its interpreter cannot answer * Windows: the missing-Triton hint names the triton-windows range for the resident torch * Keep the CWD-relative legacy venv's torch on migration; Windows-on-ARM Triton hint * Trim comments in the Windows torch 2.13 install route * Keep the resident torch on every Windows repair path: forced setup reinstall, migrated venv, CWD venv without python.exe; bounded fallback; UV_OFFLINE through Test-UvEnvFlag * Gate the cu130 torch 2.13 route on --package unsloth and ignore prerelease resident torch * Skip the core-update torch freeze when the override path cannot be made space-free; match --package unsloth case-insensitively in install.sh * Never let a setup or update retry move torch to another release; keep the resident torch on unforced setup runs * Keep the torch freeze file user-private and pin a resident torch only within the index's published range * Give the Windows torch freeze file a current-user-only ACL; freeze emulated x64 venvs on Windows on ARM too |
||
|
Daniel Han
|
14ad75e857
|
Studio: install prebuilt flash-attn, causal-conv1d and mamba-ssm wheels on Windows and ARM (#13262)
* Studio: install prebuilt flash-attn, causal-conv1d and mamba-ssm wheels on Windows Windows x64 resolves to our win_amd64 builds on prebuilt-wheels-cu13 (upstream naming, cxx11abiFALSE, cp313, torch 2.13 / 2.14 cu13). Windows on ARM resolves flash-attn to NVIDIA's Flash-Attention-for-WoA wheel for torch 2.14, pinned by a #sha256= fragment that uv and pip both verify. Windows is wheel-only everywhere: no upstream name is ever built (no upstream release has a Windows asset) and a missing or rejected wheel never falls back to a PyPI source build. Setup, long-context training, the causal-conv1d fast path and its lazy hook, SSM inference and install-kernels all take the Windows path; mamba-ssm on Windows first requires an importable triton. Linux URLs are unchanged. * Windows wheels are cxx11abiTRUE: the Windows cu130 torch reports the flag as True * Bound the Windows flash-attn setup probe like its import probe * install-kernels: Windows mamba_ssm waits for Triton; rejected-wheel log says what Windows does * Trim comments in the Windows kernel wheel install paths * Re-check flash-attn when the Windows torch flavor invariant replaces torch * Resolve the linux_aarch64 and win_arm64 prebuilt kernel wheels |
||
 alkinun |
6d7c6e962d
|
Studio installer: drop a flash-attn built for a torch that is gone, and pair torch 2.9 with torchao 0.15.0 (#13247)
* Studio installer: drop a flash-attn built for a torch that is gone The Linux torch repair (step 13) runs after the flash-attn step. When it moves torch, e.g. from 2.12+cu130 to 2.9+cu126 on a CUDA-12 driver, the cu13torch2.10 wheel the earlier step installed can no longer import. The repair re-selected torchao and evicted a mismatched xFormers, but never looked at flash-attn. Later passes did not heal it either: _ensure_flash_attn only removed a copy it had just installed itself. With no wheel for the new torch (flash-attn v2.8.3 ships no cu12/torch2.9/cp313 asset) it warned and kept the broken one. xformers imports flash_attn whenever find_spec sees it, so every diffusers pipeline then failed with "libcudart.so.13: cannot open shared object file". - Re-run _ensure_flash_attn when the step 13 repair moves torch. - A resident flash-attn that does not import, under a torch that does, is removed when no working wheel replaces it, and force-replaced when one does (a same-version build for another CUDA otherwise counts as installed). Fixes #13244 (flash-attn half). * Studio installer: pair torch 2.9 with torchao 0.15.0 diffusers 0.41.0 imports torchao.quantization.FqnToConfig whenever torchao is installed, and FqnToConfig first shipped in torchao 0.15.0. torch 2.9 hosts got 0.14.0, so once a broken flash-attn was out of the way, every diffusers pipeline still failed to import with "cannot import name 'FqnToConfig'". transformers 5's TorchAoConfig has the same 0.15 floor. 0.15.0 is also the build for this torch: its C++ extensions target torch 2.9.1, while 0.14.0 targets 2.8.0 and skipped them on every 2.9 release. It is published on every download.pytorch.org leaf that serves torch 2.9 (cu126, cu128, cu129, cu130, rocm6.3, rocm6.4, xpu, cpu), which also closes the cu129 gap, where only 0.14.1 existed. torch <= 2.8 keeps 0.14.0. Fixes #13244 (torchao half). * Trim comments in PR scope --------- Co-authored-by: mahiatlinux <mahiatlinux@users.noreply.github.com> |
||
|
Daniel Han
|
e31a08032a
|
install.sh: install XPU PyTorch on Linux when an Intel Arc / Data Center GPU is the only GPU (#13193)
* install.sh: install XPU PyTorch on Linux when an Arc / Data Center GPU is the only GPU * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * XPU auto route: yield to an added NVIDIA/AMD GPU, force the update pass on a stale XPU wheel, honour an emptied ZE_AFFINITY_MASK, report an unexpressible repair * XPU auto route: decline under any ZE_AFFINITY_MASK, revalidate the Intel GPU before replaying a recorded XPU flavor * XPU auto route: decline under SYCL device filters, match PVC by exact id (not Cedar Trail), Windows-safe fake PCI names * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * XPU auto route: add PTL Arc Pro ids 0xB084-0xB087, treat an empty or "default" ZE_AFFINITY_MASK as unset Mesa (iris_pci_ids.h) names 0xB084-0xB087 Arc Pro B390/B370, the kernel binds them under xe, and compute-runtime lists them (unnamed). Level Zero skips the mask when it is empty or "default" (compute-runtime isAffinityMaskSet), so every Intel GPU stays visible there. * XPU auto route: honour a stated xpu backend, decline under SYCL_DEVICE_ALLOWLIST, record the opt-out as a deliberate CPU choice * XPU auto route: read sysfs as utf-8 and apply the repo's ruff kwarg format * XPU auto route: record the opt-out as deliberate CPU whatever device selectors are set * Trim comments --------- Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com> |
||
 Natani L. Mayday |
267f03500f
|
Unsloth Studio installer (AMD/Linux): use ROCm 6.4 PyTorch on ROCm 6.0 to 6.3 so bitsandbytes training doesn't crash (#10277)
* fix(studio): floor automatic ROCm torch to BNB compatibility * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * test(studio): align ROCm routing coverage with BNB floor * fix(install): normalize the gfx probe before the gfx906 BNB-floor exemption _probe_amd_gfx_arch emits one token per rocminfo match and rocminfo names each agent twice, so a single MI50 reads back as gfx906\ngfx906; an UNSLOTH_ROCM_GFX_ARCH override keeps its ISA suffix. Comparing that raw string against the literal gfx906 never matched on real hardware, so the exemption did not fire and the host was floored to rocm6.4, which the legacy reroute then rewrote to rocm6.3 rather than leaving the literal rocm6.0-6.3 tag in place. Strip the suffix and dedupe before the comparison, matching _is_gfx906_bnb_skip and the legacy reroute block. Deduping also yields the sole-distinct-arch rule: a mixed gfx906 host keeps the generic floor. Covers the shape real discovery produces, which the single-token amd-smi mock could not: rocminfo-driven gfx906 at one and two agents, a suffixed override, a gfx1100 host that must still floor, and a mixed host. * Skip Radeon repo wheels that cannot run torch.compile on the venv Python With the rocm6.4 floor, a Radeon card on ROCm 6.0-6.3 now takes the repo.radeon.com rocm-rel-6.4 route. That listing carries torch 2.5.1 as its only cp313 build, and a fresh Linux install creates a Python 3.13 venv, so the install finished but the first training step failed with "Dynamo is not supported on Python 3.13+". Reproduced on AMD CI in rocm/dev-ubuntu-22.04 6.1.2 and 6.3.4 containers. torch.compile reached Python 3.13 in torch 2.6 and 3.14 in 2.10. When the matched Radeon set is older than that for the venv's Python, fall back to the ROCm index, which has torch 2.9.1 for cp313 at rocm6.4. This also covers hosts already on ROCm 6.4, which hit the same listing. * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Extract the BNB floor helper in the bad-arch gate harness test_rocm_bad_arch_gate.sh builds get_torch_index_url from a fixed helper list. The ROCm leaf now goes through _rocm_bnb_compatible_generic_tag, so without it the harness returned an empty leaf and the version-keyed cases failed; its ordering check also looked for the old echo form. * Pin IS_WINDOWS in the AMD fast-path probe host stub On a Windows runner the module reads sys.platform as win32, so _ensure_rocm_torch took its Windows branch and the stubbed Linux host installed nothing. * Floor generic ROCm torch only for a known non-gfx906 target An unreadable arch, or a gfx906 that only the KFD topology names, was moved to rocm6.4, which has no gfx906 BLAS kernels. Use the same predicate as the repair path: floor only when the selected runtime target is known and is not gfx906, otherwise keep the literal tag, as install.sh does. Also pin IS_MACOS in the AMD fast-path probe host stub. * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Lift the BNB floor helper into the explicit-request shell harness get_torch_index_url floors its generic leaf through _rocm_bnb_compatible_generic_tag; the harness extracted the selector without it, so the substitution was empty and every generic pick read as a bare .../whl/ index. * Tighten BNB-floor comments and drop dead locals Trim the gfx906 normalisation comment in get_torch_index_url, wrap the _radeon_torch_compiles_for_pytag comment, correct a comment that claimed the tag-selection predicate matched the repair, remove the never-read _selected_match parse, and drop three initialisers only read inside the block that assigns them. No behaviour change. --------- Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com> Co-authored-by: Daniel Han <danielhanchen@gmail.com> Co-authored-by: LeoBorcherding <borchborchmail@gmail.com> |
||
|
oobabooga
|
8f389e6151
|
Studio: repair ROCm attention packages and bound Qwen-Image-2.1 math prefill (#13115)
* Studio: repair ROCm attention packages and bound Qwen-Image-2.1 math prefill * Hide ROCm probe consoles and overlap fused backend checks * Restore guard-disabled ROCm SDPA flags when a healthy card loads * Decode ROCm probe output as UTF-8 and update the RDNA1 device pack test * Force UTF-8 stdio in the ROCm probe child * Pin stubbed SDPA probe tests to the probe result, not ambient process flags * Trim restating comments in ROCm attention recovery * Apply the ROCm SDPA guard again when a retried probe completes * Bootstrap ROCm DLL dirs in SDPA probe children, throttle incomplete retries, keep torch-free diagnostics * Let setup.ps1's fast path run the ROCm device pack repair * Apply the ROCm SDPA guard wherever a half-precision probe completes * Drop a redundant comment * Keep utf8_child_env inline in the SDPA probe call --------- Co-authored-by: Daniel Han <23090290+danielhanchen@users.noreply.github.com> |
||
|
Daniel Han
|
7730160ab2
|
Studio: install the released Diffusers 0.41.0 instead of the pinned main commit (#13045)
* Studio: install the released Diffusers 0.41.0 instead of the pinned main commit * Studio tests: cover the released Diffusers pin and the commented-out main build * Studio: keep plain Krea 2 single files on Studio's loader under diffusers 0.41 * Studio: prefetch the Diffusers release before the startup repair installs it * Studio tests: read the release prefetch's requirement before Windows ARM64 filtering * Studio: release-mode self-heal touches index installs only; a missing or damaged Diffusers still forces the pass * Studio: keep Studio's Krea 2 / HunyuanImage converters ahead of diffusers' own * Studio: tighten the comments added for the Diffusers 0.41.0 move * Studio: shorten the diffusers pin file headers * Studio: release repair keeps user builds, prefetches under the install's constraints, and upgrades index prereleases * Studio: trim the test and installer comments after review |
||
|
Daniel Han
|
2622a5d07d
|
Studio: share one kernel install core with unsloth install-kernels (#12828)
* Share one kernel install core across Studio setup, training, chat and install-kernels * Test the shared kernel install helpers * Pass pinned kernel fields explicitly in the SSM runtime * Route setup's remaining uninstall through the shared command * Trim comments in the shared kernel install changes * Drop redundant comments in the kernel install changes * Shorten kernel install module docstrings |
||
|
Daniel Han
|
e54e4fa81e
|
Studio (AMD, Windows): pin the multi-arch ROCm torch to rocm7.14.0, whose fused attention works (#12670)
* Studio (AMD, Windows): pin the multi-arch ROCm torch to rocm7.14.0, whose fused attention works * Standalone repair: replace a rocm7.14.1 multi-arch build instead of keeping it * Tighten rocm7.14.0 pin comment |
||
|
Daniel Han
|
eaef459e86
|
Studio: torch 2.13 for new Linux cu130 Python 3.13 installs, existing installs keep their torch (#12150)
* Studio: install torch 2.13 on new Linux cu130 Python 3.13 installs, keep existing torch The prebuilt-wheels-cu13 release ships flash-attn, causal-conv1d and mamba-ssm for torch 2.13 and 2.14 on cp313 linux_x86_64 cu13. New installs on exactly that route now get torch 2.13 (the release vLLM and SGLang pin) with torchvision 0.28 and torchaudio 2.11. Every other route keeps its window unchanged. Existing installs keep their torch: the kept-release pin is evaluated against its own 2.4-2.14 window instead of the new-install spec, the kept pairing asks for torchaudio 2.11 once the torch minor is past it, and studio update repairs on the cu130 route reinstall the resident release rather than a range. * Studio: only default to torch 2.13 once PyPI unsloth admits it; freeze torch >= 2.13 through core updates studio update first runs the setup code of the installed release, which upgrades unsloth under its own torch cap: with 2026.9.11 (torch<2.13.0) a torch 2.13 install was swapped for PyPI's generic 2.12.1 and lost its prebuilt kernels. The 2.13 route now also requires the newest unsloth on PyPI to admit torch 2.13, answering no on any fetch or parse failure, and the core package update pins a resident torch >= 2.13 via UV_OVERRIDE the way install.sh already does for every unsloth install. * Tighten the torch 2.13 route comments * Keep only cu130-served torch on repair; never let pip or an inherited override undo the update freeze * Size the preservation window from the local route alone; keep relative override includes resolvable * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Keep the old torch window when a uv upload-date cutoff is set * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Repair to the default range when no resident release is keepable, leaving 2.13 to install.sh's gate * Stand the torch 2.13 gate down offline and on any configured package index * Drop a duplicated torchaudio comment * Give torch 2.13 only to a fresh home: record legacy-layout torch, never fall back to or default into 2.13 for an existing install * Treat a legacy .venv with a broken interpreter as an existing install * Desktop: manual Repair installation moves to the newest supported PyTorch * install.sh: an upgrade with the 2.13 route closed keeps a resident torch above the default range --------- Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com> |
||
|
alkinun
|
150e6df033
|
Studio: keep PyTorch mirror leaves out of query tokens (#10546)
Route every PyTorch mirror leaf through _pytorch_whl_leaf_url so a mirror carrying its credential in a query or fragment never gets the accelerator leaf glued into the token. A repair that the mirror cannot express aborts instead of installing from a mangled URL or leaving the mirror; path-only mirrors and full UNSLOTH_TORCH_INDEX_URL values are unchanged. Closes #10516. |
||
 xiao |
0dd7dfc21b
|
Remove xFormers built for another torch after Linux repair (#11783)
* Remove xFormers built for another torch after Linux repair (#11639) * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Only remove xFormers after the Linux repair when the torch family changed PyPI's xFormers 0.0.35 is built for 2.10.0+cu128 and loads its extension under 2.11.0+cu130 (stable ABI since 0.0.34), so an exact build-string compare removed a working xFormers from every CUDA install. Compare cuda / rocm / xpu / cpu instead. * Tighten the xFormers eviction comments * Treat a CUDA major change as a different xFormers build family xFormers' _C.so links libcudart.so.<major>; a cu130 torch ships only the CUDA 13 runtime, so a cu128 build cannot load there unless a system CUDA 12 runtime happens to be on the loader path. * Shorten the xFormers eviction docstring --------- Co-authored-by: Wangxiaoxiaoa <Wangxiaoxiaoa@users.noreply.github.com> Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com> Co-authored-by: Daniel Han <23090290+danielhanchen@users.noreply.github.com> |
||
|
Long Yixing
|
f07d552fcc
|
Move the Unsloth Studio MLX pins to mlx 0.32.3 and mlx-vlm 0.7.4 (#12334)
* build(studio): move the MLX pins to mlx 0.32.3 and mlx-vlm 0.7.4 The Unsloth Studio installer pins the MLX stack it installs separately from unsloth-zoo's pyproject, and its own note says to keep the two in sync. unsloth-zoo is raising its ceiling to mlx-vlm 0.7.4 and its mlx pin to 0.32.3, so the installer and the self-heal move with it: `mlx` and `mlx-metal` to `==0.32.3`, `mlx-vlm` to `>=0.4.4,<=0.7.4`, `mlx-lm` unchanged. mlx 0.32.3 fixes the GQA-8 decode attention kernel that 0.32.2 introduced, which read the first sequence's keys and values for every row of a long-context batch (mlx#4431), the case batched chat generation hits. It publishes the same wheels as 0.32.2 (macOS 14, 15 and 26 on arm64, CPython 3.10 and newer), so the minimum macOS and Python gates are unchanged. mlx-vlm 0.7.4 raises its mlx-audio floor to 0.5.2, which Unsloth Studio does not import directly. Both installer paths already intersect the mlx-vlm range with what the installed unsloth-zoo declares, so this should land after an unsloth-zoo release carrying the matching pins; until then the range stays where that zoo allows it. The Unsloth Studio MLX backend tests pass unchanged on mlx 0.32.3 + mlx-vlm 0.7.4 and on mlx 0.32.2 + mlx-vlm 0.7.1. * Shorten the MLX self-heal pin rationale comment --------- Co-authored-by: Daniel Han <23090290+danielhanchen@users.noreply.github.com> |
||
 Leo Borcherding |
f00582ab29
|
Unsloth Studio installer (AMD/Windows): install PyTorch for RX 5000 to 9000 cards from AMD's multi-arch index (#11846)
* Windows installers: route RDNA 1 (gfx1010/1011/1012) to AMD's multi-arch nightly index RDNA 1 has no family on repo.amd.com, so every Windows installer put an RX 5700 XT on CPU torch and said so (#8529). AMD's multi-arch nightly index carries per-card kernel packs for it: `torch[device-gfx1010]` resolves torch plus the gfx1010 pack. With that torch, #11615 and the zoo's #1356 / #1316, the card trains (#11614). install_python_stack.py, install.ps1 and setup.ps1 now route gfx1010 / gfx1011 / gfx1012 to that index, pinned to one tag (a nightly moves), with torchvision on the same tag and no torchaudio (none is published for it). The three RDNA 1 rows move from the "not covered" name tables to the routed ones on the Windows copies; the backend's copy follows. Linux is unchanged: nothing has run that route on bare-metal Linux, and WSL2's GPU driver refuses RDNA 1 outright. Tests: the #8529 suites now exercise the "not covered" wording with Polaris (RX 580, gfx803), which still owns it everywhere; the routing guards keep RDNA 1 banned on Linux and assert the Windows route; the parity test accepts a multi-arch device as routable on the Windows copies only; a new file pins the package specs, the index, the name tables and the PowerShell mirrors. * Expect the RX 5700 XT to resolve in the Windows name tables now that it routes * Drop a torchaudio built against another torch after the multi-arch install The multi-arch index publishes no torchaudio, so the one left by an earlier CPU or per-family pass is linked against a torch that is gone and throws a Windows "Entry Point Not Found" dialog when anything imports it. Seen on the first fresh install from this branch: torch 2.12.0+rocm10.2 next to torchaudio 2.11.0+rocm7.13. Remove it after the multi-arch pass; a torchaudio carrying the pinned tag, should AMD publish one, stays. * Pin that a lone RDNA 1 host takes the Vulkan llama.cpp route * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Run the stale-torchaudio cleanup on every path that ends with the multi-arch torch setup.ps1 and install.ps1 install the pair themselves and set the marker that makes the python repair return early, so the cleanup there never ran on a fresh install (seen: torchaudio 2.11.0+rocm7.13.0 still present after the multi-arch pass). Do it in the two PowerShell installers right after their trio lands, and in the python marker shortcut when the installed torch carries the multi-arch tag. * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Give the Windows final step the last word on torchaudio in a multi-arch venv The dependency pass re-resolves torchaudio 2.11.0 on every run: torch-stoi and descript-audiotools require it unconditionally and nothing exists for the pinned torch (AMD's index lists no torchaudio for the tag, PyPI stops at 2.11.0). The cleanups that run right after the trio install therefore lose to step 8. Run it once more at the end of the Windows flow, after every with-deps step. * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Stop removing torchaudio: 2.11 works beside the multi-arch torch 2.12 Measured on the RX 5700 XT venv the installer built: torchaudio 2.11.0 next to torch 2.12.0+rocm10.2 imports, resamples, computes a mel spectrogram and loads torch-stoi, with no dialog. The dependency pass installs it (torch-stoi and descript-audiotools require it; PyPI stops at 2.11.0 and AMD's index has none), and taking it out again only lost audio features. The pinned trio still lists no torchaudio, which is what the index needs; the rest is left to the resolver. * RDNA 1 on Windows: install from AMD's stable multi-arch index, not the nightly repo.amd.com/rocm/whl-multi-arch publishes the same per-device packaging as the nightly, on release tags: torch 2.11.0+rocm7.14.1 with the gfx1010/1011/1012 device packs, torchvision 0.26.0 and torchaudio 2.11.0 on the same tag. Measured on an RX 5700 XT: resolves in one go, fp16 matmul correct, Triton unchanged (buffer ops still need #11615), and the 3-step LoRA/QLoRA rows on Qwen3.5-0.8B and Qwen3-1.7B match the nightly to the fourth decimal. So the route pins that release instead of a nightly date: the index also serves 2.12.0, which sits on the <2.12.0 window the rest of the Windows install applies, so 2.11.0 is the newest release inside it. torchaudio goes back into the trio and the empty-audio-slot handling ($RocmNoAudio, the trio filter) goes away. * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Windows AMD trio: pass the three specs plainly again, and anchor the repair tests on the helper torchaudio is back in the multi-arch trio, so the empty-slot filter on install.ps1's three ROCm trio commands has nothing to filter; the plain form is what the pr5940 follow-up tests read. The two cuda_repair tests looked for the inline _WINDOWS_ROCM_TORCH_PKG_SPECS.get in _ensure_rocm_torch, which now calls _windows_rocm_torch_pkg_specs; they anchor on that call. * Windows repair site: do not call _bare_gfx() where the function shadows it _ensure_rocm_torch binds a local named _bare_gfx further down, so the multi-arch message calling the module helper raised UnboundLocalError on the Windows repair path for a gfx1010 host with a CPU torch. Inline the bare-arch spelling there and run that site in a test. * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * RDNA 1 route: count it as covered in the two gates outside the route, and move the wheel-less fixtures to Polaris The backend's repairability check and setup.ps1's pre-Intel "AMD gets GPU wheels" gate both read a list that still omitted gfx1010-1012, so a 5700 XT on Windows could not establish a torch mismatch and lost to an Intel Arc on a mixed host. The backend gains a Windows-only extension of the supported set (Linux still declines RDNA 1); setup.ps1's list gains the three arches. Tests that used the RX 5700 XT / gfx1010 as the card with no Windows wheels move to Polaris (RX 580 / gfx803); the Linux-only parity tests learn that RDNA 1 names are unsupported on the Linux copies and routed on the Windows copies. * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Unsloth Studio (AMD/Windows): install every RDNA arch from AMD's stable multi-arch index repo.amd.com/rocm/whl-multi-arch has a per-device kernel pack for every RDNA arch at the release tag #11755 pins (2.11.0+rocm7.14.1, torchvision 0.26.0, torchaudio 2.11.0 on the same tag). The per-family Windows indexes stop one ROCm release earlier, an exact pin has nothing for the kept-release rule to keep (#11814), and per-device packs are smaller than family bundles. So the RDNA 1 route becomes the route for RDNA 1 through 4 (gfx1153 included, gfx1033 and CDNA stay on their family), in the python repair and both PowerShell installers. The family map stays: a host mirroring the family layout (UNSLOTH_ROCM_WINDOWS_MIRROR, no multi-arch mirror) keeps the family route for arches that have one, and the stale/mismatch classifiers still read families off the installed runtime. The trio is derived from the index that was chosen, so it can never name a build the index does not serve. Measured on an RX 6500 XT (gfx1034) and, via #11755, an RX 5700 XT (gfx1010). RDNA 3 / 3.5 / 4 are the same build and shape, unmeasured; draft until someone runs it. Part of #11815. * Bundle-coverage test: anchor the family-map regex on its definition line * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Tests: expect main's per-arch torch floors on the family route * Trim comments added by the multi-arch route * Install torchvision's device pack on the multi-arch route Bare torchvision from repo.amd.com/rocm/whl-multi-arch carries no GPU kernels: torchvision.ops.nms raised hipErrorInvalidDeviceFunction on a gfx1151 (Radeon 8060S, Windows 11). torchvision[device-gfxNNNN] pulls amd-torchvision-device-gfxNNNN, which resolves for every routed arch. * Count gfx1153 as a Windows ROCm arch in the backend The installers route gfx1153 to the multi-arch index, but the backend's supported set stopped at gfx1152, so a gfx1153 host left on CPU torch never qualified for the mismatch repair. Add a parity test against _WINDOWS_MULTIARCH_GFX, and correct the _index_is_multiarch docstring: explicit unknown-family pins are installed verbatim and never reach it. * Repair a swapped card on a multi-arch ROCm install The multi-arch build names no rocm-sdk-libraries family, so the Windows repair's family comparison reads None and never reinstalls after a card swap, leaving torch with no kernels for the new GPU. Check the installed amd-torch-device / amd-torchvision-device packs for the routed arch instead. Legacy per-family installs are left to the family check. * Trim comments restating the multi-arch code * Keep a multi-arch mirror's query token intact Appending the index slash after the whole URL put it inside a ?token= query on an authenticated mirror. Split on ? / # first, as _index_url_join does for the family indexes; plain URLs are unchanged. * Recognise a query-token multi-arch mirror by its path _index_is_multiarch compared whole URLs, so https://m/whl-multi-arch?token=x never matched its own resolved form (.../whl-multi-arch/?token=x) and the repair installed the trio without device extras. Compare path parts only. --------- Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com> Co-authored-by: Daniel Han <23090290+danielhanchen@users.noreply.github.com> |
||
 Nilay |
b84349a1f8
|
Studio: keep working when GitHub rate limits or is down (#10670)
Anonymous GitHub API calls are limited to 60 an hour per IP. When that limit hit, the update banner, the llama.cpp changelog, release notes, the sd.cpp installer and the prebuilt wheel probes failed or misreported. - A 403/429 that GitHub explains as throttling (429, Retry-After, X-RateLimit-Remaining: 0, or a rate-limit body) records one process-wide lockout until the reset, capped at an hour; a plain permission 403 records nothing. The freshness check, changelog and release notes honour it. - Release notes send GITHUB_TOKEN / GH_TOKEN to https://api.github.com only, as an unredirected header. - url_exists returns None when availability cannot be checked, so a refusal is no longer reported as "no published wheel"; callers still take their fallback path. - The sd.cpp installer stops at the first rate-limited release lookup and says how to lift the limit, instead of trying every fallback repo. - The llama.cpp installer resolves the diffusion visual server from the approved checksum manifest instead of listing release assets over the API. |
||
|
Leo Borcherding
|
79ba3eacfc
|
Unsloth Studio (AMD RDNA 1, Windows): install ROCm torch for the RX 5700 XT from AMD's multi-arch index (#11755)
* Windows installers: route RDNA 1 (gfx1010/1011/1012) to AMD's multi-arch nightly index RDNA 1 has no family on repo.amd.com, so every Windows installer put an RX 5700 XT on CPU torch and said so (#8529). AMD's multi-arch nightly index carries per-card kernel packs for it: `torch[device-gfx1010]` resolves torch plus the gfx1010 pack. With that torch, #11615 and the zoo's #1356 / #1316, the card trains (#11614). install_python_stack.py, install.ps1 and setup.ps1 now route gfx1010 / gfx1011 / gfx1012 to that index, pinned to one tag (a nightly moves), with torchvision on the same tag and no torchaudio (none is published for it). The three RDNA 1 rows move from the "not covered" name tables to the routed ones on the Windows copies; the backend's copy follows. Linux is unchanged: nothing has run that route on bare-metal Linux, and WSL2's GPU driver refuses RDNA 1 outright. Tests: the #8529 suites now exercise the "not covered" wording with Polaris (RX 580, gfx803), which still owns it everywhere; the routing guards keep RDNA 1 banned on Linux and assert the Windows route; the parity test accepts a multi-arch device as routable on the Windows copies only; a new file pins the package specs, the index, the name tables and the PowerShell mirrors. * Expect the RX 5700 XT to resolve in the Windows name tables now that it routes * Drop a torchaudio built against another torch after the multi-arch install The multi-arch index publishes no torchaudio, so the one left by an earlier CPU or per-family pass is linked against a torch that is gone and throws a Windows "Entry Point Not Found" dialog when anything imports it. Seen on the first fresh install from this branch: torch 2.12.0+rocm10.2 next to torchaudio 2.11.0+rocm7.13. Remove it after the multi-arch pass; a torchaudio carrying the pinned tag, should AMD publish one, stays. * Pin that a lone RDNA 1 host takes the Vulkan llama.cpp route * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Run the stale-torchaudio cleanup on every path that ends with the multi-arch torch setup.ps1 and install.ps1 install the pair themselves and set the marker that makes the python repair return early, so the cleanup there never ran on a fresh install (seen: torchaudio 2.11.0+rocm7.13.0 still present after the multi-arch pass). Do it in the two PowerShell installers right after their trio lands, and in the python marker shortcut when the installed torch carries the multi-arch tag. * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Give the Windows final step the last word on torchaudio in a multi-arch venv The dependency pass re-resolves torchaudio 2.11.0 on every run: torch-stoi and descript-audiotools require it unconditionally and nothing exists for the pinned torch (AMD's index lists no torchaudio for the tag, PyPI stops at 2.11.0). The cleanups that run right after the trio install therefore lose to step 8. Run it once more at the end of the Windows flow, after every with-deps step. * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Stop removing torchaudio: 2.11 works beside the multi-arch torch 2.12 Measured on the RX 5700 XT venv the installer built: torchaudio 2.11.0 next to torch 2.12.0+rocm10.2 imports, resamples, computes a mel spectrogram and loads torch-stoi, with no dialog. The dependency pass installs it (torch-stoi and descript-audiotools require it; PyPI stops at 2.11.0 and AMD's index has none), and taking it out again only lost audio features. The pinned trio still lists no torchaudio, which is what the index needs; the rest is left to the resolver. * RDNA 1 on Windows: install from AMD's stable multi-arch index, not the nightly repo.amd.com/rocm/whl-multi-arch publishes the same per-device packaging as the nightly, on release tags: torch 2.11.0+rocm7.14.1 with the gfx1010/1011/1012 device packs, torchvision 0.26.0 and torchaudio 2.11.0 on the same tag. Measured on an RX 5700 XT: resolves in one go, fp16 matmul correct, Triton unchanged (buffer ops still need #11615), and the 3-step LoRA/QLoRA rows on Qwen3.5-0.8B and Qwen3-1.7B match the nightly to the fourth decimal. So the route pins that release instead of a nightly date: the index also serves 2.12.0, which sits on the <2.12.0 window the rest of the Windows install applies, so 2.11.0 is the newest release inside it. torchaudio goes back into the trio and the empty-audio-slot handling ($RocmNoAudio, the trio filter) goes away. * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Windows AMD trio: pass the three specs plainly again, and anchor the repair tests on the helper torchaudio is back in the multi-arch trio, so the empty-slot filter on install.ps1's three ROCm trio commands has nothing to filter; the plain form is what the pr5940 follow-up tests read. The two cuda_repair tests looked for the inline _WINDOWS_ROCM_TORCH_PKG_SPECS.get in _ensure_rocm_torch, which now calls _windows_rocm_torch_pkg_specs; they anchor on that call. * Windows repair site: do not call _bare_gfx() where the function shadows it _ensure_rocm_torch binds a local named _bare_gfx further down, so the multi-arch message calling the module helper raised UnboundLocalError on the Windows repair path for a gfx1010 host with a CPU torch. Inline the bare-arch spelling there and run that site in a test. * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * RDNA 1 route: count it as covered in the two gates outside the route, and move the wheel-less fixtures to Polaris The backend's repairability check and setup.ps1's pre-Intel "AMD gets GPU wheels" gate both read a list that still omitted gfx1010-1012, so a 5700 XT on Windows could not establish a torch mismatch and lost to an Intel Arc on a mixed host. The backend gains a Windows-only extension of the supported set (Linux still declines RDNA 1); setup.ps1's list gains the three arches. Tests that used the RX 5700 XT / gfx1010 as the card with no Windows wheels move to Polaris (RX 580 / gfx803); the Linux-only parity tests learn that RDNA 1 names are unsupported on the Linux copies and routed on the Windows copies. * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Trim comments in RDNA 1 multi-arch route * Drop RDNA 1 from comments that still call it unroutable on Windows * RDNA 1 route: follow #11834's gfx1034 specs, strip HIP suffixes from the gfx override, reinstall a per-family build on a now-RDNA 1 host - test_other_arches_keep_their_specs compares gfx1034 against _WINDOWS_ROCM_TORCH_PKG_SPECS; #11834 pinned the gfx103X family, so bare names no longer apply. - setup.ps1 and install.ps1 drop a ":xnack-" style suffix from UNSLOTH_ROCM_GFX_ARCH before routing, as the Python resolver already does. - A standalone studio update on a venv holding a per-family ROCm torch reinstalls from the multi-arch index when the card is RDNA 1 and its amd-torch-device pack is missing. * Pin the RDNA 1 repair and override fixes with tests, fix the gfx1034 spec test The gfx1034 update described in b3efb0c was not in that commit; the test still expected bare package names that main no longer returns. * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Trim comments on the RDNA 1 multi-arch route --------- Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com> Co-authored-by: Daniel Han <23090290+danielhanchen@users.noreply.github.com> |
||
|
Daniel Han
|
7b07d86099
|
Unsloth Studio (AMD/Windows): real torchao INT8 / FP8 export on Windows ROCm (#7102)
* Studio: don't offer torchao INT8/FP8 export on Windows ROCm (torchao unavailable) torch.distributed is unsupported on Windows ROCm, so real torchao cannot import and Studio import-stubs it; the stub's config classes return None, so TorchAoConfig(quant_type=None) crashed exports with 'quant_type must be either a string or an AOBaseConfig instance, got NoneType'. Gate the portable torchao FP8/INT8 path off on Windows ROCm via a shared is_win32_rocm() helper (used by both the import stub and the export gate so they can't drift), and add an early defensive error in export_merged_model so a forced torchao request fails fast with a clear message instead of the cryptic crash. The Export UI also hides torchao and stops claiming it works there. No change on Linux, macOS, or Windows CUDA (torchao is real); Windows ROCm users keep 16-bit merged and GGUF quantization. * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Studio: address review on torchao Windows-ROCm gate Normalize the requested alias through unsloth's torchao normalizer before the gate, so equivalent forms (portable_fp8, hyphen/space variants) also hit the clear Windows-ROCm rejection instead of being misclassified as compressed-tensors. Remove frontend/backend detection drift: expose win32_rocm (mirrors is_win32_rocm(): hip OR a rocm build tag) in the export capability payload and have the Export UI read it, instead of re-deriving Windows ROCm from versions.rocm (unset on AMD SDK wheels). Prune already-selected formats when the gate flips, so a stale torchao pick made before hardware resolves is not exported. Register the stub meta_path finder only once. Use an explicit None check for the stub sentinel. Tighten comments. * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Add torchao Windows-ROCm import shim to import_fixes Legacy Windows ROCm PyTorch wheels ship without the torch.distributed C-extension, so importing torchao crashes at `from torch._C._distributed_c10d import (...)` with "No module named 'torch._C._distributed_c10d'". That makes torchao completely unimportable and disables FP8/INT8 weight-only export. fix_torchao_windows_rocm_import() installs a capability-gated compatibility shim: it registers the version-exact _c10d_functional op schemas via a FRAGMENT library plus a fake torch._C._distributed_c10d module, then runs `import torchao` as an in-transaction acceptance test with atomic rollback. It fires only on the exact broken config (win32 + torch.version.hip + real torchao installed + distributed C-extension genuinely absent + no _c10d_functional dispatcher ops) and is a strict no-op everywhere else, including on fixed wheels (ROCm/TheRock#5694). Opt out with UNSLOTH_DISABLE_TORCHAO_ROCM_SHIM=1. Wired into _gpu_init before importing unsloth_zoo so the zoo torchao stub self-disables once real torchao is importable. Adds drift tests that pin the schema table to the live dispatcher and assert the no-op, guard, FRAGMENT, and rollback invariants. * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Fix torchao Windows-ROCm shim: define _dtensor schema and match is_win32_rocm detection Address two review findings on the shim. torchao's `from torch.distributed._tensor import DTensor` loads torch.distributed.tensor._collective_utils, which runs `register_fake("_dtensor::shard_dim_alltoall")` at import time. That op is DEF'd only in C++ (Functional.cpp), so it is absent on distributed-less ROCm wheels and register_fake raises "operator _dtensor::shard_dim_alltoall does not exist", failing the acceptance `import torchao` and rolling the shim back. Define the _dtensor schema via a second FRAGMENT library in the same transaction. Schema verified against the live 2.9 dispatcher and the v2.11.0 Functional.cpp source. Match the Studio is_win32_rocm() detector: fire on torch.version.hip OR a "rocm" __version__ tag (AMD SDK wheels lack torch.version.hip but tag rocm). Gating on hip alone left those wheels torchao-stubbed even though the export gate disables torchao on them. The capability guards (distributed absent, no _c10d_functional/_dtensor dispatcher ops) still rule out false positives. Extend the native-present guard to the _dtensor namespace and add drift tests pinning the _dtensor schema to the live dispatcher and the version-tag detection. * Export page: defer format pruning until hardware info is authoritative The availableFormats prune effect ran on the initial render before /api/system/hardware resolves, when hasNvidia is false and the NVIDIA-only compressed-tensors formats are transiently absent. On a fresh Export mount with the module cache empty (cold start, or a remount during refreshHardwareInfo), a running FP8/NVFP4 selection was pruned permanently, since the later hardware response only adds formats back to availableFormats and never restores selectedFormats. Gate the effect on hardware.loaded so it prunes only against the authoritative capability set, matching the effect's stated intent. * Tighten torchao Windows-ROCm shim comments Comment-only: condense the shim header, the _c10d_functional/_dtensor schema notes, the is_win32_rocm parity note, and the export-page prune comment. No code changes. * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Load real torchao on Windows ROCm instead of hiding torchao export torchao dies at import on torch builds without torch.distributed (pytorch/ao#3452). unsloth/_torchao_nodist.py runs each torchao module inside a window where only torchao's own imports and op lookups get inert stand-ins, removed after each module loads. The Studio export worker loads real torchao through it, the installer installs torchao on Windows ROCm, and the torchao formats are hidden only when it cannot load. torchao_int8 uses Int8WeightOnlyConfig(version=2) so torchao 0.17 exports serialize. * Use the repo's SPDX header on the new torchao files * Do not fail the Windows ROCm install when torchao cannot be installed Only export needs it there, and its formats are hidden without it. * Tighten comments * Replace a stub inherited from run.py, gate on transformers' torchao minimum, fix symbol skew first - spawn re-runs run.py as __mp_main__, which stubs torchao before the export worker's loader; drop that stub while no consumer has imported it. - torchao_export_loadable requires torchao >= 0.15 (transformers 5's TorchAoConfig minimum). - fix_torchao_torch_symbol_skew runs before the no-distributed shim, so torchao 0.18 on torch < 2.10 imports. * Gate the worker's torchao load on the version floor, find editable unsloth, survive the xformers stub - install_torchao_windows_rocm_real_or_stub loads real torchao only when torchao_export_loadable() (torchao >= 0.15), so an API request for torchao on 0.14 fails cleanly instead of in TorchAoConfig. - Locate unsloth with importlib.util.find_spec so setuptools' editable finder is consulted. - fix_xformers_performance_issue skips an xformers in sys.modules with no distribution: Studio's Windows ROCm stub, which a spawn child re-running run.py carries into import unsloth. * Name the app Unsloth in the torchao hints (desktop branding contract) --------- Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com> Co-authored-by: danielhanchen <unslothai@gmail.com> |
||
|
Long Yixing
|
a00fcbb33d
|
Studio: honor response_format on the MLX backend with grammar-constrained decoding (#10180)
* feat(studio): compile response_format into an MLX decoding grammar

Studio's MLX chat paths refused `response_format` outright, while the GGUF path forwards it to llama-server, which builds a GBNF grammar from the schema. This adds the piece MLX was missing: a module that compiles a request's contract into an llguidance grammar and masks the logits row with it.

`constraint_spec_from_response_format` accepts the three OpenAI types. `{"type": "text"}` is the default spelled out and yields no constraint. `json_object` promises an object and honors a `schema` member when the caller sends one, which is where llama-server reads it too. `json_schema` takes the schema from the OpenAI wrapper and also from a top-level `schema`, the lenient spelling clients commonly send. A supplied member that is not a JSON Schema object is refused rather than decoded against a laxer grammar. Anything the engine cannot compile becomes a `ResponseFormatError` naming `response_format`, so a caller gets the reason instead of a reply that ignores the field.

Binding is deferred to the first mask: a padded lm_head is wider than the tokenizer's vocabulary, and the logits row is the only place that width is known. The stop token comes from the runtime's own set rather than the tokenizer's, since a checkpoint may name different end ids in its config than in its tokenizer, and a finished document held to a token nothing stops for would spend the rest of `max_tokens` waiting. `advance` raises on a token the mask never offered instead of falling through to unconstrained text.

A reasoning model gets an optional, bounded prelude so a `<think>` block can close before the document begins; unbounded, an unclosed block could consume the whole budget. Where generation reaches a value only a reserved control token could spell, the mask refuses while the request can still be reported, rather than letting the decode loop end mid-document and report a normal finish.

Compiled grammars are cached by schema hash, and the tokenizer wrap by tokenizer, vocabulary width and stop set. Both caches are bounded.

* feat(studio): apply the decoding grammar on both MLX generate paths

Wires the constraint into the text and vision MLX paths and carries the contract across the orchestrator/worker boundary.

The grammar mask leads the sampling processor chain, ahead of logit bias, the penalties and the temperature/top-p/top-k knobs, so nothing below it can restore a token the grammar excluded. An unconstrained request keeps the existing order and never imports the grammar engine or allocates a bitmask.

`detect_think_prefill` now takes the calling path's own answer to whether its rendering keeps special tokens, instead of inferring it from tokenizer metadata. The suppression turns on `skip_special_tokens` stripping the closing marker, which is a property of how a path renders rather than of the vocabulary: a path streaming the detokenizer's text keeps the marker, so the block closes and the opener belongs in the reply. Read from the tokenizer instead, it emitted a stray closing marker with no opener.

Diffusion generation refuses the contract: it does not decode left to right, so a per-step token mask cannot constrain it.

`llguidance` is installed with the MLX stack on Apple Silicon.

* feat(studio): honor response_format on the MLX chat-completions route

Narrows the refusal to the backends that genuinely cannot honor a contract, and returns the schema's own errors as 400s naming `response_format`.

A contract the grammar engine cannot compile -- a malformed schema, a supplied member that is not a schema object, a missing engine -- answers 400 with the reason rather than returning an unconstrained reply that ignored the field. Validating compiles the grammar, which is CPU-bound and as large as the client's schema, so it runs on a dedicated pool instead of the executor where local token streams advance.

Post-decode reinterpretation withdraws under a contract. A grammar has already fixed what the reply means, so tool-call healing must not promote a schema value that happens to spell call markup, and the unfinished-intent nudge must not follow a complete document with a second one. Only a missing `response_format` reads as absence; any other value that is not the spelled-out default counts as a contract, so a value coerced on the way in withdraws healing rather than reading as nothing.

For the llama.cpp passthrough, a `json_schema` request carrying its schema at the top level is rewritten into the wrapper before forwarding. llama-server reads that type's schema only from `json_schema.schema` and falls back to an object grammar without it, while the MLX path honors both spellings; unrewritten, one request would mean an integer on one backend and an object on the other.

* [pre-commit.ci] auto fixes from pre-commit.com hooks

for more information, see https://pre-commit.ci

* Skip guided decoding tests where llguidance.mlx or Metal is unavailable

* Trim comments in guided decoding changes

* Trim docstrings and remaining comments in guided decoding changes

* Pin llguidance, skip it when satisfied, and never fail the install on it

* Test guided decoding end to end through mlx_lm with a random model

* Keep video ahead of the new generation parameters, as on main

* Keep a constrained VLM reply whole: skip the normalizer for a document, re-emit an allowed opener

* Read routes source as UTF-8 so the contract test runs on Windows

* Keep Deep Research's prompt-only JSON retry working on backends without a grammar engine

* Tell the text grammar a closer survives whenever the prefill re-emits its opener

* Trim guided decoding comments and restore the sampling processors docstring

* Keep reasoning from spelling the closer as text and forging the document boundary

* Decode a constrained reply without tokenization-space cleanup

* Let UNSLOTH_STUDIO_FULL_DEPS force the MLX grammar engine step

* Test that a constrained plain reply skips tokenization-space cleanup

* Refuse a schema literal the reply would lose as a stripped special token

* Withhold exactly the specials each decode path drops from a constrained document

* Exempt the tokenizer end token only when the runtime names no stops

* Hold the VLM grammar to the stop ids the decode loop ends on

* Tighten comments in guided decoding fixes

---------

Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com>
Co-authored-by: Daniel Han <23090290+danielhanchen@users.noreply.github.com>
|
||
|
Daniel Han
|
cc44b7d297
|
Unsloth Studio installer (AMD/Linux): send RDNA 4 cards (RX 9000, R9700) to AMD's gfx120X wheels (#11935)
* Route RDNA 4 to AMD's gfx120X-all wheels on Linux below ROCm 7.13 The generic pytorch.org ROCm wheels up to rocm7.2 ship the null HIP _grouped_mm kernel on gfx1200/gfx1201 (TheRock #5284), so the trainer swaps in a slow Python fallback whenever torch.version.hip is below 7.13. A ROCm 7.14 host is capped to rocm7.2 and always lands there. AMD's gfx120X-all index serves torch 2.11.0+rocm7.13.0 for cp310-cp314, the same coverage the Strix reroute already relies on, and install.ps1 already routes Windows RDNA 4 there. Extend the Strix reroute to gfx1200/gfx1201 in install.sh and install_python_stack.py: - install.sh rewrites the leaf to gfx120x-all so the rocm6.4 floor block below cannot undo it; the floor target flag is still set for the migrated venv repair. - install_python_stack.py shares one set for the reroute and the pending check, so a venv already on the AMD build is left alone. - Explicit UNSLOTH_TORCH_INDEX_URL / _FAMILY pins and the gfx906 override are unchanged. Tests move the RDNA 4 expectations from rocm6.4 to gfx120x-all, retarget cases that used gfx120X as a plain generic arch, and add the new route with gfx1100 and rocm7.13 controls. * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Trim comments in RDNA 4 AMD arch index routing * Reinstall a migrated sub-7.13 wheel when torch is routed to an AMD per-arch index * Also reinstall a migrated 7.13 wheel built for another AMD family * Keep RDNA 4 on the generic wheels in a Python 3.9 venv, which gfx120X-all does not serve * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Keep the migrated repair test from reading an AMD host's own rocm package With no family given, the stubbed venv left importlib.metadata.requires unpatched, so on a ROCm host it read the real rocm-sdk-libraries-gfx1151 and reinstalled where the case expects no change. * Pin the ROCm repair test helpers to Linux x86_64 _ensure_rocm_torch() is a no-op on macOS and aarch64, so on those runners the pip mocks were never called and the new RDNA 4 routing tests failed. * Trim comments in the RDNA 4 routing change * Drop comments that restate the RDNA 4 test names * Expect RDNA 4 to install from the AMD index when the ROCm version is unreadable --------- Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com> |
||
|
Long Yixing
|
8c8dd864cd
|
feat(install): fall back to CERNET and npmmirror when package hosts are blocked or slow (#11786)
* feat(studio): let UNSLOTH_NODE_MIRROR rebase the Node.js dist downloads install_node_prebuilt.py always fetched index.json, SHASUMS256.txt and the archive from nodejs.org. UNSLOTH_NODE_MIRROR now replaces that base for every Node dist URL; archives are still verified against the sha256 pins committed in node_prebuilt_pins.json, so a mirror cannot change what gets installed. * feat(install): fall back to CERNET and npmmirror when package hosts are blocked or slow install.sh and studio/setup.sh now probe pypi.org, download.pytorch.org, nodejs.org and registry.npmjs.org in parallel (5 s connect, 10 s total) before the first package install. A host that fails the probe while its mirror passes is redirected through the env vars the package tools already read: PyPI to https://mirrors.cernet.edu.cn/pypi/web/simple, PyTorch wheels to UNSLOTH_PYTORCH_MIRROR=https://mirrors.cernet.edu.cn/pytorch/whl, Node.js to UNSLOTH_NODE_MIRROR=https://mirrors.cernet.edu.cn/nodejs-release, and npm to UNSLOTH_NPM_REGISTRY=https://registry.npmmirror.com. When pypi.org still answers but misses the budget, uv gets the mirror first and pypi.org second with UV_INDEX_STRATEGY=unsafe-first-match, and pip gets the mirror as PIP_INDEX_URL with pypi.org as PIP_EXTRA_INDEX_URL, so packages the mirror has not synced yet still resolve. When pypi.org does not answer at all, only the mirror is used: unsafe-first-match fetches every index and fails outright when one is unreachable. A host the user already redirected (UV_* / PIP_* index vars, an index in uv.toml or pip.conf, UNSLOTH_PYTORCH_MIRROR, UNSLOTH_TORCH_INDEX_URL, UNSLOTH_NODE_MIRROR, UNSLOTH_NPM_REGISTRY) is left alone, setup.sh skips the probe when install.sh already ran it, and UNSLOTH_MIRROR_FALLBACK=0 turns the fallback off. * feat(install): mirror fallback for blocked or slow package hosts on Windows install.ps1 and studio/setup.ps1 get the same fallback as install.sh: pypi.org, download.pytorch.org, nodejs.org and registry.npmjs.org are probed in parallel, and a host that fails while its CERNET or npmmirror counterpart passes is redirected through the same env vars (UV_*/PIP_* index vars, UNSLOTH_PYTORCH_MIRROR, UNSLOTH_NODE_MIRROR, UNSLOTH_NPM_REGISTRY), with the same slow-versus-blocked PyPI split and the same respect for indexes the user already configured. The helpers live in the block shared with setup.ps1. The probe uses WebRequest.GetResponseAsync rather than HttpClient, which would need Add-Type, and sends a User-Agent because the CERNET mirrors answer 403 without one. On a session whose SecurityProtocol excludes TLS 1.2 it pins TLS 1.2 for the probe only. install.ps1 restores every variable the fallback may set when it exits, since under irm | iex they belong to the caller's session. setup.ps1 now computes its npm --registry args after the probe, so a fallback registry reaches every npm and bun install. * feat(install): fall back to npmmirror for uv-managed Python builds when releases.astral.sh is blocked or slow * feat(install): install the pinned uv from a PyPI mirror wheel when releases.astral.sh is blocked or slow * feat(install): install the pinned uv from a PyPI mirror wheel on Windows when releases.astral.sh is blocked or slow * fix(install): define the mirror fallback outside the Unsloth Studio launcher heredoc The mirror fallback functions sat inside the quoted heredoc that writes the launcher script, so install.sh never defined them and aborted with "_mirror_fallback: not found" right before installing uv. Move the block next to its call and add a check that the block is outside every heredoc in install.sh and studio/setup.sh. * feat(install): pick mirrors by measured speed on real artifacts Each default package host is timed alone on a 1 MiB slice of an artifact it serves, and one below 1 MiB/s, or whose index does not answer, is raced against its mirror and swapped for it only when the mirror is faster and its own index answers. CERNET redirects each tree to a different university mirror, so each tree is timed on its own, and releases.astral.sh is timed once for both uv and its Python builds. * feat(install): pick Windows mirrors by measured speed on real artifacts Ports the speed probe from install.sh to install.ps1 and studio/setup.ps1: each default host is timed alone on a 1 MiB slice of an artifact it serves, and one below 1 MiB/s, or whose index does not answer, is raced against its mirror and swapped for it only when the mirror is faster and its own index answers. Each probe uses a fresh connection and its own deadline, as a separate curl process would, and the probes raise Windows PowerShell 5.1's two-connections-per-host limit so the race's CERNET requests do not queue. The uv Python-builds mirror is dropped on Windows, where uv is always given a resolved interpreter. * feat(install): retry a step whose default host's transport failed through its mirror The mirror probe leaves healthy defaults alone. When a later step fails because the default host stopped answering (a timeout, reset, DNS or TLS error, a 5xx/429, or a download that stalled), the installers now rerun that step once through the host's mirror, after the step's own same-host attempts. The host is read from the failure output, or from the command when a stalled download names no URL; resolution, not-found and other hosts' failures are never retried, so try-then-fallback steps keep their own fallback. A host stays on its mirror for later steps only when the rerun succeeded. Covers install.sh's install commands, setup.sh's npm installs, install_python_stack.py's pip_install and pip_install_try, and the node and pinned uv downloads (only when no source served the file). * feat(install): retry a Windows step whose default host's transport failed through its mirror The Windows mirror fallback now exports the same spare list as the POSIX installers: one mirror per probed host still on its default. install.ps1 reruns a failed package install once through that host's mirror after its own attempts, only when the output shows a transport failure on that host (or a stalled download in a command that uses the default index). A torch mirror rewrites the default torch URLs the command reads, and a mirror is kept for later steps only when the rerun succeeds. studio/setup.ps1 does the same for the frontend and OXC npm installs, and retries the Node download and the pinned uv download (the latter only when no source answered). Every install_python_stack.py run on Windows gets the same retry through the exported list. The shared-helper sync script now also copies a new shared function that has no comment above it. * fix(install): use TUNA's CERNET mirror and npmmirror for Node mirrors.cernet.edu.cn sends the PyPI simple index to a mirror that rate-limits uv's parallel metadata requests (429), failing resolves; tuna.mirrors.cernet.edu.cn serves the index and files from Tsinghua. The Node dist mirror moves to registry.npmmirror.com/-/binary/node, which keeps nodejs.org's layout (index.json, SHASUMS256.txt, archives), and is timed on its own tarball. * feat(install): fall back to pypi.org only for releases the PyPI mirror lacks A switched PyPI host now uses the mirror alone, also when pypi.org was only slow: uv's unsafe-first-match fetched every package from pypi.org too, so a pypi.org that dropped mid-install failed every step. When pypi.org still answered, a failed resolve that reports a version or package as not available (a fresh release the mirror has not synced yet) reruns once with pypi.org behind the mirror, and later steps keep that setup if the rerun works. Commands that pin their own index are left alone. install_python_stack.py classifies its installs the same way. * feat(install.ps1): fall back to pypi.org only for releases the PyPI mirror lacks The Windows installers now match install.sh: a switched PyPI host uses the mirror alone, also when pypi.org was only slow, and when pypi.org still answered, an install whose resolve reports a version or package as not available reruns once with pypi.org behind the mirror, keeping that setup for later steps if it works. Commands that pin their own index or pass --no-index are left alone. * fix(install): keep uv on a project-level index when falling back to the PyPI mirror uv reads uv.toml, or pyproject.toml with a [tool.uv] table, from the current directory or the nearest parent, and an exported UV_DEFAULT_INDEX overrides it. The mirror fallback only checked UV_CONFIG_FILE and the user and system uv.toml, so launching the installer from a project that configures its own index would redirect uv to the mirror. It now also checks the nearest project config, as install_python_stack.py's _uv_config_files does, and recognizes [[tool.uv.index]]. * fix(studio): probe package hosts only before a setup step downloads packages setup.sh and setup.ps1 ran the mirror speed probe at startup, so every unsloth studio update, even one with nothing to install, fetched a 1 MiB sample from each default package host. The probe now runs right before the Python dependency pass and before a Transformers sidecar is rebuilt, the update steps that download from PyPI and PyTorch. install.sh and install.ps1 still probe up front and pass the result on, so fresh installs are unchanged; a standalone update's Node, npm and uv steps use the default hosts, as before the mirror fallback. * test: expect _pip_install_once among the requirements-filter callers pip_install now wraps _pip_install_once with the mirror retry, and the install itself, including its _effective_requirements call, lives in _pip_install_once. * fix(install): leave pip on an index set in the Unsloth Studio venv's pip config pip also reads site config from the venv it runs in (<venv>/pip.conf, pip.ini on Windows). The mirror fallback only checked PIP_CONFIG_FILE and the user and global files, so a private index set in the Unsloth Studio venv was overridden by the exported PIP_INDEX_URL whenever the install fell back from uv to pip. The check now includes the venv's site config. * fix(install): keep a verbose install working on a host without tee The mirror retry reads a failed command's output, so the verbose install arm copied it to a log with tee. install.sh otherwise needs no tee, and on a minimal image without it the pipe closed and the command died of SIGPIPE. The arm now falls back to cat there, which only costs that host the retry. The tests that lift run_install_cmd out of install.sh also lift the functions it now calls, and stub the mirror retry. * fix(studio): arm the mirror retries before setup's first download and skip the probe on a --local re-overlay With the probe moved to the Python dependency pass, a standalone setup reached its Node and npm downloads with no mirror retry armed. setup.sh and setup.ps1 now arm every host's one-shot mirror retry at startup without probing (_mirror_fallback spare / Invoke-MirrorFallback -SpareOnly), and still probe lazily before the first package download. setup.sh arms it from the directory its installs run in, once VENV_DIR is set, so the retry respects the same uv and pip config they do. A --local update runs the dependency pass every time to re-overlay the checkout, almost entirely from uv's cache, so on an existing venv that pass relies on the armed retries instead of probing every host first. * Trim installer mirror fallback comments * Respect NPM_CONFIG_REGISTRY and recheck default indexes in the mirror race A registry set through NPM_CONFIG_REGISTRY / npm_config_registry outranks the frontend .npmrc today; the fallback exported UNSLOTH_NPM_REGISTRY, which becomes --registry and overrode it. Treat it as user configuration. The race re-timed the default artifact but reused the first-round default index result, so one index answer lost in the first round forced a healthy host into blocked mode. Probe the default index again beside the mirror's. * Only use the mirror fallback in mainland China Outside mainland China the installers now behave as before the fallback: no probe, no mirror retries armed, nothing exported. Location is read without a network call: a mainland time zone (Asia/Shanghai and its aliases, Windows "China Standard Time"), or a resolver from a mainland public DNS or cloud (AliDNS, DNSPod, 114DNS, Baidu, CNNIC, Alibaba Cloud and Tencent Cloud internal resolvers), which covers UTC cloud VMs there. UNSLOTH_MIRROR_FALLBACK=1 opts in anywhere; =0 still opts out. * Keep the installers byte-identical to before outside mainland China With no mirror retry armed (outside mainland China, or opted out): - run_install_cmd runs the plain runner, so set -e stops the installer where a command fails as before, and verbose output is not copied to a temp file through tee. - The PowerShell runners stream verbose output without buffering it, and the npm / install retries return before reading any output. - _mirror_retry in install_python_stack.py returns before decoding and scanning the failed output (183 ms for 1 MB of output before). - A retry state inherited from a parent process is dropped, so neither a stale _UNSLOTH_MIRROR_SPARE nor UNSLOTH_MIRROR_FALLBACK=0 can be bypassed. - setup.sh no longer changes directory (and OLDPWD) to arm the retries. The location is read once per process, resolvers come from .NET instead of Get-DnsClientServerAddress (no module or CIM load on Windows), and the 114DNS filtering resolvers plus DNSPod 182.254.116.116 / 119.28.28.28 count as mainland China. An interrupted install also removes a kept output copy. * Mirror fallback: honour XDG_CONFIG_DIRS, skip permission failures, retry sidecars - pip and uv read an index from every directory in XDG_CONFIG_DIRS; an index configured there now counts as user configuration, so the fallback no longer overrides it. - The Node install no longer retries through the mirror on exit 4 (permission denied), matching setup.ps1. - Transformers sidecar installs rerun once with pypi.org behind the mirror when the probe switched a slow pypi.org, as the dependency pass already does for a pin the mirror has not synced. All three only act when the fallback is on (mainland China or UNSLOTH_MIRROR_FALLBACK=1). * Trim mirror fallback comments * Mirror fallback: probe nothing when UV_OFFLINE is set uv's own no-network switch (its spellings: 1, t, true, y, yes, on) now skips the speed probes and the mirror race; the one-shot retries stay armed, as they only follow a failed network command. * Keep vendor names out of the installer comments tests/studio/test_installer_av_shapes.py bans vendor names in shipped scripts, which are handed whole to scanners; the location check comment now describes the resolvers without naming the clouds. --------- Co-authored-by: danielhanchen <danielhanchen@gmail.com> Co-authored-by: Daniel Han <23090290+danielhanchen@users.noreply.github.com> |
||
|
oobabooga
|
14ceddf6b0
|
Studio: skip xFormers when its torch requirement is unmet (#11847)
Studio's Linux installer could pair xFormers 0.0.35 (torch>=2.10) with torch 2.6.0, which made every diffusers import fail. xFormers is now checked against its declared torch requirement from package metadata: an incompatible build is hidden before diffusers imports it (attention falls back to torch SDPA), the final Linux torch repair removes it even when torch is unchanged, and on-demand reinstalls are skipped while it is hidden. Compatible builds are kept. |
||
|
Leo Borcherding
|
4ff930acbd
|
Unsloth Studio (AMD): floor torch at 2.11 on the gfx103X-all and gfx110X-all families too (#11834)
* Unsloth Studio (AMD): floor torch at 2.11 on gfx103X-all and gfx110X-all too The torch 2.11 floor for the _grouped_mm bug named five arches, and install.ps1 keeps a venv's existing torch release unless the arch has a floor, so a gfx103X-all venv that once got 2.10.0+rocm7.13.0 kept it through every update. That build access-violates in _grouped_mm on an RX 6500 XT (clean venv, torch alone), and unsloth-zoo probes _grouped_mm at import, so `import unsloth` dies. gfx103X-all and gfx110X-all join the allowlist in all four installers: the python repair map pins the rocm7.2 trio for gfx1030-1036 and gfx1100-1103, the PowerShell floor maps carry the same arches, the allowlist literals and install.sh's two constraint arms carry the two leaves. gfx908 / gfx90a stay bare (no Windows wheels, unmeasured, Linux floors them via rocm7.2). Every family index serves 2.11.0+rocm7.13.0 on both platforms, so the floor resolves. Fixes #11814. * [pre-commit.ci] auto fixes from pre-commit.com hooks for more information, see https://pre-commit.ci * Floor follow-ups: the tests that used gfx103X / gfx110X as the unfloored leaf move to CDNA The backend explicit-request case, the fast-path probe and the hermeticity table each used gfx1030 / gfx1102 / gfx1103 as "an arch outside the 2.11 pin table"; those are in it now, so gfx90a / gfx908 play that part, and the gfx1103 reroute test asserts the floored trio it now installs. The no-version shell test greps the widened case arm. * Trim comments on the gfx103X/gfx110X torch floor * Drop two restating comments on the gfx103X/gfx110X floor --------- Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com> Co-authored-by: Daniel Han <23090290+danielhanchen@users.noreply.github.com> |
||
|
Daniel Han
|
4af7e844de
|
Studio: verify the Diffusers main zip against a pinned SHA-256 (#11908)
On a host with no working git, the pinned Diffusers main build is installed from the GitHub archive zip for its commit, and that route also runs unattended from the backend startup repair. The commit in the URL names the tree but does not check the bytes served for it. The archive's SHA-256 is now pinned next to the commit in diffusers-main.txt and passed as the #sha256= URL fragment, which pip and uv verify before building. Existing installs and the git route are unaffected; a pin with no digest skips the zip route and keeps the release. |
||
|
Daniel Han
|
0fc6f17225
|
Studio installer: do not run Apple's git shim to ask whether git works (#11759)
Without the Command Line Tools, Apple Silicon's /usr/bin/git is a shim, and running it (even git --version) raises the "install the command line developer tools" dialog. install.sh's _has_working_git answers from the path there; install_python_stack.py's ran the shim unconditionally. That was harmless while only the triton step, skipped on macOS, asked, but since the pinned Diffusers main build became the default (#11405) every macOS install asks, so a Mac without the CLT got the dialog mid-install. The Python probe now mirrors install.sh: on Apple Silicon hardware (Rosetta included, via hw.optional.arm64), a git that resolves to exactly /usr/bin/git with no toolchain selected (xcode-select -p fails) is answered as missing without running it. Homebrew, Xcode.app and Intel Mac gits are still run. |