mirror of
https://github.com/unslothai/unsloth.git
synced 2026-10-21 14:00:32 +00:00
Studio: eject a model with a running chat from the Loaded models card (#14161)
Clicking the minus on a chat model in the bottom-left Loaded models card failed whenever that model still had a chat generating, including one that was stuck. The card showed "Unloading this model would stop 1 chat that is still generating. Stop them first, or retry with force_cancel_active." and offered no way to retry. A chat started from an API client or another tab has no Stop button in this tab, so restarting Studio was the only way out from the card. The card now asks the same "Stop 1 running chat?" question the model picker already asks. "Stop and unload" stops that model's chats and unloads it. "Keep generating" leaves the model loaded and the chat running. A model with nothing generating still ejects straight away with no question. Fixes #14154 ## Before and after Studio built from the merge base (left) and from this branch (right), `unsloth/Qwen3-0.6B-GGUF` Q4_K_M loaded, one chat streaming from an API client so this tab has no Stop button, then the minus on the Loaded models row clicked. Clicking eject: the card used to surface the 409; it now asks the same "Stop 1 running chat?" question the model picker asks. 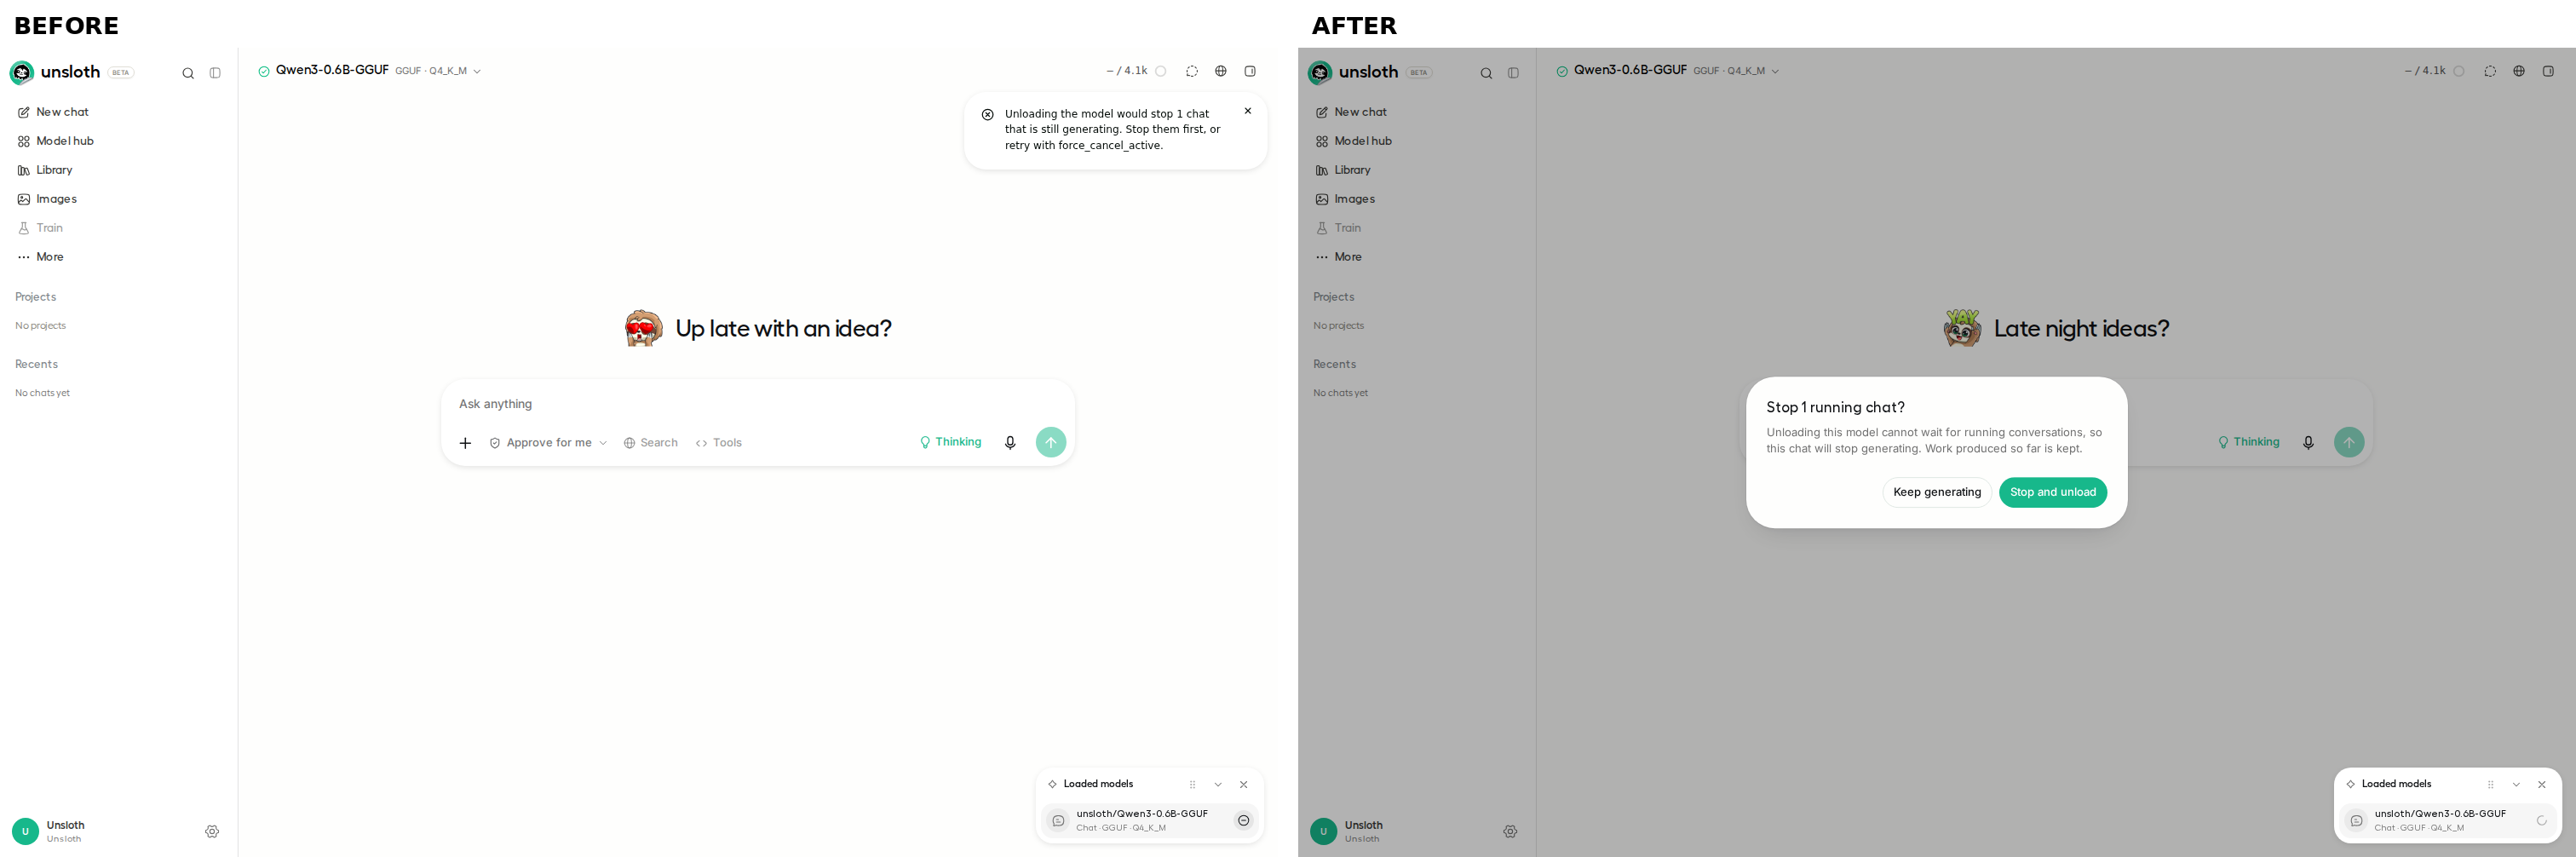 After the click settles: before, the model is still loaded; after "Stop and unload", the model is ejected and the card is empty (`/api/inference/status` reports nothing loaded). 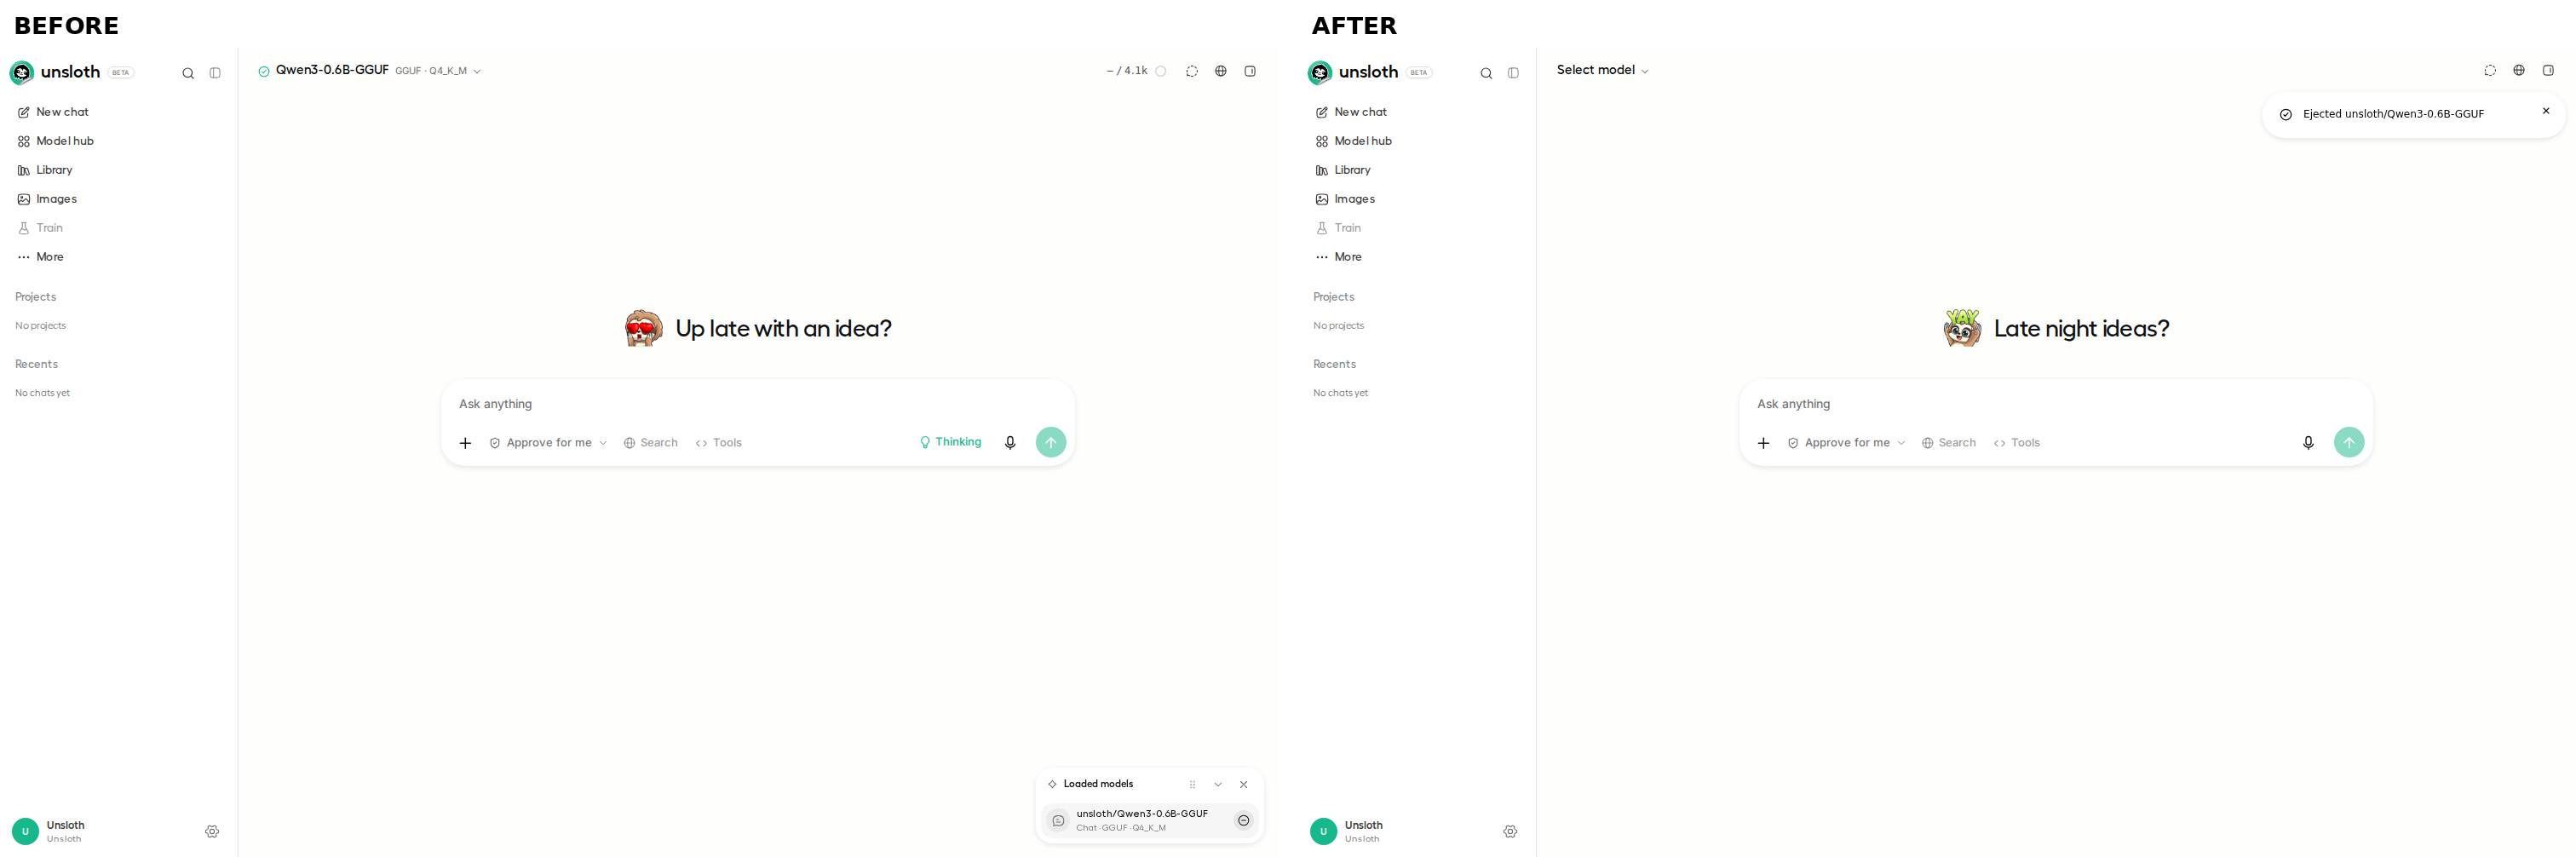 --------- Co-authored-by: pre-commit-ci[bot] <66853113+pre-commit-ci[bot]@users.noreply.github.com> Co-authored-by: Daniel Han <23090290+danielhanchen@users.noreply.github.com>


This commit is contained in:
 Nilay
 GitHub
parent
28a222f20c
commit
4ea4c758dc
15 changed files with 356 additions and 17 deletions
|
|
@ -287,6 +287,16 @@ def _resident_loader(modality: str) -> str | None:
|
|||
return gpu_arbiter.owner_account(modality) if gpu_arbiter.holds(modality) else None
|
||||
|
||||
|
||||
def shares_resident_with_others(modality: str) -> bool:
|
||||
"""Whether release_shared_resident would drop the caller's share, without dropping it."""
|
||||
if not policy.installation_has_managed_accounts():
|
||||
return False
|
||||
account_id = current_account_id()
|
||||
with _sharers_lock:
|
||||
sharers = _resident_sharers.get(modality)
|
||||
return bool(sharers) and account_id in sharers and len(sharers) > 1
|
||||
|
||||
|
||||
def release_shared_resident(modality: str) -> bool:
|
||||
"""Drop the caller's share while others keep the model; False leaves the share for a real unload."""
|
||||
if not policy.installation_has_managed_accounts():
|
||||
|
|
|
|||
|
|
@ -18262,7 +18262,16 @@ async def get_active_generations(
|
|||
)
|
||||
if slot is not None:
|
||||
only, llama = set(slot.generations), slot.llama
|
||||
elif await asyncio.to_thread(model_slots.in_slot, None, lambda: _loaded_satisfies(model)):
|
||||
elif await asyncio.to_thread(
|
||||
model_slots.in_slot,
|
||||
None,
|
||||
# A cached standard-backend model counts as primary: /unload of it stops primary chats.
|
||||
lambda: _loaded_satisfies(model)
|
||||
or (
|
||||
(standard := _peek_inference_backend()) is not None
|
||||
and _unload_evicts_standard_backend(standard, model)
|
||||
),
|
||||
):
|
||||
exclude |= model_slots.all_generations()
|
||||
else:
|
||||
only = set() # an absent model cannot interrupt any generation
|
||||
|
|
@ -22687,12 +22696,30 @@ async def _unload_model_impl(request: UnloadRequest, current_subject: str):
|
|||
routed_slot.set(filling[0])
|
||||
on_primary = routed_slot.get() is None
|
||||
if on_primary:
|
||||
if (
|
||||
sharing = (
|
||||
request.cancel_load_request_id is None
|
||||
and account_access.managed_account()
|
||||
and account_access.release_shared_resident("chat")
|
||||
):
|
||||
and account_access.shares_resident_with_others("chat")
|
||||
)
|
||||
if sharing and not await asyncio.to_thread(_loaded_satisfies, request.model_path):
|
||||
# Another model's name must not drop this share, and the generic teardown below would
|
||||
# clear every sharer's record of the shared model: answer the idempotent no-op.
|
||||
return UnloadResponse(status = "unloaded", model = request.model_path)
|
||||
if sharing:
|
||||
# Leaving a share stops only this account's chats on it; the others keep theirs.
|
||||
scope = account_access.account_scope()
|
||||
elsewhere = model_slots.all_generations()
|
||||
running = active_generations.count(scope, elsewhere, include_external = False)
|
||||
if running and not request.force_cancel_active:
|
||||
raise _active_generations_conflict(
|
||||
"Unloading the model",
|
||||
running,
|
||||
active_generations.active_thread_ids(scope, elsewhere, include_external = False),
|
||||
)
|
||||
if account_access.release_shared_resident("chat"):
|
||||
if running:
|
||||
active_generations.cancel_all(scope, elsewhere, include_external = False)
|
||||
return UnloadResponse(status = "unloaded", model = request.model_path)
|
||||
account_access.require_resident_control(
|
||||
"chat", _loaded_slot_ident() if account_access.managed_account() else None
|
||||
)
|
||||
|
|
|
|||
|
|
@ -194,6 +194,46 @@ def test_a_sharer_leaving_keeps_the_model_for_the_others(monkeypatch, shared, ac
|
|||
assert "chat" not in access._resident_sharers
|
||||
|
||||
|
||||
def test_a_sharer_leaving_mid_chat_is_refused_unless_forced_and_stops_only_its_chat(
|
||||
monkeypatch, shared, accounts
|
||||
):
|
||||
reuse_load(monkeypatch, accounts["alice"])
|
||||
alice_run, bob_run = threading.Event(), threading.Event()
|
||||
with (
|
||||
run_as(accounts["alice"], active_generations.ActiveGeneration, alice_run),
|
||||
run_as(accounts["bob"], active_generations.ActiveGeneration, bob_run),
|
||||
):
|
||||
with client_for(accounts["alice"]) as client:
|
||||
refused = client.post("/api/inference/unload", json = {"model_path": RESIDENT})
|
||||
assert refused.status_code == 409, refused.text
|
||||
assert sees_resident(accounts["alice"])
|
||||
forced = client.post(
|
||||
"/api/inference/unload",
|
||||
json = {"model_path": RESIDENT, "force_cancel_active": True},
|
||||
)
|
||||
assert forced.status_code == 200, forced.text
|
||||
assert alice_run.is_set()
|
||||
assert not bob_run.is_set()
|
||||
assert not shared.unloaded
|
||||
assert not sees_resident(accounts["alice"])
|
||||
assert sees_resident(accounts["bob"])
|
||||
|
||||
|
||||
def test_a_forced_unload_naming_another_model_stops_no_shared_chat(monkeypatch, shared, accounts):
|
||||
reuse_load(monkeypatch, accounts["alice"])
|
||||
alice_run = threading.Event()
|
||||
with run_as(accounts["alice"], active_generations.ActiveGeneration, alice_run):
|
||||
with client_for(accounts["alice"]) as client:
|
||||
response = client.post(
|
||||
"/api/inference/unload",
|
||||
json = {"model_path": "someone/stale-gguf", "force_cancel_active": True},
|
||||
)
|
||||
assert response.status_code == 200, response.text
|
||||
assert not alice_run.is_set()
|
||||
assert not shared.unloaded
|
||||
assert sees_resident(accounts["alice"])
|
||||
|
||||
|
||||
def test_a_replacement_starts_the_sharers_afresh(monkeypatch, shared, accounts):
|
||||
reuse_load(monkeypatch, accounts["alice"])
|
||||
run_as(accounts["bob"], access.publish_resident, "chat", "bob/other-model")
|
||||
|
|
|
|||
|
|
@ -1115,6 +1115,29 @@ def test_active_generations_for_a_model_lists_only_its_chats(backends):
|
|||
assert slots["parallel_slots"] == 4
|
||||
|
||||
|
||||
def test_active_generations_for_a_cached_primary_model_lists_the_primary_chats(
|
||||
backends, monkeypatch
|
||||
):
|
||||
_, extra = backends
|
||||
standard = FakeOrchestrator("org/Active")
|
||||
standard.models["org/Cached"] = {}
|
||||
monkeypatch.setattr(orchestrator, "_inference_backend", standard)
|
||||
monkeypatch.setattr(inf, "_llama_cpp_backend", FakeLlama())
|
||||
app = FastAPI()
|
||||
app.include_router(inf.studio_router, prefix = "/api/inference")
|
||||
app.dependency_overrides[get_current_subject] = lambda: "test-subject"
|
||||
on_primary, on_slot = threading.Event(), threading.Event()
|
||||
extra.generations.add(on_slot)
|
||||
with (
|
||||
active_generations.ActiveGeneration(on_primary, thread_id = "chat-on-primary"),
|
||||
active_generations.ActiveGeneration(on_slot, thread_id = "chat-on-B"),
|
||||
TestClient(app) as client,
|
||||
):
|
||||
get = lambda q: client.get("/api/inference/active-generations" + q).json()["thread_ids"]
|
||||
assert get("?model=org/Cached") == ["chat-on-primary"]
|
||||
assert get("?model=org/gone") == []
|
||||
|
||||
|
||||
def test_an_integrated_gpu_keeps_its_free_memory_next_to_a_loaded_model():
|
||||
from core.inference.llama_cpp import _net_of_held_vram
|
||||
|
||||
|
|
|
|||
|
|
@ -276,8 +276,10 @@ export const BUDGET = {
|
|||
// its strings join the eager English catalog and settings search index. #14223 and #14232 add no raw bytes.
|
||||
// Raised by that growth, to the measured build at 6ccf0e4e74 (6,842,532 B raw / 2,060,400 B transfer) plus a
|
||||
// 160 B raw / 189 B transfer margin.
|
||||
transferBytes: 2_060_589,
|
||||
rawBytes: 6_842_692,
|
||||
// The Loaded models card's eject confirmation (#14161, eager shell) adds 356 B raw / 158 B transfer over 28a222f20
|
||||
// (6,842,874 B raw, 2,060,540 B transfer); limits = that build plus the same margin.
|
||||
transferBytes: 2_060_729,
|
||||
rawBytes: 6_843_034,
|
||||
};
|
||||
|
||||
// The chunk count is reported but not budgeted. Splitting a page out of the entry raises it while lowering the
|
||||
|
|
|
|||
|
|
@ -37,10 +37,14 @@ export function StopRunningChatsDialog() {
|
|||
const sharer = hasNonChat ? "request" : "conversation";
|
||||
// Ejecting leaves no model loaded. Saying it "reloads the model" and offering "Stop and reload"
|
||||
// promised the opposite of what confirming does, for the destructive one.
|
||||
const unloads = effect === "unload";
|
||||
const lead = unloads
|
||||
? `${action || "Unloading the model"} leaves no model loaded, and every open ${sharer} shares it, `
|
||||
: `${action ? `${action} reloads the model, ` : "Reloading the model "}which every open ${sharer} shares, `;
|
||||
const unloads = effect !== "reload";
|
||||
// Model-neutral: a cached standard-backend unload also stops the active model's chats.
|
||||
const lead =
|
||||
effect === "unloadOne"
|
||||
? `${action || "Unloading this model"} cannot wait for running ${sharer}s, `
|
||||
: unloads
|
||||
? `${action || "Unloading the model"} leaves no model loaded, and every open ${sharer} shares it, `
|
||||
: `${action ? `${action} reloads the model, ` : "Reloading the model "}which every open ${sharer} shares, `;
|
||||
const shown = titles.slice(0, 5);
|
||||
const remaining = Math.max(0, titles.length - shown.length);
|
||||
|
||||
|
|
|
|||
|
|
@ -259,6 +259,7 @@ export {
|
|||
PROMPT_QUEUE_RUN_FAILED_EVENT,
|
||||
PROMPT_QUEUE_STOP_EVENT,
|
||||
requestLocalPromptQueueStop,
|
||||
requestScopedLocalPromptQueueStop,
|
||||
type PromptQueueRunFailedEventDetail,
|
||||
type PromptQueueStopEventDetail,
|
||||
} from "./utils/prompt-queue-boundary";
|
||||
|
|
|
|||
|
|
@ -5,8 +5,8 @@ import { create } from "zustand";
|
|||
|
||||
type Resolver = (confirmed: boolean) => void;
|
||||
|
||||
/** What confirming does to the model: reload it, or leave none loaded. */
|
||||
export type StopRunningChatsEffect = "reload" | "unload";
|
||||
/** What confirming does: reload, leave no model loaded, or unload just this one. */
|
||||
export type StopRunningChatsEffect = "reload" | "unload" | "unloadOne";
|
||||
|
||||
// One at a time: a new request declines any pending one so no promise leaks.
|
||||
let pendingResolver: Resolver | null = null;
|
||||
|
|
|
|||
|
|
@ -81,7 +81,11 @@ export async function ejectChatModel(
|
|||
// else's.
|
||||
const holdsTarget = (names: string[] | undefined) =>
|
||||
names?.some((name) => deps.matches(target, name)) ?? false;
|
||||
if (deps.cachedRow || holdsTarget(await deps.readCached?.())) {
|
||||
// Re-read even for a cached row: another tab may have evicted it since the card polled, and
|
||||
// unloading a name nobody holds would still stop the active model's queues. A failed read
|
||||
// keeps the row's own word, as before.
|
||||
const cachedNow = await deps.readCached?.().catch(() => undefined);
|
||||
if (cachedNow === undefined ? deps.cachedRow : holdsTarget(cachedNow)) {
|
||||
// A cached row is never the active model, so the scoped read can never
|
||||
// match it. Name it directly: the Transformers backend can still hold it.
|
||||
await deps.unload(target);
|
||||
|
|
|
|||
|
|
@ -8,8 +8,10 @@
|
|||
|
||||
import { authFetch } from "@/features/auth";
|
||||
import {
|
||||
confirmStopRunningChatsIfNeeded,
|
||||
getInferenceStatus,
|
||||
isExternalModelId,
|
||||
requestScopedLocalPromptQueueStop,
|
||||
resolveInferenceCheckpointId,
|
||||
unloadModel,
|
||||
useChatRuntimeStore,
|
||||
|
|
@ -152,6 +154,12 @@ export async function readLoadedModels(
|
|||
|
||||
/** Release the model this row names, and only that one. See eject-chat-model.ts. */
|
||||
async function ejectChatRow(entry: LoadedModelEntry): Promise<EjectOutcome> {
|
||||
const decision = await confirmStopRunningChatsIfNeeded(
|
||||
"Unloading this model",
|
||||
"unloadOne",
|
||||
entry.name,
|
||||
);
|
||||
if (!decision.proceed) return { status: "declined" };
|
||||
const { unloadedAliases, stillResident, replacedBy } = await ejectChatModel(
|
||||
entry.name,
|
||||
{
|
||||
|
|
@ -167,7 +175,14 @@ async function ejectChatRow(entry: LoadedModelEntry): Promise<EjectOutcome> {
|
|||
),
|
||||
};
|
||||
},
|
||||
unload: (modelPath) => unloadModel({ model_path: modelPath }),
|
||||
// Only once an unload is really sent: a row replaced since the poll unloads nothing.
|
||||
unload: (modelPath) => {
|
||||
requestScopedLocalPromptQueueStop(decision.promptQueueThreadIds);
|
||||
return unloadModel({
|
||||
model_path: modelPath,
|
||||
force_cancel_active: decision.forceCancelActive,
|
||||
});
|
||||
},
|
||||
matches: modelIdsMatch,
|
||||
cachedRow: entry.inactive === true,
|
||||
readCached: async () => (await bounded(getInferenceStatus)).loaded ?? [],
|
||||
|
|
@ -204,6 +219,7 @@ function clearChatSelectionFor(aliases: string[]): void {
|
|||
export type EjectOutcome =
|
||||
| { status: "ejected" }
|
||||
| { status: "alreadyFree" }
|
||||
| { status: "declined" }
|
||||
| { status: "replaced"; resident: string }
|
||||
| { status: "stillResident"; model: string }
|
||||
// The unload was accepted but the read that confirms it did not answer, so neither "done" nor
|
||||
|
|
|
|||
|
|
@ -216,6 +216,7 @@ export function useLoadedModels(
|
|||
const label = shortModelLabel(entry.name);
|
||||
try {
|
||||
const outcome = await ejectLoadedModel(entry);
|
||||
if (outcome.status === "declined") return;
|
||||
if (outcome.status === "stillResident") {
|
||||
toast.warning(
|
||||
`"${shortModelLabel(outcome.model)}" was loaded while ejecting, so it is still using memory. Eject again to release it.`,
|
||||
|
|
|
|||
|
|
@ -0,0 +1,21 @@
|
|||
// SPDX-License-Identifier: AGPL-3.0-only
|
||||
// Copyright 2026-present the Unsloth AI Inc. team. All rights reserved. See /studio/LICENSE.AGPL-3.0
|
||||
|
||||
// bundler-resolver's two rules, plus the barrels loaded-models-api.ts reaches that pull in
|
||||
// TSX: chat, images and video go to loaded-models-eject-stub.ts, auth to its store stub.
|
||||
import { resolve as resolveBundler } from "../bundler-resolver.mjs";
|
||||
|
||||
const EJECT_STUB = new URL("./loaded-models-eject-stub.ts", import.meta.url)
|
||||
.href;
|
||||
const STUBS = new Map([
|
||||
["@/features/chat", EJECT_STUB],
|
||||
["@/features/images/api", EJECT_STUB],
|
||||
["@/features/video/api", EJECT_STUB],
|
||||
["@/features/auth", new URL("./store-stubs/auth.ts", import.meta.url).href],
|
||||
]);
|
||||
|
||||
export function resolve(specifier, context, next) {
|
||||
const stub = STUBS.get(specifier);
|
||||
if (stub) return next(stub, context);
|
||||
return resolveBundler(specifier, context, next);
|
||||
}
|
||||
91
studio/frontend/tests/helpers/loaded-models-eject-stub.ts
Normal file
91
studio/frontend/tests/helpers/loaded-models-eject-stub.ts
Normal file
|
|
@ -0,0 +1,91 @@
|
|||
// SPDX-License-Identifier: AGPL-3.0-only
|
||||
// Copyright 2026-present the Unsloth AI Inc. team. All rights reserved. See /studio/LICENSE.AGPL-3.0
|
||||
|
||||
// Stubs the chat, images and video barrels; /unload 409s like the backend while a chat
|
||||
// is generating unless forced.
|
||||
|
||||
type UnloadPayload = { model_path: string; force_cancel_active?: boolean };
|
||||
|
||||
export const state = {
|
||||
active: null as string | null,
|
||||
loaded: [] as string[],
|
||||
generating: false,
|
||||
confirmAnswer: { proceed: true, forceCancelActive: false },
|
||||
confirmCalls: [] as { action: string; effect: string; model?: string }[],
|
||||
unloads: [] as UnloadPayload[],
|
||||
queueStops: [] as string[][],
|
||||
};
|
||||
|
||||
export function resetStub({
|
||||
active = null as string | null,
|
||||
loaded = [] as string[],
|
||||
generating = false,
|
||||
} = {}): void {
|
||||
state.active = active;
|
||||
state.loaded = [...loaded];
|
||||
state.generating = generating;
|
||||
state.confirmAnswer = { proceed: true, forceCancelActive: false };
|
||||
state.confirmCalls = [];
|
||||
state.unloads = [];
|
||||
state.queueStops = [];
|
||||
}
|
||||
|
||||
export async function getInferenceStatus() {
|
||||
return { active_model: state.active, loaded: [...state.loaded] };
|
||||
}
|
||||
|
||||
export function resolveInferenceCheckpointId(status: {
|
||||
active_model: string | null;
|
||||
}): string | null {
|
||||
return status.active_model ?? null;
|
||||
}
|
||||
|
||||
export function isExternalModelId() {
|
||||
return false;
|
||||
}
|
||||
|
||||
export async function unloadModel(payload: UnloadPayload): Promise<void> {
|
||||
state.unloads.push(payload);
|
||||
if (state.generating && !payload.force_cancel_active) {
|
||||
throw new Error(
|
||||
"Unloading this model would stop 1 chat that is still generating. Stop them first, or retry with force_cancel_active.",
|
||||
);
|
||||
}
|
||||
state.generating = false;
|
||||
state.loaded = state.loaded.filter((name) => name !== payload.model_path);
|
||||
if (state.active === payload.model_path) state.active = null;
|
||||
}
|
||||
|
||||
export async function confirmStopRunningChatsIfNeeded(
|
||||
action: string,
|
||||
effect: string,
|
||||
model?: string,
|
||||
) {
|
||||
state.confirmCalls.push({ action, effect, model });
|
||||
const answer = state.generating
|
||||
? state.confirmAnswer
|
||||
: { proceed: true, forceCancelActive: false };
|
||||
const threads = state.generating ? ["running-thread"] : [];
|
||||
return { ...answer, promptQueueThreadIds: threads, preStreamRunTokens: [] };
|
||||
}
|
||||
|
||||
export function requestScopedLocalPromptQueueStop(threadIds: string[]) {
|
||||
state.queueStops.push(threadIds);
|
||||
}
|
||||
|
||||
export const useChatRuntimeStore = {
|
||||
getState: () => ({ params: { checkpoint: null }, clearCheckpoint() {} }),
|
||||
};
|
||||
|
||||
export async function getDiffusionStatus() {
|
||||
return { loaded: false };
|
||||
}
|
||||
export async function unloadDiffusionModel() {
|
||||
return { loaded: false };
|
||||
}
|
||||
export async function getVideoStatus() {
|
||||
return { loaded: false };
|
||||
}
|
||||
export async function unloadVideoModel() {
|
||||
return { loaded: false };
|
||||
}
|
||||
|
|
@ -21,8 +21,9 @@ function resident(checkpoint: string): ResidentChatModel {
|
|||
function backend(
|
||||
timeline: (ResidentChatModel | null)[],
|
||||
cachedRow = false,
|
||||
/** What the runtime still holds after a cached row's unload. */
|
||||
/** What the runtime still holds after a cached row's unload; before it, the row itself too. */
|
||||
cachedAfter: string[] | null = null,
|
||||
cachedTarget = "unsloth/Qwen3-4B",
|
||||
) {
|
||||
const unloaded: string[] = [];
|
||||
let read = 0;
|
||||
|
|
@ -35,7 +36,14 @@ function backend(
|
|||
},
|
||||
matches: modelIdsMatch,
|
||||
cachedRow,
|
||||
...(cachedAfter === null ? {} : { readCached: async () => cachedAfter }),
|
||||
...(cachedAfter === null
|
||||
? {}
|
||||
: {
|
||||
readCached: async () =>
|
||||
cachedRow && unloaded.length === 0
|
||||
? [...cachedAfter, cachedTarget]
|
||||
: cachedAfter,
|
||||
}),
|
||||
},
|
||||
};
|
||||
}
|
||||
|
|
@ -130,7 +138,11 @@ test("a cached row the backend kept is reported still resident", async () => {
|
|||
const result = await ejectChatModel("unsloth/Qwen3-4B", deps);
|
||||
assert.deepEqual(unloaded, ["unsloth/Qwen3-4B"], "the unload was attempted");
|
||||
assert.equal(result.stillResident, "unsloth/Qwen3-4B");
|
||||
assert.deepEqual(result.unloadedAliases, [], "nothing to clear the picker on");
|
||||
assert.deepEqual(
|
||||
result.unloadedAliases,
|
||||
[],
|
||||
"nothing to clear the picker on",
|
||||
);
|
||||
});
|
||||
|
||||
test("a cached row the backend released is reported ejected", async () => {
|
||||
|
|
|
|||
|
|
@ -0,0 +1,87 @@
|
|||
// SPDX-License-Identifier: AGPL-3.0-only
|
||||
// Copyright 2026-present the Unsloth AI Inc. team. All rights reserved. See /studio/LICENSE.AGPL-3.0
|
||||
|
||||
// Ejecting a model with a running chat must send a forced unload, not surface the 409.
|
||||
|
||||
import assert from "node:assert/strict";
|
||||
import { register } from "node:module";
|
||||
import test from "node:test";
|
||||
|
||||
register("./helpers/loaded-models-eject-resolver.mjs", import.meta.url);
|
||||
|
||||
const stub = await import("./helpers/loaded-models-eject-stub.ts");
|
||||
const { ejectLoadedModel } = await import(
|
||||
"../src/features/loaded-models/loaded-models-api.ts"
|
||||
);
|
||||
|
||||
const QWEN = "unsloth/Qwen3-4B-GGUF";
|
||||
const ORNITH = "ornith-ai/Ornith-1.5-35B-A3B-GGUF";
|
||||
|
||||
function chatRow(name: string, inactive = false) {
|
||||
return {
|
||||
id: `chat:${name}`,
|
||||
kind: "text" as const,
|
||||
source: "chat" as const,
|
||||
name,
|
||||
detail: inactive ? "Still in memory" : "GGUF",
|
||||
...(inactive ? { inactive: true } : {}),
|
||||
};
|
||||
}
|
||||
|
||||
test("a generating model is ejected once stopping its chat is confirmed", async () => {
|
||||
stub.resetStub({ active: QWEN, loaded: [QWEN], generating: true });
|
||||
stub.state.confirmAnswer = { proceed: true, forceCancelActive: true };
|
||||
const outcome = await ejectLoadedModel(chatRow(QWEN));
|
||||
assert.deepEqual(stub.state.confirmCalls, [
|
||||
{ action: "Unloading this model", effect: "unloadOne", model: QWEN },
|
||||
]);
|
||||
assert.equal(stub.state.unloads[0].force_cancel_active, true);
|
||||
assert.deepEqual(stub.state.queueStops, [["running-thread"]]);
|
||||
assert.deepEqual(outcome, { status: "ejected" });
|
||||
assert.equal(stub.state.active, null);
|
||||
});
|
||||
|
||||
test("a row replaced since the poll stops no queue and unloads nothing", async () => {
|
||||
stub.resetStub({ active: ORNITH, loaded: [ORNITH], generating: true });
|
||||
stub.state.confirmAnswer = { proceed: true, forceCancelActive: true };
|
||||
const outcome = await ejectLoadedModel(chatRow(QWEN));
|
||||
assert.deepEqual(stub.state.unloads, []);
|
||||
assert.deepEqual(stub.state.queueStops, []);
|
||||
assert.deepEqual(outcome, { status: "replaced", resident: ORNITH });
|
||||
});
|
||||
|
||||
test("a generating model kept in memory beside the active one is ejected too", async () => {
|
||||
stub.resetStub({ active: QWEN, loaded: [QWEN, ORNITH], generating: true });
|
||||
stub.state.confirmAnswer = { proceed: true, forceCancelActive: true };
|
||||
const outcome = await ejectLoadedModel(chatRow(ORNITH, true));
|
||||
assert.deepEqual(stub.state.unloads, [
|
||||
{ model_path: ORNITH, force_cancel_active: true },
|
||||
]);
|
||||
assert.deepEqual(outcome, { status: "ejected" });
|
||||
assert.deepEqual(stub.state.loaded, [QWEN]);
|
||||
});
|
||||
|
||||
test("a cached row another tab already evicted stops no queue", async () => {
|
||||
stub.resetStub({ active: QWEN, loaded: [QWEN], generating: true });
|
||||
stub.state.confirmAnswer = { proceed: true, forceCancelActive: true };
|
||||
const outcome = await ejectLoadedModel(chatRow(ORNITH, true));
|
||||
assert.deepEqual(stub.state.unloads, []);
|
||||
assert.deepEqual(stub.state.queueStops, []);
|
||||
assert.notEqual(outcome.status, "ejected");
|
||||
});
|
||||
|
||||
test("declining to stop the chat leaves the model loaded", async () => {
|
||||
stub.resetStub({ active: QWEN, loaded: [QWEN], generating: true });
|
||||
stub.state.confirmAnswer = { proceed: false, forceCancelActive: false };
|
||||
const outcome = await ejectLoadedModel(chatRow(QWEN));
|
||||
assert.deepEqual(stub.state.unloads, []);
|
||||
assert.deepEqual(outcome, { status: "declined" });
|
||||
assert.equal(stub.state.active, QWEN);
|
||||
});
|
||||
|
||||
test("an idle model is ejected without forcing anything", async () => {
|
||||
stub.resetStub({ active: QWEN, loaded: [QWEN] });
|
||||
const outcome = await ejectLoadedModel(chatRow(QWEN));
|
||||
assert.equal(stub.state.unloads[0].force_cancel_active ?? false, false);
|
||||
assert.deepEqual(outcome, { status: "ejected" });
|
||||
});
|
||||
Loading…
Add table
Add a link
Reference in a new issue