mirror of
https://github.com/unslothai/unsloth.git
synced 2026-10-21 14:00:32 +00:00
Studio: Developer mode opt-in for experimental CPU video generation (#14247)
Closes #9458. Video stays hidden on hosts without a supported GPU by default. This adds an owner-only Developer mode in Settings > General with one switch, "Allow video generation on CPU (experimental)". `UNSLOTH_VIDEO_ALLOW_CPU` overrides the saved setting in either direction. ## What changes - `video_capability()` admits only the plain CPU-only case (reason `no_accelerator`) when the opt-in is on, marked `video_cpu_experimental`. Detection failures, missing or broken PyTorch, Intel Macs and GPUs PyTorch cannot reach stay blocked. - The setting lives in the owner's store (`PUT /api/settings/developer-mode`, owner only, 403 for managed accounts; any account can read it). - `/api/health` carries `video_cpu_opt_in` so the sidebar keeps the Video row enabled once opted in. - Enabling opens a confirm dialog: "CPU video generation may take hours, consume large amounts of RAM, and may freeze your system. Continue at your own risk.", plus host RAM against a 32 GB minimum and a measured speed estimate. Disabling restores the GPU gate at once. - The Video page shows a persistent "CPU (experimental)" banner while it is in effect. The backend video pipelines already resolve to a float32 CPU target when no accelerator is visible (the routes on `main` already render on CPU; only the capability gate and the UI blocked it), so no inference code changes. ## Testing - Wan2.1-T2V-1.3B with no GPU visible, through `/video/load` and `/video/generate` on a real Studio server: 832x480, 5 frames, 3 steps, generate 228 s on 16 threads, peak RSS 24.5 GiB (this sets the 32 GB minimum). After the owner PUT, `/api/system` moved from `no_accelerator` to `video_supported: true, video_cpu_experimental: true`, and the load reported device `cpu`, float32. The output matches the base tree's frame for frame (mean 141.29). - Tiny Wan pipelines render on CPU for `wan2.1-t2v-1.3b`, `wan2.2-ti2v-5b` and `wan2.2-t2v-a14b`. - Backend: 34 new tests (capability matrix, every other refusal reason staying blocked with the opt-in on, env and setting precedence, owner-only PUT, health wiring); the related suites pass (145 in the capability, developer-mode and account settings files). - Frontend: 8 new tests (RAM check, confirm flow, gate wiring); `tsc` and the strict i18n parity check pass. Not verified on CPU: LTX-2 / 2.5, HunyuanVideo 1.5 and MiniMax-H3 (no tiny repos; MiniMax-H3 already runs through the CPU sd.cpp build on such hosts). A default-length clip (33 frames, 30 steps) was not timed; "hours" is extrapolated from about 27 s per denoise step at 832x480. ## Screenshots Studio started with no GPU visible (`/api/system` reports `no_accelerator` on both sides). Settings > General: AFTER adds the Developer mode section with the switch, off by default. 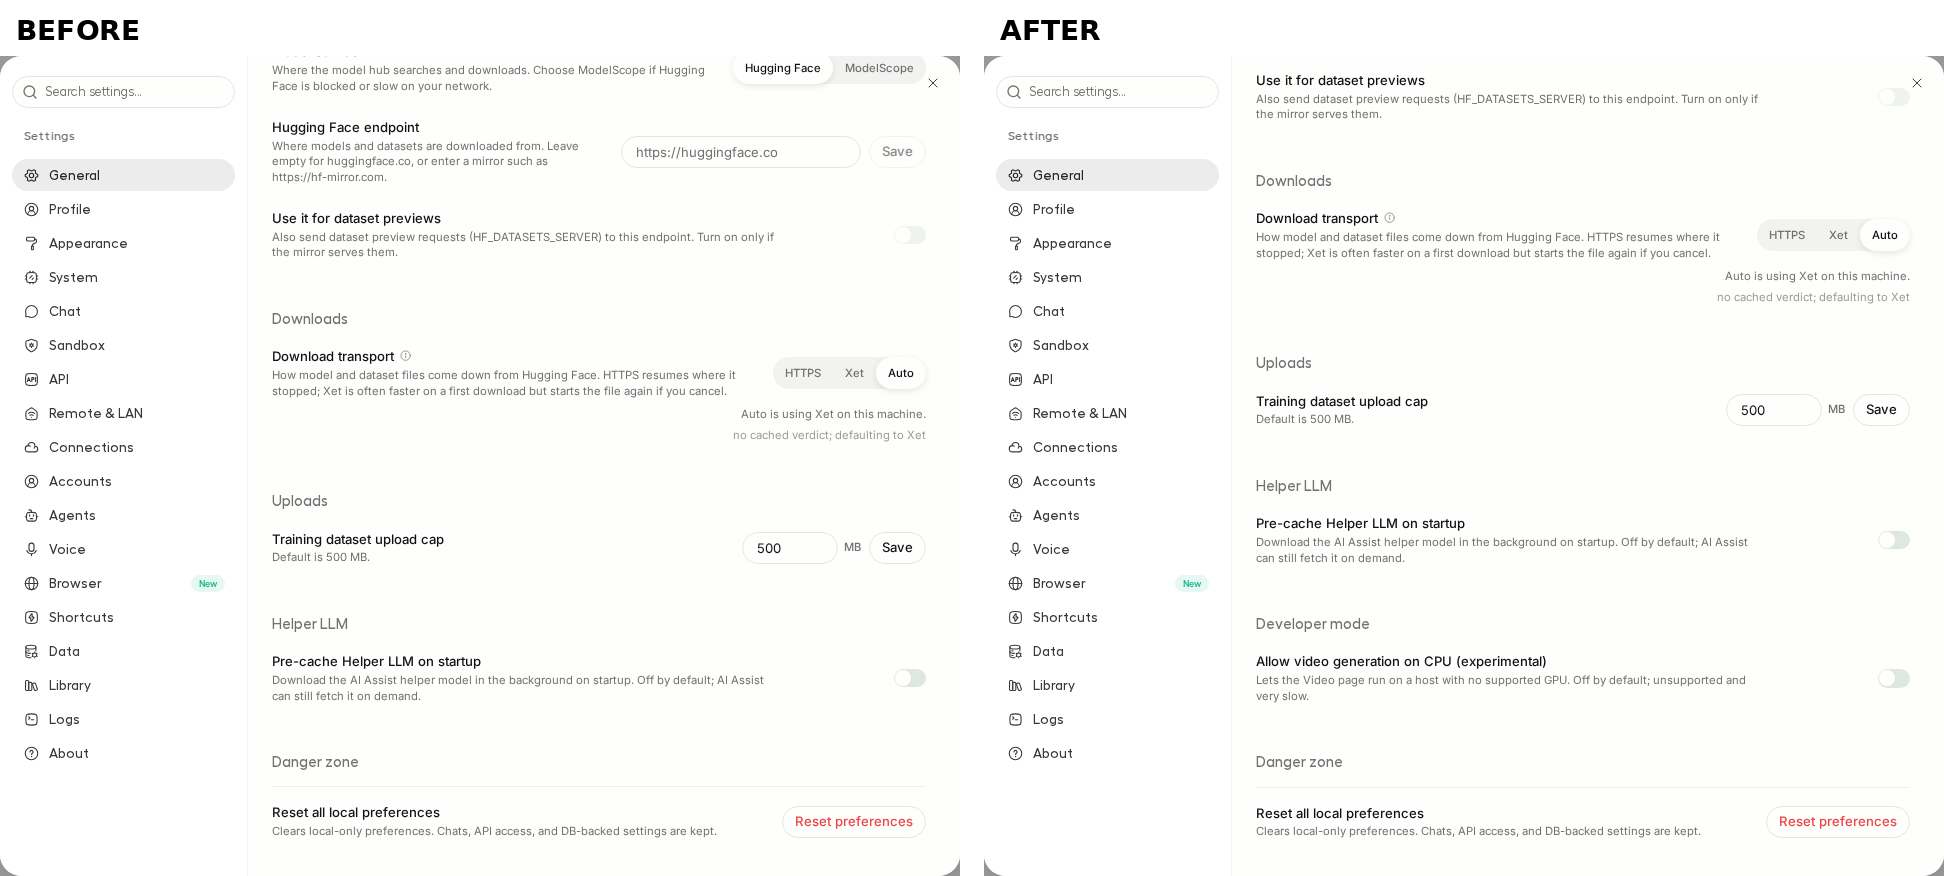 Turning the switch on asks first (the issue's warning, host RAM against the minimum, and the measured speed): 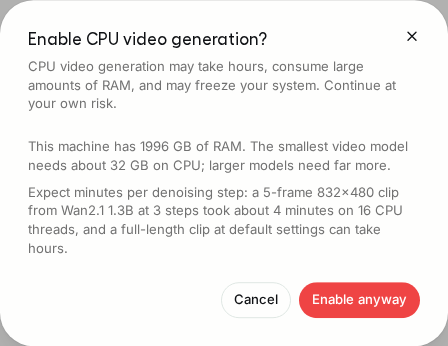 After confirming, `/api/system` reports `video_supported: true, video_cpu_experimental: true` without a restart, and the Video page opens with the CPU (experimental) banner. BEFORE, the same host keeps the no-accelerator block: 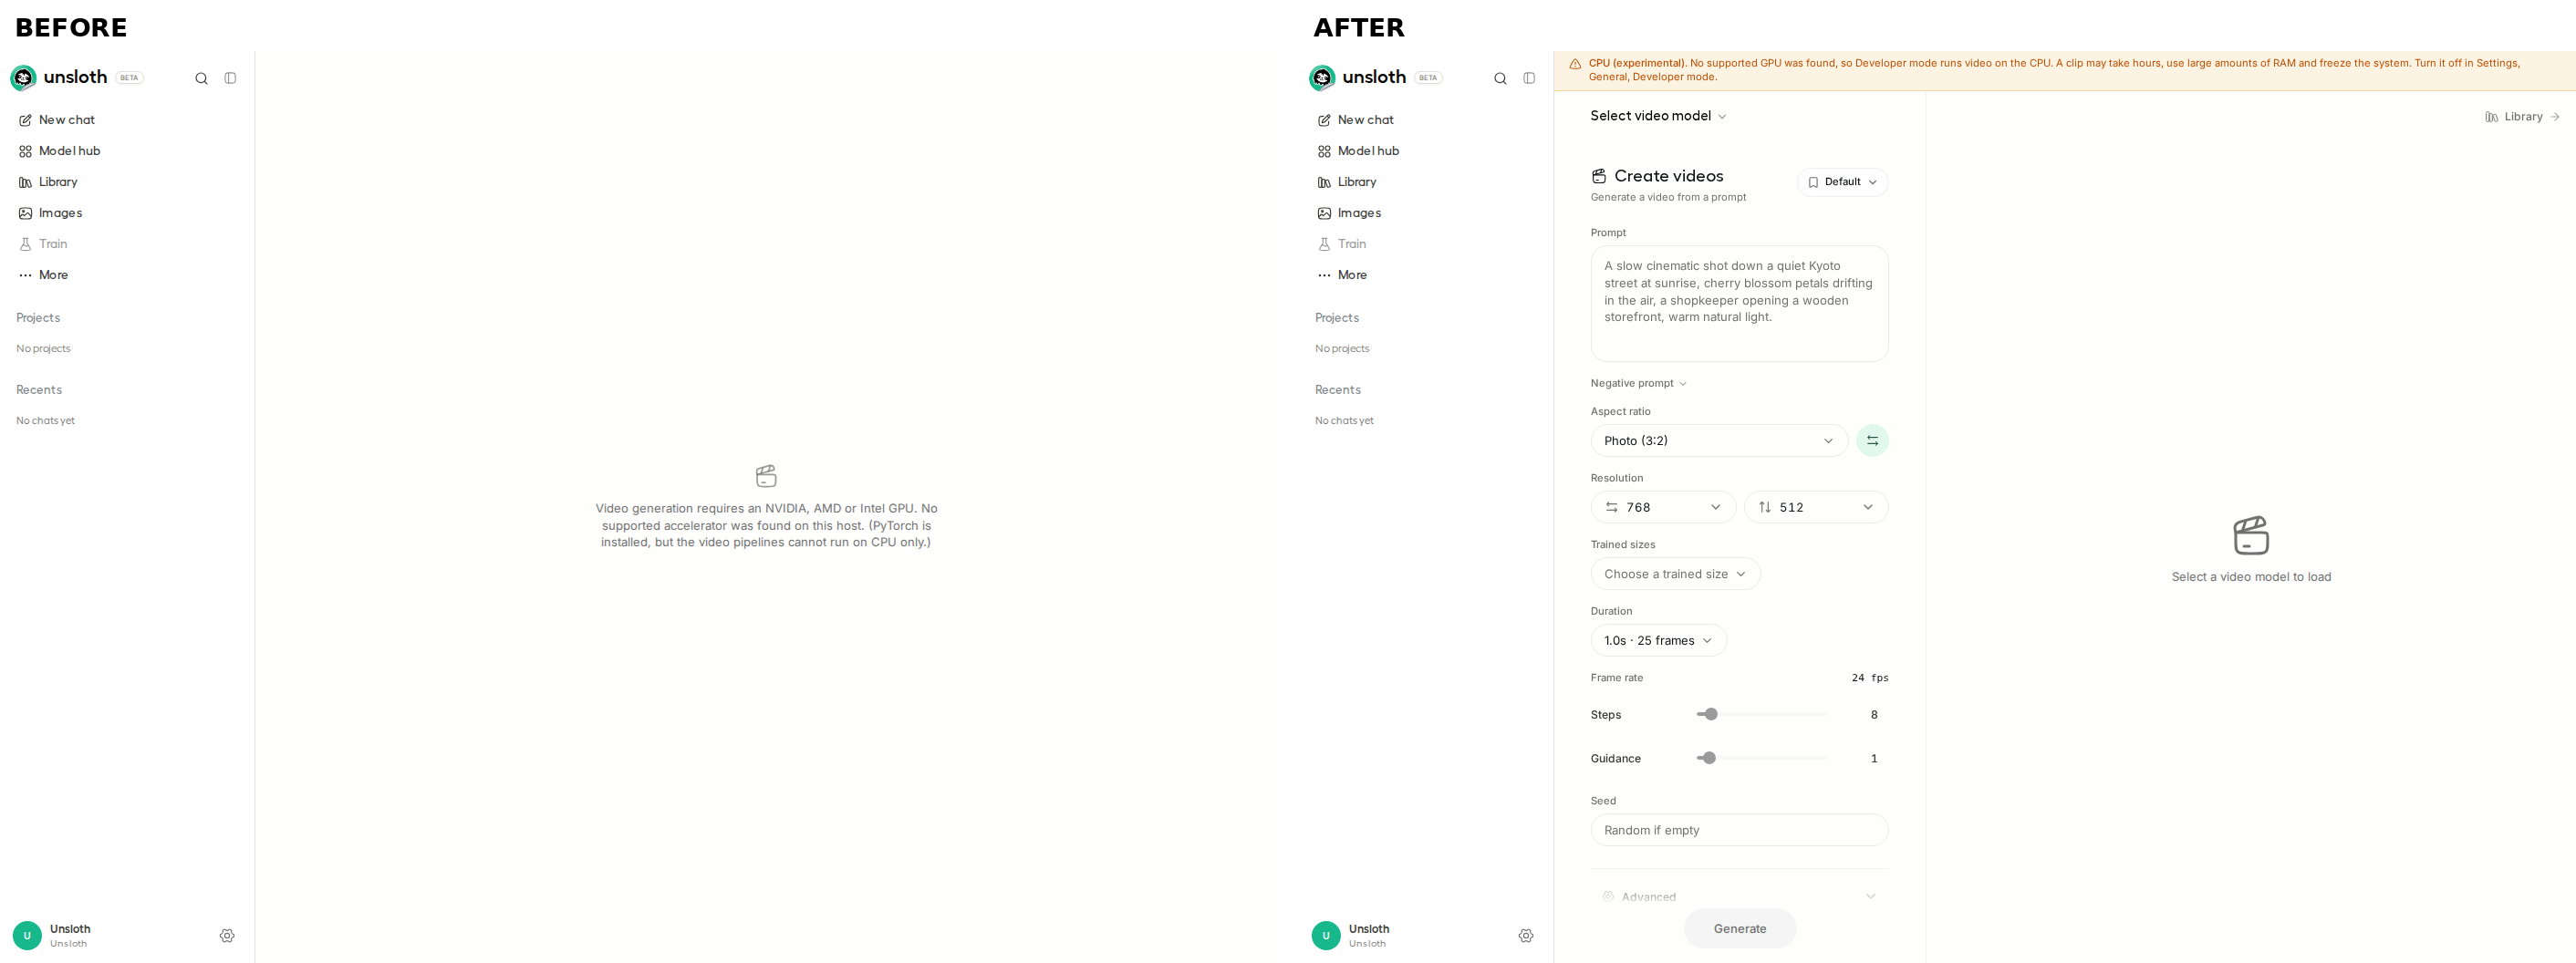



This commit is contained in:
 Daniel Han
 GitHub
parent
39efb789eb
commit
26e246d407
36 changed files with 1272 additions and 10 deletions
|
|
@ -2284,6 +2284,15 @@ async def health_check(request: Request):
|
|||
# Why chat_only is set; fingerprints the host, so keep it authed. One snapshot for all three.
|
||||
authed["chat_only"] = snapshot[0]
|
||||
authed["chat_only_reason"] = snapshot[1]
|
||||
# Developer mode's CPU video opt-in, so the sidebar can keep the Video row navigable on a
|
||||
# CPU-only host that opted in. Read only on that host: everywhere else it cannot matter.
|
||||
authed["video_cpu_opt_in"] = False
|
||||
if snapshot[0] and snapshot[1] == "no_gpu":
|
||||
try:
|
||||
from utils.video_cpu_settings import video_cpu_enabled
|
||||
authed["video_cpu_opt_in"] = bool(video_cpu_enabled())
|
||||
except Exception:
|
||||
pass
|
||||
# What specifically blocked that reason, when detection recorded one. Only the MLX gate does today, and only
|
||||
# because it is all-or-nothing: without it the greyed-out Train row can only say "run `unsloth studio
|
||||
# update`". From the snapshot, so it cannot come from a different detection pass than the reason beside it.
|
||||
|
|
|
|||
|
|
@ -91,6 +91,7 @@ from utils.helper_precache_settings import (
|
|||
set_helper_precache_enabled,
|
||||
)
|
||||
from utils import first_token_timeout, sandbox_memory_limit, systemone_settings, tool_result_limit
|
||||
from utils import video_cpu_settings
|
||||
from utils.download_transport_settings import (
|
||||
get_download_transport_mode,
|
||||
set_download_transport_mode,
|
||||
|
|
@ -763,6 +764,24 @@ class HelperPrecacheResponse(BaseModel):
|
|||
disabled_by_env: bool
|
||||
|
||||
|
||||
class DeveloperModePayload(BaseModel):
|
||||
video_cpu: StrictBool
|
||||
|
||||
|
||||
class DeveloperModeResponse(BaseModel):
|
||||
# Effective answer (env override, else the setting) and the persisted setting on its own.
|
||||
video_cpu: bool
|
||||
video_cpu_setting: bool
|
||||
default_video_cpu: bool = video_cpu_settings.DEFAULT_VIDEO_CPU_ENABLED
|
||||
# True/False when UNSLOTH_VIDEO_ALLOW_CPU decides, null when the setting does.
|
||||
video_cpu_env_override: Optional[bool] = None
|
||||
# Whether the opt-in changes anything here: only a CPU-only host whose sole blocker is the
|
||||
# missing accelerator. A GPU host already runs video; a broken install stays refused.
|
||||
video_cpu_applicable: bool
|
||||
host_ram_bytes: Optional[int] = None
|
||||
min_ram_bytes: int = video_cpu_settings.VIDEO_CPU_MIN_RAM_GB * 1024**3
|
||||
|
||||
|
||||
class DownloadTransportPayload(BaseModel):
|
||||
mode: Literal["auto", "xet", "http"]
|
||||
|
||||
|
|
@ -1173,6 +1192,24 @@ def _helper_precache_response(enabled: bool | None = None) -> HelperPrecacheResp
|
|||
)
|
||||
|
||||
|
||||
def _developer_mode_response() -> DeveloperModeResponse:
|
||||
try:
|
||||
from utils.hardware import hardware as hardware_mod
|
||||
applicable = (
|
||||
hardware_mod._video_capability_verdict().get("video_unsupported_reason")
|
||||
== "no_accelerator"
|
||||
)
|
||||
except Exception: # noqa: BLE001 -- an unanswerable probe must not fail the settings read
|
||||
applicable = False
|
||||
return DeveloperModeResponse(
|
||||
video_cpu = video_cpu_settings.video_cpu_enabled(),
|
||||
video_cpu_setting = video_cpu_settings.get_video_cpu_setting(),
|
||||
video_cpu_env_override = video_cpu_settings.video_cpu_env_override(),
|
||||
video_cpu_applicable = applicable,
|
||||
host_ram_bytes = video_cpu_settings.host_ram_bytes(),
|
||||
)
|
||||
|
||||
|
||||
def _download_transport_response(mode: str | None = None) -> DownloadTransportResponse:
|
||||
# No Xet probe: this renders a row, not a download start. The free-RAM gate is asked for
|
||||
# anyway, since the row states what the next download will use.
|
||||
|
|
@ -1618,6 +1655,33 @@ def update_helper_precache(
|
|||
return _helper_precache_response(enabled)
|
||||
|
||||
|
||||
@_shared_settings_router.get("/developer-mode", response_model = DeveloperModeResponse)
|
||||
def get_developer_mode(
|
||||
current_subject: str = Depends(get_current_subject),
|
||||
) -> DeveloperModeResponse:
|
||||
return _developer_mode_response()
|
||||
|
||||
|
||||
@_owner_settings_router.put("/developer-mode", response_model = DeveloperModeResponse)
|
||||
def update_developer_mode(
|
||||
payload: DeveloperModePayload, current_subject: str = Depends(get_current_subject)
|
||||
) -> DeveloperModeResponse:
|
||||
try:
|
||||
enabled = video_cpu_settings.set_video_cpu_setting(payload.video_cpu)
|
||||
except ValueError as exc:
|
||||
raise log_and_http_error(
|
||||
exc,
|
||||
400,
|
||||
safe_error_detail(exc, fallback = "Invalid Developer mode setting."),
|
||||
event = "settings.update_developer_mode_failed",
|
||||
log = logger,
|
||||
) from exc
|
||||
logger.info(
|
||||
"settings.developer_mode_updated subject=%s video_cpu=%s", current_subject, enabled
|
||||
)
|
||||
return _developer_mode_response()
|
||||
|
||||
|
||||
def _decision_description(checkpoint, mlx: bool) -> str:
|
||||
from core.systemone import catalog
|
||||
if (
|
||||
|
|
|
|||
|
|
@ -362,6 +362,7 @@ OWNER_PATHS = [
|
|||
"/upload-limit": ("PUT",),
|
||||
"/tool-result-limit": ("PUT",),
|
||||
"/helper-precache": ("PUT",),
|
||||
"/developer-mode": ("PUT",),
|
||||
"/download-transport": ("PUT",),
|
||||
"/xet-notice/reserve": ("POST",),
|
||||
"/model-memory": ("GET", "PUT"),
|
||||
|
|
|
|||
|
|
@ -59,6 +59,9 @@ def _patch(
|
|||
# when this suite runs on a macOS runner. Default follows `apple` so existing callers
|
||||
# keep the host they were written for.
|
||||
monkeypatch.setattr(hw.platform, "system", lambda: system or ("Darwin" if apple else "Linux"))
|
||||
# Developer mode's CPU opt-in reads the env and the settings store; pinned off so neither an
|
||||
# ambient UNSLOTH_VIDEO_ALLOW_CPU nor a real Studio home changes the matrix below.
|
||||
monkeypatch.setattr(hw, "_video_cpu_opt_in", lambda: False)
|
||||
|
||||
|
||||
# -- capability matrix --------------------------------------------------------------------------
|
||||
|
|
@ -248,7 +251,7 @@ def test_hardware_package_reexports_video_capability():
|
|||
|
||||
|
||||
def test_video_capability_separates_apple_silicon_from_intel_macs():
|
||||
cap = _func_src("utils/hardware/hardware.py", "video_capability")
|
||||
cap = _func_src("utils/hardware/hardware.py", "_video_capability_verdict")
|
||||
assert "DeviceType.CUDA, DeviceType.XPU" in cap
|
||||
assert "_has_torch()" in cap
|
||||
# Strip comments before asserting on the gate. This assertion used to name
|
||||
|
|
|
|||
336
studio/backend/tests/test_video_cpu_developer_mode.py
Normal file
336
studio/backend/tests/test_video_cpu_developer_mode.py
Normal file
|
|
@ -0,0 +1,336 @@
|
|||
# SPDX-License-Identifier: AGPL-3.0-only
|
||||
# Copyright 2026-present the Unsloth AI Inc. team. All rights reserved. See /studio/LICENSE.AGPL-3.0
|
||||
|
||||
"""Developer mode's CPU video opt-in (unslothai/unsloth#9458).
|
||||
|
||||
Off by default; when on, only a plain CPU-only host (reason ``no_accelerator``) is admitted, as
|
||||
experimental. Every other refusal stays one. ``UNSLOTH_VIDEO_ALLOW_CPU`` overrides the persisted
|
||||
owner setting both ways. The setting is installation wide: written only by the owner, read from the
|
||||
owner's store whoever asks. Hardware probes are mocked, so this runs on any host.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import sys
|
||||
import types
|
||||
|
||||
import pytest
|
||||
from fastapi import FastAPI
|
||||
from fastapi.testclient import TestClient
|
||||
|
||||
import utils.hardware.hardware as hw
|
||||
from auth import policy
|
||||
from auth.authentication import get_current_subject
|
||||
from utils import video_cpu_settings as vcs
|
||||
from utils.account_context import OWNER, AccountContext, bind_account, current_account, reset_account
|
||||
|
||||
ALICE = AccountContext("a" * 32, "alice")
|
||||
|
||||
|
||||
@pytest.fixture
|
||||
def store(monkeypatch):
|
||||
"""A fake studio_db keyed by the account that is bound when it is called."""
|
||||
per_account: dict[str, dict] = {}
|
||||
studio_db = types.ModuleType("storage.studio_db")
|
||||
|
||||
def get_app_setting(key, fallback = None):
|
||||
return per_account.get(current_account().account_id, {}).get(key, fallback)
|
||||
|
||||
def upsert_app_settings(settings, **_kw):
|
||||
per_account.setdefault(current_account().account_id, {}).update(settings)
|
||||
return dict(per_account[current_account().account_id])
|
||||
|
||||
studio_db.get_app_setting = get_app_setting
|
||||
studio_db.upsert_app_settings = upsert_app_settings
|
||||
monkeypatch.setitem(sys.modules, "storage.studio_db", studio_db)
|
||||
monkeypatch.delenv(vcs.VIDEO_CPU_ENV, raising = False)
|
||||
return per_account
|
||||
|
||||
|
||||
def _host(
|
||||
monkeypatch,
|
||||
*,
|
||||
device = hw.DeviceType.CPU,
|
||||
torch = True,
|
||||
apple = False,
|
||||
system = "Linux",
|
||||
chat_only_reason = "no_gpu",
|
||||
mps = None,
|
||||
torch_import_error = None,
|
||||
):
|
||||
monkeypatch.setattr(hw, "_has_torch", lambda: torch)
|
||||
monkeypatch.setattr(hw, "get_device", lambda: device)
|
||||
monkeypatch.setattr(hw, "is_apple_silicon", lambda: apple)
|
||||
monkeypatch.setattr(hw, "CHAT_ONLY_REASON", chat_only_reason)
|
||||
monkeypatch.setattr(hw, "CHAT_ONLY_DETAIL", None)
|
||||
monkeypatch.setattr(hw, "TORCH_IMPORT_ERROR", torch_import_error)
|
||||
monkeypatch.setattr(hw, "current_chat_only_verdict", lambda: (chat_only_reason, None))
|
||||
monkeypatch.setattr(hw, "_torch_mps_available", lambda: torch if mps is None else mps)
|
||||
monkeypatch.setattr(hw.platform, "system", lambda: system)
|
||||
|
||||
|
||||
def _opt_in(store, value):
|
||||
store.setdefault(OWNER.account_id, {})[vcs.VIDEO_CPU_SETTING_KEY] = value
|
||||
|
||||
|
||||
# -- capability matrix ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
def test_cpu_only_host_stays_refused_by_default(monkeypatch, store):
|
||||
_host(monkeypatch)
|
||||
cap = hw.video_capability()
|
||||
assert cap["video_supported"] is False
|
||||
assert cap["video_unsupported_reason"] == "no_accelerator"
|
||||
assert cap["video_cpu_experimental"] is False
|
||||
# The host is one the opt-in would admit, so Settings can offer it.
|
||||
assert cap["video_cpu_opt_in_applicable"] is True
|
||||
assert "Developer mode" in cap["video_unsupported_message"]
|
||||
|
||||
|
||||
def test_opt_in_admits_a_cpu_only_host_as_experimental(monkeypatch, store):
|
||||
_host(monkeypatch)
|
||||
_opt_in(store, True)
|
||||
cap = hw.video_capability()
|
||||
assert cap == {
|
||||
"video_supported": True,
|
||||
"video_unsupported_reason": None,
|
||||
"video_unsupported_message": None,
|
||||
"video_cpu_experimental": True,
|
||||
"video_cpu_opt_in_applicable": True,
|
||||
}
|
||||
|
||||
|
||||
def test_disabling_restores_the_gate(monkeypatch, store):
|
||||
_host(monkeypatch)
|
||||
_opt_in(store, True)
|
||||
assert hw.video_capability()["video_supported"] is True
|
||||
_opt_in(store, False)
|
||||
cap = hw.video_capability()
|
||||
assert cap["video_supported"] is False
|
||||
assert cap["video_unsupported_reason"] == "no_accelerator"
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"host, reason",
|
||||
[
|
||||
(dict(chat_only_reason = "detection_failed"), "detection_failed"),
|
||||
(dict(torch = False), "pytorch_not_installed"),
|
||||
(dict(system = "Darwin"), "macos_unsupported"),
|
||||
(dict(chat_only_reason = "torch_cpu_build"), "torch_cpu_build"),
|
||||
(dict(chat_only_reason = "torch_cuda_unavailable"), "torch_cuda_unavailable"),
|
||||
(dict(device = hw.DeviceType.MLX, apple = True, system = "Darwin", mps = False), "mps_unavailable"),
|
||||
(
|
||||
dict(
|
||||
device = hw.DeviceType.CPU,
|
||||
apple = True,
|
||||
system = "Darwin",
|
||||
torch = False,
|
||||
chat_only_reason = "mlx_unavailable",
|
||||
torch_import_error = "OSError('broken')",
|
||||
),
|
||||
"detection_failed",
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_every_other_refusal_stays_blocked_with_the_opt_in_on(monkeypatch, store, host, reason):
|
||||
"""Only the missing accelerator is waived: a broken probe, a missing or broken torch, an Intel
|
||||
Mac or a GPU torch cannot reach would be silently pushed to the CPU instead of repaired."""
|
||||
_host(monkeypatch, **host)
|
||||
_opt_in(store, True)
|
||||
monkeypatch.setenv(vcs.VIDEO_CPU_ENV, "1")
|
||||
cap = hw.video_capability()
|
||||
assert cap["video_supported"] is False
|
||||
assert cap["video_unsupported_reason"] == reason
|
||||
assert cap["video_cpu_experimental"] is False
|
||||
assert cap["video_cpu_opt_in_applicable"] is False
|
||||
|
||||
|
||||
@pytest.mark.parametrize("device", [hw.DeviceType.CUDA, hw.DeviceType.XPU])
|
||||
def test_accelerated_hosts_are_never_marked_experimental(monkeypatch, store, device):
|
||||
_host(monkeypatch, device = device, chat_only_reason = None)
|
||||
_opt_in(store, True)
|
||||
cap = hw.video_capability()
|
||||
assert cap["video_supported"] is True
|
||||
assert cap["video_cpu_experimental"] is False
|
||||
assert cap["video_cpu_opt_in_applicable"] is False
|
||||
|
||||
|
||||
def test_apple_silicon_with_metal_is_not_marked_experimental(monkeypatch, store):
|
||||
_host(monkeypatch, device = hw.DeviceType.MLX, apple = True, system = "Darwin", chat_only_reason = None)
|
||||
_opt_in(store, True)
|
||||
cap = hw.video_capability()
|
||||
assert cap["video_supported"] is True
|
||||
assert cap["video_cpu_experimental"] is False
|
||||
|
||||
|
||||
def test_an_unreadable_setting_reads_as_off(monkeypatch, store):
|
||||
_host(monkeypatch)
|
||||
|
||||
def boom():
|
||||
raise RuntimeError("settings store unavailable")
|
||||
|
||||
monkeypatch.setattr(vcs, "video_cpu_enabled", boom)
|
||||
cap = hw.video_capability()
|
||||
assert cap["video_supported"] is False
|
||||
assert cap["video_unsupported_reason"] == "no_accelerator"
|
||||
|
||||
|
||||
# -- env / setting precedence --------------------------------------------------------------------
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"env, setting, expected",
|
||||
[
|
||||
(None, None, False), # default off
|
||||
(None, True, True),
|
||||
(None, False, False),
|
||||
("1", None, True),
|
||||
("true", False, True), # env on beats setting off
|
||||
("0", True, False), # env off beats setting on
|
||||
("off", True, False),
|
||||
("", True, True), # empty env is unset
|
||||
("maybe", True, True), # unrecognised env falls through to the setting
|
||||
("maybe", None, False),
|
||||
],
|
||||
)
|
||||
def test_env_overrides_the_setting_both_ways(monkeypatch, store, env, setting, expected):
|
||||
_host(monkeypatch)
|
||||
if env is not None:
|
||||
monkeypatch.setenv(vcs.VIDEO_CPU_ENV, env)
|
||||
if setting is not None:
|
||||
_opt_in(store, setting)
|
||||
assert vcs.video_cpu_enabled() is expected
|
||||
assert hw.video_capability()["video_supported"] is expected
|
||||
|
||||
|
||||
def test_the_setting_is_read_from_the_owner_store_for_any_account(monkeypatch, store):
|
||||
_host(monkeypatch)
|
||||
_opt_in(store, True)
|
||||
store.setdefault(ALICE.account_id, {})[vcs.VIDEO_CPU_SETTING_KEY] = False
|
||||
token = bind_account(ALICE)
|
||||
try:
|
||||
assert vcs.get_video_cpu_setting() is True
|
||||
assert hw.video_capability()["video_cpu_experimental"] is True
|
||||
finally:
|
||||
reset_account(token)
|
||||
|
||||
|
||||
def test_setting_rejects_non_booleans(store):
|
||||
with pytest.raises(ValueError):
|
||||
vcs.set_video_cpu_setting("sometimes")
|
||||
|
||||
|
||||
# -- settings route ------------------------------------------------------------------------------
|
||||
|
||||
|
||||
def _client(account):
|
||||
from routes import settings as settings_route
|
||||
|
||||
app = FastAPI()
|
||||
|
||||
async def subject():
|
||||
token = bind_account(account)
|
||||
try:
|
||||
yield account.username
|
||||
finally:
|
||||
reset_account(token)
|
||||
|
||||
app.dependency_overrides[get_current_subject] = subject
|
||||
app.include_router(settings_route.router, prefix = "/api/settings")
|
||||
return TestClient(app)
|
||||
|
||||
|
||||
@pytest.fixture
|
||||
def multi_user(monkeypatch):
|
||||
monkeypatch.setattr(policy, "installation_is_multi_user", lambda: True)
|
||||
|
||||
|
||||
def test_a_managed_account_cannot_enable_cpu_video(monkeypatch, store, multi_user):
|
||||
_host(monkeypatch)
|
||||
with _client(ALICE) as client:
|
||||
response = client.put("/api/settings/developer-mode", json = {"video_cpu": True})
|
||||
assert response.status_code == 403
|
||||
assert vcs.VIDEO_CPU_SETTING_KEY not in store.get(OWNER.account_id, {})
|
||||
assert hw.video_capability()["video_supported"] is False
|
||||
|
||||
|
||||
def test_the_owner_toggles_cpu_video_and_reads_it_back(monkeypatch, store, multi_user):
|
||||
_host(monkeypatch)
|
||||
with _client(OWNER) as client:
|
||||
before = client.get("/api/settings/developer-mode").json()
|
||||
on = client.put("/api/settings/developer-mode", json = {"video_cpu": True})
|
||||
assert on.status_code == 200
|
||||
after_on = hw.video_capability()
|
||||
off = client.put("/api/settings/developer-mode", json = {"video_cpu": False}).json()
|
||||
assert before["video_cpu"] is False and before["default_video_cpu"] is False
|
||||
assert before["video_cpu_applicable"] is True
|
||||
assert before["min_ram_bytes"] == vcs.VIDEO_CPU_MIN_RAM_GB * 1024**3
|
||||
assert on.json()["video_cpu"] is True and on.json()["video_cpu_setting"] is True
|
||||
assert store[OWNER.account_id][vcs.VIDEO_CPU_SETTING_KEY] is False
|
||||
assert after_on["video_cpu_experimental"] is True
|
||||
assert off["video_cpu"] is False
|
||||
assert hw.video_capability()["video_supported"] is False
|
||||
|
||||
|
||||
def test_a_managed_account_can_read_but_not_write(monkeypatch, store, multi_user):
|
||||
_host(monkeypatch)
|
||||
_opt_in(store, True)
|
||||
with _client(ALICE) as client:
|
||||
response = client.get("/api/settings/developer-mode")
|
||||
assert response.status_code == 200
|
||||
assert response.json()["video_cpu"] is True
|
||||
|
||||
|
||||
def test_the_route_reports_the_env_override(monkeypatch, store, multi_user):
|
||||
_host(monkeypatch)
|
||||
monkeypatch.setenv(vcs.VIDEO_CPU_ENV, "0")
|
||||
with _client(OWNER) as client:
|
||||
body = client.put("/api/settings/developer-mode", json = {"video_cpu": True}).json()
|
||||
# The setting is saved, but the env decides the effective answer, and says so.
|
||||
assert body["video_cpu_setting"] is True
|
||||
assert body["video_cpu"] is False
|
||||
assert body["video_cpu_env_override"] is False
|
||||
|
||||
|
||||
def test_the_route_rejects_a_non_boolean(monkeypatch, store, multi_user):
|
||||
_host(monkeypatch)
|
||||
with _client(OWNER) as client:
|
||||
response = client.put("/api/settings/developer-mode", json = {"video_cpu": "yes"})
|
||||
assert response.status_code == 422
|
||||
|
||||
|
||||
def test_gpu_host_reports_the_opt_in_as_not_applicable(monkeypatch, store, multi_user):
|
||||
_host(monkeypatch, device = hw.DeviceType.CUDA, chat_only_reason = None)
|
||||
with _client(OWNER) as client:
|
||||
body = client.get("/api/settings/developer-mode").json()
|
||||
assert body["video_cpu_applicable"] is False
|
||||
|
||||
|
||||
# -- wiring (source) -----------------------------------------------------------------------------
|
||||
|
||||
|
||||
def test_health_reports_the_opt_in_only_for_a_no_gpu_verdict():
|
||||
"""The sidebar greys the Video row on a measured no_gpu host; health carries the opt-in so the
|
||||
row stays navigable once the owner enabled it. Read only on that host, so no other poll pays."""
|
||||
from pathlib import Path
|
||||
|
||||
src = (Path(__file__).resolve().parent.parent / "main.py").read_text(encoding = "utf-8")
|
||||
block = src[src.index('authed["video_cpu_opt_in"] = False') :][:400]
|
||||
assert 'if snapshot[0] and snapshot[1] == "no_gpu":' in block
|
||||
assert "video_cpu_enabled()" in block
|
||||
|
||||
|
||||
def test_hardware_endpoints_carry_the_experimental_marker():
|
||||
# Both system endpoints spread video_capability(), so the marker rides on both unchanged.
|
||||
from pathlib import Path
|
||||
|
||||
src = (Path(__file__).resolve().parent.parent / "main.py").read_text(encoding = "utf-8")
|
||||
assert src.count("**video_capability()") >= 2
|
||||
hook = (
|
||||
Path(__file__).resolve().parent.parent.parent
|
||||
/ "frontend"
|
||||
/ "src"
|
||||
/ "hooks"
|
||||
/ "use-hardware-info.ts"
|
||||
).read_text(encoding = "utf-8")
|
||||
assert "video_cpu_experimental" in hook
|
||||
|
|
@ -1964,8 +1964,35 @@ def export_capability() -> dict:
|
|||
}
|
||||
|
||||
|
||||
def _video_cpu_opt_in() -> bool:
|
||||
"""Developer mode's CPU video opt-in (env override, else the owner setting). Never raises: an unreadable setting is off."""
|
||||
try:
|
||||
from utils.video_cpu_settings import video_cpu_enabled
|
||||
return bool(video_cpu_enabled())
|
||||
except Exception as exc: # noqa: BLE001 -- the gate must answer even when the settings store cannot
|
||||
logger.debug("video_capability: CPU opt-in unreadable (%s); treating it as off", exc)
|
||||
return False
|
||||
|
||||
|
||||
def video_capability() -> dict:
|
||||
"""Whether video generation can run here, with a torch-aware reason when it cannot. Supported on CUDA and XPU, and on Apple Silicon with a usable MPS device: the pipelines in core/inference/video.py are device-neutral, resolving the device through the shared diffusion device target whose capability flags already decline the CUDA-only options, so Metal needs no branches of its own. Safe to call without torch. Returns {video_supported, video_unsupported_reason, video_unsupported_message}."""
|
||||
"""Whether video generation can run here, with a torch-aware reason when it cannot. Supported on CUDA and XPU, and on Apple Silicon with a usable MPS device: the pipelines in core/inference/video.py are device-neutral, resolving the device through the shared diffusion device target whose capability flags already decline the CUDA-only options, so Metal needs no branches of its own. Safe to call without torch.
|
||||
|
||||
A plain CPU-only host (reason ``no_accelerator``: torch imports, detection worked, no GPU at all) is refused by default; Developer mode (``utils.video_cpu_settings``) admits it as experimental, the diffusers pipelines then resolving to the float32 CPU target. Every other refusal stays one whatever the opt-in says. Returns {video_supported, video_unsupported_reason, video_unsupported_message, video_cpu_experimental, video_cpu_opt_in_applicable}: the last says whether the opt-in would change the answer on this host, so Settings can say when it has no effect."""
|
||||
cap = _video_capability_verdict()
|
||||
applicable = cap["video_unsupported_reason"] == "no_accelerator"
|
||||
if applicable and _video_cpu_opt_in():
|
||||
return {
|
||||
"video_supported": True,
|
||||
"video_unsupported_reason": None,
|
||||
"video_unsupported_message": None,
|
||||
"video_cpu_experimental": True,
|
||||
"video_cpu_opt_in_applicable": True,
|
||||
}
|
||||
return {**cap, "video_cpu_experimental": False, "video_cpu_opt_in_applicable": applicable}
|
||||
|
||||
|
||||
def _video_capability_verdict() -> dict:
|
||||
"""``video_capability`` without the Developer mode opt-in: {video_supported, video_unsupported_reason, video_unsupported_message}."""
|
||||
if get_device() in (DeviceType.CUDA, DeviceType.XPU):
|
||||
return {
|
||||
"video_supported": True,
|
||||
|
|
@ -2027,8 +2054,9 @@ def video_capability() -> dict:
|
|||
reason = "no_accelerator"
|
||||
message = (
|
||||
"Video generation requires an NVIDIA, AMD or Intel GPU. No supported accelerator was "
|
||||
"found on this host. (PyTorch is installed, but the video pipelines cannot run on CPU "
|
||||
"only.)"
|
||||
"found on this host. (PyTorch is installed, but the video pipelines are not enabled on "
|
||||
"CPU only. The owner can allow experimental CPU video in Settings > General > "
|
||||
"Developer mode.)"
|
||||
)
|
||||
return {
|
||||
"video_supported": False,
|
||||
|
|
|
|||
102
studio/backend/utils/video_cpu_settings.py
Normal file
102
studio/backend/utils/video_cpu_settings.py
Normal file
|
|
@ -0,0 +1,102 @@
|
|||
# SPDX-License-Identifier: AGPL-3.0-only
|
||||
# Copyright 2026-present the Unsloth AI Inc. team. All rights reserved. See /studio/LICENSE.AGPL-3.0
|
||||
|
||||
"""Developer mode: the installation-wide opt-in that lets video generation run on a CPU-only host.
|
||||
|
||||
Off by default. When on, ``video_capability()`` reports video as supported (experimental) on a host
|
||||
whose only blocker is the missing accelerator (reason ``no_accelerator``); every other refusal
|
||||
(detection failure, broken or missing torch, Intel Mac, a GPU that is present but unusable) stays
|
||||
blocked, since running on the CPU would not be what the user asked for there.
|
||||
|
||||
Precedence: ``UNSLOTH_VIDEO_ALLOW_CPU`` in the backend environment, when set to a recognised
|
||||
boolean, wins over the persisted owner setting in both directions (an admin can force it on for a
|
||||
headless install, or off for a shared one). Unset or unrecognised falls through to the setting.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import os
|
||||
from typing import Any, Optional
|
||||
|
||||
VIDEO_CPU_SETTING_KEY = "developer_mode_video_cpu"
|
||||
VIDEO_CPU_ENV = "UNSLOTH_VIDEO_ALLOW_CPU"
|
||||
DEFAULT_VIDEO_CPU_ENABLED = False
|
||||
|
||||
# Host RAM below which the Settings dialog warns before enabling. Wan2.1-T2V-1.3B, the smallest
|
||||
# video family, peaked at 24.5 GiB of server RSS on CPU (float32 pipeline, 832x480, 5 frames,
|
||||
# 3 steps; measured end to end through /video/load + /video/generate); 32 GiB leaves room for the
|
||||
# OS and the browser. Every larger family needs far more.
|
||||
VIDEO_CPU_MIN_RAM_GB = 32
|
||||
|
||||
_TRUE = {"1", "true", "yes", "on"}
|
||||
_FALSE = {"0", "false", "no", "off"}
|
||||
|
||||
|
||||
def _coerce_bool(value: Any) -> Optional[bool]:
|
||||
if isinstance(value, bool):
|
||||
return value
|
||||
if isinstance(value, str):
|
||||
normalized = value.strip().lower()
|
||||
if normalized in _TRUE:
|
||||
return True
|
||||
if normalized in _FALSE or normalized == "":
|
||||
return False
|
||||
return None
|
||||
|
||||
|
||||
def video_cpu_env_override() -> Optional[bool]:
|
||||
"""The environment's answer, or None when ``UNSLOTH_VIDEO_ALLOW_CPU`` is unset or unrecognised."""
|
||||
raw = os.environ.get(VIDEO_CPU_ENV)
|
||||
if raw is None or not raw.strip():
|
||||
return None
|
||||
normalized = raw.strip().lower()
|
||||
if normalized in _TRUE:
|
||||
return True
|
||||
if normalized in _FALSE:
|
||||
return False
|
||||
return None
|
||||
|
||||
|
||||
def get_video_cpu_setting() -> bool:
|
||||
"""The persisted owner setting. Read from the owner's store whoever asks, since it is installation
|
||||
wide; a missing or unreadable setting is the default (off)."""
|
||||
try:
|
||||
from storage.studio_db import get_app_setting
|
||||
from utils.account_context import OWNER, run_as
|
||||
stored = run_as(OWNER, get_app_setting, VIDEO_CPU_SETTING_KEY, None)
|
||||
except Exception:
|
||||
stored = None
|
||||
parsed = _coerce_bool(stored)
|
||||
return parsed if parsed is not None else DEFAULT_VIDEO_CPU_ENABLED
|
||||
|
||||
|
||||
def set_video_cpu_setting(value: Any) -> bool:
|
||||
"""Persist the owner setting. Callers are the owner-only settings route."""
|
||||
parsed = _coerce_bool(value)
|
||||
if parsed is None:
|
||||
raise ValueError("Developer mode CPU video must be true or false.")
|
||||
from storage.studio_db import upsert_app_settings
|
||||
|
||||
upsert_app_settings({VIDEO_CPU_SETTING_KEY: parsed})
|
||||
return parsed
|
||||
|
||||
|
||||
def video_cpu_enabled() -> bool:
|
||||
"""Whether CPU video is opted in: the env override when set, else the persisted setting. Never raises."""
|
||||
forced = video_cpu_env_override()
|
||||
if forced is not None:
|
||||
return forced
|
||||
return get_video_cpu_setting()
|
||||
|
||||
|
||||
def host_ram_bytes() -> Optional[int]:
|
||||
"""Total physical RAM, or None when it cannot be read. Never raises."""
|
||||
try:
|
||||
import psutil
|
||||
return int(psutil.virtual_memory().total)
|
||||
except Exception: # noqa: BLE001 -- fall back to sysconf
|
||||
pass
|
||||
try:
|
||||
return int(os.sysconf("SC_PAGE_SIZE") * os.sysconf("SC_PHYS_PAGES"))
|
||||
except Exception: # noqa: BLE001
|
||||
return None
|
||||
|
|
@ -364,8 +364,9 @@ function RootLayout() {
|
|||
const chatOnlyReason = usePlatformStore((s) => s.chatOnlyReason);
|
||||
// Video is the other row the sidebar grays out, on the two verdicts its pipelines cannot run on
|
||||
// at all. Same hint the row reads, so the two cannot disagree about which hosts they are.
|
||||
const videoCpuOptIn = usePlatformStore((s) => s.videoCpuOptIn);
|
||||
const videoDisabled =
|
||||
videoNavHint(chatOnlyMeasured, chatOnlyReason) !== undefined;
|
||||
videoNavHint(chatOnlyMeasured, chatOnlyReason, videoCpuOptIn) !== undefined;
|
||||
// Exact match: a prefix would treat /chatty as chat, hiding its not-found UI.
|
||||
const isChatRoute = pathname === "/chat";
|
||||
const { pinned, setPinned, togglePinned } = useSidebarPin();
|
||||
|
|
|
|||
|
|
@ -1307,6 +1307,7 @@ export function AppSidebar() {
|
|||
|
||||
const chatOnly = usePlatformStore((s) => s.isChatOnly());
|
||||
const chatOnlyReason = usePlatformStore((s) => s.chatOnlyReason);
|
||||
const videoCpuOptIn = usePlatformStore((s) => s.videoCpuOptIn);
|
||||
const chatOnlyDetail = usePlatformStore((s) => s.chatOnlyDetail);
|
||||
const chatOnlyHint = usePlatformStore((s) => s.chatOnlyHint);
|
||||
const detectionDeferred = usePlatformStore((s) => s.detectionDeferred);
|
||||
|
|
@ -1346,7 +1347,7 @@ export function AppSidebar() {
|
|||
? "Training needs an NVIDIA or AMD GPU."
|
||||
: undefined;
|
||||
// Everything without a hint reaches VideoPage, which answers from the backend's video verdict.
|
||||
const videoDisabledHint = videoNavHint(chatOnlyMeasured, chatOnlyReason);
|
||||
const videoDisabledHint = videoNavHint(chatOnlyMeasured, chatOnlyReason, videoCpuOptIn);
|
||||
const videoDisabled = videoDisabledHint !== undefined;
|
||||
|
||||
// Two things can change the verdict after the first /api/health: the backend MLX self-heal
|
||||
|
|
|
|||
|
|
@ -44,6 +44,9 @@ interface PlatformState {
|
|||
// MLX gate covers mlx, mlx-lm, and mlx-vlm together; record the blocker when known.
|
||||
chatOnlyDetail: string | null;
|
||||
chatOnlyHint: string | null;
|
||||
// Developer mode's CPU video opt-in, from authed /api/health; keeps the Video row navigable
|
||||
// on a no-GPU host that opted in.
|
||||
videoCpuOptIn: boolean;
|
||||
// authenticated /api/health values for cloudflareUrl, serverUrl, and secure.
|
||||
cloudflareUrl: string | null;
|
||||
serverUrl: string | null;
|
||||
|
|
@ -77,6 +80,7 @@ export const usePlatformStore = create<PlatformState>()((_, get) => ({
|
|||
chatOnlyReason: null,
|
||||
chatOnlyDetail: null,
|
||||
chatOnlyHint: null,
|
||||
videoCpuOptIn: false,
|
||||
cloudflareUrl: null,
|
||||
serverUrl: null,
|
||||
secure: false,
|
||||
|
|
@ -163,6 +167,7 @@ export async function fetchDeviceType(options?: {
|
|||
file_manager?: FileManager;
|
||||
chat_only?: boolean;
|
||||
chat_only_reason?: string | null;
|
||||
video_cpu_opt_in?: boolean;
|
||||
hardware_detecting?: boolean;
|
||||
cloudflare_url?: string | null;
|
||||
server_url?: string | null;
|
||||
|
|
@ -230,6 +235,11 @@ export async function fetchDeviceType(options?: {
|
|||
chatOnlyReason,
|
||||
chatOnlyDetail,
|
||||
chatOnlyHint,
|
||||
// Rides with the verdict: a provisional reply carries neither, so it keeps the stored one.
|
||||
videoCpuOptIn:
|
||||
data.video_cpu_opt_in === undefined
|
||||
? previous.videoCpuOptIn
|
||||
: data.video_cpu_opt_in === true,
|
||||
cloudflareUrl: data.cloudflare_url ?? null,
|
||||
serverUrl: data.server_url ?? null,
|
||||
secure: data.secure ?? false,
|
||||
|
|
|
|||
|
|
@ -47,8 +47,12 @@ export function isDetectionDeferred(data: HealthVerdict): boolean {
|
|||
export function videoNavHint(
|
||||
chatOnlyMeasured: boolean,
|
||||
chatOnlyReason: string | null,
|
||||
// Developer mode's CPU video opt-in (/api/health video_cpu_opt_in). Waives only the plain
|
||||
// no-GPU host; VideoPage still answers from the backend's own video verdict.
|
||||
videoCpuOptIn = false,
|
||||
): string | undefined {
|
||||
if (!chatOnlyMeasured) return undefined;
|
||||
if (chatOnlyReason === "no_gpu" && videoCpuOptIn) return undefined;
|
||||
// Not "or a GPU": an Intel Mac's own dGPU is not one the video pipelines can use, so offering
|
||||
// that reads as a fix that would not work. Mirrors the backend's message for this host.
|
||||
if (chatOnlyReason === "intel_mac")
|
||||
|
|
|
|||
76
studio/frontend/src/features/settings/api/developer-mode.ts
Normal file
76
studio/frontend/src/features/settings/api/developer-mode.ts
Normal file
|
|
@ -0,0 +1,76 @@
|
|||
// SPDX-License-Identifier: AGPL-3.0-only
|
||||
// Copyright 2026-present the Unsloth AI Inc. team. All rights reserved. See /studio/LICENSE.AGPL-3.0
|
||||
|
||||
import { authFetch } from "@/features/auth";
|
||||
import { readFastApiError } from "@/lib/format-fastapi-error";
|
||||
|
||||
export type DeveloperModeSettings = {
|
||||
/** Effective answer: the env override when set, else the saved setting. */
|
||||
videoCpu: boolean;
|
||||
videoCpuSetting: boolean;
|
||||
defaultVideoCpu: boolean;
|
||||
/** true / false when UNSLOTH_VIDEO_ALLOW_CPU decides, null when the setting does. */
|
||||
videoCpuEnvOverride: boolean | null;
|
||||
/** Whether the opt-in changes anything on this host (a CPU-only host, nothing else wrong). */
|
||||
videoCpuApplicable: boolean;
|
||||
hostRamBytes: number | null;
|
||||
minRamBytes: number;
|
||||
};
|
||||
|
||||
type ApiDeveloperModeSettings = {
|
||||
// biome-ignore lint/style/useNamingConvention: API schema
|
||||
video_cpu: boolean;
|
||||
// biome-ignore lint/style/useNamingConvention: API schema
|
||||
video_cpu_setting: boolean;
|
||||
// biome-ignore lint/style/useNamingConvention: API schema
|
||||
default_video_cpu: boolean;
|
||||
// biome-ignore lint/style/useNamingConvention: API schema
|
||||
video_cpu_env_override: boolean | null;
|
||||
// biome-ignore lint/style/useNamingConvention: API schema
|
||||
video_cpu_applicable: boolean;
|
||||
// biome-ignore lint/style/useNamingConvention: API schema
|
||||
host_ram_bytes: number | null;
|
||||
// biome-ignore lint/style/useNamingConvention: API schema
|
||||
min_ram_bytes: number;
|
||||
};
|
||||
|
||||
export function developerModeFromApi(
|
||||
settings: ApiDeveloperModeSettings,
|
||||
): DeveloperModeSettings {
|
||||
return {
|
||||
videoCpu: settings.video_cpu,
|
||||
videoCpuSetting: settings.video_cpu_setting,
|
||||
defaultVideoCpu: settings.default_video_cpu,
|
||||
videoCpuEnvOverride: settings.video_cpu_env_override ?? null,
|
||||
videoCpuApplicable: settings.video_cpu_applicable,
|
||||
hostRamBytes: settings.host_ram_bytes ?? null,
|
||||
minRamBytes: settings.min_ram_bytes,
|
||||
};
|
||||
}
|
||||
|
||||
export async function loadDeveloperModeSettings(): Promise<DeveloperModeSettings> {
|
||||
const res = await authFetch("/api/settings/developer-mode");
|
||||
if (!res.ok) {
|
||||
throw new Error(
|
||||
await readFastApiError(res, "Failed to load Developer mode settings"),
|
||||
);
|
||||
}
|
||||
return developerModeFromApi(await res.json());
|
||||
}
|
||||
|
||||
export async function updateDeveloperModeSettings(
|
||||
videoCpu: boolean,
|
||||
): Promise<DeveloperModeSettings> {
|
||||
const res = await authFetch("/api/settings/developer-mode", {
|
||||
method: "PUT",
|
||||
headers: { "Content-Type": "application/json" },
|
||||
// biome-ignore lint/style/useNamingConvention: API schema
|
||||
body: JSON.stringify({ video_cpu: videoCpu }),
|
||||
});
|
||||
if (!res.ok) {
|
||||
throw new Error(
|
||||
await readFastApiError(res, "Failed to update Developer mode settings"),
|
||||
);
|
||||
}
|
||||
return developerModeFromApi(await res.json());
|
||||
}
|
||||
|
|
@ -0,0 +1,191 @@
|
|||
// SPDX-License-Identifier: AGPL-3.0-only
|
||||
// Copyright 2026-present the Unsloth AI Inc. team. All rights reserved. See /studio/LICENSE.AGPL-3.0
|
||||
|
||||
import { Button } from "@/components/ui/button";
|
||||
import {
|
||||
Dialog,
|
||||
DialogContent,
|
||||
DialogDescription,
|
||||
DialogFooter,
|
||||
DialogHeader,
|
||||
DialogTitle,
|
||||
} from "@/components/ui/dialog";
|
||||
import { Switch } from "@/components/ui/switch";
|
||||
import { usePlatformStore } from "@/config/env";
|
||||
import { refreshHardwareInfo } from "@/hooks/use-hardware-info";
|
||||
import { useT } from "@/i18n";
|
||||
import { useEffect, useState } from "react";
|
||||
import {
|
||||
type DeveloperModeSettings,
|
||||
loadDeveloperModeSettings,
|
||||
updateDeveloperModeSettings,
|
||||
} from "../api/developer-mode";
|
||||
import {
|
||||
videoCpuRamCheck,
|
||||
videoCpuToggleNeedsConfirm,
|
||||
} from "../lib/video-cpu-warning";
|
||||
import { SettingsRow } from "./settings-row";
|
||||
import { SettingsSection } from "./settings-section";
|
||||
|
||||
/** Owner-only. Developer mode's one switch: experimental video generation on a CPU-only host.
|
||||
* Enabling asks first, with the host's RAM against the minimum; disabling restores the GPU gate. */
|
||||
export function DeveloperModeSection() {
|
||||
const t = useT();
|
||||
const [settings, setSettings] = useState<DeveloperModeSettings | null>(null);
|
||||
const [error, setError] = useState<string | null>(null);
|
||||
const [saving, setSaving] = useState(false);
|
||||
const [confirmOpen, setConfirmOpen] = useState(false);
|
||||
|
||||
useEffect(() => {
|
||||
let cancelled = false;
|
||||
void loadDeveloperModeSettings()
|
||||
.then((next) => {
|
||||
if (cancelled) return;
|
||||
setSettings(next);
|
||||
setError(null);
|
||||
})
|
||||
.catch((err) => {
|
||||
if (cancelled) return;
|
||||
setError(
|
||||
err instanceof Error
|
||||
? err.message
|
||||
: t("settings.general.developerMode.loadError"),
|
||||
);
|
||||
});
|
||||
return () => {
|
||||
cancelled = true;
|
||||
};
|
||||
}, [t]);
|
||||
|
||||
const save = async (videoCpu: boolean) => {
|
||||
setSaving(true);
|
||||
setError(null);
|
||||
try {
|
||||
const next = await updateDeveloperModeSettings(videoCpu);
|
||||
setSettings(next);
|
||||
// Both gates are cached: the sidebar's Video row reads the /api/health verdict and the Video
|
||||
// page /api/system/hardware. Update the one and re-read the other, so neither needs a reload.
|
||||
usePlatformStore.setState({ videoCpuOptIn: next.videoCpu });
|
||||
void refreshHardwareInfo();
|
||||
} catch (err) {
|
||||
setError(
|
||||
err instanceof Error
|
||||
? err.message
|
||||
: t("settings.general.developerMode.saveError"),
|
||||
);
|
||||
} finally {
|
||||
setSaving(false);
|
||||
}
|
||||
};
|
||||
|
||||
const onToggle = (next: boolean) => {
|
||||
if (videoCpuToggleNeedsConfirm(next)) {
|
||||
setConfirmOpen(true);
|
||||
return;
|
||||
}
|
||||
void save(false);
|
||||
};
|
||||
|
||||
const ram = settings
|
||||
? videoCpuRamCheck(settings.hostRamBytes, settings.minRamBytes)
|
||||
: null;
|
||||
const envForced = settings?.videoCpuEnvOverride ?? null;
|
||||
|
||||
let note: string | null = null;
|
||||
if (error) note = error;
|
||||
else if (envForced !== null)
|
||||
note = t(
|
||||
envForced
|
||||
? "settings.general.developerMode.forcedOnByEnv"
|
||||
: "settings.general.developerMode.forcedOffByEnv",
|
||||
);
|
||||
else if (settings && !settings.videoCpuApplicable)
|
||||
note = t("settings.general.developerMode.notApplicable");
|
||||
|
||||
return (
|
||||
<>
|
||||
<SettingsSection title={t("settings.general.developerMode.sectionTitle")}>
|
||||
<SettingsRow
|
||||
label={t("settings.general.developerMode.videoCpu")}
|
||||
description={t("settings.general.developerMode.videoCpuDescription")}
|
||||
below={
|
||||
note ? (
|
||||
<span
|
||||
data-testid="developer-mode-note"
|
||||
className={
|
||||
error
|
||||
? "max-w-[calc(260px*var(--ui-space-scale,1))] text-right text-xs text-destructive"
|
||||
: "max-w-[calc(260px*var(--ui-space-scale,1))] text-right text-xs text-muted-foreground"
|
||||
}
|
||||
>
|
||||
{note}
|
||||
</span>
|
||||
) : null
|
||||
}
|
||||
>
|
||||
<Switch
|
||||
data-testid="developer-mode-video-cpu"
|
||||
checked={settings?.videoCpu ?? false}
|
||||
disabled={!settings || saving || envForced !== null}
|
||||
onCheckedChange={onToggle}
|
||||
/>
|
||||
</SettingsRow>
|
||||
</SettingsSection>
|
||||
|
||||
<Dialog open={confirmOpen} onOpenChange={setConfirmOpen}>
|
||||
<DialogContent className="max-w-md" data-testid="developer-mode-confirm">
|
||||
<DialogHeader>
|
||||
<DialogTitle>
|
||||
{t("settings.general.developerMode.confirmTitle")}
|
||||
</DialogTitle>
|
||||
<DialogDescription>
|
||||
{t("settings.general.developerMode.confirmWarning")}
|
||||
</DialogDescription>
|
||||
</DialogHeader>
|
||||
<div className="flex flex-col gap-2 text-sm text-muted-foreground">
|
||||
{ram?.status === "below" ? (
|
||||
<p
|
||||
data-testid="developer-mode-ram-warning"
|
||||
className="text-amber-600 dark:text-amber-400"
|
||||
>
|
||||
{t("settings.general.developerMode.ramBelowMinimum", {
|
||||
host: String(ram.hostGib),
|
||||
min: String(ram.minGib),
|
||||
})}
|
||||
</p>
|
||||
) : ram?.status === "ok" ? (
|
||||
<p>
|
||||
{t("settings.general.developerMode.ramOk", {
|
||||
host: String(ram.hostGib),
|
||||
min: String(ram.minGib),
|
||||
})}
|
||||
</p>
|
||||
) : ram ? (
|
||||
<p>
|
||||
{t("settings.general.developerMode.ramUnknown", {
|
||||
min: String(ram.minGib),
|
||||
})}
|
||||
</p>
|
||||
) : null}
|
||||
<p>{t("settings.general.developerMode.performanceEstimate")}</p>
|
||||
</div>
|
||||
<DialogFooter>
|
||||
<Button variant="outline" onClick={() => setConfirmOpen(false)}>
|
||||
{t("common.cancel")}
|
||||
</Button>
|
||||
<Button
|
||||
disabled={saving}
|
||||
onClick={() => {
|
||||
setConfirmOpen(false);
|
||||
void save(true);
|
||||
}}
|
||||
className="bg-destructive hover:bg-destructive/90 text-destructive-foreground"
|
||||
>
|
||||
{t("settings.general.developerMode.confirmAction")}
|
||||
</Button>
|
||||
</DialogFooter>
|
||||
</DialogContent>
|
||||
</Dialog>
|
||||
</>
|
||||
);
|
||||
}
|
||||
|
|
@ -0,0 +1,38 @@
|
|||
// SPDX-License-Identifier: AGPL-3.0-only
|
||||
// Copyright 2026-present the Unsloth AI Inc. team. All rights reserved. See /studio/LICENSE.AGPL-3.0
|
||||
|
||||
/** Developer mode CPU video: what the confirm dialog says about this host. Pure, so it is unit tested. */
|
||||
|
||||
const GIB = 1024 ** 3;
|
||||
|
||||
export type VideoCpuRamCheck = {
|
||||
/** "below" warns; "unknown" (no reading) says nothing either way. */
|
||||
status: "below" | "ok" | "unknown";
|
||||
hostGib: number | null;
|
||||
minGib: number;
|
||||
};
|
||||
|
||||
/** Host RAM against the backend's minimum, both rounded to whole GiB for display. */
|
||||
export function videoCpuRamCheck(
|
||||
hostRamBytes: number | null | undefined,
|
||||
minRamBytes: number,
|
||||
): VideoCpuRamCheck {
|
||||
const minGib = Math.round(minRamBytes / GIB);
|
||||
if (
|
||||
typeof hostRamBytes !== "number" ||
|
||||
!Number.isFinite(hostRamBytes) ||
|
||||
hostRamBytes <= 0
|
||||
) {
|
||||
return { status: "unknown", hostGib: null, minGib };
|
||||
}
|
||||
const hostGib = Math.round(hostRamBytes / GIB);
|
||||
// Compared in bytes with 5% slack: a 32 GB machine reports ~31.3 GiB after firmware and kernel
|
||||
// reservations, and must not be told it is below a 32 GiB minimum.
|
||||
const status = hostRamBytes >= minRamBytes * 0.95 ? "ok" : "below";
|
||||
return { status, hostGib, minGib };
|
||||
}
|
||||
|
||||
/** Only turning the opt-in ON asks first; turning it off restores the GPU gate at once. */
|
||||
export function videoCpuToggleNeedsConfirm(next: boolean): boolean {
|
||||
return next;
|
||||
}
|
||||
|
|
@ -36,6 +36,8 @@ export const SETTINGS_SEARCH_INDEX: Record<SettingsTab, TranslationKey[]> = {
|
|||
"settings.general.rag.embeddingModel",
|
||||
"settings.general.helperLlm.sectionTitle",
|
||||
"settings.general.helperLlm.preloadOnStartup",
|
||||
"settings.general.developerMode.sectionTitle",
|
||||
"settings.general.developerMode.videoCpu",
|
||||
"settings.general.hub.sectionTitle",
|
||||
"settings.general.hub.source",
|
||||
"settings.general.hub.endpoint",
|
||||
|
|
|
|||
|
|
@ -68,6 +68,7 @@ import {
|
|||
} from "@/features/library";
|
||||
import { ChangePasswordDialog } from "../components/change-password-dialog";
|
||||
import { DesktopRepairControl } from "../components/desktop-repair-control";
|
||||
import { DeveloperModeSection } from "../components/developer-mode-section";
|
||||
import {
|
||||
DesktopUpdateControl,
|
||||
DesktopUpdateNote,
|
||||
|
|
@ -836,6 +837,8 @@ export function GeneralTab() {
|
|||
/>
|
||||
</SettingsRow>
|
||||
</SettingsSection>
|
||||
|
||||
<DeveloperModeSection />
|
||||
</>
|
||||
) : null}
|
||||
|
||||
|
|
|
|||
|
|
@ -4,6 +4,7 @@
|
|||
import { generationFailureLogsAction } from "@/features/settings/lib/view-logs-action";
|
||||
import { useCallback, useEffect, useMemo, useRef, useState, type ReactNode } from "react";
|
||||
import {
|
||||
Alert02Icon,
|
||||
ArrowExpand01Icon,
|
||||
ArrowLeftRightIcon,
|
||||
ArrowUpDownIcon,
|
||||
|
|
@ -1018,16 +1019,41 @@ export function VideoPage({
|
|||
}
|
||||
|
||||
return (
|
||||
<VideoGenerator active={active} onInitialReady={onInitialReady} />
|
||||
<VideoGenerator
|
||||
active={active}
|
||||
onInitialReady={onInitialReady}
|
||||
cpuExperimental={hardware.videoCpuExperimental}
|
||||
/>
|
||||
);
|
||||
}
|
||||
|
||||
/** Kept up for as long as Developer mode is what lets this host render: nothing else on the page
|
||||
* says the clip is about to run on the CPU. */
|
||||
function VideoCpuExperimentalBanner() {
|
||||
return (
|
||||
<div
|
||||
role="status"
|
||||
data-testid="video-cpu-experimental"
|
||||
className="relative z-40 flex shrink-0 items-start gap-2 border-b border-amber-500/30 bg-amber-500/10 px-4 py-1.5 text-xs leading-snug text-amber-700 dark:text-amber-300"
|
||||
>
|
||||
<HugeiconsIcon icon={Alert02Icon} strokeWidth={1.75} className="mt-px size-3.5 shrink-0" />
|
||||
<span>
|
||||
<span className="font-medium">CPU (experimental).</span> No supported GPU was found, so
|
||||
Developer mode runs video on the CPU. A clip may take hours, use large amounts of RAM and
|
||||
freeze the system. Turn it off in Settings, General, Developer mode.
|
||||
</span>
|
||||
</div>
|
||||
);
|
||||
}
|
||||
|
||||
function VideoGenerator({
|
||||
active = true,
|
||||
onInitialReady,
|
||||
cpuExperimental = false,
|
||||
}: {
|
||||
active?: boolean;
|
||||
onInitialReady?: () => void;
|
||||
cpuExperimental?: boolean;
|
||||
}) {
|
||||
const t = useT();
|
||||
const initialReadySent = useRef(false);
|
||||
|
|
@ -3860,6 +3886,7 @@ function VideoGenerator({
|
|||
</div>
|
||||
</DialogContent>
|
||||
</Dialog>
|
||||
{cpuExperimental ? <VideoCpuExperimentalBanner /> : null}
|
||||
{/* Header: selector over the rail, Library link over the preview, as on Images and Audio. */}
|
||||
<div className="pointer-events-none relative z-40 grid h-[calc(48px*var(--ui-space-scale,1))] shrink-0 grid-cols-[minmax(0,var(--media-rail-width,calc(408px*var(--ui-space-scale,1))))_minmax(13rem,1fr)] @max-[30rem]:grid-cols-[minmax(0,1fr)_auto]">
|
||||
<div
|
||||
|
|
|
|||
|
|
@ -43,6 +43,9 @@ export interface HardwareInfo {
|
|||
videoSupported: boolean | null;
|
||||
videoUnsupportedReason: string | null;
|
||||
videoUnsupportedMessage: string | null;
|
||||
// True when video is supported only because Developer mode admitted a CPU-only host; the
|
||||
// Video page keeps a warning up while it is. False against an older backend.
|
||||
videoCpuExperimental: boolean;
|
||||
loaded: boolean;
|
||||
}
|
||||
|
||||
|
|
@ -66,6 +69,7 @@ const DEFAULT: HardwareInfo = {
|
|||
videoSupported: null,
|
||||
videoUnsupportedReason: null,
|
||||
videoUnsupportedMessage: null,
|
||||
videoCpuExperimental: false,
|
||||
loaded: false,
|
||||
};
|
||||
|
||||
|
|
@ -128,6 +132,7 @@ async function fetchOnce(): Promise<HardwareInfo> {
|
|||
videoSupported: data?.video_supported ?? null,
|
||||
videoUnsupportedReason: data?.video_unsupported_reason ?? null,
|
||||
videoUnsupportedMessage: data?.video_unsupported_message ?? null,
|
||||
videoCpuExperimental: data?.video_cpu_experimental === true,
|
||||
loaded: true,
|
||||
};
|
||||
if (generation === cacheGeneration) {
|
||||
|
|
|
|||
|
|
@ -1704,6 +1704,23 @@ export const ar = {
|
|||
loadError: "فشل تحميل إعدادات نموذج LLM المساعد.",
|
||||
saveError: "فشل حفظ إعدادات نموذج LLM المساعد.",
|
||||
},
|
||||
developerMode: {
|
||||
sectionTitle: "وضع المطوّر",
|
||||
videoCpu: "السماح بتوليد الفيديو على CPU (تجريبي)",
|
||||
videoCpuDescription: "يتيح تشغيل صفحة الفيديو على جهاز لا يحتوي على GPU مدعوم. مُعطّل افتراضيًا؛ غير مدعوم وبطيء جدًا.",
|
||||
notApplicable: "ليس له تأثير على هذا الجهاز: إما أن الفيديو يعمل بالفعل على GPU الخاص به، أو أنه محظور بسبب أمر لا يستطيع CPU تجاوزه.",
|
||||
forcedOnByEnv: "مُفعّل بواسطة UNSLOTH_VIDEO_ALLOW_CPU في بيئة الخادم الخلفي.",
|
||||
forcedOffByEnv: "مُعطّل بواسطة UNSLOTH_VIDEO_ALLOW_CPU في بيئة الخادم الخلفي.",
|
||||
confirmTitle: "تفعيل توليد الفيديو على CPU؟",
|
||||
confirmWarning: "قد يستغرق توليد الفيديو على CPU ساعات، ويستهلك كميات كبيرة من RAM، وقد يتسبب في تجميد نظامك. تابع على مسؤوليتك الخاصة.",
|
||||
ramBelowMinimum: "يحتوي هذا الجهاز على {host} GB من RAM، وهو أقل من {min} GB التي يحتاجها أصغر نموذج فيديو على CPU. من المرجح أن يفشل التحميل أو يتجمد النظام.",
|
||||
ramOk: "يحتوي هذا الجهاز على {host} GB من RAM. يحتاج أصغر نموذج فيديو إلى حوالي {min} GB على CPU؛ وتحتاج النماذج الأكبر إلى أكثر من ذلك بكثير.",
|
||||
ramUnknown: "يحتاج أصغر نموذج فيديو إلى حوالي {min} GB من RAM على CPU؛ وتحتاج النماذج الأكبر إلى أكثر من ذلك بكثير.",
|
||||
performanceEstimate: "توقّع دقائق لكل خطوة إزالة ضوضاء: استغرق مقطع من 5 إطارات بدقة 832x480 من Wan2.1 1.3B بثلاث خطوات حوالي 4 دقائق على 16 خيط CPU، وقد يستغرق مقطع كامل الطول بالإعدادات الافتراضية ساعات.",
|
||||
confirmAction: "تفعيل على أي حال",
|
||||
loadError: "تعذّر تحميل إعدادات وضع المطوّر.",
|
||||
saveError: "تعذّر حفظ إعدادات وضع المطوّر.",
|
||||
},
|
||||
modelAutoSwitch: {
|
||||
sectionTitle: "التبديل التلقائي للنموذج (OpenAI API)",
|
||||
enable: "تبديل النموذج حسب الطلب",
|
||||
|
|
|
|||
|
|
@ -1718,6 +1718,23 @@ export const de = {
|
|||
saveError:
|
||||
"Helfer-LLM-Einstellungen konnten nicht gespeichert werden.",
|
||||
},
|
||||
developerMode: {
|
||||
sectionTitle: "Entwicklermodus",
|
||||
videoCpu: "Videogenerierung auf der CPU erlauben (experimentell)",
|
||||
videoCpuDescription: "Ermöglicht die Videoseite auf einem Host ohne unterstützte GPU. Standardmäßig aus; nicht unterstützt und sehr langsam.",
|
||||
notApplicable: "Hat auf diesem Rechner keine Wirkung: Video läuft entweder bereits auf der GPU oder wird durch etwas blockiert, das die CPU nicht umgehen kann.",
|
||||
forcedOnByEnv: "Aktiviert durch UNSLOTH_VIDEO_ALLOW_CPU in der Backend-Umgebung.",
|
||||
forcedOffByEnv: "Deaktiviert durch UNSLOTH_VIDEO_ALLOW_CPU in der Backend-Umgebung.",
|
||||
confirmTitle: "Videogenerierung auf der CPU aktivieren?",
|
||||
confirmWarning: "Die Videogenerierung auf der CPU kann Stunden dauern, große Mengen RAM verbrauchen und dein System einfrieren lassen. Fortfahren auf eigenes Risiko.",
|
||||
ramBelowMinimum: "Dieser Rechner hat {host} GB RAM, weniger als die {min} GB, die das kleinste Videomodell auf der CPU benötigt. Das Laden schlägt wahrscheinlich fehl oder friert das System ein.",
|
||||
ramOk: "Dieser Rechner hat {host} GB RAM. Das kleinste Videomodell benötigt auf der CPU etwa {min} GB; größere Modelle benötigen deutlich mehr.",
|
||||
ramUnknown: "Das kleinste Videomodell benötigt auf der CPU etwa {min} GB RAM; größere Modelle benötigen deutlich mehr.",
|
||||
performanceEstimate: "Rechne mit Minuten pro Denoising-Schritt: Ein 832x480-Clip mit 5 Frames aus Wan2.1 1.3B mit 3 Schritten dauerte auf 16 CPU-Threads etwa 4 Minuten, und ein Clip in voller Länge mit Standardeinstellungen kann Stunden dauern.",
|
||||
confirmAction: "Trotzdem aktivieren",
|
||||
loadError: "Entwicklermodus-Einstellungen konnten nicht geladen werden.",
|
||||
saveError: "Entwicklermodus-Einstellungen konnten nicht gespeichert werden.",
|
||||
},
|
||||
modelAutoSwitch: {
|
||||
sectionTitle: "Automatischer Modellwechsel (OpenAI API)",
|
||||
enable: "Modell je Anfrage wechseln",
|
||||
|
|
|
|||
|
|
@ -1760,6 +1760,32 @@ export const en = {
|
|||
loadError: "Failed to load Helper LLM settings.",
|
||||
saveError: "Failed to save Helper LLM settings.",
|
||||
},
|
||||
developerMode: {
|
||||
sectionTitle: "Developer mode",
|
||||
videoCpu: "Allow video generation on CPU (experimental)",
|
||||
videoCpuDescription:
|
||||
"Lets the Video page run on a host with no supported GPU. Off by default; unsupported and very slow.",
|
||||
notApplicable:
|
||||
"Has no effect on this machine: video either already runs on its GPU, or is blocked by something the CPU cannot work around.",
|
||||
forcedOnByEnv:
|
||||
"Turned on by UNSLOTH_VIDEO_ALLOW_CPU in the backend environment.",
|
||||
forcedOffByEnv:
|
||||
"Turned off by UNSLOTH_VIDEO_ALLOW_CPU in the backend environment.",
|
||||
confirmTitle: "Enable CPU video generation?",
|
||||
confirmWarning:
|
||||
"CPU video generation may take hours, consume large amounts of RAM, and may freeze your system. Continue at your own risk.",
|
||||
ramBelowMinimum:
|
||||
"This machine has {host} GB of RAM, below the {min} GB the smallest video model needs on CPU. Loading is likely to fail or freeze the system.",
|
||||
ramOk:
|
||||
"This machine has {host} GB of RAM. The smallest video model needs about {min} GB on CPU; larger models need far more.",
|
||||
ramUnknown:
|
||||
"The smallest video model needs about {min} GB of RAM on CPU; larger models need far more.",
|
||||
performanceEstimate:
|
||||
"Expect minutes per denoising step: a 5-frame 832x480 clip from Wan2.1 1.3B at 3 steps took about 4 minutes on 16 CPU threads, and a full-length clip at default settings can take hours.",
|
||||
confirmAction: "Enable anyway",
|
||||
loadError: "Failed to load Developer mode settings.",
|
||||
saveError: "Failed to save Developer mode settings.",
|
||||
},
|
||||
modelAutoSwitch: {
|
||||
sectionTitle: "Model auto-switch (OpenAI API)",
|
||||
enable: "Switch model by request",
|
||||
|
|
|
|||
|
|
@ -1714,6 +1714,23 @@ export const es = {
|
|||
loadError: "No se pudo cargar la configuración del LLM auxiliar.",
|
||||
saveError: "No se pudo guardar la configuración del LLM auxiliar.",
|
||||
},
|
||||
developerMode: {
|
||||
sectionTitle: "Modo desarrollador",
|
||||
videoCpu: "Permitir la generación de video en CPU (experimental)",
|
||||
videoCpuDescription: "Permite usar la página de Video en un equipo sin GPU compatible. Desactivado por defecto; no es compatible oficialmente y es muy lento.",
|
||||
notApplicable: "No tiene efecto en este equipo: el video ya se ejecuta en su GPU o está bloqueado por algo que la CPU no puede sortear.",
|
||||
forcedOnByEnv: "Activado por UNSLOTH_VIDEO_ALLOW_CPU en el entorno del backend.",
|
||||
forcedOffByEnv: "Desactivado por UNSLOTH_VIDEO_ALLOW_CPU en el entorno del backend.",
|
||||
confirmTitle: "¿Activar la generación de video en CPU?",
|
||||
confirmWarning: "La generación de video en CPU puede tardar horas, consumir grandes cantidades de RAM y congelar tu sistema. Continúa bajo tu propio riesgo.",
|
||||
ramBelowMinimum: "Este equipo tiene {host} GB de RAM, menos de los {min} GB que necesita el modelo de video más pequeño en CPU. Es probable que la carga falle o congele el sistema.",
|
||||
ramOk: "Este equipo tiene {host} GB de RAM. El modelo de video más pequeño necesita unos {min} GB en CPU; los modelos más grandes necesitan mucho más.",
|
||||
ramUnknown: "El modelo de video más pequeño necesita unos {min} GB de RAM en CPU; los modelos más grandes necesitan mucho más.",
|
||||
performanceEstimate: "Espera minutos por cada paso de eliminación de ruido: un clip de 5 fotogramas a 832x480 de Wan2.1 1.3B con 3 pasos tardó unos 4 minutos en 16 hilos de CPU, y un clip de duración completa con la configuración predeterminada puede tardar horas.",
|
||||
confirmAction: "Activar de todos modos",
|
||||
loadError: "No se pudo cargar la configuración del modo desarrollador.",
|
||||
saveError: "No se pudo guardar la configuración del modo desarrollador.",
|
||||
},
|
||||
modelAutoSwitch: {
|
||||
sectionTitle: "Cambio automático de modelo (API de OpenAI)",
|
||||
enable: "Cambiar de modelo según la solicitud",
|
||||
|
|
|
|||
|
|
@ -1716,6 +1716,23 @@ export const fr = {
|
|||
loadError: "Échec du chargement des paramètres du LLM assistant.",
|
||||
saveError: "Échec de l'enregistrement des paramètres du LLM assistant.",
|
||||
},
|
||||
developerMode: {
|
||||
sectionTitle: "Mode développeur",
|
||||
videoCpu: "Autoriser la génération vidéo sur CPU (expérimental)",
|
||||
videoCpuDescription: "Permet d'utiliser la page Vidéo sur une machine sans GPU compatible. Désactivé par défaut ; non pris en charge et très lent.",
|
||||
notApplicable: "Sans effet sur cette machine : la vidéo s'exécute déjà sur son GPU, ou elle est bloquée par un problème que le CPU ne peut pas contourner.",
|
||||
forcedOnByEnv: "Activé par UNSLOTH_VIDEO_ALLOW_CPU dans l'environnement du backend.",
|
||||
forcedOffByEnv: "Désactivé par UNSLOTH_VIDEO_ALLOW_CPU dans l'environnement du backend.",
|
||||
confirmTitle: "Activer la génération vidéo sur CPU ?",
|
||||
confirmWarning: "La génération vidéo sur CPU peut prendre des heures, consommer de grandes quantités de RAM et figer votre système. Continuez à vos risques et périls.",
|
||||
ramBelowMinimum: "Cette machine dispose de {host} GB de RAM, moins que les {min} GB nécessaires au plus petit modèle vidéo sur CPU. Le chargement risque d'échouer ou de figer le système.",
|
||||
ramOk: "Cette machine dispose de {host} GB de RAM. Le plus petit modèle vidéo nécessite environ {min} GB sur CPU ; les modèles plus grands en demandent bien davantage.",
|
||||
ramUnknown: "Le plus petit modèle vidéo nécessite environ {min} GB de RAM sur CPU ; les modèles plus grands en demandent bien davantage.",
|
||||
performanceEstimate: "Comptez plusieurs minutes par étape de débruitage : un clip de 5 images en 832x480 avec Wan2.1 1.3B en 3 étapes a pris environ 4 minutes sur 16 threads CPU, et un clip complet avec les paramètres par défaut peut prendre des heures.",
|
||||
confirmAction: "Activer quand même",
|
||||
loadError: "Impossible de charger les paramètres du mode développeur.",
|
||||
saveError: "Impossible d'enregistrer les paramètres du mode développeur.",
|
||||
},
|
||||
modelAutoSwitch: {
|
||||
sectionTitle: "Changement automatique de modèle (API OpenAI)",
|
||||
enable: "Changer de modèle par requête",
|
||||
|
|
|
|||
|
|
@ -1802,6 +1802,23 @@ export const he = {
|
|||
loadError: "טעינת הגדרות מודל העזר נכשלה.",
|
||||
saveError: "שמירת הגדרות מודל העזר נכשלה.",
|
||||
},
|
||||
developerMode: {
|
||||
sectionTitle: "מצב מפתחים",
|
||||
videoCpu: "אפשר יצירת וידאו על CPU (ניסיוני)",
|
||||
videoCpuDescription: "מאפשר להפעיל את דף הווידאו במחשב ללא GPU נתמך. כבוי כברירת מחדל; לא נתמך ואיטי מאוד.",
|
||||
notApplicable: "אין לכך השפעה במחשב זה: הווידאו כבר רץ על ה-GPU שלו, או שהוא חסום בגלל משהו שה-CPU לא יכול לעקוף.",
|
||||
forcedOnByEnv: "הופעל על ידי UNSLOTH_VIDEO_ALLOW_CPU בסביבת ה-backend.",
|
||||
forcedOffByEnv: "כובה על ידי UNSLOTH_VIDEO_ALLOW_CPU בסביבת ה-backend.",
|
||||
confirmTitle: "להפעיל יצירת וידאו על CPU?",
|
||||
confirmWarning: "יצירת וידאו על CPU עלולה להימשך שעות, לצרוך כמויות גדולות של RAM ולגרום להקפאת המערכת. המשך על אחריותך בלבד.",
|
||||
ramBelowMinimum: "במחשב זה יש {host} GB של RAM, פחות מ-{min} GB שדגם הווידאו הקטן ביותר צריך על CPU. סביר שהטעינה תיכשל או תקפיא את המערכת.",
|
||||
ramOk: "במחשב זה יש {host} GB של RAM. דגם הווידאו הקטן ביותר צריך כ-{min} GB על CPU; דגמים גדולים יותר צריכים הרבה יותר.",
|
||||
ramUnknown: "דגם הווידאו הקטן ביותר צריך כ-{min} GB של RAM על CPU; דגמים גדולים יותר צריכים הרבה יותר.",
|
||||
performanceEstimate: "צפה לדקות לכל שלב הסרת רעש: קליפ של 5 פריימים ב-832x480 מ-Wan2.1 1.3B עם 3 שלבים נמשך כ-4 דקות על 16 תהליכוני CPU, וקליפ באורך מלא בהגדרות ברירת המחדל עלול להימשך שעות.",
|
||||
confirmAction: "הפעל בכל זאת",
|
||||
loadError: "טעינת הגדרות מצב המפתחים נכשלה.",
|
||||
saveError: "שמירת הגדרות מצב המפתחים נכשלה.",
|
||||
},
|
||||
modelAutoSwitch: {
|
||||
sectionTitle: "החלפת מודל אוטומטית (OpenAI API)",
|
||||
enable: "החלף מודל לפי בקשה",
|
||||
|
|
|
|||
|
|
@ -1709,6 +1709,23 @@ export const hi = {
|
|||
loadError: "Helper LLM सेटिंग्स लोड करने में विफल।",
|
||||
saveError: "Helper LLM सेटिंग्स सहेजने में विफल।",
|
||||
},
|
||||
developerMode: {
|
||||
sectionTitle: "डेवलपर मोड",
|
||||
videoCpu: "CPU पर वीडियो जनरेशन की अनुमति दें (प्रायोगिक)",
|
||||
videoCpuDescription: "समर्थित GPU के बिना होस्ट पर वीडियो पेज चलाने देता है। डिफ़ॉल्ट रूप से बंद; असमर्थित और बहुत धीमा।",
|
||||
notApplicable: "इस मशीन पर इसका कोई प्रभाव नहीं: वीडियो या तो पहले से इसके GPU पर चलता है, या किसी ऐसी चीज़ से अवरुद्ध है जिसे CPU दूर नहीं कर सकता।",
|
||||
forcedOnByEnv: "बैकएंड एनवायरनमेंट में UNSLOTH_VIDEO_ALLOW_CPU द्वारा चालू किया गया।",
|
||||
forcedOffByEnv: "बैकएंड एनवायरनमेंट में UNSLOTH_VIDEO_ALLOW_CPU द्वारा बंद किया गया।",
|
||||
confirmTitle: "CPU पर वीडियो जनरेशन चालू करें?",
|
||||
confirmWarning: "CPU पर वीडियो जनरेशन में घंटों लग सकते हैं, यह बड़ी मात्रा में RAM का उपयोग कर सकता है, और आपका सिस्टम फ़्रीज़ हो सकता है। अपने जोखिम पर जारी रखें।",
|
||||
ramBelowMinimum: "इस मशीन में {host} GB RAM है, जो CPU पर सबसे छोटे वीडियो मॉडल के लिए आवश्यक {min} GB से कम है। लोडिंग विफल हो सकती है या सिस्टम फ़्रीज़ हो सकता है।",
|
||||
ramOk: "इस मशीन में {host} GB RAM है। सबसे छोटे वीडियो मॉडल को CPU पर लगभग {min} GB चाहिए; बड़े मॉडलों को कहीं अधिक चाहिए।",
|
||||
ramUnknown: "सबसे छोटे वीडियो मॉडल को CPU पर लगभग {min} GB RAM चाहिए; बड़े मॉडलों को कहीं अधिक चाहिए।",
|
||||
performanceEstimate: "हर डीनॉइज़िंग स्टेप में कई मिनट लगने की अपेक्षा करें: Wan2.1 1.3B से 3 स्टेप पर 5-फ़्रेम 832x480 क्लिप में 16 CPU थ्रेड पर लगभग 4 मिनट लगे, और डिफ़ॉल्ट सेटिंग्स पर पूरी लंबाई की क्लिप में घंटों लग सकते हैं।",
|
||||
confirmAction: "फिर भी चालू करें",
|
||||
loadError: "डेवलपर मोड सेटिंग्स लोड करने में विफल।",
|
||||
saveError: "डेवलपर मोड सेटिंग्स सहेजने में विफल।",
|
||||
},
|
||||
modelAutoSwitch: {
|
||||
sectionTitle: "मॉडल ऑटो-स्विच (OpenAI API)",
|
||||
enable: "अनुरोध के अनुसार मॉडल बदलें",
|
||||
|
|
|
|||
|
|
@ -1621,6 +1621,23 @@ export const it = {
|
|||
saveError:
|
||||
"Salvataggio delle impostazioni dell'LLM di supporto non riuscito.",
|
||||
},
|
||||
developerMode: {
|
||||
sectionTitle: "Modalità sviluppatore",
|
||||
videoCpu: "Consenti la generazione video su CPU (sperimentale)",
|
||||
videoCpuDescription: "Consente di usare la pagina Video su un host senza GPU supportata. Disattivato per impostazione predefinita; non supportato e molto lento.",
|
||||
notApplicable: "Nessun effetto su questa macchina: il video viene già eseguito sulla GPU oppure è bloccato da qualcosa che la CPU non può aggirare.",
|
||||
forcedOnByEnv: "Attivato da UNSLOTH_VIDEO_ALLOW_CPU nell'ambiente del backend.",
|
||||
forcedOffByEnv: "Disattivato da UNSLOTH_VIDEO_ALLOW_CPU nell'ambiente del backend.",
|
||||
confirmTitle: "Attivare la generazione video su CPU?",
|
||||
confirmWarning: "La generazione video su CPU può richiedere ore, consumare grandi quantità di RAM e bloccare il sistema. Procedi a tuo rischio.",
|
||||
ramBelowMinimum: "Questa macchina ha {host} GB di RAM, meno dei {min} GB richiesti dal modello video più piccolo su CPU. È probabile che il caricamento fallisca o blocchi il sistema.",
|
||||
ramOk: "Questa macchina ha {host} GB di RAM. Il modello video più piccolo richiede circa {min} GB su CPU; i modelli più grandi ne richiedono molta di più.",
|
||||
ramUnknown: "Il modello video più piccolo richiede circa {min} GB di RAM su CPU; i modelli più grandi ne richiedono molta di più.",
|
||||
performanceEstimate: "Prevedi alcuni minuti per ogni passo di denoising: una clip di 5 frame a 832x480 con Wan2.1 1.3B a 3 passi ha richiesto circa 4 minuti su 16 thread CPU, e una clip completa con le impostazioni predefinite può richiedere ore.",
|
||||
confirmAction: "Attiva comunque",
|
||||
loadError: "Impossibile caricare le impostazioni della modalità sviluppatore.",
|
||||
saveError: "Impossibile salvare le impostazioni della modalità sviluppatore.",
|
||||
},
|
||||
modelAutoSwitch: {
|
||||
sectionTitle: "Cambio automatico del modello (API OpenAI)",
|
||||
enable: "Cambia modello in base alla richiesta",
|
||||
|
|
|
|||
|
|
@ -1698,6 +1698,23 @@ export const ja = {
|
|||
loadError: "Helper LLM 設定の読み込みに失敗しました。",
|
||||
saveError: "Helper LLM 設定の保存に失敗しました。",
|
||||
},
|
||||
developerMode: {
|
||||
sectionTitle: "開発者モード",
|
||||
videoCpu: "CPU での動画生成を許可する (実験的)",
|
||||
videoCpuDescription: "対応 GPU のないホストで動画ページを実行できるようにします。デフォルトはオフです。サポート対象外で、非常に低速です。",
|
||||
notApplicable: "このマシンでは効果がありません。動画はすでに GPU で実行されているか、CPU では回避できない理由でブロックされています。",
|
||||
forcedOnByEnv: "バックエンド環境の UNSLOTH_VIDEO_ALLOW_CPU によってオンになっています。",
|
||||
forcedOffByEnv: "バックエンド環境の UNSLOTH_VIDEO_ALLOW_CPU によってオフになっています。",
|
||||
confirmTitle: "CPU での動画生成を有効にしますか?",
|
||||
confirmWarning: "CPU での動画生成には数時間かかることがあり、大量の RAM を消費し、システムがフリーズする可能性があります。自己責任で続行してください。",
|
||||
ramBelowMinimum: "このマシンの RAM は {host} GB で、最小の動画モデルが CPU で必要とする {min} GB を下回っています。読み込みに失敗するか、システムがフリーズする可能性が高いです。",
|
||||
ramOk: "このマシンの RAM は {host} GB です。最小の動画モデルは CPU で約 {min} GB 必要で、より大きなモデルはさらに多くを必要とします。",
|
||||
ramUnknown: "最小の動画モデルは CPU で約 {min} GB の RAM が必要で、より大きなモデルはさらに多くを必要とします。",
|
||||
performanceEstimate: "ノイズ除去 1 ステップあたり数分かかります。Wan2.1 1.3B で 3 ステップ、5 フレームの 832x480 クリップは 16 CPU スレッドで約 4 分かかり、デフォルト設定のフルレングスのクリップでは数時間かかることがあります。",
|
||||
confirmAction: "それでも有効にする",
|
||||
loadError: "開発者モードの設定を読み込めませんでした。",
|
||||
saveError: "開発者モードの設定を保存できませんでした。",
|
||||
},
|
||||
modelAutoSwitch: {
|
||||
sectionTitle: "モデル自動切り替え (OpenAI API)",
|
||||
enable: "リクエストごとにモデルを切り替え",
|
||||
|
|
|
|||
|
|
@ -1702,6 +1702,23 @@ export const ko = {
|
|||
loadError: "Helper LLM 설정을 불러오지 못했습니다.",
|
||||
saveError: "Helper LLM 설정을 저장하지 못했습니다.",
|
||||
},
|
||||
developerMode: {
|
||||
sectionTitle: "개발자 모드",
|
||||
videoCpu: "CPU에서 동영상 생성 허용 (실험적)",
|
||||
videoCpuDescription: "지원되는 GPU가 없는 호스트에서 동영상 페이지를 실행할 수 있게 합니다. 기본값은 꺼짐이며, 지원되지 않고 매우 느립니다.",
|
||||
notApplicable: "이 컴퓨터에서는 효과가 없습니다. 동영상이 이미 GPU에서 실행되고 있거나, CPU로 우회할 수 없는 문제로 차단되어 있습니다.",
|
||||
forcedOnByEnv: "백엔드 환경의 UNSLOTH_VIDEO_ALLOW_CPU에 의해 켜졌습니다.",
|
||||
forcedOffByEnv: "백엔드 환경의 UNSLOTH_VIDEO_ALLOW_CPU에 의해 꺼졌습니다.",
|
||||
confirmTitle: "CPU 동영상 생성을 활성화할까요?",
|
||||
confirmWarning: "CPU 동영상 생성은 몇 시간이 걸릴 수 있고, 많은 RAM을 사용하며, 시스템이 멈출 수 있습니다. 위험을 감수하고 계속하세요.",
|
||||
ramBelowMinimum: "이 컴퓨터의 RAM은 {host} GB로, 가장 작은 동영상 모델이 CPU에서 필요로 하는 {min} GB보다 적습니다. 로드가 실패하거나 시스템이 멈출 가능성이 높습니다.",
|
||||
ramOk: "이 컴퓨터의 RAM은 {host} GB입니다. 가장 작은 동영상 모델은 CPU에서 약 {min} GB가 필요하며, 더 큰 모델은 훨씬 더 많이 필요합니다.",
|
||||
ramUnknown: "가장 작은 동영상 모델은 CPU에서 약 {min} GB의 RAM이 필요하며, 더 큰 모델은 훨씬 더 많이 필요합니다.",
|
||||
performanceEstimate: "노이즈 제거 단계마다 몇 분씩 걸립니다. Wan2.1 1.3B로 3단계, 5프레임 832x480 클립을 만드는 데 16개 CPU 스레드에서 약 4분이 걸렸으며, 기본 설정의 전체 길이 클립은 몇 시간이 걸릴 수 있습니다.",
|
||||
confirmAction: "그래도 활성화",
|
||||
loadError: "개발자 모드 설정을 불러오지 못했습니다.",
|
||||
saveError: "개발자 모드 설정을 저장하지 못했습니다.",
|
||||
},
|
||||
modelAutoSwitch: {
|
||||
sectionTitle: "모델 자동 전환 (OpenAI API)",
|
||||
enable: "요청에 따라 모델 전환",
|
||||
|
|
|
|||
|
|
@ -1710,6 +1710,23 @@ export const ptBR = {
|
|||
loadError: "Falha ao carregar as configurações do LLM Auxiliar.",
|
||||
saveError: "Falha ao salvar as configurações do LLM Auxiliar.",
|
||||
},
|
||||
developerMode: {
|
||||
sectionTitle: "Modo desenvolvedor",
|
||||
videoCpu: "Permitir geração de vídeo na CPU (experimental)",
|
||||
videoCpuDescription: "Permite usar a página de Vídeo em uma máquina sem GPU compatível. Desativado por padrão; sem suporte oficial e muito lento.",
|
||||
notApplicable: "Não tem efeito nesta máquina: o vídeo já roda na GPU ou está bloqueado por algo que a CPU não consegue contornar.",
|
||||
forcedOnByEnv: "Ativado por UNSLOTH_VIDEO_ALLOW_CPU no ambiente do backend.",
|
||||
forcedOffByEnv: "Desativado por UNSLOTH_VIDEO_ALLOW_CPU no ambiente do backend.",
|
||||
confirmTitle: "Ativar geração de vídeo na CPU?",
|
||||
confirmWarning: "A geração de vídeo na CPU pode levar horas, consumir grandes quantidades de RAM e travar seu sistema. Continue por sua conta e risco.",
|
||||
ramBelowMinimum: "Esta máquina tem {host} GB de RAM, abaixo dos {min} GB que o menor modelo de vídeo precisa na CPU. O carregamento provavelmente falhará ou travará o sistema.",
|
||||
ramOk: "Esta máquina tem {host} GB de RAM. O menor modelo de vídeo precisa de cerca de {min} GB na CPU; modelos maiores precisam de muito mais.",
|
||||
ramUnknown: "O menor modelo de vídeo precisa de cerca de {min} GB de RAM na CPU; modelos maiores precisam de muito mais.",
|
||||
performanceEstimate: "Espere minutos por etapa de remoção de ruído: um clipe de 5 quadros em 832x480 do Wan2.1 1.3B com 3 etapas levou cerca de 4 minutos em 16 threads de CPU, e um clipe completo com as configurações padrão pode levar horas.",
|
||||
confirmAction: "Ativar mesmo assim",
|
||||
loadError: "Falha ao carregar as configurações do modo desenvolvedor.",
|
||||
saveError: "Falha ao salvar as configurações do modo desenvolvedor.",
|
||||
},
|
||||
modelAutoSwitch: {
|
||||
sectionTitle: "Troca automática de modelo (API OpenAI)",
|
||||
enable: "Trocar de modelo por requisição",
|
||||
|
|
|
|||
|
|
@ -1709,6 +1709,23 @@ export const ru = {
|
|||
loadError: "Не удалось загрузить настройки вспомогательной LLM.",
|
||||
saveError: "Не удалось сохранить настройки вспомогательной LLM.",
|
||||
},
|
||||
developerMode: {
|
||||
sectionTitle: "Режим разработчика",
|
||||
videoCpu: "Разрешить генерацию видео на CPU (экспериментально)",
|
||||
videoCpuDescription: "Позволяет использовать страницу «Видео» на компьютере без поддерживаемого GPU. По умолчанию выключено; не поддерживается и работает очень медленно.",
|
||||
notApplicable: "Не влияет на этот компьютер: видео либо уже работает на GPU, либо заблокировано тем, что CPU не может обойти.",
|
||||
forcedOnByEnv: "Включено переменной UNSLOTH_VIDEO_ALLOW_CPU в окружении бэкенда.",
|
||||
forcedOffByEnv: "Выключено переменной UNSLOTH_VIDEO_ALLOW_CPU в окружении бэкенда.",
|
||||
confirmTitle: "Включить генерацию видео на CPU?",
|
||||
confirmWarning: "Генерация видео на CPU может занять несколько часов, потреблять большой объём RAM и привести к зависанию системы. Продолжайте на свой страх и риск.",
|
||||
ramBelowMinimum: "На этом компьютере {host} GB RAM, что меньше {min} GB, необходимых самой маленькой видеомодели на CPU. Загрузка, скорее всего, завершится ошибкой или приведёт к зависанию системы.",
|
||||
ramOk: "На этом компьютере {host} GB RAM. Самой маленькой видеомодели на CPU нужно около {min} GB; более крупным моделям нужно гораздо больше.",
|
||||
ramUnknown: "Самой маленькой видеомодели на CPU нужно около {min} GB RAM; более крупным моделям нужно гораздо больше.",
|
||||
performanceEstimate: "Рассчитывайте на несколько минут на каждый шаг шумоподавления: клип из 5 кадров 832x480 на Wan2.1 1.3B с 3 шагами занял около 4 минут на 16 потоках CPU, а клип полной длины с настройками по умолчанию может занять несколько часов.",
|
||||
confirmAction: "Всё равно включить",
|
||||
loadError: "Не удалось загрузить настройки режима разработчика.",
|
||||
saveError: "Не удалось сохранить настройки режима разработчика.",
|
||||
},
|
||||
modelAutoSwitch: {
|
||||
sectionTitle: "Автопереключение модели (OpenAI API)",
|
||||
enable: "Переключать модель по запросу",
|
||||
|
|
|
|||
|
|
@ -1854,6 +1854,23 @@ export const sv = {
|
|||
loadError: "Det gick inte att läsa in inställningarna för hjälp-LLM.",
|
||||
saveError: "Det gick inte att spara inställningarna för hjälp-LLM.",
|
||||
},
|
||||
developerMode: {
|
||||
sectionTitle: "Utvecklarläge",
|
||||
videoCpu: "Tillåt videogenerering på CPU (experimentellt)",
|
||||
videoCpuDescription: "Låter videosidan köras på en värd utan GPU som stöds. Av som standard; stöds inte och är mycket långsamt.",
|
||||
notApplicable: "Har ingen effekt på den här datorn: video körs antingen redan på dess GPU eller blockeras av något som CPU:n inte kan kringgå.",
|
||||
forcedOnByEnv: "Aktiverat av UNSLOTH_VIDEO_ALLOW_CPU i backend-miljön.",
|
||||
forcedOffByEnv: "Inaktiverat av UNSLOTH_VIDEO_ALLOW_CPU i backend-miljön.",
|
||||
confirmTitle: "Aktivera videogenerering på CPU?",
|
||||
confirmWarning: "Videogenerering på CPU kan ta timmar, förbruka stora mängder RAM och få ditt system att frysa. Fortsätt på egen risk.",
|
||||
ramBelowMinimum: "Den här datorn har {host} GB RAM, mindre än de {min} GB som den minsta videomodellen behöver på CPU. Inläsningen kommer troligen att misslyckas eller frysa systemet.",
|
||||
ramOk: "Den här datorn har {host} GB RAM. Den minsta videomodellen behöver cirka {min} GB på CPU; större modeller behöver betydligt mer.",
|
||||
ramUnknown: "Den minsta videomodellen behöver cirka {min} GB RAM på CPU; större modeller behöver betydligt mer.",
|
||||
performanceEstimate: "Räkna med minuter per brusreduceringssteg: ett klipp på 5 bildrutor i 832x480 från Wan2.1 1.3B med 3 steg tog cirka 4 minuter på 16 CPU-trådar, och ett klipp i full längd med standardinställningar kan ta timmar.",
|
||||
confirmAction: "Aktivera ändå",
|
||||
loadError: "Det gick inte att läsa in inställningarna för utvecklarläge.",
|
||||
saveError: "Det gick inte att spara inställningarna för utvecklarläge.",
|
||||
},
|
||||
modelAutoSwitch: {
|
||||
sectionTitle: "Automatiskt modellbyte (OpenAI API)",
|
||||
enable: "Byt modell enligt begäran",
|
||||
|
|
|
|||
|
|
@ -1688,6 +1688,23 @@ export const zhCN = {
|
|||
loadError: "加载辅助 LLM 设置失败。",
|
||||
saveError: "保存辅助 LLM 设置失败。",
|
||||
},
|
||||
developerMode: {
|
||||
sectionTitle: "开发者模式",
|
||||
videoCpu: "允许在 CPU 上生成视频(实验性)",
|
||||
videoCpuDescription: "允许在没有受支持 GPU 的主机上运行视频页面。默认关闭;不受支持且速度非常慢。",
|
||||
notApplicable: "在此机器上无效:视频要么已在其 GPU 上运行,要么被 CPU 无法绕过的问题阻止。",
|
||||
forcedOnByEnv: "已由后端环境中的 UNSLOTH_VIDEO_ALLOW_CPU 开启。",
|
||||
forcedOffByEnv: "已由后端环境中的 UNSLOTH_VIDEO_ALLOW_CPU 关闭。",
|
||||
confirmTitle: "启用 CPU 视频生成?",
|
||||
confirmWarning: "CPU 视频生成可能耗时数小时,占用大量 RAM,并可能导致系统卡死。继续操作风险自负。",
|
||||
ramBelowMinimum: "此机器有 {host} GB RAM,低于最小视频模型在 CPU 上所需的 {min} GB。加载很可能失败或导致系统卡死。",
|
||||
ramOk: "此机器有 {host} GB RAM。最小的视频模型在 CPU 上约需 {min} GB;更大的模型需要多得多。",
|
||||
ramUnknown: "最小的视频模型在 CPU 上约需 {min} GB RAM;更大的模型需要多得多。",
|
||||
performanceEstimate: "每个去噪步骤预计需要数分钟:使用 Wan2.1 1.3B 以 3 步生成 5 帧 832x480 片段,在 16 个 CPU 线程上约耗时 4 分钟,而默认设置下的完整长度片段可能需要数小时。",
|
||||
confirmAction: "仍然启用",
|
||||
loadError: "加载开发者模式设置失败。",
|
||||
saveError: "保存开发者模式设置失败。",
|
||||
},
|
||||
modelAutoSwitch: {
|
||||
sectionTitle: "模型自动切换(OpenAI API)",
|
||||
enable: "按请求切换模型",
|
||||
|
|
|
|||
|
|
@ -189,6 +189,7 @@ function generalTab(initialToken: string) {
|
|||
"../components/documents-rag-section": componentStub,
|
||||
"../components/language-select": componentStub,
|
||||
"../components/download-transport-row": componentStub,
|
||||
"../components/developer-mode-section": componentStub,
|
||||
"../components/hub-settings-section": componentStub,
|
||||
"../components/notification-frequency-select": componentStub,
|
||||
"../components/settings-row": componentStub,
|
||||
|
|
|
|||
|
|
@ -362,7 +362,7 @@ test("the workspace chords land where the guard lets them", async () => {
|
|||
// gate. Read through the same helper the disabled row reads.
|
||||
assert.match(
|
||||
SRC__ROOT,
|
||||
/const videoDisabled =\n\s*videoNavHint\(chatOnlyMeasured, chatOnlyReason\) !== undefined;/,
|
||||
/const videoDisabled =\n\s*videoNavHint\(chatOnlyMeasured, chatOnlyReason, videoCpuOptIn\) !== undefined;/,
|
||||
);
|
||||
assert.match(
|
||||
SRC__ROOT,
|
||||
|
|
@ -370,7 +370,7 @@ test("the workspace chords land where the guard lets them", async () => {
|
|||
);
|
||||
assert.match(
|
||||
APP_SIDEBAR,
|
||||
/const videoDisabledHint = videoNavHint\(chatOnlyMeasured, chatOnlyReason\);/,
|
||||
/const videoDisabledHint = videoNavHint\(chatOnlyMeasured, chatOnlyReason, videoCpuOptIn\);/,
|
||||
);
|
||||
assert.match(APP_SIDEBAR, /disabled: videoDisabled,/);
|
||||
|
||||
|
|
|
|||
|
|
@ -441,7 +441,7 @@ test("the Video row is disabled exactly when the hint has something to say", asy
|
|||
const { readFile } = await import("node:fs/promises");
|
||||
assert.match(
|
||||
APP_SIDEBAR,
|
||||
/const videoDisabledHint = videoNavHint\(chatOnlyMeasured, chatOnlyReason\)/,
|
||||
/const videoDisabledHint = videoNavHint\(chatOnlyMeasured, chatOnlyReason, videoCpuOptIn\)/,
|
||||
"the Video hint no longer comes from the shared derivation",
|
||||
);
|
||||
assert.match(
|
||||
|
|
|
|||
113
studio/frontend/tests/video-cpu-developer-mode.test.ts
Normal file
113
studio/frontend/tests/video-cpu-developer-mode.test.ts
Normal file
|
|
@ -0,0 +1,113 @@
|
|||
// SPDX-License-Identifier: AGPL-3.0-only
|
||||
// Copyright 2026-present the Unsloth AI Inc. team. All rights reserved. See /studio/LICENSE.AGPL-3.0
|
||||
|
||||
// Developer mode's CPU video opt-in (unslothai/unsloth#9458): off by default, enabling asks first
|
||||
// with the issue's warning and the host RAM against the minimum, and while it is in effect the
|
||||
// Video page keeps a "CPU (experimental)" warning up and the sidebar row stays navigable.
|
||||
|
||||
import assert from "node:assert/strict";
|
||||
import test from "node:test";
|
||||
|
||||
import { readSrc, registerBundlerResolver } from "./helpers/kit.ts";
|
||||
|
||||
registerBundlerResolver();
|
||||
|
||||
const { videoCpuRamCheck, videoCpuToggleNeedsConfirm } = await import(
|
||||
"../src/features/settings/lib/video-cpu-warning.ts"
|
||||
);
|
||||
const { videoNavHint } = await import("../src/config/hardware-verdict.ts");
|
||||
|
||||
const GIB = 1024 ** 3;
|
||||
const MIN = 32 * GIB;
|
||||
|
||||
test("RAM below the minimum warns, at or near it does not", () => {
|
||||
assert.deepEqual(videoCpuRamCheck(16 * GIB, MIN), {
|
||||
status: "below",
|
||||
hostGib: 16,
|
||||
minGib: 32,
|
||||
});
|
||||
assert.equal(videoCpuRamCheck(64 * GIB, MIN).status, "ok");
|
||||
// A "32 GB" machine reports ~31.3 GiB after reservations; it must not be told it is short.
|
||||
assert.equal(videoCpuRamCheck(31.3 * GIB, MIN).status, "ok");
|
||||
assert.equal(videoCpuRamCheck(29 * GIB, MIN).status, "below");
|
||||
});
|
||||
|
||||
test("an unreadable RAM figure says nothing either way", () => {
|
||||
for (const host of [null, undefined, 0, -1, Number.NaN]) {
|
||||
const check = videoCpuRamCheck(host as number | null, MIN);
|
||||
assert.equal(check.status, "unknown");
|
||||
assert.equal(check.hostGib, null);
|
||||
assert.equal(check.minGib, 32);
|
||||
}
|
||||
});
|
||||
|
||||
test("only turning the opt-in on asks for confirmation", () => {
|
||||
assert.equal(videoCpuToggleNeedsConfirm(true), true);
|
||||
assert.equal(videoCpuToggleNeedsConfirm(false), false);
|
||||
});
|
||||
|
||||
test("the sidebar waives only the plain no-GPU hint, and only when opted in", () => {
|
||||
assert.equal(typeof videoNavHint(true, "no_gpu"), "string");
|
||||
assert.equal(typeof videoNavHint(true, "no_gpu", false), "string");
|
||||
assert.equal(videoNavHint(true, "no_gpu", true), undefined);
|
||||
// A GPU torch cannot reach, or an Intel Mac, stays disabled whatever the opt-in says.
|
||||
for (const reason of ["torch_cpu_build", "torch_cuda_unavailable", "intel_mac"]) {
|
||||
assert.equal(typeof videoNavHint(true, reason, true), "string", reason);
|
||||
}
|
||||
});
|
||||
|
||||
test("the confirm dialog carries the issue's warning text verbatim", () => {
|
||||
const en = readSrc("i18n/locales/en.ts");
|
||||
assert.ok(
|
||||
en.includes(
|
||||
"CPU video generation may take hours, consume large amounts of RAM, and may freeze your system. Continue at your own risk.",
|
||||
),
|
||||
);
|
||||
const section = readSrc("features/settings/components/developer-mode-section.tsx");
|
||||
assert.match(section, /settings\.general\.developerMode\.confirmWarning/);
|
||||
assert.match(section, /settings\.general\.developerMode\.ramBelowMinimum/);
|
||||
assert.match(section, /settings\.general\.developerMode\.performanceEstimate/);
|
||||
// Enabling goes through the dialog; only the confirm button saves true.
|
||||
assert.match(section, /videoCpuToggleNeedsConfirm\(next\)[\s\S]*setConfirmOpen\(true\)/);
|
||||
assert.match(section, /setConfirmOpen\(false\);\s*void save\(true\);/);
|
||||
// Saving refreshes both cached gates.
|
||||
assert.match(section, /usePlatformStore\.setState\(\{ videoCpuOptIn: next\.videoCpu \}\)/);
|
||||
assert.match(section, /refreshHardwareInfo\(\)/);
|
||||
// An env override decides, so the switch is not offered against it.
|
||||
assert.match(section, /disabled=\{!settings \|\| saving \|\| envForced !== null\}/);
|
||||
});
|
||||
|
||||
test("the section is rendered for the owner only", () => {
|
||||
const tab = readSrc("features/settings/tabs/general-tab.tsx");
|
||||
const ownerBlock = tab.indexOf("{isOwner ? (");
|
||||
const section = tab.indexOf("<DeveloperModeSection />");
|
||||
assert.ok(ownerBlock >= 0 && section > ownerBlock, "DeveloperModeSection outside the owner block");
|
||||
const close = tab.indexOf(") : null}", ownerBlock);
|
||||
assert.ok(section < close, "DeveloperModeSection outside the owner block");
|
||||
});
|
||||
|
||||
test("the Video page keeps a CPU (experimental) warning up while the opt-in is in effect", () => {
|
||||
const hook = readSrc("hooks/use-hardware-info.ts");
|
||||
assert.match(hook, /videoCpuExperimental: data\?\.video_cpu_experimental === true/);
|
||||
assert.match(hook, /videoCpuExperimental: false,/);
|
||||
const page = readSrc("features/video/video-page.tsx");
|
||||
assert.match(page, /cpuExperimental=\{hardware\.videoCpuExperimental\}/);
|
||||
assert.match(page, /\{cpuExperimental \? <VideoCpuExperimentalBanner \/> : null\}/);
|
||||
assert.match(page, /CPU \(experimental\)\./);
|
||||
// The gate itself is unchanged: only an explicit false hides the generator.
|
||||
assert.match(page, /hardware\.videoSupported === false/);
|
||||
});
|
||||
|
||||
test("the health verdict carries the opt-in into the platform store", () => {
|
||||
const env = readSrc("config/env.ts");
|
||||
assert.match(env, /video_cpu_opt_in\?: boolean;/);
|
||||
assert.match(env, /videoCpuOptIn: false,/);
|
||||
assert.match(env, /previous\.videoCpuOptIn/);
|
||||
for (const file of ["components/app-sidebar.tsx", "app/routes/__root.tsx"]) {
|
||||
assert.match(
|
||||
readSrc(file),
|
||||
/videoNavHint\(chatOnlyMeasured, chatOnlyReason, videoCpuOptIn\)/,
|
||||
file,
|
||||
);
|
||||
}
|
||||
});
|
||||
Loading…
Add table
Add a link
Reference in a new issue