mirror of
https://github.com/unslothai/unsloth.git
synced 2026-10-30 02:30:06 +00:00
Studio: train a speculative decoding drafter with fine-tunes and export it for llama.cpp and vLLM (#13806)
Lets Unsloth Studio and Unsloth Desktop train a speculative decoding drafter together with a fine-tune, and ships it with merged and GGUF exports so the fine-tuned model decodes faster in llama.cpp and vLLM. Builds on #13719 (merged) and unslothai/unsloth-zoo#1748 / #1762 (merged). ## What users see Train tab, advanced mode: a new collapsed section "Speculative Decoding Drafter" with one checkbox, "Train a speculative decoding drafter". What it does depends on the selected model: - Model has a native MTP head (Qwen3.5 / 3.6, GLM-4.5 / 4.7, Qwen3-Next, ...): "Retrains this model's MTP head". - Model has no MTP head (Llama, Qwen3, Gemma 4, gpt-oss, ...): "Trains an EAGLE-3 drafter (this model has no MTP head)". - Neither engine can run a drafter for it (Gemma 3, Mistral 3): disabled, with the reason. Expanded: data source (dataset answers, or the model's own answers: slower, closer to what the model generates), number of examples, epochs, learning rate, draft tokens. With the box unticked nothing changes: the training request is byte-identical to today's. After the fine-tune finishes, a "Training drafter" phase trains the drafter against the fine-tuned model (frozen, adapter active). A drafter failure is reported as a warning and the fine-tune is kept; stopping during this phase discards only the drafter. The export page then says "Includes trained drafter (MTP | EAGLE-3)" and shows the `vllm serve` command. ## How it works Backend: - `TrainingStartRequest.drafter` (optional) -> route -> worker config -> `core/training/drafter.py`, run in the worker after the fine-tune is saved: frees the SFT optimizer and data, builds examples (SFT rows with the same prompt masking, or greedy regeneration), then `FastModel.get_mtp_head` + `UnslothMTPTrainer` (native head, saved as `mtp_head.safetensors` beside the adapter) or the zoo EAGLE-3 trainer (saved to `eagle3/`). Writes `drafter.json` (strategy, layers, metrics). Progress has its own step counter and does not touch the fine-tune's loss history. - `GET /api/train/drafter-capability?model_name=...`: native head detected from the checkpoint's tensor index (not the config alone), otherwise EAGLE-3 support for the architecture. - Export: the native head is re-attached when export reloads the adapter and stitched into merged and GGUF outputs (#13719). EAGLE-3 is copied to `<export>/eagle3` (verifier = the Hub repo on push, else the base model) and converted to `eagle3-<name>-F16.gguf` next to GGUF exports; `drafter.json` carries the `vllm serve ... --speculative-config` command. - Inference: llama-server gets `--model-draft <eagle3 gguf> --spec-type draft-eagle3` when an export's drafter sits beside the GGUF and the binary supports it; a GGUF whose `drafter.json` says its MTP head was trained turns MTP on in auto even under the 3B size floor and the MLA default-off (the user trained it to be used). GGUFs without that file route exactly as before. The managed vLLM engine adds `--speculative-config` when the model folder has a `drafter.json`. - Fix: after an export reload, an outer save wrapper hid the MTP save wrapper, so the head was stitched twice per save. Internal savers now set a context flag the wrapper honours wherever it sits in the chain. Frontend: `drafter-section.tsx`, store / types / defaults / persistence (v23, old state migrates to off) / YAML / payload mapping (sent only when ticked, supported for the selected model, and not CPT / embedding / decision / MLX), `training_drafter` phase label, export banner; strings in all 14 locales. ## Tests - Backend: `test_drafter_training.py`, `test_drafter_launch_flags.py`, the managed engine, admission and phase sync suites: 439 passed. - Frontend: `training-start-payload-drafter.test.ts` (off payload unchanged in every gated case, on payload = off payload plus exactly the drafter block, bounds, persistence migration, YAML round trip) and persistence: 24 passed; `npm run typecheck`, `npm run i18n:check:strict`, `npm run build` pass. Regression A/B (Studio journeys auth / settings / crawl / inference settings / parallel / train_responses_only / export_reload / diffusion train, plus the core regression smoke, `jobs/sft.py`, `jobs/inference_smoke.py`), base vs head on Colab A100 / L4 and Kaggle T4x2: no functional regression (63 steps identical, 10 DOM-only, 1 failing on both sides: `export_reload/export_merged`). The visual diffs that reproduced are the Train form (the new section) and a chat title in a parallel-streams journey whose order depends on which stream finishes first. ## End-to-end results Driven only through Studio's HTTP API on Colab (train with the drafter, merged 16-bit + GGUF Q8_0 export, then serve), 60 held-out prompts, 192 new tokens, greedy, arms interleaved on one GPU, 95% paired bootstrap CIs over prompts. Qwen3.5-2B, native MTP head retrained on 600 of the model's own answers (L4, bf16): | Engine | Arm | Acceptance | Speedup vs no draft | |---|---|---|---| | llama.cpp | stock head | 0.740 | 1.51x [1.48, 1.55] | | llama.cpp | trained head | 0.757 | 1.53x [1.49, 1.57] | | vLLM 0.31.0 | stock head | 0.747 | 1.55x [1.51, 1.59] | | vLLM 0.31.0 | trained head | 0.766 | 1.57x [1.53, 1.61] | Trained vs stock is a tie on this small model (llama.cpp 1.013x [0.996, 1.032], vLLM 1.015x [0.999, 1.031]; an A100 run gave 1.035x [1.018, 1.052]). The default learning rate for the MTP head is 2e-5: at 1e-4 the retrained head drafted worse than stock (acceptance 0.53 vs 0.70). Qwen3-1.7B, new EAGLE-3 drafter from 6,000 dataset rows, 2 epochs (T4, fp16): llama.cpp acceptance 0.449, 1.28x [1.21, 1.35] vs no draft, 60/60 outputs identical; vLLM acceptance 0.463, about 2.2x (the T4 no-draft baseline was noisy). ## Limits - A drafter learns the prompt format it was trained on: trained on Alpaca-formatted rows, it drafts worse on chat-template prompts (the EAGLE-3 drafter above was slower than no draft there, 0.81x), so train it on rows formatted the way the model will be served. - "Model's own answers" regenerates every example (600 prompts took about 35 minutes on an A100). - EAGLE-3 was not run on a bf16 GPU end to end. - The trained-MTP marker lives in `drafter.json` beside the GGUF, not in GGUF metadata; a GGUF downloaded on its own keeps Studio's default MTP policy. - LoRA-only exports keep the MTP head beside the adapter but do not carry the EAGLE-3 folder. - No drafter training on Mac (MLX) yet. ## Screenshots Before (base) on the left, after (this PR) on the right. Train tab, advanced view: the new collapsed "Speculative Decoding Drafter" section under the training hyperparameters. 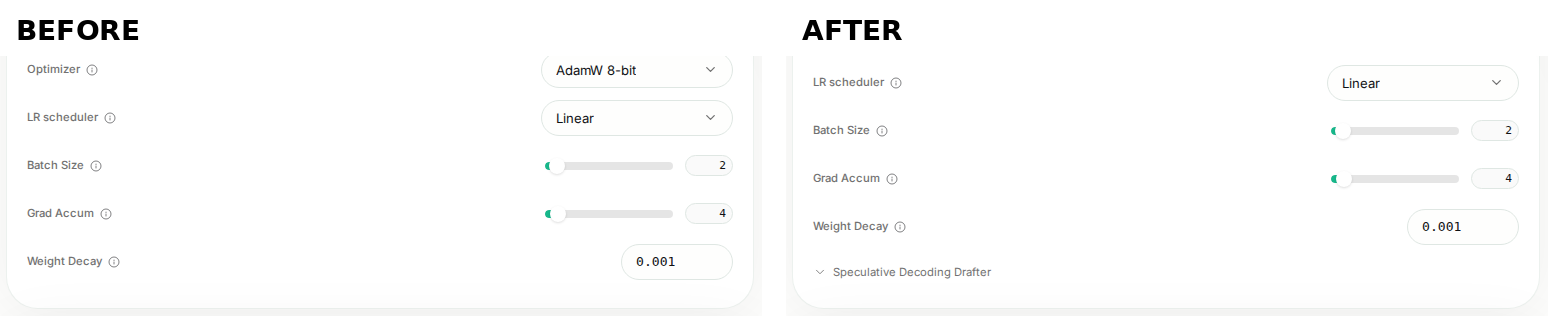 Qwen3.5-2B (native MTP head): "Retrains this model's MTP head". 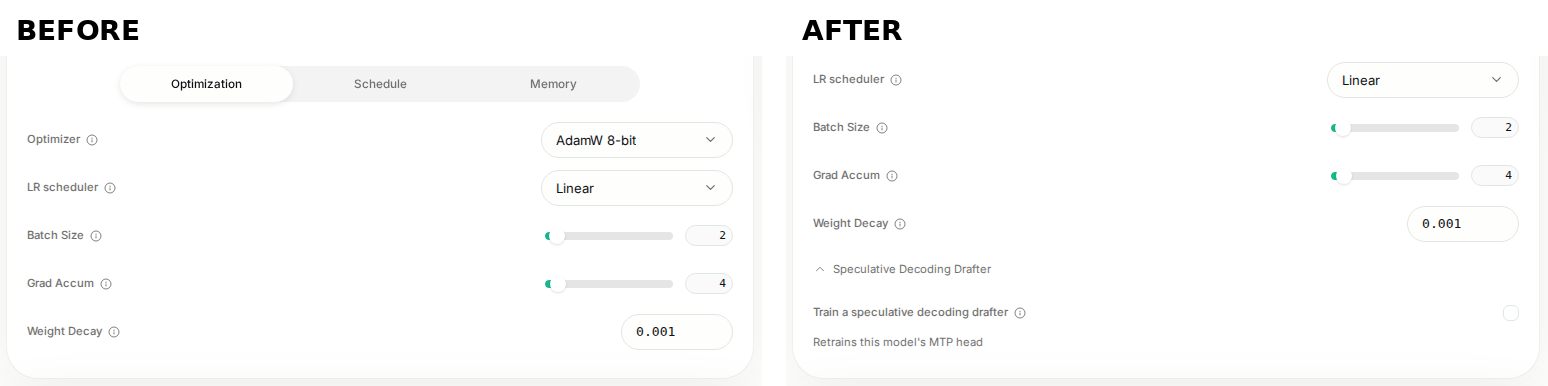 Qwen3-1.7B (no MTP head): "Trains an EAGLE-3 drafter (this model has no MTP head)". 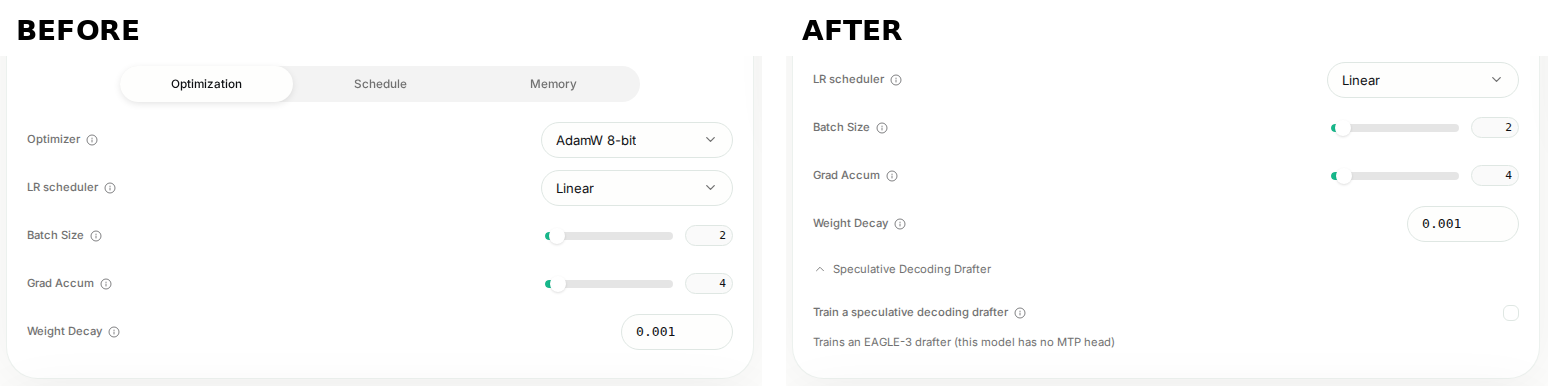 Gemma 3 1B: no drafter either engine can run, so the checkbox is disabled with the reason. 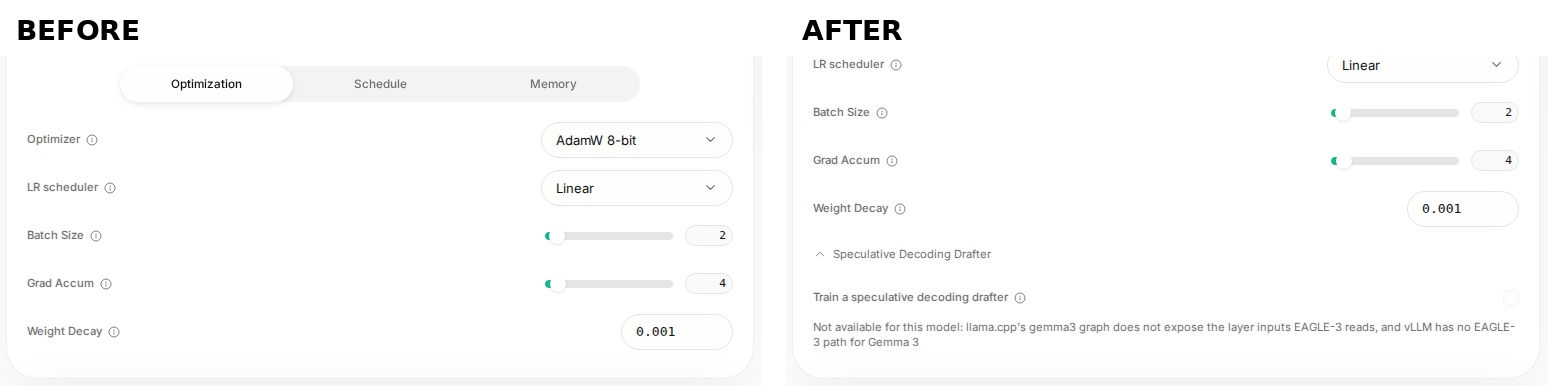




This commit is contained in:
 Daniel Han
 GitHub
parent
dac778ce2a
commit
1be7795180
55 changed files with 4270 additions and 19 deletions
332
studio/backend/core/export/drafter_export.py
Normal file
332
studio/backend/core/export/drafter_export.py
Normal file
|
|
@ -0,0 +1,332 @@
|
|||
# SPDX-License-Identifier: AGPL-3.0-only
|
||||
# Copyright 2026-present the Unsloth AI Inc. team. All rights reserved. See /studio/LICENSE.AGPL-3.0
|
||||
|
||||
"""Carry a drafter trained with the fine-tune (core/training/drafter.py) into merged and GGUF exports.
|
||||
|
||||
The MTP head needs no copying: the export reload re-attaches `mtp_head.safetensors` and the merged / GGUF
|
||||
savers stitch it. An EAGLE-3 drafter is a separate model, copied next to the export. Each export gets a
|
||||
`drafter.json` saying how to serve the pair; Studio's llama-server launcher reads it beside a GGUF.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import os
|
||||
import shlex
|
||||
import shutil
|
||||
from typing import Any, Optional
|
||||
|
||||
from loggers import get_logger
|
||||
|
||||
logger = get_logger(__name__)
|
||||
|
||||
DRAFTER_MANIFEST = "drafter.json"
|
||||
EAGLE3_DIRNAME = "eagle3"
|
||||
|
||||
|
||||
def _read_json(path: str) -> Optional[dict]:
|
||||
try:
|
||||
with open(path, encoding = "utf-8") as f:
|
||||
data = json.load(f)
|
||||
except (OSError, ValueError):
|
||||
return None
|
||||
return data if isinstance(data, dict) else None
|
||||
|
||||
|
||||
def _hub_adapter_snapshot(repo_id: str, token = None) -> Optional[str]:
|
||||
"""A Hub adapter's cached files (its manifest and MTP head): the loader re-attached that head."""
|
||||
if os.path.isabs(repo_id) or repo_id.count("/") != 1:
|
||||
return None
|
||||
try:
|
||||
from huggingface_hub import hf_hub_download
|
||||
|
||||
path = hf_hub_download(repo_id, DRAFTER_MANIFEST, token = token)
|
||||
for name in ("adapter_config.json", "mtp_head.safetensors"):
|
||||
try:
|
||||
hf_hub_download(repo_id, name, token = token)
|
||||
except Exception:
|
||||
pass
|
||||
return os.path.dirname(path)
|
||||
except Exception:
|
||||
return None
|
||||
|
||||
|
||||
def training_manifest(checkpoint_dir: Optional[str], token = None) -> Optional[dict]:
|
||||
"""The manifest the training run wrote, when its drafter is still complete on disk. `token` is
|
||||
the credential the checkpoint was loaded with (a private Hub adapter)."""
|
||||
if checkpoint_dir and not os.path.isdir(checkpoint_dir):
|
||||
checkpoint_dir = _hub_adapter_snapshot(checkpoint_dir, token)
|
||||
if not checkpoint_dir or not os.path.isdir(checkpoint_dir):
|
||||
return None
|
||||
manifest = _read_json(os.path.join(checkpoint_dir, DRAFTER_MANIFEST))
|
||||
if not manifest or manifest.get("strategy") not in ("mtp", "eagle3"):
|
||||
return None
|
||||
if manifest["strategy"] == "eagle3" and not os.path.isfile(
|
||||
os.path.join(checkpoint_dir, EAGLE3_DIRNAME, "config.json")
|
||||
):
|
||||
return None
|
||||
if manifest["strategy"] == "mtp" and not (
|
||||
os.path.isfile(os.path.join(checkpoint_dir, "mtp_head.safetensors"))
|
||||
or not os.path.isfile(os.path.join(checkpoint_dir, "adapter_config.json"))
|
||||
):
|
||||
return None
|
||||
return manifest
|
||||
|
||||
|
||||
def _engines(manifest: dict) -> dict:
|
||||
# Manifests from before per-engine support was recorded meant both.
|
||||
engines = manifest.get("engines")
|
||||
if not isinstance(engines, dict):
|
||||
return {"vllm": True, "llama_cpp": True}
|
||||
return {"vllm": bool(engines.get("vllm")), "llama_cpp": bool(engines.get("llama_cpp"))}
|
||||
|
||||
|
||||
def clear_stale(directory: str, ggufs: Optional[list[str]] = None) -> None:
|
||||
"""Remove a previous export's drafter from a reused folder, so nothing pairs it with this model."""
|
||||
info = _read_json(os.path.join(directory, DRAFTER_MANIFEST))
|
||||
if not info or info.get("strategy") not in ("mtp", "eagle3"):
|
||||
return
|
||||
listed = info.get("ggufs") or []
|
||||
if ggufs is not None and listed and not set(listed) & {os.path.basename(g) for g in ggufs}:
|
||||
return # describes other GGUFs in this folder
|
||||
for name in info.get("files") or []:
|
||||
path = os.path.join(directory, os.path.basename(name))
|
||||
if os.path.basename(name) == EAGLE3_DIRNAME and os.path.isdir(path):
|
||||
shutil.rmtree(path, ignore_errors = True)
|
||||
elif name.lower().endswith(".gguf") and os.path.isfile(path):
|
||||
os.remove(path)
|
||||
os.remove(os.path.join(directory, DRAFTER_MANIFEST))
|
||||
|
||||
|
||||
def _vllm_command(target: str, spec: dict, hub: bool) -> str:
|
||||
"""`vllm serve` for the exported pair. Hub repos: the repo id, after a download when the EAGLE-3
|
||||
drafter sits in a subfolder (vLLM loads a speculative model from a repo id or a local path only)."""
|
||||
prefix = ""
|
||||
if hub and spec["method"] == "eagle3":
|
||||
local = target.rstrip("/").split("/")[-1] or "model"
|
||||
prefix = f"hf download {shlex.quote(target)} --local-dir {shlex.quote(local)} && "
|
||||
target, spec = local, dict(spec, model = f"{local}/{EAGLE3_DIRNAME}")
|
||||
return f"{prefix}vllm serve {shlex.quote(target)} --speculative-config " + shlex.quote(
|
||||
json.dumps(spec, separators = (",", ":"))
|
||||
)
|
||||
|
||||
|
||||
def _steps(manifest: dict) -> int:
|
||||
try:
|
||||
return max(1, int(manifest.get("draft_steps") or 3))
|
||||
except (TypeError, ValueError):
|
||||
return 3
|
||||
|
||||
|
||||
def _write(directory: str, info: dict) -> None:
|
||||
path = os.path.join(directory, DRAFTER_MANIFEST)
|
||||
tmp = path + ".tmp"
|
||||
with open(tmp, "w", encoding = "utf-8") as f:
|
||||
json.dump(info, f, indent = 1)
|
||||
os.replace(tmp, path)
|
||||
|
||||
|
||||
def _set_verifier(eagle_dir: str, verifier: str) -> None:
|
||||
config_path = os.path.join(eagle_dir, "config.json")
|
||||
config = _read_json(config_path)
|
||||
if config is None:
|
||||
raise RuntimeError(f"{config_path} is not a readable EAGLE-3 config")
|
||||
spec = config.setdefault("speculators_config", {})
|
||||
spec.setdefault("verifier", {})["name_or_path"] = verifier
|
||||
with open(config_path, "w", encoding = "utf-8") as f:
|
||||
json.dump(config, f, indent = 2)
|
||||
|
||||
|
||||
def package_merged(
|
||||
checkpoint_dir: Optional[str],
|
||||
final_dir: str,
|
||||
*,
|
||||
verifier: Optional[str] = None,
|
||||
allow_mtp: bool = True,
|
||||
token = None,
|
||||
) -> Optional[dict]:
|
||||
"""Write `drafter.json` (and copy the EAGLE-3 drafter) into a merged export. None when the run
|
||||
trained no drafter. `verifier` is what the drafter's config names as its target: the Hub repo on a
|
||||
push, else the base model id (vLLM refuses a local verifier path inside a speculators config, so
|
||||
local serving passes the target explicitly). `allow_mtp` is False for exports that cannot carry
|
||||
a stitched head (compressed-tensors, torchao): only an EAGLE-3 drafter ships with those."""
|
||||
manifest = training_manifest(checkpoint_dir, token)
|
||||
if manifest is None or (manifest["strategy"] == "mtp" and not allow_mtp):
|
||||
clear_stale(final_dir)
|
||||
return None
|
||||
strategy, steps = manifest["strategy"], _steps(manifest)
|
||||
engines = _engines(manifest)
|
||||
hub = verifier is not None
|
||||
verifier = verifier or manifest.get("base_model") or ""
|
||||
target = verifier if hub else os.path.abspath(final_dir)
|
||||
if strategy == "mtp":
|
||||
spec = {"method": "mtp", "num_speculative_tokens": steps}
|
||||
files: list[str] = []
|
||||
else:
|
||||
dest = os.path.join(final_dir, EAGLE3_DIRNAME)
|
||||
source = os.path.join(checkpoint_dir, EAGLE3_DIRNAME)
|
||||
# An export into the training folder itself must not delete the only copy.
|
||||
if not (os.path.isdir(dest) and os.path.samefile(source, dest)):
|
||||
shutil.rmtree(dest, ignore_errors = True)
|
||||
shutil.copytree(source, dest)
|
||||
_set_verifier(dest, verifier)
|
||||
spec = {
|
||||
"method": "eagle3",
|
||||
"model": os.path.join(target, EAGLE3_DIRNAME),
|
||||
"num_speculative_tokens": steps,
|
||||
}
|
||||
files = [EAGLE3_DIRNAME]
|
||||
info = {
|
||||
"strategy": strategy,
|
||||
"files": files,
|
||||
"engines": engines,
|
||||
"vllm_command": _vllm_command(target, spec, hub) if engines["vllm"] else None,
|
||||
"llama_cpp_args": None,
|
||||
"base_model": manifest.get("base_model"),
|
||||
"verifier": verifier if strategy == "eagle3" else None,
|
||||
"draft_steps": steps,
|
||||
"metrics": manifest.get("metrics") or {},
|
||||
}
|
||||
_write(final_dir, info)
|
||||
return info
|
||||
|
||||
|
||||
def eagle3_gguf_name(ggufs: list[str]) -> str:
|
||||
stem = os.path.basename(ggufs[0]).split(".")[0] if ggufs else ""
|
||||
# `eagle3-` prefix: Studio's model pickers treat it as a drafter companion, not a model.
|
||||
return f"eagle3-{stem or 'model'}-F16.gguf"
|
||||
|
||||
|
||||
def package_gguf(
|
||||
checkpoint_dir: Optional[str],
|
||||
merged_dir: Optional[str],
|
||||
gguf_dir: str,
|
||||
ggufs: list[str],
|
||||
token = None,
|
||||
) -> tuple[Optional[dict], list[str]]:
|
||||
"""(drafter info, extra files written into gguf_dir). The MTP head is already inside each GGUF; an
|
||||
EAGLE-3 drafter is converted beside them against the merged target (the converter reads its config
|
||||
and tokenizer). Raises when the drafter cannot be converted: a pair missing its drafter is incomplete."""
|
||||
manifest = training_manifest(checkpoint_dir, token)
|
||||
engines = _engines(manifest) if manifest else {}
|
||||
if manifest is None or not engines["llama_cpp"]:
|
||||
clear_stale(gguf_dir, ggufs)
|
||||
return None, []
|
||||
strategy, steps = manifest["strategy"], _steps(manifest)
|
||||
extra: list[str] = []
|
||||
names = [os.path.basename(g) for g in ggufs]
|
||||
if strategy == "mtp":
|
||||
args = ["--spec-type", "draft-mtp", "--spec-draft-n-max", str(steps)]
|
||||
else:
|
||||
if not merged_dir or not os.path.isfile(os.path.join(merged_dir, "config.json")):
|
||||
raise RuntimeError(
|
||||
"the merged target checkpoint needed to convert the EAGLE-3 drafter is missing"
|
||||
)
|
||||
from unsloth_zoo.speculative import convert_eagle3_to_gguf
|
||||
|
||||
out = os.path.join(gguf_dir, eagle3_gguf_name(ggufs))
|
||||
convert_eagle3_to_gguf(
|
||||
os.path.join(checkpoint_dir, EAGLE3_DIRNAME), merged_dir, out, outtype = "f16"
|
||||
)
|
||||
if not os.path.isfile(out):
|
||||
raise RuntimeError("EAGLE-3 drafter conversion wrote no GGUF")
|
||||
extra.append(out)
|
||||
args = [
|
||||
"--model-draft",
|
||||
os.path.basename(out),
|
||||
"--spec-type",
|
||||
"draft-eagle3",
|
||||
"--spec-draft-n-max",
|
||||
str(steps),
|
||||
]
|
||||
info = {
|
||||
"strategy": strategy,
|
||||
"files": [os.path.basename(f) for f in extra],
|
||||
"ggufs": names,
|
||||
"engines": engines,
|
||||
"mtp_trained": strategy == "mtp",
|
||||
"vllm_command": None,
|
||||
"llama_cpp_args": args,
|
||||
"base_model": manifest.get("base_model"),
|
||||
"draft_steps": steps,
|
||||
"metrics": manifest.get("metrics") or {},
|
||||
}
|
||||
_write(gguf_dir, info)
|
||||
extra.append(os.path.join(gguf_dir, DRAFTER_MANIFEST))
|
||||
return info, extra
|
||||
|
||||
|
||||
def package_lora(
|
||||
checkpoint_dir: Optional[str],
|
||||
adapter_dir: str,
|
||||
head_saved: Optional[bool] = None,
|
||||
token = None,
|
||||
) -> Optional[dict]:
|
||||
"""Carry the training manifest with a LoRA export that kept the trained MTP head beside it, so a
|
||||
later merge / GGUF of that adapter still marks the head as trained (Studio's MTP launch policy).
|
||||
`head_saved` overrides the sidecar check (a Hub push saves the adapter elsewhere)."""
|
||||
manifest = training_manifest(checkpoint_dir, token)
|
||||
if head_saved is None:
|
||||
head_saved = os.path.isfile(os.path.join(adapter_dir, "mtp_head.safetensors"))
|
||||
if manifest is None or manifest["strategy"] != "mtp" or not head_saved:
|
||||
clear_stale(adapter_dir)
|
||||
return None
|
||||
keep = (
|
||||
"version",
|
||||
"strategy",
|
||||
"base_model",
|
||||
"draft_steps",
|
||||
"metrics",
|
||||
"engines",
|
||||
"family",
|
||||
"llama_cpp_status",
|
||||
"vllm",
|
||||
"llama_cpp",
|
||||
"created_at",
|
||||
)
|
||||
info = {k: manifest[k] for k in keep if k in manifest}
|
||||
info["files"] = ["mtp_head.safetensors"]
|
||||
_write(adapter_dir, info)
|
||||
return info
|
||||
|
||||
|
||||
def export_drafter_details(output_path: Optional[str]) -> Optional[dict[str, Any]]:
|
||||
"""The `drafter` block an export response carries (the frontend contract)."""
|
||||
if not output_path or not os.path.isdir(output_path):
|
||||
return None
|
||||
info = _read_json(os.path.join(output_path, DRAFTER_MANIFEST))
|
||||
if not info or info.get("strategy") not in ("mtp", "eagle3"):
|
||||
return None
|
||||
return {
|
||||
"strategy": info["strategy"],
|
||||
"files": list(info.get("files") or []),
|
||||
"vllm_command": info.get("vllm_command"),
|
||||
"llama_cpp_args": info.get("llama_cpp_args"),
|
||||
}
|
||||
|
||||
|
||||
def eagle3_sidecar_path(gguf_path: Optional[str]) -> Optional[str]:
|
||||
"""The EAGLE-3 drafter GGUF exported next to this GGUF, when its manifest pairs them."""
|
||||
info = gguf_drafter_sidecar(gguf_path)
|
||||
if not info or info.get("strategy") != "eagle3":
|
||||
return None
|
||||
directory = os.path.dirname(os.path.abspath(gguf_path))
|
||||
for name in info.get("files") or []:
|
||||
path = os.path.join(directory, os.path.basename(name))
|
||||
if name.lower().endswith(".gguf") and os.path.isfile(path):
|
||||
return path
|
||||
return None
|
||||
|
||||
|
||||
def gguf_drafter_sidecar(gguf_path: Optional[str]) -> Optional[dict]:
|
||||
"""The export manifest next to a GGUF, when it names that GGUF (llama-server launch policy)."""
|
||||
if not gguf_path:
|
||||
return None
|
||||
directory = os.path.dirname(os.path.abspath(gguf_path))
|
||||
info = _read_json(os.path.join(directory, DRAFTER_MANIFEST))
|
||||
if not info or info.get("strategy") not in ("mtp", "eagle3"):
|
||||
return None
|
||||
ggufs = info.get("ggufs") or []
|
||||
if ggufs and os.path.basename(gguf_path) not in ggufs:
|
||||
return None
|
||||
return info
|
||||
|
|
@ -729,6 +729,7 @@ class ExportBackend:
|
|||
def __init__(self):
|
||||
self.inference_backend = get_inference_backend()
|
||||
self.current_checkpoint = None
|
||||
self._checkpoint_token = None
|
||||
self.current_model = None
|
||||
self.current_tokenizer = None
|
||||
self.is_vision = False
|
||||
|
|
@ -757,6 +758,7 @@ class ExportBackend:
|
|||
self.current_model = None
|
||||
self.current_tokenizer = None
|
||||
self.current_checkpoint = None
|
||||
self._checkpoint_token = None
|
||||
self._audio_type = None
|
||||
self.decision = None
|
||||
|
||||
|
|
@ -1043,6 +1045,9 @@ class ExportBackend:
|
|||
self.current_model = model
|
||||
self.current_tokenizer = tokenizer
|
||||
self.current_checkpoint = checkpoint_path
|
||||
self._checkpoint_token = token
|
||||
if not self.is_peft and not _IS_MLX:
|
||||
self._attach_full_checkpoint_mtp_head(checkpoint_path)
|
||||
|
||||
if self._audio_type:
|
||||
model_type = f"Audio ({self._audio_type})"
|
||||
|
|
@ -1425,6 +1430,13 @@ class ExportBackend:
|
|||
else save_directory
|
||||
)
|
||||
self._write_export_metadata(final_dir)
|
||||
if not _IS_MLX:
|
||||
# Compressed / torchao siblings carry no stitched MTP head; an EAGLE-3 drafter ships.
|
||||
self._package_drafter_merged(
|
||||
final_dir,
|
||||
repo_id if push_to_hub else None,
|
||||
allow_mtp = not (is_compressed or is_torchao),
|
||||
)
|
||||
logger.info(f"Model saved successfully to {final_dir}")
|
||||
output_path = str(Path(final_dir).resolve())
|
||||
|
||||
|
|
@ -1468,6 +1480,7 @@ class ExportBackend:
|
|||
save_method = save_method,
|
||||
**merged_token_kw,
|
||||
)
|
||||
self._package_drafter_merged(upload_dir, repo_id)
|
||||
# Whatever was built, only weights are worth a repo; without them the
|
||||
# merging push below runs instead, as it did before this was uploaded.
|
||||
if _holds_checkpoint_weights(upload_dir):
|
||||
|
|
@ -1576,6 +1589,8 @@ class ExportBackend:
|
|||
else:
|
||||
self.current_model.save_pretrained(save_directory)
|
||||
self.current_tokenizer.save_pretrained(save_directory)
|
||||
# A full fine-tune trained with a drafter ships it like a merged export.
|
||||
self._package_drafter_merged(save_directory, repo_id if push_to_hub else None)
|
||||
|
||||
self._write_export_metadata(save_directory)
|
||||
logger.info(f"Model saved successfully to {save_directory}")
|
||||
|
|
@ -1617,6 +1632,7 @@ class ExportBackend:
|
|||
)
|
||||
self.current_model.save_pretrained(upload_dir)
|
||||
self.current_tokenizer.save_pretrained(upload_dir)
|
||||
self._package_drafter_merged(upload_dir, repo_id)
|
||||
hf_api = HfApi(token = hf_token)
|
||||
repo_url = hf_api.create_repo(repo_id, private = private, exist_ok = True)
|
||||
repo_id = getattr(repo_url, "repo_id", repo_id)
|
||||
|
|
@ -1712,6 +1728,7 @@ class ExportBackend:
|
|||
|
||||
output_path: Optional[str] = None
|
||||
exported_ggufs: List[str] = []
|
||||
drafter_gguf_files: List[str] = []
|
||||
exported_modelfile = False
|
||||
exported_modelfile_bytes: Optional[bytes] = None
|
||||
exported_is_vlm = False
|
||||
|
|
@ -1801,6 +1818,10 @@ class ExportBackend:
|
|||
"GGUF conversion produced only AppleDouble metadata companions "
|
||||
f"and no usable .gguf file for {abs_save_dir}"
|
||||
)
|
||||
drafter_gguf_files = self._package_drafter_gguf(
|
||||
reported.get("save_directory") or _model_tmp, abs_save_dir, exported_ggufs
|
||||
)
|
||||
exported_ggufs.extend(f for f in drafter_gguf_files if f.endswith(".gguf"))
|
||||
exported_is_vlm = bool(
|
||||
reported.get("is_vlm", getattr(self, "is_vision", False))
|
||||
)
|
||||
|
|
@ -1922,6 +1943,7 @@ class ExportBackend:
|
|||
allow_patterns = [
|
||||
*(glob.escape(os.path.basename(f)) for f in exported_ggufs),
|
||||
*(["Modelfile"] if exported_modelfile else []),
|
||||
*(["drafter.json"] if drafter_gguf_files else []),
|
||||
],
|
||||
)
|
||||
if exported_config is not None:
|
||||
|
|
@ -1987,6 +2009,98 @@ class ExportBackend:
|
|||
)
|
||||
return False, f"GGUF export failed: {str(e)}", None
|
||||
|
||||
def _attach_full_checkpoint_mtp_head(self, checkpoint_path: str) -> None:
|
||||
"""A full fine-tune keeps its trained MTP head only inside its shards, which transformers
|
||||
drops on load: attach it so every export writes it back."""
|
||||
try:
|
||||
from core.export.drafter_export import training_manifest
|
||||
|
||||
if not os.path.isdir(checkpoint_path) or os.path.isfile(
|
||||
os.path.join(checkpoint_path, "adapter_config.json")
|
||||
):
|
||||
return
|
||||
manifest = training_manifest(checkpoint_path)
|
||||
if not manifest or manifest.get("strategy") != "mtp":
|
||||
return
|
||||
from unsloth import FastModel
|
||||
|
||||
FastModel.get_mtp_head(self.current_model, source = checkpoint_path)
|
||||
logger.info(f"Attached the trained MTP head from {checkpoint_path}")
|
||||
except Exception as exception:
|
||||
logger.warning(f"Could not attach the trained MTP head: {exception}")
|
||||
|
||||
def _package_drafter_merged(
|
||||
self,
|
||||
final_dir: str,
|
||||
repo_id: Optional[str],
|
||||
allow_mtp: bool = True,
|
||||
) -> None:
|
||||
"""Ship the drafter trained with this fine-tune next to a merged export (best-effort: the
|
||||
merged model is valid without it)."""
|
||||
try:
|
||||
from core.export.drafter_export import package_merged
|
||||
info = package_merged(
|
||||
self.current_checkpoint,
|
||||
final_dir,
|
||||
verifier = repo_id,
|
||||
allow_mtp = allow_mtp,
|
||||
token = self._checkpoint_token,
|
||||
)
|
||||
if info:
|
||||
logger.info(f"Packaged the trained {info['strategy']} drafter into {final_dir}")
|
||||
except Exception as exception:
|
||||
logger.warning(f"Could not package the trained drafter: {exception}")
|
||||
|
||||
def _package_drafter_lora(
|
||||
self,
|
||||
adapter_dir: str,
|
||||
head_saved: Optional[bool] = None,
|
||||
) -> bool:
|
||||
try:
|
||||
from core.export.drafter_export import package_lora
|
||||
return (
|
||||
package_lora(
|
||||
self.current_checkpoint, adapter_dir, head_saved, token = self._checkpoint_token
|
||||
)
|
||||
is not None
|
||||
)
|
||||
except Exception as exception:
|
||||
logger.warning(f"Could not carry the drafter manifest with the adapter: {exception}")
|
||||
return False
|
||||
|
||||
def _push_drafter_lora_manifest(self, hf_api, repo_id: str) -> None:
|
||||
"""push_to_hub uploads the head beside the adapter but not Studio's manifest."""
|
||||
try:
|
||||
from unsloth.save import _attached_mtp_head
|
||||
from core.export.drafter_export import DRAFTER_MANIFEST
|
||||
with tempfile.TemporaryDirectory() as tmp:
|
||||
head = _attached_mtp_head(self.current_model) is not None
|
||||
if self._package_drafter_lora(tmp, head_saved = head):
|
||||
hf_api.upload_file(
|
||||
path_or_fileobj = os.path.join(tmp, DRAFTER_MANIFEST),
|
||||
path_in_repo = DRAFTER_MANIFEST,
|
||||
repo_id = repo_id,
|
||||
repo_type = "model",
|
||||
)
|
||||
except Exception as exception:
|
||||
logger.warning(f"Could not upload the drafter manifest with the adapter: {exception}")
|
||||
|
||||
def _package_drafter_gguf(self, merged_dir: str, gguf_dir: str, ggufs: List[str]) -> List[str]:
|
||||
try:
|
||||
from core.export.drafter_export import package_gguf
|
||||
|
||||
info, files = package_gguf(
|
||||
self.current_checkpoint, merged_dir, gguf_dir, ggufs, token = self._checkpoint_token
|
||||
)
|
||||
if info:
|
||||
logger.info(f"Packaged the trained {info['strategy']} drafter with the GGUF export")
|
||||
return files
|
||||
except Exception as exception:
|
||||
logger.warning(
|
||||
f"Could not package the trained drafter with the GGUF export: {exception}"
|
||||
)
|
||||
return []
|
||||
|
||||
def _write_q4nx_companions(self, q4nx_dir: Path, config: Optional[bytes]) -> None:
|
||||
"""The tokenizer files FastFlowLM loads next to model.q4nx (see q4nx.CONFIG_FILES)."""
|
||||
with tempfile.TemporaryDirectory(prefix = "_tmp_tokenizer_", dir = q4nx_dir) as scratch:
|
||||
|
|
@ -2357,6 +2471,7 @@ class ExportBackend:
|
|||
else:
|
||||
self.current_model.save_pretrained(save_directory)
|
||||
self.current_tokenizer.save_pretrained(save_directory)
|
||||
self._package_drafter_lora(save_directory)
|
||||
self._write_export_metadata(save_directory)
|
||||
logger.info(f"Adapter saved successfully to {save_directory}")
|
||||
output_path = str(Path(save_directory).resolve())
|
||||
|
|
@ -2418,6 +2533,7 @@ class ExportBackend:
|
|||
_publish_unsloth_model_card(hf_api, repo_id, self.current_model, hf_token)
|
||||
self.current_model.push_to_hub(repo_id, token = hf_token, private = private)
|
||||
self.current_tokenizer.push_to_hub(repo_id, token = hf_token, private = private)
|
||||
self._push_drafter_lora_manifest(hf_api, repo_id)
|
||||
logger.info(f"Adapter pushed successfully to {repo_id}")
|
||||
|
||||
return True, "LoRA adapter exported successfully", output_path
|
||||
|
|
|
|||
|
|
@ -262,6 +262,11 @@ class EngineAdapter:
|
|||
*(["--trust-remote-code"] if trust_remote_code else []),
|
||||
# Prefix caching is on by default in both; this only reports its hits in usage.
|
||||
"--enable-prompt-tokens-details" if self.name == "vllm" else "--enable-cache-report",
|
||||
*(
|
||||
vllm_speculative_args(model)
|
||||
if self.name == "vllm" and not options.get("no_speculative_config")
|
||||
else []
|
||||
),
|
||||
*self.extra_args,
|
||||
"--host",
|
||||
"127.0.0.1",
|
||||
|
|
@ -303,6 +308,59 @@ ADAPTERS = {
|
|||
}
|
||||
|
||||
|
||||
def _wsl_guest_to_host(path: str, nt: "bool | None" = None) -> str:
|
||||
"""`/mnt/c/x` (the path the Windows WSL engine is given) back to `C:\\x` for host-side reads."""
|
||||
import os
|
||||
import re
|
||||
|
||||
if (os.name == "nt" if nt is None else nt) and re.match(r"^/mnt/[a-zA-Z](/|$)", path):
|
||||
return path[5].upper() + ":\\" + path[7:].replace("/", "\\")
|
||||
return path
|
||||
|
||||
|
||||
def vllm_speculative_args(model) -> list[str]:
|
||||
"""`--speculative-config` for a merged Studio export that carries a drafter trained with the
|
||||
fine-tune (drafter.json): its own MTP head, or the EAGLE-3 drafter in `<export>/eagle3`."""
|
||||
import json
|
||||
import os
|
||||
|
||||
if not isinstance(model, str):
|
||||
return []
|
||||
host = _wsl_guest_to_host(model)
|
||||
if not os.path.isdir(host):
|
||||
return []
|
||||
try:
|
||||
with open(os.path.join(host, "drafter.json"), encoding = "utf-8") as f:
|
||||
info = json.load(f)
|
||||
except (OSError, ValueError):
|
||||
return []
|
||||
if not isinstance(info, dict):
|
||||
return []
|
||||
# A drafter vLLM cannot run (llama.cpp-only EAGLE-3 targets, some MTP families) must not stop
|
||||
# the model from starting.
|
||||
if isinstance(info.get("engines"), dict) and not info["engines"].get("vllm"):
|
||||
return []
|
||||
steps = info.get("draft_steps") or 3
|
||||
if info.get("strategy") == "mtp":
|
||||
spec = {"method": "mtp", "num_speculative_tokens": int(steps)}
|
||||
elif info.get("strategy") == "eagle3" and os.path.isfile(
|
||||
os.path.join(host, "eagle3", "config.json")
|
||||
):
|
||||
spec = {
|
||||
"method": "eagle3",
|
||||
# The path vLLM sees: the WSL guest's when the model path was translated for it.
|
||||
"model": (
|
||||
model.rstrip("/") + "/eagle3"
|
||||
if host != model
|
||||
else os.path.join(os.path.abspath(model), "eagle3")
|
||||
),
|
||||
"num_speculative_tokens": int(steps),
|
||||
}
|
||||
else:
|
||||
return []
|
||||
return ["--speculative-config", json.dumps(spec, separators = (",", ":"))]
|
||||
|
||||
|
||||
def launch_arguments(
|
||||
engine,
|
||||
python,
|
||||
|
|
|
|||
|
|
@ -822,6 +822,7 @@ _UNRECOVERABLE_LOCAL_ERRNOS = frozenset(
|
|||
_SPEC_KIND_CAPABILITY: dict[str, str] = {
|
||||
"dspark": "supports_dspark",
|
||||
"dflash": "supports_dflash",
|
||||
"eagle3": "supports_eagle3",
|
||||
"mtp": "supports_mtp",
|
||||
}
|
||||
|
||||
|
|
@ -3315,7 +3316,7 @@ _DRAFTER_KINDS = ("mtp", "dspark", "dflash", "eagle3")
|
|||
_DRAFTER_DIR_KINDS = ("mtp", "dspark")
|
||||
|
||||
# Human label per resolved spec mode, for launch logging and the UI notice.
|
||||
_DRAFTER_DISPLAY_LABELS = {"dspark": "DSpark", "dflash": "DFlash"}
|
||||
_DRAFTER_DISPLAY_LABELS = {"dspark": "DSpark", "dflash": "DFlash", "eagle3": "EAGLE-3"}
|
||||
|
||||
|
||||
def _drafter_path_kind(path: str) -> Optional[str]:
|
||||
|
|
@ -7625,6 +7626,7 @@ _CANONICAL_SPEC_MODES = {
|
|||
"auto",
|
||||
"mtp",
|
||||
"dspark",
|
||||
"eagle3",
|
||||
"dflash",
|
||||
"ngram",
|
||||
"mtp+ngram",
|
||||
|
|
@ -7636,6 +7638,7 @@ _LEGACY_SPEC_MODE_MAP = {
|
|||
"draft-mtp": "mtp",
|
||||
"draft-dspark": "dspark",
|
||||
"draft-dflash": "dflash",
|
||||
"draft-eagle3": "eagle3",
|
||||
"ngram-mod": "ngram",
|
||||
"none": "off",
|
||||
"disable": "off",
|
||||
|
|
@ -7643,6 +7646,25 @@ _LEGACY_SPEC_MODE_MAP = {
|
|||
}
|
||||
|
||||
|
||||
def _trained_drafter_sidecar(model_path):
|
||||
"""(eagle3 drafter path, MTP head trained, draft steps) from the drafter.json a Studio export
|
||||
wrote beside the GGUF."""
|
||||
if not model_path:
|
||||
return None, False, None
|
||||
try:
|
||||
from core.export.drafter_export import eagle3_sidecar_path, gguf_drafter_sidecar
|
||||
|
||||
info = gguf_drafter_sidecar(model_path) or {}
|
||||
try:
|
||||
steps = max(1, int(info["draft_steps"])) if info.get("draft_steps") else None
|
||||
except (TypeError, ValueError):
|
||||
steps = None
|
||||
return eagle3_sidecar_path(model_path), bool(info.get("mtp_trained")), steps
|
||||
except Exception as exc:
|
||||
logger.debug("Could not read a drafter manifest beside %s: %s", model_path, exc)
|
||||
return None, False, None
|
||||
|
||||
|
||||
def _canonicalize_spec_mode(value):
|
||||
"""Map any accepted ``speculative_type`` input onto a canonical mode.
|
||||
|
||||
|
|
@ -10387,6 +10409,7 @@ class LlamaCppBackend:
|
|||
"supports_mtp": False,
|
||||
"supports_dspark": False,
|
||||
"supports_dflash": False,
|
||||
"supports_eagle3": False,
|
||||
"mtp_probe_inconclusive": True,
|
||||
"ngram_mod_flavor": None,
|
||||
"supports_ngram_mod": False,
|
||||
|
|
@ -10451,6 +10474,7 @@ class LlamaCppBackend:
|
|||
mtp_token: Optional[str] = None
|
||||
supports_dspark = False
|
||||
supports_dflash = False
|
||||
supports_eagle3 = False
|
||||
ngram_mod_flavor: Optional[str] = None
|
||||
spec_draft_n_max_flag: Optional[str] = None
|
||||
spec_draft_n_max_default: Optional[int] = None
|
||||
|
|
@ -10628,6 +10652,9 @@ class LlamaCppBackend:
|
|||
spec_help.lower(),
|
||||
)
|
||||
)
|
||||
supports_eagle3 = bool(
|
||||
re.search(r"(?<![a-z0-9_-])draft-eagle3(?![a-z0-9_-])", spec_help.lower())
|
||||
)
|
||||
# Same word-boundary match as DSpark: draft-dflash only exists on
|
||||
# builds that carry the arch, and emitting a --spec-type the binary
|
||||
# does not know aborts the launch instead of falling back.
|
||||
|
|
@ -10810,6 +10837,7 @@ class LlamaCppBackend:
|
|||
"supports_mtp": supports_mtp,
|
||||
"supports_dspark": bool(supports_dspark and saw_spec_type and probe_ok),
|
||||
"supports_dflash": bool(supports_dflash and saw_spec_type and probe_ok),
|
||||
"supports_eagle3": bool(supports_eagle3 and saw_spec_type and probe_ok),
|
||||
"mtp_probe_inconclusive": mtp_probe_inconclusive,
|
||||
"ngram_mod_flavor": ngram_mod_flavor,
|
||||
"supports_ngram_mod": ngram_mod_flavor is not None,
|
||||
|
|
@ -33544,6 +33572,8 @@ class LlamaCppBackend:
|
|||
_spec_requested_dflash = any(
|
||||
"draft-dflash" in str(t).lower() for t in spec_flags
|
||||
) or _extra_args_requests_dflash(extra_args, env = _launch_spec_env)
|
||||
# A paired EAGLE-3 drafter (Studio export) can abort the server the same way.
|
||||
_spec_requested_eagle3 = any("draft-eagle3" in str(t).lower() for t in spec_flags)
|
||||
# Any MTP launch, not only tensor: a respawn would replay a drafter that
|
||||
# aborts every decode (#13253). Cleared if the MTP-drop fallback wins.
|
||||
_mtp_active_for_launched_server = bool(_spec_requested_mtp)
|
||||
|
|
@ -33625,7 +33655,12 @@ class LlamaCppBackend:
|
|||
_spec_cpu_replay_cmd: Optional[List[str]] = None
|
||||
if (
|
||||
not healthy
|
||||
and (_spec_requested_mtp or _spec_requested_dspark or _spec_requested_dflash)
|
||||
and (
|
||||
_spec_requested_mtp
|
||||
or _spec_requested_dspark
|
||||
or _spec_requested_dflash
|
||||
or _spec_requested_eagle3
|
||||
)
|
||||
and not _load_cancelled()
|
||||
):
|
||||
_spec_cpu_replay_cmd = list(_last_spawn_cmd)
|
||||
|
|
@ -34376,6 +34411,8 @@ class LlamaCppBackend:
|
|||
embedded_mtp_partial_offload: bool = False,
|
||||
draft_device: Optional[str] = None,
|
||||
mtp_drafter_unloadable: bool = False,
|
||||
eagle3_draft_path: Optional[str] = None,
|
||||
mtp_trained: Optional[bool] = None,
|
||||
) -> List[str]:
|
||||
"""Return the llama-server flag list for the requested spec mode.
|
||||
|
||||
|
|
@ -34426,6 +34463,12 @@ class LlamaCppBackend:
|
|||
self._spec_draft_n_max = None
|
||||
self._speculative_type = None
|
||||
self._spec_fallback_reason = None
|
||||
# A drafter trained with the fine-tune and exported beside this GGUF (drafter.json).
|
||||
trained_steps = None
|
||||
if eagle3_draft_path is None or mtp_trained is None:
|
||||
sidecar_eagle3, sidecar_trained, trained_steps = _trained_drafter_sidecar(model_path)
|
||||
eagle3_draft_path = eagle3_draft_path or sidecar_eagle3
|
||||
mtp_trained = sidecar_trained if mtp_trained is None else mtp_trained
|
||||
|
||||
# Canonical UI-facing requested mode (legacy values mapped via
|
||||
# _canonicalize_spec_mode).
|
||||
|
|
@ -34454,8 +34497,13 @@ class LlamaCppBackend:
|
|||
_mtp_size_b = _extract_model_size_b(model_identifier)
|
||||
# The sub-3B regression is an embedded-head cost; a separate drafter
|
||||
# (Gemma) is a cheap standalone model that wins below 3B, so exempt it.
|
||||
# A head the user trained with this fine-tune is what they asked to draft with, so the
|
||||
# size floor (a stock-head cost measurement) and the MLA default-off below do not apply.
|
||||
_mtp_too_small = (
|
||||
_mtp_size_b is not None and _mtp_size_b < _MTP_MIN_SIZE_B and not bool(mtp_draft_path)
|
||||
_mtp_size_b is not None
|
||||
and _mtp_size_b < _MTP_MIN_SIZE_B
|
||||
and not bool(mtp_draft_path)
|
||||
and not mtp_trained
|
||||
)
|
||||
# Drafterless Gemma (name-only MTP, no embedded head), or any quant whose only
|
||||
# drafter was dropped as unopenable: emitting MTP would abort llama-server, so
|
||||
|
|
@ -34477,6 +34525,7 @@ class LlamaCppBackend:
|
|||
and not bool(mtp_draft_path)
|
||||
and not _mla_mtp_auto_enabled()
|
||||
and not _arch_has_fast_mla_mtp(getattr(self, "_architecture", None))
|
||||
and not mtp_trained
|
||||
)
|
||||
|
||||
if user_owns_spec_type:
|
||||
|
|
@ -34500,6 +34549,49 @@ class LlamaCppBackend:
|
|||
# and under Auto neither the requested mode nor the resolved
|
||||
# _speculative_type ("default" after a fallback) still carries the kind.
|
||||
_auto_mode = (canonical_mode or "auto") == "auto"
|
||||
if canonical_mode == "eagle3" or (
|
||||
_auto_mode and eagle3_draft_path and caps.get("supports_eagle3")
|
||||
):
|
||||
self._spec_drafter_kind = "eagle3"
|
||||
if not caps.get("supports_eagle3"):
|
||||
logger.warning(
|
||||
"EAGLE-3 requested but llama-server lacks --spec-type draft-eagle3; "
|
||||
"loading without speculative decoding."
|
||||
)
|
||||
flags.append("--spec-default")
|
||||
self._speculative_type = "default"
|
||||
self._spec_fallback_reason = "binary_no_mtp"
|
||||
return flags
|
||||
if not eagle3_draft_path:
|
||||
logger.warning(
|
||||
"EAGLE-3 requested but no trained eagle3-*.gguf drafter sits next to this "
|
||||
"model; loading without speculative decoding."
|
||||
)
|
||||
flags.append("--spec-default")
|
||||
self._speculative_type = "default"
|
||||
self._spec_fallback_reason = "drafter_not_found"
|
||||
return flags
|
||||
draft_n_max = (
|
||||
int(spec_draft_n_max) if spec_draft_n_max is not None else (trained_steps or 3)
|
||||
)
|
||||
if spec_draft_n_max is not None:
|
||||
self._spec_draft_n_max = draft_n_max
|
||||
n_max_flag = caps.get("spec_draft_n_max_flag") or "--spec-draft-n-max"
|
||||
flags.extend(
|
||||
[
|
||||
"--model-draft",
|
||||
eagle3_draft_path,
|
||||
"--spec-type",
|
||||
"draft-eagle3",
|
||||
str(n_max_flag),
|
||||
str(draft_n_max),
|
||||
]
|
||||
)
|
||||
if draft_device:
|
||||
flags.extend(["--spec-draft-device", draft_device])
|
||||
self._speculative_type = "draft-eagle3"
|
||||
logger.info("Spec decoding: draft-eagle3 using %s", eagle3_draft_path)
|
||||
return flags
|
||||
if canonical_mode == "dspark" or (
|
||||
_auto_mode and dspark_draft_path and caps.get("supports_dspark")
|
||||
):
|
||||
|
|
@ -34519,6 +34611,8 @@ class LlamaCppBackend:
|
|||
n = int(spec_draft_n_max)
|
||||
self._spec_draft_n_max = n
|
||||
return n
|
||||
if mtp_trained and trained_steps and self._spec_drafter_kind == "mtp":
|
||||
return trained_steps # the depth the exported head was trained for
|
||||
return 2 if gpus else 3
|
||||
|
||||
def _emit_dspark() -> None:
|
||||
|
|
|
|||
|
|
@ -490,6 +490,10 @@ class _MambaSeqLimit(RuntimeError):
|
|||
self.blocks = blocks
|
||||
|
||||
|
||||
class _EngineExited(RuntimeError):
|
||||
"""The engine process exited during startup (not a stop, cancel or timeout)."""
|
||||
|
||||
|
||||
def _token_file_token(env) -> str | None:
|
||||
"""The `hf auth login` token a local engine would read from its inherited HF_HOME; the WSL
|
||||
guest gets its own HF_HOME, so the token has to cross over. Anonymous loads keep none."""
|
||||
|
|
@ -546,8 +550,49 @@ class ManagedEngine:
|
|||
model_path = None,
|
||||
):
|
||||
"""``model`` is the served name; ``model_path`` is what the engine loads when they differ."""
|
||||
args = (model, context, gpu_ids, env, cancel_event)
|
||||
options = dict(options or {})
|
||||
try:
|
||||
return self._start_seq_limited(
|
||||
model, context, gpu_ids, env, cancel_event, options, trust_remote_code, model_path
|
||||
)
|
||||
except _EngineExited as exc:
|
||||
if not self._drafter_retry(model, model_path, options):
|
||||
raise
|
||||
if cancel_event is not None and cancel_event.is_set():
|
||||
self.stop()
|
||||
raise RuntimeError("Model load cancelled") from exc
|
||||
# A drafter trained with the fine-tune must not keep the model itself from loading.
|
||||
from loggers import get_logger
|
||||
|
||||
get_logger(__name__).warning(
|
||||
"vLLM did not start with the trained drafter (%s); retrying without it.", exc
|
||||
)
|
||||
self._tail.clear()
|
||||
self._mamba_blocks = None
|
||||
self.phase = "starting"
|
||||
return self._start_seq_limited(
|
||||
model,
|
||||
context,
|
||||
gpu_ids,
|
||||
env,
|
||||
cancel_event,
|
||||
{**options, "no_speculative_config": True},
|
||||
trust_remote_code,
|
||||
model_path,
|
||||
)
|
||||
|
||||
def _drafter_retry(self, model, model_path, options) -> bool:
|
||||
"""A failed vLLM start that passed a drafter's --speculative-config is retried without it."""
|
||||
if self.engine != "vllm" or (options or {}).get("no_speculative_config"):
|
||||
return False
|
||||
from core.inference.engine_adapters import vllm_speculative_args
|
||||
|
||||
return bool(vllm_speculative_args(model_path or model))
|
||||
|
||||
def _start_seq_limited(
|
||||
self, model, context, gpu_ids, env, cancel_event, options, trust_remote_code, model_path
|
||||
):
|
||||
args = (model, context, gpu_ids, env, cancel_event)
|
||||
key = (
|
||||
self.engine,
|
||||
model_path or model,
|
||||
|
|
@ -736,7 +781,7 @@ class ManagedEngine:
|
|||
message = "Engine failed to start. " + "\n".join(self._tail)
|
||||
if self._mamba_blocks:
|
||||
raise _MambaSeqLimit(message, self._mamba_blocks)
|
||||
raise RuntimeError(message)
|
||||
raise _EngineExited(message)
|
||||
try:
|
||||
response = client.get(self.base_url + "/health", headers = self.headers)
|
||||
if response.status_code == 200:
|
||||
|
|
@ -753,6 +798,12 @@ class ManagedEngine:
|
|||
# Not a stop request: an external stop() meanwhile must still cancel the relaunch.
|
||||
self._teardown()
|
||||
raise
|
||||
except _EngineExited:
|
||||
if self._drafter_retry(model, model_path, options):
|
||||
self._teardown()
|
||||
else:
|
||||
self.stop()
|
||||
raise
|
||||
except Exception:
|
||||
self.stop()
|
||||
raise
|
||||
|
|
|
|||
881
studio/backend/core/training/drafter.py
Normal file
881
studio/backend/core/training/drafter.py
Normal file
|
|
@ -0,0 +1,881 @@
|
|||
# SPDX-License-Identifier: AGPL-3.0-only
|
||||
# Copyright 2026-present the Unsloth AI Inc. team. All rights reserved. See /studio/LICENSE.AGPL-3.0
|
||||
|
||||
"""Speculative-decoding drafter trained after the fine-tune.
|
||||
|
||||
Models with a native MTP head retrain it (llama.cpp `draft-mtp`, vLLM `method="mtp"`); models without one get
|
||||
an EAGLE-3 drafter in the speculators layout (llama.cpp `draft-eagle3`, vLLM `method="eagle3"`). A fresh MTP
|
||||
head on an architecture without an MTP graph would run in neither engine, so it is never offered.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import gc
|
||||
import hashlib
|
||||
import json
|
||||
import os
|
||||
import re
|
||||
import shutil
|
||||
import threading
|
||||
import time
|
||||
from typing import Any, Callable, Optional
|
||||
|
||||
from loggers import get_logger
|
||||
|
||||
logger = get_logger(__name__)
|
||||
|
||||
DRAFTER_MANIFEST = "drafter.json"
|
||||
EAGLE3_DIRNAME = "eagle3"
|
||||
MTP_HEAD_FILE = "mtp_head.safetensors"
|
||||
# The MTP head is pretrained: at 1e-4, 600 answers made a fine-tuned Qwen3.5-2B's head draft worse than
|
||||
# stock in llama.cpp (acceptance 0.740 -> 0.655), at 2e-5 better (0.755). EAGLE-3 starts from scratch.
|
||||
DEFAULT_LR = {"mtp": 2e-5, "eagle3": 3e-4}
|
||||
|
||||
# Families vLLM serves with its MTP proposer (vllm/config/speculative.py, 0.31.0).
|
||||
_VLLM_MTP_FAMILIES = {
|
||||
"qwen3_5",
|
||||
"qwen3_next",
|
||||
"glm4_moe",
|
||||
"glm4_moe_lite",
|
||||
"deepseek_v3",
|
||||
"deepseek_v32",
|
||||
"glm_moe_dsa",
|
||||
"hy_v3",
|
||||
"nemotron_h",
|
||||
"step3p5",
|
||||
"exaone_moe",
|
||||
}
|
||||
# EAGLE-3 targets: vLLM `SupportsEagle3` models, and llama.cpp archs that expose layer inputs
|
||||
# (`t_layer_inp`; gemma3 / mistral3 do not). Used only when unsloth_zoo has no eagle3_supported().
|
||||
_EAGLE3_VLLM = {
|
||||
"llama",
|
||||
"mistral",
|
||||
"mistral3",
|
||||
"qwen2",
|
||||
"qwen3",
|
||||
"qwen3_moe",
|
||||
"qwen3_5_text",
|
||||
"qwen3_5_moe_text",
|
||||
"qwen3_next",
|
||||
"gemma4_text",
|
||||
"gpt_oss",
|
||||
"minimax_m2",
|
||||
"nemotron_h",
|
||||
}
|
||||
_EAGLE3_LLAMA_CPP = {
|
||||
"llama",
|
||||
"mistral",
|
||||
"qwen3",
|
||||
"qwen3_moe",
|
||||
"qwen3_5_text",
|
||||
"qwen3_5_moe_text",
|
||||
"qwen3_next",
|
||||
"gemma4_text",
|
||||
"gemma3n_text",
|
||||
"gpt_oss",
|
||||
"minimax_m2",
|
||||
"lfm2",
|
||||
"nemotron_h",
|
||||
}
|
||||
_QUANT_SUFFIX = re.compile(
|
||||
r"-(unsloth-)?bnb-4bit$|-(unsloth-)?(fp8|awq|gptq)(-int4)?$", re.IGNORECASE
|
||||
)
|
||||
|
||||
|
||||
def _adapter_base(model_name: str, hf_token = None) -> Optional[str]:
|
||||
"""The base a LoRA adapter (local folder or Hub repo) was trained on; None for a plain model."""
|
||||
try:
|
||||
from utils.models.model_config import get_base_model_from_lora_identifier
|
||||
return get_base_model_from_lora_identifier(model_name, hf_token = hf_token)
|
||||
except Exception as exc:
|
||||
logger.debug("Adapter base lookup failed for %s: %s", model_name, exc)
|
||||
adapter_config = os.path.join(model_name or "", "adapter_config.json")
|
||||
if model_name and os.path.isfile(adapter_config):
|
||||
try:
|
||||
with open(adapter_config, encoding = "utf-8") as f:
|
||||
return json.load(f).get("base_model_name_or_path")
|
||||
except (OSError, ValueError):
|
||||
pass
|
||||
return None
|
||||
|
||||
|
||||
def _text_config(model_name: str, hf_token: Optional[str] = None):
|
||||
from transformers import AutoConfig
|
||||
|
||||
source = _adapter_base(model_name, hf_token) or model_name
|
||||
config = AutoConfig.from_pretrained(source, token = hf_token)
|
||||
return config.get_text_config() if hasattr(config, "get_text_config") else config, source
|
||||
|
||||
|
||||
def _mtp_source_candidates(source: str) -> list[str]:
|
||||
"""The checkpoint itself, then the original repo a quantized re-upload came from."""
|
||||
candidates = [source]
|
||||
stripped = _QUANT_SUFFIX.sub("", source)
|
||||
if stripped != source:
|
||||
candidates.append(stripped)
|
||||
return candidates
|
||||
|
||||
|
||||
def _find_mtp_source(
|
||||
source: str,
|
||||
config,
|
||||
repo_id: Optional[str] = None,
|
||||
) -> Optional[str]:
|
||||
"""`repo_id` is the model id when `source` is a pinned snapshot path, whose name has lost the
|
||||
quantized suffix the original-repo fallback strips."""
|
||||
from unsloth_zoo.speculative.mtp import find_mtp_tensor_names
|
||||
|
||||
candidates = _mtp_source_candidates(source)
|
||||
if repo_id and repo_id != source:
|
||||
candidates += [c for c in _mtp_source_candidates(repo_id) if c not in candidates]
|
||||
for candidate in candidates:
|
||||
try:
|
||||
if find_mtp_tensor_names(candidate, config = config):
|
||||
return candidate
|
||||
except Exception as exc: # unreadable index, offline, gated
|
||||
logger.debug("No MTP tensors readable from %s: %s", candidate, exc)
|
||||
return None
|
||||
|
||||
|
||||
def _mtp_family(config):
|
||||
try:
|
||||
from unsloth_zoo.speculative.mtp import mtp_family_name
|
||||
except ImportError:
|
||||
return None, None
|
||||
name = mtp_family_name(config)
|
||||
if name is None:
|
||||
return None, None
|
||||
status = "drafts"
|
||||
if name != "qwen3_5":
|
||||
from unsloth_zoo.speculative.mtp_families import MTP_FAMILIES
|
||||
family = MTP_FAMILIES.get(name)
|
||||
status = getattr(family, "llama_cpp", "unverified")
|
||||
return name, status
|
||||
|
||||
|
||||
def eagle3_support(config) -> tuple[bool, bool, Optional[str]]:
|
||||
"""(vllm, llama_cpp, reason) for an EAGLE-3 drafter on this target."""
|
||||
try:
|
||||
from unsloth_zoo.speculative import eagle3_supported
|
||||
except ImportError:
|
||||
eagle3_supported = None
|
||||
model_type = getattr(config, "model_type", None)
|
||||
vllm = model_type in _EAGLE3_VLLM
|
||||
llama_cpp = model_type in _EAGLE3_LLAMA_CPP
|
||||
if eagle3_supported is not None:
|
||||
ok, reason = eagle3_supported(config)
|
||||
if not ok:
|
||||
return False, False, reason
|
||||
if not (vllm or llama_cpp):
|
||||
return False, False, f"`{model_type}` has no EAGLE-3 drafter support in vLLM or llama.cpp."
|
||||
return vllm, llama_cpp, None
|
||||
|
||||
|
||||
_CAPABILITY_CACHE: dict = {}
|
||||
_CAPABILITY_TTL_S = 600
|
||||
_TOKEN_ENV = "UNSLOTH_DRAFTER_PROBE_TOKEN"
|
||||
_PROBE = """
|
||||
import json, os, sys
|
||||
os.environ.setdefault("UNSLOTH_IS_PRESENT", "1")
|
||||
sys.path.insert(0, os.getcwd())
|
||||
token = os.environ.pop({env!r}, "")
|
||||
token = False if token == "0" else (token or None)
|
||||
from core.training.drafter import capability_in_process
|
||||
print("DRAFTER_CAPABILITY " + json.dumps(capability_in_process(sys.argv[1], token)))
|
||||
"""
|
||||
|
||||
|
||||
_PROBE_SLOTS = threading.BoundedSemaphore(2)
|
||||
_PROBE_LOCKS: dict = {}
|
||||
_PROBE_LOCKS_GUARD = threading.Lock()
|
||||
|
||||
|
||||
def drafter_capability(model_name: str, hf_token = None) -> dict:
|
||||
"""The capability, probed in a child process: importing unsloth_zoo in the API server races its
|
||||
background torch warm-up (import deadlock in torch._dynamo) and patches the server process.
|
||||
One probe per key at a time (later callers wait for its cached answer), at most two at once."""
|
||||
# Keyed on the token itself: one caller's private-model answer is never served to another.
|
||||
token_key = hashlib.sha256(hf_token.encode()).hexdigest() if hf_token else hf_token
|
||||
key = (model_name, token_key)
|
||||
with _PROBE_LOCKS_GUARD:
|
||||
lock = _PROBE_LOCKS.setdefault(key, threading.Lock())
|
||||
with lock:
|
||||
hit = _CAPABILITY_CACHE.get(key)
|
||||
if hit and time.time() - hit[0] < _CAPABILITY_TTL_S:
|
||||
return dict(hit[1])
|
||||
with _PROBE_SLOTS:
|
||||
return _probe_capability(model_name, hf_token, key)
|
||||
|
||||
|
||||
def _probe_capability(model_name: str, hf_token, key) -> dict:
|
||||
import subprocess
|
||||
import sys
|
||||
|
||||
from hub.utils.hf_tokens import apply_token_to_child_env
|
||||
|
||||
env = dict(os.environ)
|
||||
env[_TOKEN_ENV] = "0" if hf_token is False else (hf_token or "")
|
||||
# Every Hub read in the child (config, tensor index) then runs as exactly this caller.
|
||||
apply_token_to_child_env(env, hf_token)
|
||||
result = None
|
||||
try:
|
||||
proc = subprocess.run(
|
||||
[sys.executable, "-c", _PROBE.format(env = _TOKEN_ENV), model_name],
|
||||
cwd = os.path.dirname(os.path.dirname(os.path.dirname(os.path.abspath(__file__)))),
|
||||
env = env,
|
||||
capture_output = True,
|
||||
text = True,
|
||||
timeout = 300,
|
||||
)
|
||||
for line in proc.stdout.splitlines():
|
||||
if line.startswith("DRAFTER_CAPABILITY "):
|
||||
result = json.loads(line[len("DRAFTER_CAPABILITY ") :])
|
||||
if result is None:
|
||||
logger.warning("Drafter capability probe failed: %s", (proc.stderr or "")[-2000:])
|
||||
except (OSError, subprocess.SubprocessError, ValueError) as exc:
|
||||
logger.warning("Drafter capability probe failed: %r", exc)
|
||||
if result is None:
|
||||
return {
|
||||
"model_name": model_name,
|
||||
"has_native_mtp": False,
|
||||
"strategy": None,
|
||||
"supported": False,
|
||||
"reason": "Could not check this model for drafter support.",
|
||||
"vllm": False,
|
||||
"llama_cpp": False,
|
||||
# Not an answer about the model: the Train tab asks again.
|
||||
"inconclusive": True,
|
||||
}
|
||||
_CAPABILITY_CACHE[key] = (time.time(), result)
|
||||
return dict(result)
|
||||
|
||||
|
||||
def capability_in_process(
|
||||
model_name: str,
|
||||
hf_token: Optional[str] = None,
|
||||
repo_id: Optional[str] = None,
|
||||
) -> dict:
|
||||
"""What the Train tab can offer for this model. Head presence comes from the checkpoint's tensor index."""
|
||||
result = {
|
||||
"model_name": model_name,
|
||||
"has_native_mtp": False,
|
||||
"strategy": None,
|
||||
"supported": False,
|
||||
"reason": None,
|
||||
"vllm": False,
|
||||
"llama_cpp": False,
|
||||
}
|
||||
try:
|
||||
import unsloth_zoo.speculative.eagle3 # noqa: F401
|
||||
import unsloth_zoo.speculative.mtp # noqa: F401
|
||||
except ImportError as exc:
|
||||
# An older unsloth_zoo would also misread a native-MTP model as EAGLE-3-only.
|
||||
logger.warning("Drafter trainers unavailable: %r", exc)
|
||||
result["reason"] = (
|
||||
f"Drafter training needs a newer unsloth_zoo (pip install -U unsloth_zoo): {exc}"
|
||||
)[:400]
|
||||
return result
|
||||
try:
|
||||
config, source = _text_config(model_name, hf_token)
|
||||
except Exception as exc:
|
||||
result["reason"] = f"Could not read the model config: {exc}"
|
||||
return result
|
||||
family, status = _mtp_family(config)
|
||||
mtp_source = _find_mtp_source(source, config, repo_id) if family is not None else None
|
||||
if mtp_source is not None:
|
||||
result.update(
|
||||
has_native_mtp = True,
|
||||
strategy = "mtp",
|
||||
supported = True,
|
||||
vllm = family in _VLLM_MTP_FAMILIES,
|
||||
llama_cpp = status in ("drafts", "partial"),
|
||||
)
|
||||
if not result["llama_cpp"]:
|
||||
result["reason"] = "llama.cpp cannot draft with this model's MTP head yet; vLLM can."
|
||||
return result
|
||||
vllm, llama_cpp, reason = eagle3_support(config)
|
||||
if vllm or llama_cpp:
|
||||
result.update(strategy = "eagle3", supported = True, vllm = vllm, llama_cpp = llama_cpp)
|
||||
if not llama_cpp:
|
||||
result["reason"] = "llama.cpp cannot run an EAGLE-3 drafter for this model; vLLM can."
|
||||
elif not vllm:
|
||||
result["reason"] = "vLLM cannot run an EAGLE-3 drafter for this model; llama.cpp can."
|
||||
return result
|
||||
result["reason"] = reason
|
||||
return result
|
||||
|
||||
|
||||
def resolve_strategy(requested: str, capability: dict) -> tuple[Optional[str], Optional[str]]:
|
||||
"""(strategy, refusal reason)."""
|
||||
if not capability.get("supported"):
|
||||
return None, capability.get("reason") or "No drafter is available for this model."
|
||||
if requested in (None, "auto"):
|
||||
return capability["strategy"], None
|
||||
if requested == "mtp" and not capability.get("has_native_mtp"):
|
||||
return None, "This model has no native MTP head; use EAGLE-3."
|
||||
if requested == "eagle3" and capability.get("strategy") != "eagle3":
|
||||
# A native-MTP model can still take an EAGLE-3 drafter when the target supports it.
|
||||
return None, "This model trains its native MTP head; EAGLE-3 is for models without one."
|
||||
return requested, None
|
||||
|
||||
|
||||
# ---------------------------------------------------------------- examples
|
||||
|
||||
|
||||
def _row_examples(row: dict, max_len: int) -> list[tuple[list[int], list[int]]]:
|
||||
ids = list(row["input_ids"])
|
||||
if "labels" in row and row["labels"] is not None:
|
||||
labels = list(row["labels"])
|
||||
elif row.get("completion_mask") is not None:
|
||||
labels = [t if m else -100 for t, m in zip(ids, row["completion_mask"])]
|
||||
elif row.get("assistant_masks") is not None:
|
||||
labels = [t if m else -100 for t, m in zip(ids, row["assistant_masks"])]
|
||||
else:
|
||||
labels = list(ids)
|
||||
# Packed rows restart position_ids at every example; split there so no draft crosses a boundary.
|
||||
positions = row.get("position_ids")
|
||||
cuts = [0]
|
||||
if positions is not None:
|
||||
cuts = [i for i, p in enumerate(positions) if p == 0] or [0]
|
||||
cuts.append(len(ids))
|
||||
out = []
|
||||
for start, end in zip(cuts, cuts[1:]):
|
||||
seg_ids, seg_labels = ids[start:end][:max_len], labels[start:end][:max_len]
|
||||
if len(seg_ids) >= 4 and any(t != -100 for t in seg_labels):
|
||||
out.append((seg_ids, seg_labels))
|
||||
return out
|
||||
|
||||
|
||||
def collect_examples(train_dataset, max_examples: int, max_len: int) -> list[dict]:
|
||||
examples = []
|
||||
for row in train_dataset:
|
||||
for ids, labels in _row_examples(row, max_len):
|
||||
examples.append({"input_ids": ids, "labels": labels})
|
||||
if len(examples) >= max_examples:
|
||||
return examples
|
||||
return examples
|
||||
|
||||
|
||||
def _assistant_header(tokenizer) -> list[int]:
|
||||
"""Token ids the chat template puts between a user turn and the answer ("<|im_start|>assistant\n", ...)."""
|
||||
text_tokenizer = getattr(tokenizer, "tokenizer", tokenizer)
|
||||
turn = [{"role": "user", "content": "x"}]
|
||||
try:
|
||||
with_prompt = tokenizer.apply_chat_template(
|
||||
turn, add_generation_prompt = True, tokenize = False
|
||||
)
|
||||
without = tokenizer.apply_chat_template(turn, add_generation_prompt = False, tokenize = False)
|
||||
except Exception:
|
||||
return []
|
||||
if not with_prompt.startswith(without):
|
||||
return []
|
||||
return text_tokenizer(with_prompt[len(without) :], add_special_tokens = False)["input_ids"]
|
||||
|
||||
|
||||
def _response_markers(tokenizer) -> list[list[int]]:
|
||||
"""Token ids that can open an answer: the chat template's assistant header, then every response
|
||||
marker Studio's completion masking knows (rows rendered with a dataset template such as Alpaca's
|
||||
"### Response:" carry no chat header)."""
|
||||
text_tokenizer = getattr(tokenizer, "tokenizer", tokenizer)
|
||||
markers = []
|
||||
header = _assistant_header(tokenizer)
|
||||
if header:
|
||||
markers.append(header)
|
||||
try:
|
||||
from utils.datasets.model_mappings import TEMPLATE_TO_RESPONSES_MAPPER
|
||||
texts = {
|
||||
m.get("response") for m in TEMPLATE_TO_RESPONSES_MAPPER.values() if isinstance(m, dict)
|
||||
}
|
||||
except Exception:
|
||||
texts = set()
|
||||
for text in sorted(t for t in texts if isinstance(t, str) and t.strip()):
|
||||
try:
|
||||
ids = text_tokenizer(text, add_special_tokens = False)["input_ids"]
|
||||
except Exception:
|
||||
continue
|
||||
if ids and ids not in markers:
|
||||
markers.append(ids)
|
||||
return markers
|
||||
|
||||
|
||||
def _marker_end(ids: list[int], marker: list[int]) -> Optional[int]:
|
||||
"""End of the marker's last occurrence; shorter prefixes cover a marker whose tail tokenizes into
|
||||
the answer, or a template that adds a thinking block after the header."""
|
||||
for width in range(len(marker), 0, -1):
|
||||
part = marker[:width]
|
||||
for start in range(len(ids) - width, 0, -1):
|
||||
if ids[start : start + width] == part:
|
||||
return start + width
|
||||
if width <= 2:
|
||||
break
|
||||
return None
|
||||
|
||||
|
||||
def _prompt_end(ids: list[int], labels: list[int], markers) -> Optional[int]:
|
||||
"""Where the answer starts: the first trained label, or (rows trained on the whole sequence) after
|
||||
the last response marker found."""
|
||||
first = next((i for i, t in enumerate(labels) if t != -100), None)
|
||||
if first:
|
||||
return first
|
||||
if markers and isinstance(markers[0], int):
|
||||
markers = [markers]
|
||||
ends = [e for e in (_marker_end(ids, m) for m in markers or []) if e and e < len(ids)]
|
||||
return max(ends) if ends else None
|
||||
|
||||
|
||||
def regenerate_examples(
|
||||
model,
|
||||
tokenizer,
|
||||
examples: list[dict],
|
||||
max_new_tokens: int = 512,
|
||||
batch_size: int = 8,
|
||||
should_stop: Callable[[], bool] = lambda: False,
|
||||
max_seq_length: Optional[int] = None,
|
||||
) -> list[dict]:
|
||||
"""The fine-tuned model's own greedy answers to each example's prompt (the drafter imitates the model);
|
||||
prompt + answer stays within `max_seq_length`."""
|
||||
import torch
|
||||
|
||||
text_tokenizer = getattr(tokenizer, "tokenizer", tokenizer)
|
||||
pad_id = text_tokenizer.pad_token_id
|
||||
if pad_id is None:
|
||||
pad_id = text_tokenizer.eos_token_id
|
||||
eos_id = text_tokenizer.eos_token_id
|
||||
markers = _response_markers(tokenizer)
|
||||
prompts = []
|
||||
for ex in examples:
|
||||
end = _prompt_end(ex["input_ids"], ex["labels"], markers)
|
||||
if end and (
|
||||
max_seq_length is None or end < max_seq_length
|
||||
): # needs a prompt and room to answer
|
||||
prompts.append(ex["input_ids"][:end])
|
||||
out = []
|
||||
device = next(model.parameters()).device
|
||||
for b in range(0, len(prompts), batch_size):
|
||||
if should_stop():
|
||||
break
|
||||
batch = prompts[b : b + batch_size]
|
||||
width = max(map(len, batch))
|
||||
new_tokens = (
|
||||
max_new_tokens
|
||||
if max_seq_length is None
|
||||
else min(max_new_tokens, max_seq_length - width)
|
||||
)
|
||||
ids = torch.tensor([[pad_id] * (width - len(p)) + p for p in batch], device = device)
|
||||
mask = torch.tensor([[0] * (width - len(p)) + [1] * len(p) for p in batch], device = device)
|
||||
with torch.no_grad():
|
||||
gen = model.generate(
|
||||
input_ids = ids,
|
||||
attention_mask = mask,
|
||||
max_new_tokens = new_tokens,
|
||||
do_sample = False,
|
||||
pad_token_id = pad_id,
|
||||
)
|
||||
for prompt, row in zip(batch, gen[:, width:].tolist()):
|
||||
if eos_id in row:
|
||||
row = row[: row.index(eos_id) + 1]
|
||||
row = [t for t in row if t != pad_id or t == eos_id]
|
||||
if row:
|
||||
out.append({"input_ids": prompt + row, "labels": [-100] * len(prompt) + row})
|
||||
return out
|
||||
|
||||
|
||||
# ---------------------------------------------------------------- phase
|
||||
|
||||
|
||||
def _progress_callback(event_queue, strategy: str, should_stop: Callable[[], bool]):
|
||||
from transformers import TrainerCallback
|
||||
class _DrafterProgress(TrainerCallback):
|
||||
def _emit(
|
||||
self,
|
||||
state,
|
||||
logs = None,
|
||||
):
|
||||
logs = logs or {}
|
||||
loss = logs.get("loss", logs.get("mtp_loss_0"))
|
||||
top1 = logs.get(
|
||||
"mtp_top1_0", logs.get("eagle3_acc_0", logs.get("top1", logs.get("acc_0")))
|
||||
)
|
||||
event_queue.put(
|
||||
{
|
||||
"type": "drafter_progress",
|
||||
"strategy": strategy,
|
||||
"step": state.global_step,
|
||||
"total_steps": state.max_steps,
|
||||
"loss": loss,
|
||||
"top1": top1,
|
||||
"state": "training",
|
||||
"ts": time.time(),
|
||||
}
|
||||
)
|
||||
event_queue.put(
|
||||
{
|
||||
"type": "status",
|
||||
"ts": time.time(),
|
||||
"message": f"Training drafter ({_LABEL[strategy]}): step {state.global_step}/{state.max_steps}",
|
||||
}
|
||||
)
|
||||
|
||||
def on_train_begin(self, args, state, control, **kwargs):
|
||||
self._emit(state)
|
||||
|
||||
def on_log(
|
||||
self,
|
||||
args,
|
||||
state,
|
||||
control,
|
||||
logs = None,
|
||||
**kwargs,
|
||||
):
|
||||
self._emit(state, logs)
|
||||
|
||||
def on_step_end(self, args, state, control, **kwargs):
|
||||
if should_stop():
|
||||
control.should_training_stop = True
|
||||
|
||||
return _DrafterProgress()
|
||||
|
||||
|
||||
_LABEL = {"mtp": "MTP head", "eagle3": "EAGLE-3"}
|
||||
|
||||
|
||||
def _training_args(cls, output_dir: str, cfg: dict, strategy: str, seed: int, extra: dict):
|
||||
import torch
|
||||
bf16 = bool(torch.cuda.is_available() and torch.cuda.is_bf16_supported())
|
||||
return cls(
|
||||
output_dir = output_dir,
|
||||
per_device_train_batch_size = 4,
|
||||
gradient_accumulation_steps = 1,
|
||||
num_train_epochs = float(cfg.get("epochs") or 1.0),
|
||||
learning_rate = float(cfg.get("learning_rate") or DEFAULT_LR[strategy]),
|
||||
lr_scheduler_type = "cosine",
|
||||
warmup_steps = 10,
|
||||
logging_steps = 5,
|
||||
save_strategy = "no",
|
||||
bf16 = bf16,
|
||||
fp16 = not bf16 and torch.cuda.is_available(),
|
||||
report_to = "none",
|
||||
seed = seed,
|
||||
weight_decay = 0.0,
|
||||
**extra,
|
||||
)
|
||||
|
||||
|
||||
def _free_sft_trainer(trainer) -> Any:
|
||||
"""Drop the SFT optimizer / scheduler / dataloaders; return the train dataset."""
|
||||
sft = getattr(trainer, "trainer", None)
|
||||
dataset = getattr(sft, "train_dataset", None)
|
||||
if sft is not None:
|
||||
for attr in ("optimizer", "lr_scheduler", "train_dataset", "eval_dataset"):
|
||||
try:
|
||||
setattr(sft, attr, None)
|
||||
except Exception:
|
||||
pass
|
||||
trainer.trainer = None
|
||||
gc.collect()
|
||||
try:
|
||||
import torch
|
||||
if torch.cuda.is_available():
|
||||
torch.cuda.empty_cache()
|
||||
except Exception:
|
||||
pass
|
||||
return dataset
|
||||
|
||||
|
||||
def write_manifest(output_dir: str, manifest: dict) -> str:
|
||||
path = os.path.join(output_dir, DRAFTER_MANIFEST)
|
||||
tmp = path + ".tmp"
|
||||
with open(tmp, "w", encoding = "utf-8") as f:
|
||||
json.dump(manifest, f, indent = 1)
|
||||
os.replace(tmp, path)
|
||||
return path
|
||||
|
||||
|
||||
def read_manifest(directory: Optional[str]) -> Optional[dict]:
|
||||
if not directory:
|
||||
return None
|
||||
path = os.path.join(directory, DRAFTER_MANIFEST)
|
||||
try:
|
||||
with open(path, encoding = "utf-8") as f:
|
||||
data = json.load(f)
|
||||
except (OSError, ValueError):
|
||||
return None
|
||||
return data if isinstance(data, dict) and data.get("strategy") in ("mtp", "eagle3") else None
|
||||
|
||||
|
||||
def run_drafter_phase(
|
||||
trainer, config: dict, output_dir: str, event_queue, send_status: Callable[[Any, str], None]
|
||||
) -> Optional[dict]:
|
||||
"""Train the drafter after a successful fine-tune. Never raises: a failure is a warning and the
|
||||
fine-tune stays saved. Returns the manifest written, or None."""
|
||||
cfg = config.get("drafter") or {}
|
||||
if not cfg.get("enabled"):
|
||||
return None
|
||||
should_stop = lambda: bool(getattr(trainer, "should_stop", False))
|
||||
strategy = None
|
||||
eagle_dir = os.path.join(output_dir, EAGLE3_DIRNAME)
|
||||
try:
|
||||
if getattr(trainer, "is_vlm", False) or getattr(trainer, "is_audio_vlm", False):
|
||||
raise RuntimeError(
|
||||
"drafter training is not available for vision or audio fine-tunes yet"
|
||||
)
|
||||
model, tokenizer = trainer.model, trainer.tokenizer
|
||||
model_name = config.get("model_name") or getattr(trainer, "model_name", "")
|
||||
text_config = _model_text_config(model)
|
||||
family, status = _mtp_family(text_config)
|
||||
# The checkpoint this run actually loaded (a pinned snapshot), under the caller's token.
|
||||
probe_target = config.get("model_snapshot_path") or model_name
|
||||
capability = (
|
||||
capability_in_process(probe_target, config.get("hf_token"), repo_id = model_name)
|
||||
if probe_target
|
||||
else {}
|
||||
)
|
||||
strategy, refusal = resolve_strategy(cfg.get("strategy", "auto"), capability)
|
||||
if strategy is None:
|
||||
raise RuntimeError(refusal)
|
||||
send_status(event_queue, f"Training drafter ({_LABEL[strategy]}): preparing examples")
|
||||
max_len = int(config.get("max_seq_length") or 2048)
|
||||
dataset = _free_sft_trainer(trainer)
|
||||
if dataset is None:
|
||||
raise RuntimeError("the fine-tune's training examples are not available")
|
||||
examples = collect_examples(dataset, int(cfg.get("max_examples") or 2000), max_len)
|
||||
del dataset
|
||||
model.eval()
|
||||
for p in model.parameters():
|
||||
p.requires_grad_(False)
|
||||
data_source = "dataset"
|
||||
if cfg.get("data_source") == "regenerate":
|
||||
markers = _response_markers(tokenizer)
|
||||
found = sum(
|
||||
bool(_prompt_end(ex["input_ids"], ex["labels"], markers)) for ex in examples
|
||||
)
|
||||
if not found and examples:
|
||||
logger.warning(
|
||||
"Drafter regenerate found no prompts: markers=%s first row ids=%s labels=%s",
|
||||
markers,
|
||||
examples[0]["input_ids"][:48],
|
||||
examples[0]["labels"][:48],
|
||||
)
|
||||
send_status(
|
||||
event_queue,
|
||||
f"Training drafter ({_LABEL[strategy]}): generating the model's answers to {found} prompts",
|
||||
)
|
||||
regenerated = regenerate_examples(
|
||||
model, tokenizer, examples, should_stop = should_stop, max_seq_length = max_len
|
||||
)
|
||||
if regenerated:
|
||||
examples = regenerated
|
||||
data_source = "regenerate"
|
||||
else:
|
||||
send_status(
|
||||
event_queue,
|
||||
f"Training drafter ({_LABEL[strategy]}): no prompts found to answer, using the dataset's answers",
|
||||
)
|
||||
if not examples:
|
||||
raise RuntimeError("no usable training examples")
|
||||
if should_stop():
|
||||
# A reused folder may still hold a previous run's drafter.
|
||||
_discard(output_dir, strategy, model = model)
|
||||
return None
|
||||
from datasets import Dataset
|
||||
|
||||
train_dataset = Dataset.from_list(examples)
|
||||
seed = int(config.get("random_seed") or 3407)
|
||||
steps = int(cfg.get("draft_steps") or 3)
|
||||
ckpt_dir = os.path.join(output_dir, "drafter_tmp")
|
||||
callback = _progress_callback(event_queue, strategy, should_stop)
|
||||
if strategy == "mtp":
|
||||
from unsloth import FastModel, MTPTrainingArguments, UnslothMTPTrainer
|
||||
|
||||
# The pinned snapshot this run loaded, not the repo's default branch.
|
||||
source = _find_mtp_source(
|
||||
capability_source(probe_target, config),
|
||||
text_config,
|
||||
capability_source(model_name, config) if model_name else None,
|
||||
)
|
||||
head = FastModel.get_mtp_head(model, source = source, random_init = source is None)
|
||||
args = _training_args(
|
||||
MTPTrainingArguments, ckpt_dir, cfg, strategy, seed, {"mtp_num_steps": steps}
|
||||
)
|
||||
drafter_trainer = UnslothMTPTrainer(
|
||||
model = head,
|
||||
target_model = model,
|
||||
args = args,
|
||||
train_dataset = train_dataset,
|
||||
processing_class = tokenizer,
|
||||
)
|
||||
else:
|
||||
from unsloth_zoo.speculative import (
|
||||
Eagle3TrainingArguments,
|
||||
UnslothEagle3Trainer,
|
||||
build_eagle3_drafter,
|
||||
build_eagle3_vocab_map,
|
||||
)
|
||||
|
||||
vocab = int(getattr(text_config, "vocab_size"))
|
||||
d2t, t2d = build_eagle3_vocab_map(
|
||||
[e["input_ids"] for e in examples], vocab, draft_vocab_size = min(32000, vocab)
|
||||
)
|
||||
head = build_eagle3_drafter(model, d2t, t2d)
|
||||
args = _training_args(Eagle3TrainingArguments, ckpt_dir, cfg, strategy, seed, {})
|
||||
drafter_trainer = UnslothEagle3Trainer(
|
||||
model = head,
|
||||
target_model = model,
|
||||
args = args,
|
||||
train_dataset = train_dataset,
|
||||
processing_class = tokenizer,
|
||||
)
|
||||
drafter_trainer.add_callback(callback)
|
||||
result = drafter_trainer.train()
|
||||
shutil.rmtree(ckpt_dir, ignore_errors = True)
|
||||
if should_stop():
|
||||
# Stop during this phase keeps the fine-tune and drops only the drafter.
|
||||
_discard(output_dir, strategy, head = head, model = model)
|
||||
return None
|
||||
send_status(event_queue, f"Training drafter ({_LABEL[strategy]}): saving")
|
||||
metrics = {
|
||||
k: v
|
||||
for k, v in (getattr(result, "metrics", None) or {}).items()
|
||||
if isinstance(v, (int, float))
|
||||
}
|
||||
history = [h for h in drafter_trainer.state.log_history if isinstance(h, dict)]
|
||||
for entry in reversed(history):
|
||||
for key, value in entry.items():
|
||||
if (
|
||||
key.startswith(
|
||||
("mtp_top1_", "mtp_loss_", "eagle3_acc_", "eagle3_loss_", "acc_", "top1")
|
||||
)
|
||||
and key not in metrics
|
||||
):
|
||||
metrics[key] = value
|
||||
base_model = capability_source(model_name, config)
|
||||
manifest = {
|
||||
"version": 1,
|
||||
"strategy": strategy,
|
||||
"base_model": base_model,
|
||||
"adapter_dir": output_dir,
|
||||
"draft_steps": steps,
|
||||
"examples": len(examples),
|
||||
"data_source": data_source,
|
||||
"metrics": metrics,
|
||||
"created_at": time.strftime("%Y-%m-%dT%H:%M:%SZ", time.gmtime()),
|
||||
# Which engines can run this drafter: exports and launchers only enable it there.
|
||||
"engines": {
|
||||
"vllm": bool(capability.get("vllm")),
|
||||
"llama_cpp": bool(capability.get("llama_cpp")),
|
||||
},
|
||||
}
|
||||
if should_stop():
|
||||
_discard(output_dir, strategy, head = head, model = model)
|
||||
return None
|
||||
if strategy == "mtp":
|
||||
from unsloth.save import _save_mtp_head_beside_adapter, _stitch_mtp_head
|
||||
if os.path.isfile(os.path.join(output_dir, "adapter_config.json")):
|
||||
_save_mtp_head_beside_adapter(model, output_dir)
|
||||
manifest["files"] = [MTP_HEAD_FILE]
|
||||
else:
|
||||
_stitch_mtp_head(model, output_dir)
|
||||
manifest["files"] = []
|
||||
manifest.update(
|
||||
family = family,
|
||||
llama_cpp_status = status,
|
||||
vllm = {"method": "mtp", "num_speculative_tokens": steps},
|
||||
llama_cpp = {"spec_type": "draft-mtp", "spec_draft_n_max": steps},
|
||||
)
|
||||
else:
|
||||
from unsloth_zoo.speculative import save_eagle3_drafter
|
||||
|
||||
shutil.rmtree(eagle_dir, ignore_errors = True)
|
||||
save_eagle3_drafter(
|
||||
eagle_dir, head, verifier_name_or_path = base_model, speculative_tokens = steps
|
||||
)
|
||||
manifest["files"] = [EAGLE3_DIRNAME]
|
||||
manifest["aux_layer_ids"] = list(getattr(head, "aux_layer_ids", None) or [])
|
||||
manifest.update(
|
||||
vllm = {"method": "eagle3", "num_speculative_tokens": steps},
|
||||
llama_cpp = {"spec_type": "draft-eagle3", "spec_draft_n_max": steps},
|
||||
)
|
||||
if should_stop() and manifest["files"]:
|
||||
# Stop pressed while saving: still drop the drafter, before any manifest names it. A head
|
||||
# already stitched into a full fine-tune's shards cannot be dropped, so it stays recorded.
|
||||
_discard(output_dir, strategy, head = head, model = model)
|
||||
return None
|
||||
write_manifest(output_dir, manifest)
|
||||
event_queue.put(
|
||||
{
|
||||
"type": "drafter_progress",
|
||||
"strategy": strategy,
|
||||
"step": None,
|
||||
"total_steps": None,
|
||||
"loss": metrics.get("train_loss"),
|
||||
"top1": metrics.get("mtp_top1_0", metrics.get("eagle3_acc_0")),
|
||||
"state": "done",
|
||||
"ts": time.time(),
|
||||
}
|
||||
)
|
||||
return manifest
|
||||
except Exception as exc:
|
||||
logger.warning("Drafter training failed: %s", exc, exc_info = True)
|
||||
_discard(output_dir, strategy)
|
||||
event_queue.put(
|
||||
{
|
||||
"type": "warning",
|
||||
"ts": time.time(),
|
||||
"message": f"Drafter training failed, the fine-tuned model is saved without it: {exc}",
|
||||
}
|
||||
)
|
||||
event_queue.put(
|
||||
{
|
||||
"type": "drafter_progress",
|
||||
"strategy": strategy,
|
||||
"step": None,
|
||||
"total_steps": None,
|
||||
"loss": None,
|
||||
"top1": None,
|
||||
"state": "failed",
|
||||
"ts": time.time(),
|
||||
}
|
||||
)
|
||||
return None
|
||||
finally:
|
||||
gc.collect()
|
||||
|
||||
|
||||
def capability_source(model_name: str, config: dict) -> str:
|
||||
"""The base checkpoint id (a local or Hub adapter resolves to its base)."""
|
||||
if not model_name:
|
||||
return model_name
|
||||
return _adapter_base(model_name, config.get("hf_token")) or model_name
|
||||
|
||||
|
||||
def _model_text_config(model):
|
||||
config = getattr(model, "config", None)
|
||||
if config is None:
|
||||
return None
|
||||
return config.get_text_config() if hasattr(config, "get_text_config") else config
|
||||
|
||||
|
||||
def discard_drafter_artifacts(output_dir: str) -> None:
|
||||
"""A run that will not train a drafter must not leave a previous run's in a reused folder."""
|
||||
if output_dir and os.path.isfile(os.path.join(output_dir, DRAFTER_MANIFEST)):
|
||||
_discard(output_dir, None)
|
||||
|
||||
|
||||
def _discard(
|
||||
output_dir: str,
|
||||
strategy: Optional[str],
|
||||
head = None,
|
||||
model = None,
|
||||
) -> None:
|
||||
"""Remove anything this phase may have written; the fine-tune itself is untouched."""
|
||||
if model is not None:
|
||||
try:
|
||||
object.__delattr__(model, "_unsloth_mtp_head")
|
||||
except AttributeError:
|
||||
pass
|
||||
for name in (EAGLE3_DIRNAME, "drafter_tmp", DRAFTER_MANIFEST, MTP_HEAD_FILE):
|
||||
path = os.path.join(output_dir, name)
|
||||
if os.path.isdir(path):
|
||||
shutil.rmtree(path, ignore_errors = True)
|
||||
elif os.path.isfile(path):
|
||||
os.remove(path)
|
||||
|
|
@ -262,6 +262,7 @@ def _build_training_worker_config(values: dict[str, Any]) -> dict[str, Any]:
|
|||
"eval_split": values.get("eval_split"),
|
||||
"eval_steps": values.get("eval_steps", 0.00),
|
||||
"early_stopping_patience": values.get("early_stopping_patience", 0),
|
||||
"drafter": values.get("drafter"),
|
||||
"dataset_streaming": values.get("dataset_streaming", False),
|
||||
"dataset_slice_start": values.get("dataset_slice_start"),
|
||||
"dataset_slice_end": values.get("dataset_slice_end"),
|
||||
|
|
@ -711,6 +712,9 @@ class TrainingProgress:
|
|||
# The end-of-run record has no step loss, so the progress filter would drop it, and with it the only
|
||||
# elapsed time that includes the final evaluation, checkpoint save and best-model reload.
|
||||
is_run_summary: bool = False
|
||||
# Drafter phase after the fine-tune: {strategy, step, total_steps, loss, top1, state}. Kept apart
|
||||
# from the SFT fields so its step counter never lands in the SFT loss history.
|
||||
drafter: Optional[dict] = None
|
||||
|
||||
|
||||
# Marks an omitted mode, which keeps the loaded one; a literal default would overwrite it.
|
||||
|
|
@ -3304,6 +3308,14 @@ class TrainingBackend:
|
|||
self._progress.status_message = event.get("message", "")
|
||||
self._progress.is_training = True
|
||||
|
||||
elif etype == "drafter_progress":
|
||||
info = {
|
||||
k: event.get(k)
|
||||
for k in ("strategy", "step", "total_steps", "loss", "top1", "state")
|
||||
}
|
||||
self._progress.drafter = info
|
||||
self._progress.is_training = True
|
||||
|
||||
elif etype == "warning":
|
||||
message = event.get("message")
|
||||
if isinstance(message, str):
|
||||
|
|
|
|||
|
|
@ -5144,6 +5144,20 @@ def run_training_process(*, event_queue: Any, stop_queue: Any, config: dict) ->
|
|||
_tqdm_stop.set()
|
||||
|
||||
progress = trainer.get_training_progress()
|
||||
drafter_note = ""
|
||||
# A Stop during the drafter phase drops only the drafter; the fine-tune is already saved.
|
||||
stopped_in_training = trainer.should_stop
|
||||
if config.get("drafter") and not progress.error and not trainer.should_stop:
|
||||
from core.training.drafter import run_drafter_phase
|
||||
|
||||
manifest = run_drafter_phase(trainer, config, output_dir, event_queue, _send_status)
|
||||
if manifest is not None:
|
||||
label = "MTP head" if manifest["strategy"] == "mtp" else "EAGLE-3 drafter"
|
||||
drafter_note = f"\nTrained {label} saved with the model."
|
||||
progress = trainer.get_training_progress()
|
||||
elif output_dir:
|
||||
from core.training.drafter import discard_drafter_artifacts
|
||||
discard_drafter_artifacts(output_dir)
|
||||
if progress.error:
|
||||
event_queue.put(
|
||||
{
|
||||
|
|
@ -5155,13 +5169,14 @@ def run_training_process(*, event_queue: Any, stop_queue: Any, config: dict) ->
|
|||
)
|
||||
else:
|
||||
saved_output_dir = (
|
||||
None if trainer.should_stop and not trainer.save_on_stop else output_dir
|
||||
None if stopped_in_training and not trainer.save_on_stop else output_dir
|
||||
)
|
||||
event_queue.put(
|
||||
{
|
||||
"type": "complete",
|
||||
"output_dir": saved_output_dir,
|
||||
"status_message": progress.status_message or "Training completed",
|
||||
"status_message": (progress.status_message or "Training completed")
|
||||
+ drafter_note,
|
||||
"ts": time.time(),
|
||||
}
|
||||
)
|
||||
|
|
|
|||
|
|
@ -117,6 +117,25 @@ def _resolve_inventory_handle(value: str) -> str:
|
|||
_CHECKPOINTING_OFF = ("false", "0", "no", "none", "off")
|
||||
|
||||
|
||||
class DrafterTrainingConfig(BaseModel):
|
||||
"""Optional speculative-decoding drafter trained after the fine-tune (omitted or disabled = off)."""
|
||||
|
||||
enabled: bool = False
|
||||
strategy: Literal["auto", "mtp", "eagle3"] = "auto"
|
||||
data_source: Literal["dataset", "regenerate"] = "dataset"
|
||||
max_examples: int = Field(2000, ge = 16, le = 100000)
|
||||
epochs: float = Field(1.0, ge = 0.1, le = 20)
|
||||
learning_rate: Optional[float] = Field(None, gt = 0, le = 1.0)
|
||||
draft_steps: int = Field(3, ge = 1, le = 8)
|
||||
|
||||
@field_validator("max_examples", "draft_steps", "epochs", mode = "before")
|
||||
@classmethod
|
||||
def _reject_booleans(cls, value: Any) -> Any:
|
||||
if isinstance(value, bool):
|
||||
raise ValueError("expected a number, not a boolean")
|
||||
return value
|
||||
|
||||
|
||||
class TrainingStartRequest(BaseModel):
|
||||
"""Request schema for starting training"""
|
||||
|
||||
|
|
@ -211,6 +230,10 @@ class TrainingStartRequest(BaseModel):
|
|||
le = 1000,
|
||||
description = "Stop after this many evaluations without a lower eval loss and keep the best weights. 0 = off",
|
||||
)
|
||||
drafter: Optional[DrafterTrainingConfig] = Field(
|
||||
None,
|
||||
description = "Train a speculative-decoding drafter (MTP head or EAGLE-3) after the fine-tune",
|
||||
)
|
||||
dataset_slice_start: Optional[int] = Field(
|
||||
None,
|
||||
ge = 0,
|
||||
|
|
@ -738,6 +761,17 @@ class TrainingStartRequest(BaseModel):
|
|||
)
|
||||
return self
|
||||
|
||||
@model_validator(mode = "after")
|
||||
def _validate_drafter(self) -> "TrainingStartRequest":
|
||||
drafter = getattr(self, "drafter", None)
|
||||
if drafter is None or not drafter.enabled:
|
||||
return self
|
||||
if getattr(self, "is_embedding", False) or getattr(self, "is_decision", False):
|
||||
raise ValueError("drafter training is only available for text generation models.")
|
||||
if getattr(self, "training_type", None) == "Continued Pretraining":
|
||||
raise ValueError("drafter training is not available for continued pretraining.")
|
||||
return self
|
||||
|
||||
|
||||
class TrainingJobResponse(BaseModel):
|
||||
"""Immediate response when training is initiated"""
|
||||
|
|
@ -774,6 +808,7 @@ class TrainingStatus(BaseModel):
|
|||
"loading_dataset",
|
||||
"configuring",
|
||||
"training",
|
||||
"training_drafter",
|
||||
"finalizing",
|
||||
"completed",
|
||||
"error",
|
||||
|
|
|
|||
|
|
@ -373,6 +373,20 @@ def _export_details(
|
|||
return {"output_path": output_path}
|
||||
|
||||
|
||||
def _with_drafter(
|
||||
details: Optional[Dict[str, Any]], output_path: Optional[str]
|
||||
) -> Optional[Dict[str, Any]]:
|
||||
"""Adds the trained drafter an export carries (drafter.json), when there is one."""
|
||||
try:
|
||||
from core.export.drafter_export import export_drafter_details
|
||||
drafter = export_drafter_details(output_path)
|
||||
except Exception:
|
||||
drafter = None
|
||||
if drafter is None or details is None:
|
||||
return details
|
||||
return {**details, "drafter": drafter}
|
||||
|
||||
|
||||
def _decision_export_details(output_path: Optional[str]) -> Optional[Dict[str, Any]]:
|
||||
"""A decision GGUF lands in the run folder's gguf/; not registered as a chat model folder."""
|
||||
if not output_path:
|
||||
|
|
@ -457,7 +471,10 @@ async def export_merged_model(
|
|||
return ExportOperationResponse(
|
||||
success = True,
|
||||
message = message,
|
||||
details = await asyncio.to_thread(_export_details, output_path, refresh_index = True),
|
||||
details = _with_drafter(
|
||||
await asyncio.to_thread(_export_details, output_path, refresh_index = True),
|
||||
output_path,
|
||||
),
|
||||
)
|
||||
except HTTPException:
|
||||
raise
|
||||
|
|
@ -518,7 +535,10 @@ async def export_base_model(
|
|||
return ExportOperationResponse(
|
||||
success = True,
|
||||
message = message,
|
||||
details = await asyncio.to_thread(_export_details, output_path, refresh_index = True),
|
||||
details = _with_drafter(
|
||||
await asyncio.to_thread(_export_details, output_path, refresh_index = True),
|
||||
output_path,
|
||||
),
|
||||
)
|
||||
except HTTPException:
|
||||
raise
|
||||
|
|
@ -574,7 +594,10 @@ async def export_gguf(
|
|||
if getattr(backend, "decision", None):
|
||||
details = await asyncio.to_thread(_decision_export_details, output_path)
|
||||
else:
|
||||
details = await asyncio.to_thread(_export_details, output_path, refresh_index = True)
|
||||
details = _with_drafter(
|
||||
await asyncio.to_thread(_export_details, output_path, refresh_index = True),
|
||||
output_path,
|
||||
)
|
||||
return ExportOperationResponse(success = True, message = message, details = details)
|
||||
except HTTPException:
|
||||
raise
|
||||
|
|
@ -732,7 +755,10 @@ async def export_lora_adapter(
|
|||
return ExportOperationResponse(
|
||||
success = True,
|
||||
message = message,
|
||||
details = await asyncio.to_thread(_export_details, output_path, refresh_index = True),
|
||||
details = _with_drafter(
|
||||
await asyncio.to_thread(_export_details, output_path, refresh_index = True),
|
||||
output_path,
|
||||
),
|
||||
)
|
||||
except HTTPException:
|
||||
raise
|
||||
|
|
|
|||
|
|
@ -13715,6 +13715,24 @@ def _estimate_gguf_required_gb(
|
|||
# guard admit a load that evicts the training run it protects.
|
||||
total_bytes += LlamaCppBackend._get_gguf_size_bytes(str(f))
|
||||
_sized_keys.add(_same_file_key(str(f)))
|
||||
# An EAGLE-3 drafter a Studio export paired with this GGUF (drafter.json): the
|
||||
# launch attaches it under Auto, so it is charged like the sidecars above.
|
||||
if main and not _charge_no_drafter and _spec_mode in ("auto", "eagle3"):
|
||||
try:
|
||||
from core.export.drafter_export import eagle3_sidecar_path
|
||||
_eagle3 = eagle3_sidecar_path(str(main))
|
||||
except Exception:
|
||||
_eagle3 = None
|
||||
# Like DSpark / DFlash: a binary without draft-eagle3 never opens it.
|
||||
if _eagle3:
|
||||
try:
|
||||
if not LlamaCppBackend.probe_server_capabilities().get("supports_eagle3"):
|
||||
_eagle3 = None
|
||||
except Exception:
|
||||
_eagle3 = None
|
||||
if _eagle3 and _same_file_key(_eagle3) not in _sized_keys:
|
||||
total_bytes += LlamaCppBackend._get_gguf_size_bytes(_eagle3)
|
||||
_sized_keys.add(_same_file_key(_eagle3))
|
||||
|
||||
# A caller owning speculation through llama_extra_args names the drafter with
|
||||
# --model-draft, which load_model hands to llama-server, so it is charged --
|
||||
|
|
|
|||
|
|
@ -96,6 +96,7 @@ except ImportError:
|
|||
from utils.paths import is_local_path, normalize_path, resolve_dataset_path
|
||||
|
||||
from auth.authentication import authenticated_via_api_key, get_current_subject
|
||||
from hub.dependencies import get_hf_token
|
||||
from hub.utils.host_paths import redact_host_paths
|
||||
from hub.utils.hf_tokens import HfTokenArg, cached_read_refused, hf_token_arg
|
||||
|
||||
|
|
@ -1683,6 +1684,47 @@ async def get_offload_state(current_subject: str = Depends(get_current_subject))
|
|||
return {"active": True, **offload}
|
||||
|
||||
|
||||
@router.get("/drafter-capability")
|
||||
async def get_drafter_capability(
|
||||
model_name: str,
|
||||
current_subject: str = Depends(get_current_subject),
|
||||
via_api_key: bool = Depends(authenticated_via_api_key),
|
||||
hf_token: Optional[str] = Depends(get_hf_token),
|
||||
):
|
||||
"""Which speculative-decoding drafter the Train tab can train for `model_name`: the native MTP head
|
||||
when the checkpoint ships one, else an EAGLE-3 drafter where vLLM or llama.cpp can run it."""
|
||||
from core.training.drafter import drafter_capability
|
||||
|
||||
from models.inference import resolve_inventory_handle
|
||||
|
||||
shown = (model_name or "").strip()
|
||||
if not shown or len(shown) > 512:
|
||||
raise HTTPException(status_code = 400, detail = "model_name is required")
|
||||
# A picker `ref:` handle resolves the way TrainingStartRequest resolves it; the answer keeps the handle.
|
||||
name = resolve_inventory_handle(shown)
|
||||
managed = managed_account()
|
||||
if managed:
|
||||
# Same rule as the training routes: Hub ids, or paths inside this account's workspace.
|
||||
try:
|
||||
account_path(name, reference = True, shared_cache = True)
|
||||
# A shared-cache snapshot is another tenant's unless this account may see that model.
|
||||
await asyncio.to_thread(_authorize_cache_fallback, name)
|
||||
except HTTPException:
|
||||
return {
|
||||
"model_name": shown,
|
||||
"has_native_mtp": False,
|
||||
"strategy": None,
|
||||
"supported": False,
|
||||
"reason": "This model is not available to this account.",
|
||||
"vllm": False,
|
||||
"llama_cpp": False,
|
||||
}
|
||||
# The caller's own token comes in the header; without one, ambient credentials for the owner
|
||||
# only, anonymous for API keys and managed accounts (the owner's token must not answer for them).
|
||||
token = hf_token_arg(hf_token, allow_ambient_token = not (via_api_key is True or managed))
|
||||
return {**await asyncio.to_thread(drafter_capability, name, token), "model_name": shown}
|
||||
|
||||
|
||||
@router.get("/hardware/visible")
|
||||
async def get_visible_hardware_utilization(current_subject: str = Depends(get_current_subject)):
|
||||
from utils.hardware import get_visible_gpu_utilization, gpu_query
|
||||
|
|
@ -1795,6 +1837,13 @@ async def start_training(
|
|||
to check progress.
|
||||
"""
|
||||
await asyncio.to_thread(_validate_decision_request, request, via_api_key)
|
||||
if request.drafter is not None and request.drafter.enabled:
|
||||
from core.training.training import should_use_mlx_training_backend
|
||||
if should_use_mlx_training_backend():
|
||||
raise HTTPException(
|
||||
status_code = 400,
|
||||
detail = "Drafter training is not available on Apple Silicon (MLX) yet.",
|
||||
)
|
||||
if managed_account():
|
||||
from utils.paths import tensorboard_root
|
||||
|
||||
|
|
@ -2119,6 +2168,11 @@ async def start_training(
|
|||
"eval_split": request.eval_split,
|
||||
"eval_steps": request.eval_steps,
|
||||
"early_stopping_patience": request.early_stopping_patience,
|
||||
"drafter": (
|
||||
request.drafter.model_dump()
|
||||
if request.drafter is not None and request.drafter.enabled
|
||||
else None
|
||||
),
|
||||
"dataset_slice_start": request.dataset_slice_start,
|
||||
"dataset_slice_end": request.dataset_slice_end,
|
||||
"custom_format_mapping": request.custom_format_mapping,
|
||||
|
|
@ -2646,7 +2700,9 @@ def _build_training_status(
|
|||
phase = "error"
|
||||
elif is_active:
|
||||
msg_lower = status_message.lower()
|
||||
if "loading" in msg_lower or "importing" in msg_lower:
|
||||
if msg_lower.startswith("training drafter"):
|
||||
phase = "training_drafter"
|
||||
elif "loading" in msg_lower or "importing" in msg_lower:
|
||||
phase = "loading_model"
|
||||
elif any(k in msg_lower for k in ["preparing", "initializing", "configuring"]):
|
||||
phase = "configuring"
|
||||
|
|
@ -2670,6 +2726,7 @@ def _build_training_status(
|
|||
"loss": getattr(progress, "loss", None),
|
||||
"learning_rate": getattr(progress, "learning_rate", None),
|
||||
"output_dir": getattr(backend, "_output_dir", None) or None,
|
||||
"drafter": getattr(progress, "drafter", None),
|
||||
"model_download_repo_id": (
|
||||
getattr(backend, "_model_download_repo_id", None) if is_active else None
|
||||
),
|
||||
|
|
|
|||
|
|
@ -1545,6 +1545,15 @@ class TestEstimateGgufRequiredGb(unittest.TestCase):
|
|||
classmethod(lambda cls, binary = None: {"supports_dspark": supported}),
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def _eagle3_capable(supported):
|
||||
from core.inference.llama_cpp import LlamaCppBackend
|
||||
return patch.object(
|
||||
LlamaCppBackend,
|
||||
"probe_server_capabilities",
|
||||
classmethod(lambda cls, binary = None: {"supports_eagle3": supported}),
|
||||
)
|
||||
|
||||
def test_local_dspark_sidecar_is_only_counted_when_requested(self):
|
||||
import tempfile
|
||||
|
||||
|
|
@ -1584,6 +1593,44 @@ class TestEstimateGgufRequiredGb(unittest.TestCase):
|
|||
self.assertAlmostEqual(dspark_gb, 5000 / (1024**3), places = 9)
|
||||
self.assertAlmostEqual(extras_gb, 5000 / (1024**3), places = 9)
|
||||
|
||||
def test_local_eagle3_drafter_paired_by_the_export_is_charged(self):
|
||||
"""A Studio export's drafter.json pairs an EAGLE-3 GGUF that Auto attaches at launch."""
|
||||
import json
|
||||
import tempfile
|
||||
|
||||
with tempfile.TemporaryDirectory() as d:
|
||||
p = Path(d)
|
||||
target = p / "model.gguf"
|
||||
target.write_bytes(b"x" * 2000)
|
||||
(p / "eagle3-model-F16.gguf").write_bytes(b"y" * 3000)
|
||||
cfg = SimpleNamespace(
|
||||
gguf_file = str(target),
|
||||
gguf_mmproj_file = None,
|
||||
gguf_mtp_file = None,
|
||||
gguf_hf_repo = None,
|
||||
gguf_variant = None,
|
||||
)
|
||||
with (
|
||||
patch.object(self.route, "_estimate_gguf_kv_gb", return_value = 0.0),
|
||||
patch.object(self.route, "_remote_gguf_compute_reserve_gb", return_value = 0.0),
|
||||
):
|
||||
with self._eagle3_capable(True):
|
||||
bare = self.route._estimate_gguf_required_gb(cfg, speculative_type = "auto")
|
||||
(p / "drafter.json").write_text(
|
||||
json.dumps({"strategy": "eagle3", "files": ["eagle3-model-F16.gguf"]})
|
||||
)
|
||||
auto = self.route._estimate_gguf_required_gb(cfg, speculative_type = "auto")
|
||||
off = self.route._estimate_gguf_required_gb(cfg, speculative_type = "off")
|
||||
# A binary without draft-eagle3 never opens the sidecar.
|
||||
with self._eagle3_capable(False):
|
||||
incapable = self.route._estimate_gguf_required_gb(
|
||||
cfg, speculative_type = "eagle3"
|
||||
)
|
||||
self.assertAlmostEqual(bare, 2000 / (1024**3), places = 9)
|
||||
self.assertAlmostEqual(auto, 5000 / (1024**3), places = 9)
|
||||
self.assertAlmostEqual(off, 2000 / (1024**3), places = 9)
|
||||
self.assertAlmostEqual(incapable, 2000 / (1024**3), places = 9)
|
||||
|
||||
def test_forced_dspark_on_an_incapable_binary_charges_no_drafter_at_all(self):
|
||||
"""The loader's DSpark branch falls back to --spec-default, which loads no
|
||||
drafter, so charging the MTP one would refuse a load that fits. Auto is
|
||||
|
|
|
|||
178
studio/backend/tests/test_drafter_launch_flags.py
Normal file
178
studio/backend/tests/test_drafter_launch_flags.py
Normal file
|
|
@ -0,0 +1,178 @@
|
|||
# SPDX-License-Identifier: AGPL-3.0-only
|
||||
# Copyright 2026-present the Unsloth AI Inc. team. All rights reserved. See /studio/LICENSE.AGPL-3.0
|
||||
|
||||
"""llama-server flags for a drafter trained with the fine-tune: an EAGLE-3 sidecar paired by the export's
|
||||
drafter.json, and a trained MTP head that lifts Auto's sub-3B / MLA defaults. GGUFs without that manifest
|
||||
keep today's routing."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
import pytest
|
||||
|
||||
sys.path.insert(0, str(Path(__file__).resolve().parent))
|
||||
from test_llama_cpp_mtp_detection import ( # noqa: F401 (stubs are installed on import)
|
||||
LlamaCppBackend,
|
||||
_canonicalize_spec_mode,
|
||||
_flags_dict,
|
||||
)
|
||||
|
||||
_SUB_3B = "unsloth/Qwen3.5-0.8B-MTP-GGUF"
|
||||
_PLAIN = "unsloth/Qwen3-4B-Instruct-GGUF"
|
||||
|
||||
|
||||
def _backend(monkeypatch, *, eagle3 = True):
|
||||
caps = {
|
||||
"found": True,
|
||||
"mtp_token": "draft-mtp",
|
||||
"supports_mtp": True,
|
||||
"supports_dspark": True,
|
||||
"supports_dflash": True,
|
||||
"supports_eagle3": eagle3,
|
||||
"mtp_probe_inconclusive": False,
|
||||
"ngram_mod_flavor": "new",
|
||||
"supports_ngram_mod": True,
|
||||
"spec_draft_n_max_flag": "--spec-draft-n-max",
|
||||
}
|
||||
monkeypatch.setattr(
|
||||
LlamaCppBackend, "probe_server_capabilities", classmethod(lambda cls, binary = None: caps)
|
||||
)
|
||||
backend = LlamaCppBackend()
|
||||
backend._nextn_predict_layers = None
|
||||
return backend
|
||||
|
||||
|
||||
def _flags(
|
||||
backend,
|
||||
mode,
|
||||
model,
|
||||
path,
|
||||
gpus = True,
|
||||
):
|
||||
return backend._build_speculative_flags(
|
||||
speculative_type = mode,
|
||||
spec_draft_n_max = None,
|
||||
extra_args = None,
|
||||
model_identifier = model,
|
||||
model_path = path,
|
||||
gpus = gpus,
|
||||
binary = "/fake/llama-server",
|
||||
)
|
||||
|
||||
|
||||
def _export(
|
||||
tmp_path,
|
||||
info,
|
||||
name = "model.Q4_K_M.gguf",
|
||||
):
|
||||
gguf = tmp_path / name
|
||||
gguf.write_bytes(b"GGUF")
|
||||
(tmp_path / "drafter.json").write_text(json.dumps(info))
|
||||
return str(gguf)
|
||||
|
||||
|
||||
def test_eagle3_mode_canonicalizes():
|
||||
assert _canonicalize_spec_mode("eagle3") == "eagle3"
|
||||
assert _canonicalize_spec_mode("draft-eagle3") == "eagle3"
|
||||
|
||||
|
||||
def test_auto_uses_paired_eagle3_sidecar(monkeypatch, tmp_path):
|
||||
(tmp_path / "eagle3-model-F16.gguf").write_bytes(b"GGUF")
|
||||
path = _export(
|
||||
tmp_path,
|
||||
{"strategy": "eagle3", "files": ["eagle3-model-F16.gguf"], "ggufs": ["model.Q4_K_M.gguf"]},
|
||||
)
|
||||
flags = _flags_dict(_flags(_backend(monkeypatch), "auto", _PLAIN, path))
|
||||
assert flags["--spec-type"] == "draft-eagle3"
|
||||
assert flags["--model-draft"] == str(tmp_path / "eagle3-model-F16.gguf")
|
||||
assert flags["--spec-draft-n-max"] == "3"
|
||||
|
||||
|
||||
def test_eagle3_without_binary_support_falls_back(monkeypatch, tmp_path):
|
||||
(tmp_path / "eagle3-model-F16.gguf").write_bytes(b"GGUF")
|
||||
path = _export(tmp_path, {"strategy": "eagle3", "files": ["eagle3-model-F16.gguf"]})
|
||||
auto = _flags(_backend(monkeypatch, eagle3 = False), "auto", _PLAIN, path)
|
||||
assert "draft-eagle3" not in auto
|
||||
forced = _flags(_backend(monkeypatch, eagle3 = False), "eagle3", _PLAIN, path)
|
||||
assert forced == ["--spec-default"]
|
||||
|
||||
|
||||
def test_forced_eagle3_without_sidecar_falls_back(monkeypatch, tmp_path):
|
||||
backend = _backend(monkeypatch)
|
||||
assert _flags(backend, "eagle3", _PLAIN, str(tmp_path / "x.gguf")) == ["--spec-default"]
|
||||
assert backend._spec_fallback_reason == "drafter_not_found"
|
||||
|
||||
|
||||
def test_manifest_naming_another_gguf_is_ignored(monkeypatch, tmp_path):
|
||||
(tmp_path / "eagle3-model-F16.gguf").write_bytes(b"GGUF")
|
||||
_export(
|
||||
tmp_path,
|
||||
{"strategy": "eagle3", "files": ["eagle3-model-F16.gguf"], "ggufs": ["other.gguf"]},
|
||||
)
|
||||
path = str(tmp_path / "model.Q4_K_M.gguf")
|
||||
assert "draft-eagle3" not in _flags(_backend(monkeypatch), "auto", _PLAIN, path)
|
||||
|
||||
|
||||
@pytest.mark.parametrize("gpus", [True, False])
|
||||
def test_trained_mtp_head_lifts_the_sub_3b_floor(monkeypatch, tmp_path, gpus):
|
||||
stock = _flags_dict(_flags(_backend(monkeypatch), "auto", _SUB_3B, None, gpus))
|
||||
assert stock.get("--spec-type") == "ngram-mod" # unchanged without a manifest
|
||||
path = _export(
|
||||
tmp_path,
|
||||
{"strategy": "mtp", "mtp_trained": True, "files": [], "ggufs": ["model.Q4_K_M.gguf"]},
|
||||
)
|
||||
trained = _flags_dict(_flags(_backend(monkeypatch), "auto", _SUB_3B, path, gpus))
|
||||
assert "draft-mtp" in trained["--spec-type"]
|
||||
|
||||
|
||||
def test_trained_mtp_head_lifts_the_mla_default_off(monkeypatch, tmp_path):
|
||||
backend = _backend(monkeypatch)
|
||||
backend._nextn_predict_layers = 1
|
||||
backend._kv_lora_rank = 512
|
||||
monkeypatch.delenv("UNSLOTH_MLA_MTP_ENABLED", raising = False)
|
||||
model = "unsloth/GLM-4.7-Flash-GGUF"
|
||||
stock = _flags_dict(_flags(backend, "auto", model, None))
|
||||
assert stock.get("--spec-type") != "draft-mtp"
|
||||
path = _export(tmp_path, {"strategy": "mtp", "mtp_trained": True, "files": []})
|
||||
trained = _flags_dict(_flags(backend, "auto", model, path))
|
||||
assert trained["--spec-type"] == "draft-mtp"
|
||||
|
||||
|
||||
def test_no_manifest_keeps_routing(monkeypatch, tmp_path):
|
||||
path = str(tmp_path / "model.Q4_K_M.gguf")
|
||||
for mode in ("auto", "mtp", "ngram", "off", "dspark"):
|
||||
a = _flags(_backend(monkeypatch), mode, _SUB_3B, None)
|
||||
b = _flags(_backend(monkeypatch), mode, _SUB_3B, path)
|
||||
assert a == b, mode
|
||||
|
||||
|
||||
def test_exported_draft_steps_set_the_default_depth(monkeypatch, tmp_path):
|
||||
(tmp_path / "eagle3-model-F16.gguf").write_bytes(b"GGUF")
|
||||
path = _export(
|
||||
tmp_path,
|
||||
{"strategy": "eagle3", "files": ["eagle3-model-F16.gguf"], "draft_steps": 5},
|
||||
)
|
||||
assert (
|
||||
_flags_dict(_flags(_backend(monkeypatch), "auto", _PLAIN, path))["--spec-draft-n-max"]
|
||||
== "5"
|
||||
)
|
||||
override = _backend(monkeypatch)._build_speculative_flags(
|
||||
speculative_type = "auto",
|
||||
spec_draft_n_max = 2,
|
||||
extra_args = None,
|
||||
model_identifier = _PLAIN,
|
||||
model_path = path,
|
||||
gpus = True,
|
||||
binary = "/fake/llama-server",
|
||||
)
|
||||
assert _flags_dict(override)["--spec-draft-n-max"] == "2"
|
||||
mtp = tmp_path / "mtp"
|
||||
mtp.mkdir()
|
||||
path = _export(mtp, {"strategy": "mtp", "mtp_trained": True, "files": [], "draft_steps": 4})
|
||||
assert (
|
||||
_flags_dict(_flags(_backend(monkeypatch), "auto", _SUB_3B, path))["--spec-draft-n-max"]
|
||||
== "4"
|
||||
)
|
||||
1205
studio/backend/tests/test_drafter_training.py
Normal file
1205
studio/backend/tests/test_drafter_training.py
Normal file
File diff suppressed because it is too large
Load diff
|
|
@ -2547,3 +2547,45 @@ def test_vllm_mamba_retry_respects_an_external_stop(isolated, monkeypatch):
|
|||
engine.start("model", 4096, [0], dict(os.environ))
|
||||
engine.stop()
|
||||
assert len(launches) == 1
|
||||
|
||||
|
||||
@_LOCAL_ENGINE_HOST
|
||||
def test_vllm_retries_once_without_a_drafter_that_breaks_startup(isolated, monkeypatch):
|
||||
import os
|
||||
from core.inference import engine_adapters
|
||||
|
||||
monkeypatch.setattr(
|
||||
engine_adapters, "vllm_speculative_args", lambda _: ["--speculative-config", "{}"]
|
||||
)
|
||||
engine, launches = _scripted_engine(isolated, monkeypatch, ["crash", "serve"])
|
||||
try:
|
||||
engine.start("model", 4096, [0], dict(os.environ))
|
||||
assert engine.phase == "ready"
|
||||
finally:
|
||||
engine.stop()
|
||||
assert [launch.get("no_speculative_config") for launch in launches] == [None, True]
|
||||
|
||||
|
||||
@_LOCAL_ENGINE_HOST
|
||||
def test_vllm_drafter_retry_respects_an_external_stop(isolated, monkeypatch):
|
||||
import os
|
||||
from core.inference import engine_adapters, managed_engine
|
||||
|
||||
monkeypatch.setattr(
|
||||
engine_adapters, "vllm_speculative_args", lambda _: ["--speculative-config", "{}"]
|
||||
)
|
||||
engine, launches = _scripted_engine(isolated, monkeypatch, ["crash", "serve"])
|
||||
original = engine._start_once
|
||||
|
||||
def first_then_stop(*args):
|
||||
try:
|
||||
return original(*args)
|
||||
except managed_engine._EngineExited:
|
||||
assert engine.stop() is True
|
||||
raise
|
||||
|
||||
monkeypatch.setattr(engine, "_start_once", first_then_stop)
|
||||
with pytest.raises(RuntimeError, match = "cancelled"):
|
||||
engine.start("model", 4096, [0], dict(os.environ))
|
||||
engine.stop()
|
||||
assert len(launches) == 1
|
||||
|
|
|
|||
|
|
@ -160,8 +160,11 @@ export const BUDGET = {
|
|||
// raw / 83 B transfer to the eager settings and English locale chunks (6,780,553 -> 6,780,901 B raw,
|
||||
// 2,038,848 -> 2,038,931 B transfer against 9f5b133254, one machine and build, Node 24, chunk count unchanged
|
||||
// at 95). Raised by that growth.
|
||||
transferBytes: 2_039_292,
|
||||
rawBytes: 6_782_356,
|
||||
// Drafter training in the Train tab adds about 4.9 KB raw / 1.4 KB transfer (6,628.3 KB raw, 1,992.9 KB transfer
|
||||
// measured against cd424654a, one machine and build, 95 chunks): its persisted training-store fields, their
|
||||
// migration and the en strings hydrate at startup; the section itself is not in the startup set.
|
||||
transferBytes: 2_041_000,
|
||||
rawBytes: 6_787_500,
|
||||
};
|
||||
|
||||
// The chunk count is reported but not budgeted. Splitting a page out of the entry raises it while lowering the
|
||||
|
|
|
|||
|
|
@ -169,6 +169,13 @@ export const DEFAULT_HYPERPARAMS = {
|
|||
saveSteps: 0,
|
||||
evalSteps: 0.0,
|
||||
earlyStoppingPatience: 0,
|
||||
drafterEnabled: false,
|
||||
drafterStrategy: "auto" as const,
|
||||
drafterDataSource: "dataset" as const,
|
||||
drafterMaxExamples: 2000,
|
||||
drafterEpochs: 1,
|
||||
drafterLearningRate: null as number | null,
|
||||
drafterDraftSteps: 3,
|
||||
packing: false,
|
||||
trainOnCompletions: false,
|
||||
gradientCheckpointing: "unsloth" as const,
|
||||
|
|
|
|||
|
|
@ -89,6 +89,14 @@ export interface ExportOperationResponse {
|
|||
details?: { output_path?: string | null } & Record<string, unknown>;
|
||||
}
|
||||
|
||||
/** The trained speculative-decoding drafter an export carried (backend `details.drafter`). */
|
||||
export interface ExportDrafterInfo {
|
||||
strategy: "mtp" | "eagle3";
|
||||
files?: string[];
|
||||
vllm_command?: string | null;
|
||||
llama_cpp_args?: string[] | string | null;
|
||||
}
|
||||
|
||||
/** GGUF export options for a decision model (Clef / Laya) checkpoint folder. */
|
||||
export interface DecisionExportInfo {
|
||||
is_decision: boolean;
|
||||
|
|
|
|||
|
|
@ -30,7 +30,7 @@ import {
|
|||
import { HugeiconsIcon } from "@hugeicons/react";
|
||||
import { useEffect, useRef, useState } from "react";
|
||||
import { useShallow } from "zustand/react/shallow";
|
||||
import type { ExportLogEntry } from "../api/export-api";
|
||||
import type { ExportDrafterInfo, ExportLogEntry } from "../api/export-api";
|
||||
import {
|
||||
EXPORT_METHODS,
|
||||
type ExportMethod,
|
||||
|
|
@ -456,6 +456,9 @@ export function ExportRunPanel(props: ExportRunPanelProps) {
|
|||
</div>
|
||||
));
|
||||
})()}
|
||||
{run.result?.drafter ? (
|
||||
<ExportDrafterNote drafter={run.result.drafter} />
|
||||
) : null}
|
||||
</div>
|
||||
</div>
|
||||
)}
|
||||
|
|
@ -650,3 +653,21 @@ export function ExportRunPanel(props: ExportRunPanelProps) {
|
|||
</div>
|
||||
);
|
||||
}
|
||||
|
||||
function ExportDrafterNote({ drafter }: { drafter: ExportDrafterInfo }) {
|
||||
return (
|
||||
<div className="flex min-w-0 flex-col gap-0.5">
|
||||
<span>
|
||||
Includes trained drafter ({drafter.strategy === "mtp" ? "MTP" : "EAGLE-3"})
|
||||
</span>
|
||||
{drafter.vllm_command ? (
|
||||
<code
|
||||
className="select-all whitespace-pre-wrap break-all font-mono text-ui-12 text-foreground/90"
|
||||
title={drafter.vllm_command}
|
||||
>
|
||||
{drafter.vllm_command}
|
||||
</code>
|
||||
) : null}
|
||||
</div>
|
||||
);
|
||||
}
|
||||
|
|
|
|||
|
|
@ -11,6 +11,7 @@ import {
|
|||
getExportStatus,
|
||||
isRecoverableTransportError,
|
||||
loadCheckpoint,
|
||||
type ExportDrafterInfo,
|
||||
type ExportLogEntry,
|
||||
type ExportLogPollEntry,
|
||||
type ExportOperationResponse,
|
||||
|
|
@ -18,6 +19,18 @@ import {
|
|||
} from "../api/export-api";
|
||||
import type { ExportMethod } from "../constants";
|
||||
|
||||
// Here, not in export-api: tests swap that module for a stub of its request functions.
|
||||
function exportDrafterFrom(
|
||||
details: ExportOperationResponse["details"] | undefined,
|
||||
): ExportDrafterInfo | null {
|
||||
const drafter = details?.drafter;
|
||||
if (typeof drafter !== "object" || drafter === null) return null;
|
||||
const strategy = (drafter as Record<string, unknown>).strategy;
|
||||
return strategy === "mtp" || strategy === "eagle3"
|
||||
? (drafter as ExportDrafterInfo)
|
||||
: null;
|
||||
}
|
||||
|
||||
/** Thrown by status recovery when the backend reports the op was cancelled. */
|
||||
class ExportCanceledError extends Error {
|
||||
constructor() {
|
||||
|
|
@ -205,6 +218,8 @@ interface ExportRuntimeState {
|
|||
outputPath: string | null;
|
||||
outputPaths: { label: string; path: string }[];
|
||||
destination: ExportDestination;
|
||||
/** Set when the export carried a trained drafter (MTP head or EAGLE-3). */
|
||||
drafter?: ExportDrafterInfo | null;
|
||||
} | null;
|
||||
error: string | null;
|
||||
cancelRequested: boolean;
|
||||
|
|
@ -479,6 +494,7 @@ export const useExportRuntimeStore = create<ExportRuntimeStore>()((set, get) =>
|
|||
// banner can list each sibling directory a multi-format run created.
|
||||
set({ phase: "exporting" });
|
||||
const outputs: { label: string; path: string }[] = [];
|
||||
let drafter: ExportDrafterInfo | null = null;
|
||||
|
||||
if (params.exportMethod === "merged") {
|
||||
// Each selected format writes its own sibling directory (PEFT or non-PEFT base alike).
|
||||
|
|
@ -490,7 +506,7 @@ export const useExportRuntimeStore = create<ExportRuntimeStore>()((set, get) =>
|
|||
if (!isCurrent()) return;
|
||||
set({ quantIndex: i });
|
||||
const sel = selections[i];
|
||||
const { outputPath } = await runRecoverableOp(() =>
|
||||
const { outputPath, details: mergedDetails } = await runRecoverableOp(() =>
|
||||
exportMerged({
|
||||
save_directory: params.saveDirectory,
|
||||
format_type: sel.formatType,
|
||||
|
|
@ -505,6 +521,7 @@ export const useExportRuntimeStore = create<ExportRuntimeStore>()((set, get) =>
|
|||
}),
|
||||
);
|
||||
if (outputPath) outputs.push({ label: sel.label, path: outputPath });
|
||||
drafter = exportDrafterFrom(mergedDetails) ?? drafter;
|
||||
if (!isCurrent()) return;
|
||||
set({ quantIndex: i + 1 });
|
||||
}
|
||||
|
|
@ -538,6 +555,7 @@ export const useExportRuntimeStore = create<ExportRuntimeStore>()((set, get) =>
|
|||
path: outputPath,
|
||||
});
|
||||
}
|
||||
drafter = exportDrafterFrom(details);
|
||||
if (outputPath && params.npuQ4nx) {
|
||||
const sep = outputPath.includes("\\") ? "\\" : "/";
|
||||
outputs.push({ label: "AMD NPU (Q4NX)", path: `${outputPath}${sep}npu-q4nx` });
|
||||
|
|
@ -545,7 +563,7 @@ export const useExportRuntimeStore = create<ExportRuntimeStore>()((set, get) =>
|
|||
if (!isCurrent()) return;
|
||||
set({ quantIndex: get().quantTotal });
|
||||
} else if (params.exportMethod === "lora") {
|
||||
const { outputPath } = await runRecoverableOp(() =>
|
||||
const { outputPath, details: loraDetails } = await runRecoverableOp(() =>
|
||||
exportLoRA({
|
||||
save_directory: params.saveDirectory,
|
||||
push_to_hub: pushToHub,
|
||||
|
|
@ -565,6 +583,7 @@ export const useExportRuntimeStore = create<ExportRuntimeStore>()((set, get) =>
|
|||
path: outputPath,
|
||||
});
|
||||
}
|
||||
drafter = exportDrafterFrom(loraDetails);
|
||||
}
|
||||
if (!isCurrent()) return;
|
||||
|
||||
|
|
@ -576,6 +595,7 @@ export const useExportRuntimeStore = create<ExportRuntimeStore>()((set, get) =>
|
|||
outputPath: outputs[0]?.path ?? null,
|
||||
outputPaths: outputs,
|
||||
destination: params.destination,
|
||||
drafter,
|
||||
},
|
||||
});
|
||||
} catch (err) {
|
||||
|
|
|
|||
195
studio/frontend/src/features/studio/sections/drafter-section.tsx
Normal file
195
studio/frontend/src/features/studio/sections/drafter-section.tsx
Normal file
|
|
@ -0,0 +1,195 @@
|
|||
// SPDX-License-Identifier: AGPL-3.0-only
|
||||
// Copyright 2026-present the Unsloth AI Inc. team. All rights reserved. See /studio/LICENSE.AGPL-3.0
|
||||
|
||||
import { Checkbox } from "@/components/ui/checkbox";
|
||||
import {
|
||||
Collapsible,
|
||||
CollapsibleContent,
|
||||
CollapsibleTrigger,
|
||||
} from "@/components/ui/collapsible";
|
||||
import { Input } from "@/components/ui/input";
|
||||
import {
|
||||
Select,
|
||||
SelectContent,
|
||||
SelectItem,
|
||||
SelectTrigger,
|
||||
SelectValue,
|
||||
} from "@/components/ui/select";
|
||||
import { usePlatformStore } from "@/config/env";
|
||||
import {
|
||||
drafterEligible,
|
||||
useDrafterCapability,
|
||||
useTrainingConfigStore,
|
||||
} from "@/features/training";
|
||||
import { useT } from "@/i18n";
|
||||
import { ChevronDownStandardIcon } from "@/lib/chevron-icons";
|
||||
import { HugeiconsIcon } from "@hugeicons/react";
|
||||
import { type ReactElement, useState } from "react";
|
||||
import { useShallow } from "zustand/react/shallow";
|
||||
import { ParamsRow } from "./params-section-controls";
|
||||
|
||||
export function DrafterSection(): ReactElement | null {
|
||||
const t = useT();
|
||||
const deviceType = usePlatformStore((state) => state.deviceType);
|
||||
const store = useTrainingConfigStore(
|
||||
useShallow((state) => ({
|
||||
selectedModel: state.selectedModel,
|
||||
eligible: drafterEligible(state),
|
||||
capability: state.drafterCapability,
|
||||
enabled: state.drafterEnabled,
|
||||
dataSource: state.drafterDataSource,
|
||||
maxExamples: state.drafterMaxExamples,
|
||||
epochs: state.drafterEpochs,
|
||||
learningRate: state.drafterLearningRate,
|
||||
draftSteps: state.drafterDraftSteps,
|
||||
setEnabled: state.setDrafterEnabled,
|
||||
setDataSource: state.setDrafterDataSource,
|
||||
setMaxExamples: state.setDrafterMaxExamples,
|
||||
setEpochs: state.setDrafterEpochs,
|
||||
setLearningRate: state.setDrafterLearningRate,
|
||||
setDraftSteps: state.setDrafterDraftSteps,
|
||||
})),
|
||||
);
|
||||
const [open, setOpen] = useState(false);
|
||||
useDrafterCapability(open || store.enabled);
|
||||
|
||||
// MLX trains through its own worker, which has no drafter phase.
|
||||
if (!store.eligible || deviceType === "mac") {
|
||||
return null;
|
||||
}
|
||||
|
||||
const capability =
|
||||
store.capability && store.capability.model_name === store.selectedModel
|
||||
? store.capability
|
||||
: null;
|
||||
const supported = capability?.supported === true;
|
||||
const helper = !capability
|
||||
? t("studio.params.drafterChecking")
|
||||
: !supported
|
||||
? t("studio.params.drafterUnavailable", {
|
||||
reason: capability.reason ?? "",
|
||||
})
|
||||
: capability.has_native_mtp
|
||||
? t("studio.params.drafterRetrainMtp")
|
||||
: t("studio.params.drafterEagle3");
|
||||
|
||||
return (
|
||||
<Collapsible open={open} onOpenChange={setOpen}>
|
||||
<CollapsibleTrigger className="flex w-full cursor-pointer items-center gap-1.5 text-xs text-muted-foreground">
|
||||
<HugeiconsIcon
|
||||
icon={ChevronDownStandardIcon}
|
||||
className={`size-3.5 transition-transform ${open ? "rotate-180" : ""}`}
|
||||
/>
|
||||
{t("studio.params.drafterSettings")}
|
||||
</CollapsibleTrigger>
|
||||
<CollapsibleContent className="mt-3 data-[state=open]:overflow-visible">
|
||||
<div className="pt-1.5 flex flex-col gap-4">
|
||||
<div className="flex flex-col gap-1">
|
||||
<ParamsRow
|
||||
label={t("studio.params.drafterTrain")}
|
||||
tooltip={t("studio.params.drafterTrainTooltip")}
|
||||
>
|
||||
<Checkbox
|
||||
id="drafterEnabled"
|
||||
aria-label={t("studio.params.drafterTrain")}
|
||||
checked={store.enabled && supported}
|
||||
disabled={!supported}
|
||||
onCheckedChange={(value) => store.setEnabled(!!value)}
|
||||
/>
|
||||
</ParamsRow>
|
||||
<span
|
||||
className="text-xs text-muted-foreground"
|
||||
data-testid="drafter-helper"
|
||||
>
|
||||
{helper}
|
||||
</span>
|
||||
</div>
|
||||
{store.enabled && supported && (
|
||||
<>
|
||||
<ParamsRow label={t("studio.params.drafterDataSource")}>
|
||||
<Select
|
||||
value={store.dataSource}
|
||||
onValueChange={(value) =>
|
||||
store.setDataSource(
|
||||
value === "regenerate" ? "regenerate" : "dataset",
|
||||
)
|
||||
}
|
||||
>
|
||||
<SelectTrigger className="w-56">
|
||||
<SelectValue />
|
||||
</SelectTrigger>
|
||||
<SelectContent>
|
||||
<SelectItem value="dataset">
|
||||
{t("studio.params.drafterDataSourceDataset")}
|
||||
</SelectItem>
|
||||
<SelectItem value="regenerate">
|
||||
{t("studio.params.drafterDataSourceRegenerate")}
|
||||
</SelectItem>
|
||||
</SelectContent>
|
||||
</Select>
|
||||
</ParamsRow>
|
||||
<ParamsRow label={t("studio.params.drafterMaxExamples")}>
|
||||
<Input
|
||||
type="number"
|
||||
step="100"
|
||||
min="16"
|
||||
max="100000"
|
||||
value={store.maxExamples}
|
||||
onChange={(event) =>
|
||||
store.setMaxExamples(Number(event.target.value))
|
||||
}
|
||||
className="w-28 font-mono"
|
||||
/>
|
||||
</ParamsRow>
|
||||
<ParamsRow label={t("studio.params.drafterEpochs")}>
|
||||
<Input
|
||||
type="number"
|
||||
step="0.5"
|
||||
min="0.1"
|
||||
max="20"
|
||||
value={store.epochs}
|
||||
onChange={(event) =>
|
||||
store.setEpochs(Number(event.target.value))
|
||||
}
|
||||
className="w-28 font-mono"
|
||||
/>
|
||||
</ParamsRow>
|
||||
<ParamsRow label={t("studio.params.drafterLearningRate")}>
|
||||
<Input
|
||||
type="number"
|
||||
step="0.00001"
|
||||
min="0"
|
||||
placeholder={t("studio.params.drafterLearningRateDefault")}
|
||||
value={store.learningRate ?? ""}
|
||||
onChange={(event) => {
|
||||
const raw = event.target.value.trim();
|
||||
const value = Number(raw);
|
||||
store.setLearningRate(
|
||||
raw === "" || !Number.isFinite(value) || value <= 0
|
||||
? null
|
||||
: value,
|
||||
);
|
||||
}}
|
||||
className="w-28 font-mono"
|
||||
/>
|
||||
</ParamsRow>
|
||||
<ParamsRow label={t("studio.params.drafterDraftSteps")}>
|
||||
<Input
|
||||
type="number"
|
||||
step="1"
|
||||
min="1"
|
||||
max="8"
|
||||
value={store.draftSteps}
|
||||
onChange={(event) =>
|
||||
store.setDraftSteps(Number(event.target.value))
|
||||
}
|
||||
className="w-28 font-mono"
|
||||
/>
|
||||
</ParamsRow>
|
||||
</>
|
||||
)}
|
||||
</div>
|
||||
</CollapsibleContent>
|
||||
</Collapsible>
|
||||
);
|
||||
}
|
||||
|
|
@ -18,6 +18,7 @@ import {
|
|||
} from "@/components/ui/tooltip";
|
||||
import { CONTEXT_LENGTHS } from "@/config/training";
|
||||
import {
|
||||
useDrafterCapability,
|
||||
useMaxStepsEpochsToggle,
|
||||
useTrainingConfigStore,
|
||||
} from "@/features/training";
|
||||
|
|
@ -26,6 +27,7 @@ import { InformationCircleIcon } from "@hugeicons/core-free-icons";
|
|||
import { HugeiconsIcon } from "@hugeicons/react";
|
||||
import { type ReactElement, useRef, useState } from "react";
|
||||
import { useShallow } from "zustand/react/shallow";
|
||||
import { DrafterSection } from "./drafter-section";
|
||||
import { FieldHint } from "./field-hint";
|
||||
import { LoraParamsSection } from "./lora-params-section";
|
||||
import { TrainingHyperparametersSection } from "./training-hyperparameters-section";
|
||||
|
|
@ -47,6 +49,9 @@ export function ParamsSection({
|
|||
mode?: "simple" | "advanced";
|
||||
}): ReactElement {
|
||||
const t = useT();
|
||||
// Simple mode hides the section, but a drafter turned on earlier still needs its capability.
|
||||
const drafterEnabled = useTrainingConfigStore((state) => state.drafterEnabled);
|
||||
useDrafterCapability(drafterEnabled);
|
||||
const store = useTrainingConfigStore(
|
||||
useShallow((state) => ({
|
||||
projectName: state.projectName,
|
||||
|
|
@ -487,6 +492,7 @@ export function ParamsSection({
|
|||
epochsSliderMax={epochsSliderMax}
|
||||
/>
|
||||
)}
|
||||
{showAdvanced && <DrafterSection />}
|
||||
</div>
|
||||
</div>
|
||||
);
|
||||
|
|
|
|||
|
|
@ -19,6 +19,8 @@ export const phaseColors: Record<TrainingPhase, string> = {
|
|||
// Busy, not done: amber like the other working states, never completed green.
|
||||
finalizing:
|
||||
"bg-amber-100 text-amber-700 dark:bg-amber-900 dark:text-amber-300",
|
||||
training_drafter:
|
||||
"bg-emerald-100 text-emerald-700 dark:bg-emerald-900 dark:text-emerald-300",
|
||||
completed:
|
||||
"bg-emerald-100 text-emerald-700 dark:bg-emerald-900 dark:text-emerald-300",
|
||||
error: "bg-red-100 text-red-700 dark:bg-red-900 dark:text-red-300",
|
||||
|
|
|
|||
|
|
@ -80,6 +80,7 @@ const phaseLabelKeys = {
|
|||
configuring: "studio.progress.phase.configuring",
|
||||
training: "studio.progress.phase.training",
|
||||
finalizing: "studio.progress.phase.finalizing",
|
||||
training_drafter: "studio.progress.phase.trainingDrafter",
|
||||
completed: "studio.progress.phase.completed",
|
||||
error: "studio.progress.phase.error",
|
||||
stopped: "studio.progress.phase.stopped",
|
||||
|
|
|
|||
|
|
@ -6,6 +6,7 @@ import {
|
|||
toBackendTrainingType,
|
||||
} from "../lib/training-methods";
|
||||
import type { SystemInfoResponse } from "@/hooks/use-system";
|
||||
import { drafterEligible, drafterRequestFrom } from "../lib/drafter-config";
|
||||
import type { TrainingStartRequest } from "../types/api";
|
||||
import type { TrainingConfigState } from "../types/config";
|
||||
|
||||
|
|
@ -318,5 +319,30 @@ export function buildTrainingStartPayload(
|
|||
tensorboard_dir: config.enableTensorboard
|
||||
? config.tensorboardDir.trim() || null
|
||||
: null,
|
||||
// Spread only when sent: a run without a drafter posts exactly the fields it did before.
|
||||
...(sendsDrafter(config, system)
|
||||
? { drafter: drafterRequestFrom(config) }
|
||||
: {}),
|
||||
};
|
||||
}
|
||||
|
||||
/** On, a run type with a drafter phase, not MLX, and not a model the backend said cannot train one.
|
||||
* A capability check still pending (or for a previous model) sends it: the backend re-checks the
|
||||
* model before the drafter phase and reports a warning instead of dropping the request silently. */
|
||||
export function sendsDrafter(
|
||||
config: TrainingConfigState,
|
||||
system: SystemInfoResponse | null = null,
|
||||
): boolean {
|
||||
const capability = config.drafterCapability;
|
||||
const refused =
|
||||
capability !== null &&
|
||||
capability.model_name === config.selectedModel &&
|
||||
!capability.supported &&
|
||||
!capability.inconclusive;
|
||||
return (
|
||||
config.drafterEnabled &&
|
||||
drafterEligible(config) &&
|
||||
system?.device_backend !== "mlx" &&
|
||||
!refused
|
||||
);
|
||||
}
|
||||
|
|
|
|||
|
|
@ -29,6 +29,8 @@ interface BackendTrainingDefaults {
|
|||
save_steps?: number;
|
||||
eval_steps?: number;
|
||||
early_stopping_patience?: number;
|
||||
/** Drafter training block (same shape as the start request's `drafter`). */
|
||||
drafter?: unknown;
|
||||
weight_decay?: number;
|
||||
random_seed?: number;
|
||||
offload_layers?: number | "auto";
|
||||
|
|
|
|||
|
|
@ -2,6 +2,7 @@
|
|||
// Copyright 2026-present the Unsloth AI Inc. team. All rights reserved. See /studio/LICENSE.AGPL-3.0
|
||||
|
||||
import { authFetch } from "@/features/auth";
|
||||
import { hubTokenHeader } from "@/features/hub";
|
||||
import { readFastApiError } from "@/lib/format-fastapi-error";
|
||||
// eslint-disable-next-line no-restricted-imports
|
||||
import { checkDiskSpace } from "@/features/settings/low-disk-check";
|
||||
|
|
@ -12,6 +13,7 @@ import {
|
|||
consumeTrainingProgressStream,
|
||||
} from "../lib/training-sse-stream";
|
||||
import type {
|
||||
DrafterCapability,
|
||||
TrainingResetResponse,
|
||||
TrainingStartRequest,
|
||||
TrainingStartRequestStatusResponse,
|
||||
|
|
@ -368,6 +370,23 @@ export function getTrainingMetrics(
|
|||
: requestTrainingMetrics.run(scope, expectedJobId);
|
||||
}
|
||||
|
||||
/** Which drafter `modelName` can train after fine-tuning (MTP retrain or EAGLE-3) and where it runs. */
|
||||
export async function getDrafterCapability(
|
||||
modelName: string,
|
||||
signal?: AbortSignal,
|
||||
hfToken?: string | null,
|
||||
): Promise<DrafterCapability> {
|
||||
// The token rides a header, never the query string (private / gated models).
|
||||
const response = await authFetch(
|
||||
`/api/train/drafter-capability?model_name=${encodeURIComponent(modelName)}`,
|
||||
{ signal, headers: hubTokenHeader(hfToken?.trim() || null) },
|
||||
);
|
||||
if (!response.ok) {
|
||||
throw new Error(await readFastApiError(response));
|
||||
}
|
||||
return (await response.json()) as DrafterCapability;
|
||||
}
|
||||
|
||||
export async function streamTrainingProgress(options: {
|
||||
signal: AbortSignal;
|
||||
expectedJobId: string;
|
||||
|
|
|
|||
|
|
@ -0,0 +1,91 @@
|
|||
// SPDX-License-Identifier: AGPL-3.0-only
|
||||
// Copyright 2026-present the Unsloth AI Inc. team. All rights reserved. See /studio/LICENSE.AGPL-3.0
|
||||
|
||||
import { useEffect, useState } from "react";
|
||||
import { useShallow } from "zustand/react/shallow";
|
||||
import { useHfTokenStore } from "@/features/hub";
|
||||
import { getDrafterCapability } from "../api/train-api";
|
||||
import { useTrainingConfigStore } from "../stores/training-config-store";
|
||||
|
||||
/** Keep `drafterCapability` current for the selected model while drafter training is on.
|
||||
* Mounted with the params section in both modes: the start payload only carries `drafter`
|
||||
* once the capability for this exact model says it can train one. */
|
||||
// The last probe, shared by every mounted copy of the hook: one request per (model, token), and a
|
||||
// failure is retried while the hook stays active, never cached as final.
|
||||
let lastProbe: { key: string; failed: boolean; done: boolean } | null = null;
|
||||
const RETRY_MS = 15_000;
|
||||
|
||||
export function useDrafterCapability(active: boolean): void {
|
||||
const { selectedModel, capabilityFor, setDrafterCapability } =
|
||||
useTrainingConfigStore(
|
||||
useShallow((state) => ({
|
||||
selectedModel: state.selectedModel,
|
||||
capabilityFor: state.drafterCapability?.model_name ?? null,
|
||||
setDrafterCapability: state.setDrafterCapability,
|
||||
})),
|
||||
);
|
||||
const token = useHfTokenStore((state) => state.token);
|
||||
const [retry, setRetry] = useState(0);
|
||||
|
||||
useEffect(() => {
|
||||
if (!active) return;
|
||||
const id = setInterval(() => {
|
||||
if (lastProbe?.failed) {
|
||||
lastProbe = null;
|
||||
setRetry((n) => n + 1);
|
||||
}
|
||||
}, RETRY_MS);
|
||||
return () => clearInterval(id);
|
||||
}, [active]);
|
||||
|
||||
useEffect(() => {
|
||||
const key = `${selectedModel}\u0000${token}`;
|
||||
if (!active) {
|
||||
if (lastProbe?.failed) lastProbe = null;
|
||||
return;
|
||||
}
|
||||
if (
|
||||
!selectedModel ||
|
||||
(capabilityFor === selectedModel && lastProbe?.key === key)
|
||||
)
|
||||
return;
|
||||
lastProbe = { key, failed: false, done: false };
|
||||
const controller = new AbortController();
|
||||
getDrafterCapability(selectedModel, controller.signal, token)
|
||||
.then((capability) => {
|
||||
if (controller.signal.aborted) return;
|
||||
lastProbe = {
|
||||
key,
|
||||
failed: Boolean(capability.inconclusive),
|
||||
done: true,
|
||||
};
|
||||
// The backend may echo a resolved path; key the answer on what was asked.
|
||||
setDrafterCapability({ ...capability, model_name: selectedModel });
|
||||
})
|
||||
.catch((error: unknown) => {
|
||||
if (controller.signal.aborted) return;
|
||||
lastProbe = { key, failed: true, done: true };
|
||||
setDrafterCapability({
|
||||
model_name: selectedModel,
|
||||
has_native_mtp: false,
|
||||
strategy: null,
|
||||
supported: false,
|
||||
reason: error instanceof Error ? error.message : String(error),
|
||||
vllm: false,
|
||||
llama_cpp: false,
|
||||
});
|
||||
});
|
||||
return () => {
|
||||
controller.abort();
|
||||
// An answer still in flight was dropped: let the next run ask again.
|
||||
if (lastProbe?.key === key && !lastProbe.done) lastProbe = null;
|
||||
};
|
||||
}, [
|
||||
active,
|
||||
selectedModel,
|
||||
capabilityFor,
|
||||
token,
|
||||
setDrafterCapability,
|
||||
retry,
|
||||
]);
|
||||
}
|
||||
|
|
@ -35,6 +35,8 @@ export {
|
|||
useTrainingUnloadGuard,
|
||||
} from "./hooks/use-training-unload-guard";
|
||||
export { useMaxStepsEpochsToggle } from "./hooks/use-max-steps-epochs-toggle";
|
||||
export { useDrafterCapability } from "./hooks/use-drafter-capability";
|
||||
export { drafterEligible } from "./lib/drafter-config";
|
||||
export { HfDatasetSubsetSplitSelectors } from "./components/hf-dataset-subset-split-selectors";
|
||||
export { useDatasetPreviewDialogStore } from "./stores/dataset-preview-dialog-store";
|
||||
export {
|
||||
|
|
|
|||
137
studio/frontend/src/features/training/lib/drafter-config.ts
Normal file
137
studio/frontend/src/features/training/lib/drafter-config.ts
Normal file
|
|
@ -0,0 +1,137 @@
|
|||
// SPDX-License-Identifier: AGPL-3.0-only
|
||||
// Copyright 2026-present the Unsloth AI Inc. team. All rights reserved. See /studio/LICENSE.AGPL-3.0
|
||||
|
||||
import { DEFAULT_HYPERPARAMS } from "@/config/training";
|
||||
import type { DrafterTrainingRequest } from "../types/api";
|
||||
import type {
|
||||
DrafterDataSource,
|
||||
DrafterStrategy,
|
||||
TrainingConfigState,
|
||||
} from "../types/config";
|
||||
|
||||
export type DrafterState = Pick<
|
||||
TrainingConfigState,
|
||||
| "drafterEnabled"
|
||||
| "drafterStrategy"
|
||||
| "drafterDataSource"
|
||||
| "drafterMaxExamples"
|
||||
| "drafterEpochs"
|
||||
| "drafterLearningRate"
|
||||
| "drafterDraftSteps"
|
||||
>;
|
||||
|
||||
export const DRAFTER_DEFAULTS: DrafterState = {
|
||||
drafterEnabled: DEFAULT_HYPERPARAMS.drafterEnabled,
|
||||
drafterStrategy: DEFAULT_HYPERPARAMS.drafterStrategy,
|
||||
drafterDataSource: DEFAULT_HYPERPARAMS.drafterDataSource,
|
||||
drafterMaxExamples: DEFAULT_HYPERPARAMS.drafterMaxExamples,
|
||||
drafterEpochs: DEFAULT_HYPERPARAMS.drafterEpochs,
|
||||
drafterLearningRate: DEFAULT_HYPERPARAMS.drafterLearningRate,
|
||||
drafterDraftSteps: DEFAULT_HYPERPARAMS.drafterDraftSteps,
|
||||
};
|
||||
|
||||
// Backend bounds (models/training.py DrafterTrainingConfig): a half-typed field must not 422 the Start.
|
||||
const MAX_EXAMPLES = [16, 100000] as const;
|
||||
const EPOCHS = [0.1, 20] as const;
|
||||
const DRAFT_STEPS = [1, 8] as const;
|
||||
|
||||
function clamp(value: number, [lo, hi]: readonly [number, number]): number {
|
||||
return Math.min(Math.max(value, lo), hi);
|
||||
}
|
||||
|
||||
export function isDrafterStrategy(value: unknown): value is DrafterStrategy {
|
||||
return value === "auto" || value === "mtp" || value === "eagle3";
|
||||
}
|
||||
|
||||
export function isDrafterDataSource(
|
||||
value: unknown,
|
||||
): value is DrafterDataSource {
|
||||
return value === "dataset" || value === "regenerate";
|
||||
}
|
||||
|
||||
function finiteOr(value: unknown, fallback: number): number {
|
||||
const n = Number(value);
|
||||
return value !== null && value !== "" && Number.isFinite(n) ? n : fallback;
|
||||
}
|
||||
|
||||
export function normalizeDrafterMaxExamples(value: unknown): number {
|
||||
return Math.floor(
|
||||
clamp(finiteOr(value, DRAFTER_DEFAULTS.drafterMaxExamples), MAX_EXAMPLES),
|
||||
);
|
||||
}
|
||||
|
||||
export function normalizeDrafterEpochs(value: unknown): number {
|
||||
return clamp(finiteOr(value, DRAFTER_DEFAULTS.drafterEpochs), EPOCHS);
|
||||
}
|
||||
|
||||
export function normalizeDrafterDraftSteps(value: unknown): number {
|
||||
return Math.floor(
|
||||
clamp(finiteOr(value, DRAFTER_DEFAULTS.drafterDraftSteps), DRAFT_STEPS),
|
||||
);
|
||||
}
|
||||
|
||||
export function normalizeDrafterLearningRate(value: unknown): number | null {
|
||||
const n = Number(value);
|
||||
return value !== null && value !== "" && Number.isFinite(n) && n > 0
|
||||
? n
|
||||
: null;
|
||||
}
|
||||
|
||||
/** State from a saved run's / YAML file's `drafter` block; absent or malformed = feature off. */
|
||||
export function drafterStateFrom(value: unknown): DrafterState {
|
||||
if (typeof value !== "object" || value === null)
|
||||
return { ...DRAFTER_DEFAULTS };
|
||||
const v = value as Record<string, unknown>;
|
||||
return {
|
||||
drafterEnabled: v.enabled === true,
|
||||
drafterStrategy: isDrafterStrategy(v.strategy)
|
||||
? v.strategy
|
||||
: DRAFTER_DEFAULTS.drafterStrategy,
|
||||
drafterDataSource: isDrafterDataSource(v.data_source)
|
||||
? v.data_source
|
||||
: DRAFTER_DEFAULTS.drafterDataSource,
|
||||
drafterMaxExamples: normalizeDrafterMaxExamples(v.max_examples),
|
||||
drafterEpochs: normalizeDrafterEpochs(v.epochs),
|
||||
drafterLearningRate: normalizeDrafterLearningRate(v.learning_rate),
|
||||
drafterDraftSteps: normalizeDrafterDraftSteps(v.draft_steps),
|
||||
};
|
||||
}
|
||||
|
||||
/** The request block for these settings, enabled or not (YAML keeps the user's settings either way). */
|
||||
export function drafterRequestFrom(
|
||||
state: DrafterState,
|
||||
): DrafterTrainingRequest {
|
||||
return {
|
||||
enabled: state.drafterEnabled,
|
||||
strategy: state.drafterStrategy,
|
||||
data_source: state.drafterDataSource,
|
||||
max_examples: normalizeDrafterMaxExamples(state.drafterMaxExamples),
|
||||
epochs: normalizeDrafterEpochs(state.drafterEpochs),
|
||||
learning_rate: normalizeDrafterLearningRate(state.drafterLearningRate),
|
||||
draft_steps: normalizeDrafterDraftSteps(state.drafterDraftSteps),
|
||||
};
|
||||
}
|
||||
|
||||
/** Runs the backend's drafter phase cannot take: embeddings, decision models, CPT, and image / audio fine-tunes. */
|
||||
export function drafterEligible(
|
||||
config: Pick<
|
||||
TrainingConfigState,
|
||||
| "modelType"
|
||||
| "isEmbeddingModel"
|
||||
| "trainingMethod"
|
||||
| "isVisionModel"
|
||||
| "isDatasetImage"
|
||||
| "isAudioModel"
|
||||
| "isDatasetAudio"
|
||||
>,
|
||||
): boolean {
|
||||
return (
|
||||
config.modelType !== "decision" &&
|
||||
config.modelType !== "embeddings" &&
|
||||
!config.isEmbeddingModel &&
|
||||
config.trainingMethod !== "cpt" &&
|
||||
// A vision / audio model on a text dataset trains the text path, which the drafter supports.
|
||||
!(config.isVisionModel && config.isDatasetImage === true) &&
|
||||
!(config.isAudioModel && config.isDatasetAudio)
|
||||
);
|
||||
}
|
||||
|
|
@ -4,6 +4,7 @@
|
|||
import * as yaml from "js-yaml";
|
||||
import type { BackendModelConfig } from "../api/models-api";
|
||||
import type { TrainingConfigState } from "../types/config";
|
||||
import { drafterRequestFrom } from "./drafter-config";
|
||||
|
||||
const EXPECTED_TOP_KEYS = new Set(["training", "lora", "logging", "inference"]);
|
||||
|
||||
|
|
@ -102,6 +103,10 @@ export function serializeConfigToYaml(
|
|||
optim: state.optimizerType,
|
||||
lr_scheduler_type: state.lrSchedulerType,
|
||||
};
|
||||
// Only when on, so a file exported without the feature reads exactly as before.
|
||||
if (state.drafterEnabled) {
|
||||
training.drafter = drafterRequestFrom(state);
|
||||
}
|
||||
|
||||
if (includeVisionImageSize) {
|
||||
training.vision_image_size = state.visionImageSize;
|
||||
|
|
|
|||
|
|
@ -19,6 +19,7 @@ import type {
|
|||
TrainingConfigStore,
|
||||
TrainingMethodProvenance,
|
||||
} from "../types/config";
|
||||
import { drafterStateFrom } from "../lib/drafter-config";
|
||||
import {
|
||||
createHfBrowseDatasetSelection,
|
||||
createUploadBrowseDatasetSelection,
|
||||
|
|
@ -26,7 +27,7 @@ import {
|
|||
} from "./training-config-policy";
|
||||
|
||||
export const TRAINING_CONFIG_PERSISTENCE_NAME = "unsloth_training_config_v1";
|
||||
export const TRAINING_CONFIG_PERSISTENCE_VERSION = 22;
|
||||
export const TRAINING_CONFIG_PERSISTENCE_VERSION = 23;
|
||||
|
||||
const NON_PERSISTED_STATE_KEYS: ReadonlySet<keyof TrainingConfigState> =
|
||||
new Set([
|
||||
|
|
@ -45,6 +46,7 @@ const NON_PERSISTED_STATE_KEYS: ReadonlySet<keyof TrainingConfigState> =
|
|||
"decisionLayout",
|
||||
"s3Config",
|
||||
"wandbToken",
|
||||
"drafterCapability",
|
||||
]);
|
||||
|
||||
export function partializeTrainingConfig(
|
||||
|
|
@ -291,6 +293,27 @@ function migrateThroughVersion22(
|
|||
}
|
||||
}
|
||||
|
||||
// Drafter training arrived in 23: older state has no drafter keys, and a hand-edited or
|
||||
// partially written one must never turn the phase on.
|
||||
function migrateThroughVersion23(
|
||||
state: PersistedTrainingConfig,
|
||||
version: number,
|
||||
): void {
|
||||
if (version >= 23) return;
|
||||
Object.assign(
|
||||
state,
|
||||
drafterStateFrom({
|
||||
enabled: state.drafterEnabled,
|
||||
strategy: state.drafterStrategy,
|
||||
data_source: state.drafterDataSource,
|
||||
max_examples: state.drafterMaxExamples,
|
||||
epochs: state.drafterEpochs,
|
||||
learning_rate: state.drafterLearningRate,
|
||||
draft_steps: state.drafterDraftSteps,
|
||||
}),
|
||||
);
|
||||
}
|
||||
|
||||
function isDatasetFormat(value: unknown): value is DatasetFormat {
|
||||
return (
|
||||
value === "auto" ||
|
||||
|
|
@ -391,6 +414,7 @@ export function migrateTrainingConfig(
|
|||
migrateThroughVersion19(state, version);
|
||||
migrateThroughVersion21(state, version);
|
||||
migrateThroughVersion22(state, version);
|
||||
migrateThroughVersion23(state, version);
|
||||
return state as unknown as TrainingConfigStore;
|
||||
}
|
||||
|
||||
|
|
|
|||
|
|
@ -110,6 +110,7 @@ export const initialTrainingConfigState: TrainingConfigState = {
|
|||
isDatasetAudio: false,
|
||||
datasetCheckFailed: false,
|
||||
maxPositionEmbeddings: null,
|
||||
drafterCapability: null,
|
||||
...DEFAULT_HYPERPARAMS,
|
||||
};
|
||||
export function hasSeparateStreamingEvalSplit(
|
||||
|
|
|
|||
|
|
@ -22,6 +22,7 @@ import {
|
|||
} from "../api/models-api";
|
||||
import type { BackendModelConfig, DecisionCheckpoint } from "../api/models-api";
|
||||
import { cacheReferenceMatchesSelection } from "../lib/cache-reference";
|
||||
import { drafterStateFrom } from "../lib/drafter-config";
|
||||
import {
|
||||
createDatasetCacheUsabilityIdentity,
|
||||
datasetCacheUsabilityIdentitiesEqual,
|
||||
|
|
@ -1610,6 +1611,20 @@ export const useTrainingConfigStore = create<TrainingConfigStore>()(
|
|||
},
|
||||
setEarlyStoppingPatience: (earlyStoppingPatience) =>
|
||||
setUserEdit({ earlyStoppingPatience }),
|
||||
setDrafterEnabled: (drafterEnabled) => setUserEdit({ drafterEnabled }),
|
||||
setDrafterStrategy: (drafterStrategy) =>
|
||||
setUserEdit({ drafterStrategy }),
|
||||
setDrafterDataSource: (drafterDataSource) =>
|
||||
setUserEdit({ drafterDataSource }),
|
||||
setDrafterMaxExamples: (drafterMaxExamples) =>
|
||||
setUserEdit({ drafterMaxExamples }),
|
||||
setDrafterEpochs: (drafterEpochs) => setUserEdit({ drafterEpochs }),
|
||||
setDrafterLearningRate: (drafterLearningRate) =>
|
||||
setUserEdit({ drafterLearningRate }),
|
||||
setDrafterDraftSteps: (drafterDraftSteps) =>
|
||||
setUserEdit({ drafterDraftSteps }),
|
||||
setDrafterCapability: (drafterCapability) =>
|
||||
set({ drafterCapability }),
|
||||
setPacking: (packing) => setUserEdit({ packing }),
|
||||
setTrainOnCompletions: (trainOnCompletions) => {
|
||||
_trainOnCompletionsManuallySet = true;
|
||||
|
|
@ -1671,6 +1686,7 @@ export const useTrainingConfigStore = create<TrainingConfigStore>()(
|
|||
earlyStoppingPatience: earlyStoppingPatienceFrom(
|
||||
config.early_stopping_patience,
|
||||
),
|
||||
...drafterStateFrom(config.drafter),
|
||||
});
|
||||
// Fetch capabilities without replacing the saved recipe.
|
||||
loadAndApplyModelDefaults(selections.selectedModel, {
|
||||
|
|
@ -1717,6 +1733,7 @@ export const useTrainingConfigStore = create<TrainingConfigStore>()(
|
|||
config.training ?? {},
|
||||
"early_stopping_patience",
|
||||
);
|
||||
const importsDrafter = Object.hasOwn(config.training ?? {}, "drafter");
|
||||
setUserEdit((state) => {
|
||||
const importsCompletionsInCpt =
|
||||
state.trainingMethod === "cpt" &&
|
||||
|
|
@ -1730,6 +1747,9 @@ export const useTrainingConfigStore = create<TrainingConfigStore>()(
|
|||
),
|
||||
}
|
||||
: {}),
|
||||
...(importsDrafter
|
||||
? drafterStateFrom(config.training?.drafter)
|
||||
: {}),
|
||||
...(patch.trainOnCompletions !== undefined
|
||||
? { trainOnCompletionsDefaultPendingFor: null }
|
||||
: {}),
|
||||
|
|
|
|||
|
|
@ -85,6 +85,31 @@ export interface TrainingStartRequest {
|
|||
enable_tensorboard: boolean;
|
||||
tensorboard_dir: string | null;
|
||||
resume_from_checkpoint?: string | null;
|
||||
/** Omitted unless the user turned drafter training on (requests stay byte-identical otherwise). */
|
||||
drafter?: DrafterTrainingRequest;
|
||||
}
|
||||
|
||||
export interface DrafterTrainingRequest {
|
||||
enabled: boolean;
|
||||
strategy: "auto" | "mtp" | "eagle3";
|
||||
data_source: "dataset" | "regenerate";
|
||||
max_examples: number;
|
||||
epochs: number;
|
||||
learning_rate: number | null;
|
||||
draft_steps: number;
|
||||
}
|
||||
|
||||
/** GET /api/train/drafter-capability: which drafter this model can train, and where it runs. */
|
||||
export interface DrafterCapability {
|
||||
model_name: string;
|
||||
has_native_mtp: boolean;
|
||||
strategy: "mtp" | "eagle3" | null;
|
||||
supported: boolean;
|
||||
reason: string | null;
|
||||
vllm: boolean;
|
||||
llama_cpp: boolean;
|
||||
/** The probe could not run (timeout, crash): retried, never a refusal. */
|
||||
inconclusive?: boolean;
|
||||
}
|
||||
|
||||
export interface TrainingStartResponse {
|
||||
|
|
|
|||
|
|
@ -15,6 +15,7 @@ import type {
|
|||
DecisionCheckpoint,
|
||||
DecisionLayout,
|
||||
} from "../api/models-api";
|
||||
import type { DrafterCapability } from "./api";
|
||||
|
||||
export type LoraVariant = "lora" | "rslora" | "loftq" | "dora";
|
||||
|
||||
|
|
@ -63,6 +64,11 @@ export interface TrainingMethodProvenance {
|
|||
/** Column-to-role mapping, e.g. { "problem": "user", "solution": "assistant", "context": "system" } */
|
||||
export type DatasetManualMapping = Record<string, string>;
|
||||
|
||||
/** "auto" retrains a native MTP head when the model has one, else trains an EAGLE-3 drafter. */
|
||||
export type DrafterStrategy = "auto" | "mtp" | "eagle3";
|
||||
/** "dataset" trains on the dataset's answers; "regenerate" on the fine-tuned model's own answers. */
|
||||
export type DrafterDataSource = "dataset" | "regenerate";
|
||||
|
||||
/** Decoder layers kept in host RAM during LoRA training: a count (0 = off) or "auto". */
|
||||
export type OffloadLayers = number | "auto";
|
||||
export type PrefetchDepth = number | "auto";
|
||||
|
|
@ -125,6 +131,17 @@ export interface TrainingConfigState {
|
|||
evalSteps: number;
|
||||
/** Evaluations without a lower eval loss before the run stops; 0 = off. */
|
||||
earlyStoppingPatience: number;
|
||||
/** Train a speculative-decoding drafter (MTP head or EAGLE-3) after fine-tuning. */
|
||||
drafterEnabled: boolean;
|
||||
drafterStrategy: DrafterStrategy;
|
||||
drafterDataSource: DrafterDataSource;
|
||||
drafterMaxExamples: number;
|
||||
drafterEpochs: number;
|
||||
/** null = the backend's default for the resolved strategy. */
|
||||
drafterLearningRate: number | null;
|
||||
drafterDraftSteps: number;
|
||||
/** Last /api/train/drafter-capability answer (its `model_name` says which model it is for). */
|
||||
drafterCapability: DrafterCapability | null;
|
||||
packing: boolean;
|
||||
trainOnCompletions: boolean;
|
||||
gradientCheckpointing: GradientCheckpointing;
|
||||
|
|
@ -267,6 +284,14 @@ export interface TrainingConfigActions {
|
|||
setSaveSteps: (value: number) => void;
|
||||
setEvalSteps: (value: number) => void;
|
||||
setEarlyStoppingPatience: (value: number) => void;
|
||||
setDrafterEnabled: (value: boolean) => void;
|
||||
setDrafterStrategy: (value: DrafterStrategy) => void;
|
||||
setDrafterDataSource: (value: DrafterDataSource) => void;
|
||||
setDrafterMaxExamples: (value: number) => void;
|
||||
setDrafterEpochs: (value: number) => void;
|
||||
setDrafterLearningRate: (value: number | null) => void;
|
||||
setDrafterDraftSteps: (value: number) => void;
|
||||
setDrafterCapability: (value: DrafterCapability | null) => void;
|
||||
setPacking: (value: boolean) => void;
|
||||
setTrainOnCompletions: (value: boolean) => void;
|
||||
setGradientCheckpointing: (value: GradientCheckpointing) => void;
|
||||
|
|
|
|||
|
|
@ -11,6 +11,8 @@ export type TrainingPhase =
|
|||
| "training"
|
||||
// Steps done, worker still saving. Non-terminal: 100% is not success.
|
||||
| "finalizing"
|
||||
// SFT saved; training the speculative-decoding drafter. Non-terminal.
|
||||
| "training_drafter"
|
||||
| "completed"
|
||||
| "error"
|
||||
| "stopped";
|
||||
|
|
|
|||
|
|
@ -3609,6 +3609,21 @@ export const ar = {
|
|||
"يُستخدم في أسماء مجلدات مخرجات التدريب والقيم الافتراضية للتصدير والسجل.",
|
||||
loraSettings: "إعدادات LoRA",
|
||||
trainingHyperparameters: "المعلمات الفائقة للتدريب",
|
||||
drafterSettings: "مسودّة فك الترميز التخميني",
|
||||
drafterTrain: "تدريب مسودّة فك الترميز التخميني",
|
||||
drafterTrainTooltip: "يدرّب رأس مسودة صغيرًا بعد الضبط الدقيق لتسريع الاستدلال في llama.cpp وvLLM؛ المخرجات لا تتغير.",
|
||||
drafterChecking: "جارٍ فحص النموذج...",
|
||||
drafterUnavailable: "غير متاح لهذا النموذج: {reason}",
|
||||
drafterRetrainMtp: "يعيد تدريب رأس MTP لهذا النموذج",
|
||||
drafterEagle3: "يدرّب مسودّة EAGLE-3 (لا يملك هذا النموذج رأس MTP)",
|
||||
drafterDataSource: "بيانات التدريب",
|
||||
drafterDataSourceDataset: "إجابات مجموعة البيانات",
|
||||
drafterDataSourceRegenerate: "إجابات النموذج نفسه (أبطأ، أفضل)",
|
||||
drafterMaxExamples: "الأمثلة",
|
||||
drafterEpochs: "الحقب",
|
||||
drafterLearningRate: "معدل التعلم",
|
||||
drafterLearningRateDefault: "افتراضي",
|
||||
drafterDraftSteps: "رموز المسودة",
|
||||
maxSteps: "الحد الأقصى للخطوات",
|
||||
epochs: "الحقب (Epochs)",
|
||||
useMaxSteps: "استخدام الحد الأقصى للخطوات",
|
||||
|
|
@ -3954,6 +3969,7 @@ export const ar = {
|
|||
configuring: "جارٍ الإعداد",
|
||||
training: "قيد التدريب",
|
||||
finalizing: "جارٍ حفظ النموذج",
|
||||
trainingDrafter: "جارٍ تدريب المسودّة",
|
||||
completed: "مكتمل",
|
||||
error: "خطأ",
|
||||
stopped: "متوقف",
|
||||
|
|
|
|||
|
|
@ -3664,6 +3664,21 @@ export const de = {
|
|||
"Wird für Namen der Trainingsausgabe-Ordner, Export-Standardwerte und den Verlauf verwendet.",
|
||||
loraSettings: "LoRA-Einstellungen",
|
||||
trainingHyperparameters: "Trainings-Hyperparameter",
|
||||
drafterSettings: "Speculative-Decoding-Drafter",
|
||||
drafterTrain: "Speculative-Decoding-Drafter trainieren",
|
||||
drafterTrainTooltip: "Trainiert nach dem Fine-Tuning einen kleinen Draft-Kopf, damit die Inferenz in llama.cpp und vLLM schneller läuft; die Ausgaben bleiben gleich.",
|
||||
drafterChecking: "Modell wird geprüft...",
|
||||
drafterUnavailable: "Für dieses Modell nicht verfügbar: {reason}",
|
||||
drafterRetrainMtp: "Trainiert den MTP-Kopf dieses Modells neu",
|
||||
drafterEagle3: "Trainiert einen EAGLE-3-Drafter (dieses Modell hat keinen MTP-Kopf)",
|
||||
drafterDataSource: "Trainingsdaten",
|
||||
drafterDataSourceDataset: "Antworten aus dem Datensatz",
|
||||
drafterDataSourceRegenerate: "Eigene Antworten des Modells (langsamer, besser)",
|
||||
drafterMaxExamples: "Beispiele",
|
||||
drafterEpochs: "Epochen",
|
||||
drafterLearningRate: "Lernrate",
|
||||
drafterLearningRateDefault: "Standard",
|
||||
drafterDraftSteps: "Draft-Tokens",
|
||||
maxSteps: "Max. Schritte",
|
||||
epochs: "Epochen",
|
||||
useMaxSteps: "Max. Schritte verwenden",
|
||||
|
|
@ -4027,6 +4042,7 @@ export const de = {
|
|||
configuring: "Wird konfiguriert",
|
||||
training: "Training",
|
||||
finalizing: "Modell wird gespeichert",
|
||||
trainingDrafter: "Drafter wird trainiert",
|
||||
completed: "Abgeschlossen",
|
||||
error: "Fehler",
|
||||
stopped: "Gestoppt",
|
||||
|
|
|
|||
|
|
@ -3648,6 +3648,21 @@ export const en = {
|
|||
"Used in training output folder names, export defaults, and history.",
|
||||
loraSettings: "LoRA Settings",
|
||||
trainingHyperparameters: "Training Hyperparameters",
|
||||
drafterSettings: "Speculative Decoding Drafter",
|
||||
drafterTrain: "Train a speculative decoding drafter",
|
||||
drafterTrainTooltip: "Trains a small draft head after fine-tuning so inference runs faster in llama.cpp and vLLM; outputs are unchanged.",
|
||||
drafterChecking: "Checking this model...",
|
||||
drafterUnavailable: "Not available for this model: {reason}",
|
||||
drafterRetrainMtp: "Retrains this model's MTP head",
|
||||
drafterEagle3: "Trains an EAGLE-3 drafter (this model has no MTP head)",
|
||||
drafterDataSource: "Training data",
|
||||
drafterDataSourceDataset: "Dataset answers",
|
||||
drafterDataSourceRegenerate: "Model's own answers (slower, better)",
|
||||
drafterMaxExamples: "Examples",
|
||||
drafterEpochs: "Epochs",
|
||||
drafterLearningRate: "Learning rate",
|
||||
drafterLearningRateDefault: "Default",
|
||||
drafterDraftSteps: "Draft tokens",
|
||||
maxSteps: "Max Steps",
|
||||
epochs: "Epochs",
|
||||
useMaxSteps: "Use Max Steps",
|
||||
|
|
@ -3993,6 +4008,7 @@ export const en = {
|
|||
configuring: "Configuring",
|
||||
training: "Training",
|
||||
finalizing: "Saving model",
|
||||
trainingDrafter: "Training drafter",
|
||||
completed: "Completed",
|
||||
error: "Error",
|
||||
stopped: "Stopped",
|
||||
|
|
|
|||
|
|
@ -3660,6 +3660,21 @@ export const es = {
|
|||
"Se usa en los nombres de las carpetas de salida del entrenamiento, los valores predeterminados de exportación y el historial.",
|
||||
loraSettings: "Configuración de LoRA",
|
||||
trainingHyperparameters: "Hiperparámetros de entrenamiento",
|
||||
drafterSettings: "Drafter de decodificación especulativa",
|
||||
drafterTrain: "Entrenar un drafter de decodificación especulativa",
|
||||
drafterTrainTooltip: "Entrena una pequeña cabeza de borrador tras el ajuste fino para que la inferencia sea más rápida en llama.cpp y vLLM; las salidas no cambian.",
|
||||
drafterChecking: "Comprobando este modelo...",
|
||||
drafterUnavailable: "No disponible para este modelo: {reason}",
|
||||
drafterRetrainMtp: "Reentrena la cabeza MTP de este modelo",
|
||||
drafterEagle3: "Entrena un drafter EAGLE-3 (este modelo no tiene cabeza MTP)",
|
||||
drafterDataSource: "Datos de entrenamiento",
|
||||
drafterDataSourceDataset: "Respuestas del dataset",
|
||||
drafterDataSourceRegenerate: "Respuestas del propio modelo (más lento, mejor)",
|
||||
drafterMaxExamples: "Ejemplos",
|
||||
drafterEpochs: "Épocas",
|
||||
drafterLearningRate: "Tasa de aprendizaje",
|
||||
drafterLearningRateDefault: "Predeterminado",
|
||||
drafterDraftSteps: "Tokens de borrador",
|
||||
maxSteps: "Pasos máximos",
|
||||
epochs: "Épocas",
|
||||
useMaxSteps: "Usar pasos máximos",
|
||||
|
|
@ -4024,6 +4039,7 @@ export const es = {
|
|||
configuring: "Configurando",
|
||||
training: "Entrenando",
|
||||
finalizing: "Guardando modelo",
|
||||
trainingDrafter: "Entrenando drafter",
|
||||
completed: "Completado",
|
||||
error: "Error",
|
||||
stopped: "Detenido",
|
||||
|
|
|
|||
|
|
@ -3673,6 +3673,21 @@ export const fr = {
|
|||
"Utilisé dans les noms des dossiers de sortie d'entraînement, les valeurs d'export par défaut et l'historique.",
|
||||
loraSettings: "Paramètres LoRA",
|
||||
trainingHyperparameters: "Hyperparamètres d'entraînement",
|
||||
drafterSettings: "Drafter de décodage spéculatif",
|
||||
drafterTrain: "Entraîner un drafter de décodage spéculatif",
|
||||
drafterTrainTooltip: "Entraîne une petite tête de brouillon après le fine-tuning pour accélérer l'inférence dans llama.cpp et vLLM ; les sorties sont inchangées.",
|
||||
drafterChecking: "Vérification du modèle...",
|
||||
drafterUnavailable: "Indisponible pour ce modèle : {reason}",
|
||||
drafterRetrainMtp: "Réentraîne la tête MTP de ce modèle",
|
||||
drafterEagle3: "Entraîne un drafter EAGLE-3 (ce modèle n'a pas de tête MTP)",
|
||||
drafterDataSource: "Données d'entraînement",
|
||||
drafterDataSourceDataset: "Réponses du dataset",
|
||||
drafterDataSourceRegenerate: "Réponses du modèle lui-même (plus lent, meilleur)",
|
||||
drafterMaxExamples: "Exemples",
|
||||
drafterEpochs: "Époques",
|
||||
drafterLearningRate: "Taux d'apprentissage",
|
||||
drafterLearningRateDefault: "Par défaut",
|
||||
drafterDraftSteps: "Tokens de brouillon",
|
||||
maxSteps: "Nombre max d'étapes",
|
||||
epochs: "Époques",
|
||||
useMaxSteps: "Utiliser le nombre max d'étapes",
|
||||
|
|
@ -4038,6 +4053,7 @@ export const fr = {
|
|||
configuring: "Configuration",
|
||||
training: "Entraînement",
|
||||
finalizing: "Enregistrement du modèle",
|
||||
trainingDrafter: "Entraînement du drafter",
|
||||
completed: "Terminé",
|
||||
error: "Erreur",
|
||||
stopped: "Arrêté",
|
||||
|
|
|
|||
|
|
@ -3717,6 +3717,21 @@ export const he = {
|
|||
"משמש בשמות תיקיות פלט האימון, ברירות מחדל של ייצוא והיסטוריה.",
|
||||
loraSettings: "הגדרות LoRA",
|
||||
trainingHyperparameters: "היפר-פרמטרים של אימון",
|
||||
drafterSettings: "מנסח לפענוח ספקולטיבי",
|
||||
drafterTrain: "אימון מנסח לפענוח ספקולטיבי",
|
||||
drafterTrainTooltip: "מאמן ראש טיוטה קטן אחרי הכוונון כדי שההסקה ב-llama.cpp וב-vLLM תהיה מהירה יותר; הפלט לא משתנה.",
|
||||
drafterChecking: "בודק את המודל...",
|
||||
drafterUnavailable: "לא זמין למודל הזה: {reason}",
|
||||
drafterRetrainMtp: "מאמן מחדש את ראש ה-MTP של המודל",
|
||||
drafterEagle3: "מאמן מנסח EAGLE-3 (למודל אין ראש MTP)",
|
||||
drafterDataSource: "נתוני אימון",
|
||||
drafterDataSourceDataset: "תשובות ממערך הנתונים",
|
||||
drafterDataSourceRegenerate: "התשובות של המודל עצמו (איטי יותר, טוב יותר)",
|
||||
drafterMaxExamples: "דוגמאות",
|
||||
drafterEpochs: "אפוקים",
|
||||
drafterLearningRate: "קצב למידה",
|
||||
drafterLearningRateDefault: "ברירת מחדל",
|
||||
drafterDraftSteps: "טוקני טיוטה",
|
||||
maxSteps: "מקסימום צעדים (Max Steps)",
|
||||
epochs: "תקופות (Epochs)",
|
||||
useMaxSteps: "השתמש ב-Max Steps",
|
||||
|
|
@ -4059,6 +4074,7 @@ export const he = {
|
|||
configuring: "מגדיר",
|
||||
training: "מאמן",
|
||||
finalizing: "שומר מודל",
|
||||
trainingDrafter: "מאמן מנסח",
|
||||
completed: "הושלם",
|
||||
error: "שגיאה",
|
||||
stopped: "נעצר",
|
||||
|
|
|
|||
|
|
@ -3619,6 +3619,21 @@ export const hi = {
|
|||
"ट्रेनिंग आउटपुट फ़ोल्डर नामों, एक्सपोर्ट डिफ़ॉल्ट, और इतिहास में उपयोग किया जाता है।",
|
||||
loraSettings: "LoRA सेटिंग्स",
|
||||
trainingHyperparameters: "ट्रेनिंग हाइपरपैरामीटर",
|
||||
drafterSettings: "स्पेक्युलेटिव डिकोडिंग ड्राफ्टर",
|
||||
drafterTrain: "स्पेक्युलेटिव डिकोडिंग ड्राफ्टर ट्रेन करें",
|
||||
drafterTrainTooltip: "फाइन-ट्यूनिंग के बाद एक छोटा ड्राफ्ट हेड ट्रेन करता है ताकि llama.cpp और vLLM में इनफ़रेंस तेज़ चले; आउटपुट नहीं बदलते।",
|
||||
drafterChecking: "मॉडल जाँचा जा रहा है...",
|
||||
drafterUnavailable: "इस मॉडल के लिए उपलब्ध नहीं: {reason}",
|
||||
drafterRetrainMtp: "इस मॉडल का MTP हेड दोबारा ट्रेन करता है",
|
||||
drafterEagle3: "EAGLE-3 ड्राफ्टर ट्रेन करता है (इस मॉडल में MTP हेड नहीं है)",
|
||||
drafterDataSource: "ट्रेनिंग डेटा",
|
||||
drafterDataSourceDataset: "डेटासेट के उत्तर",
|
||||
drafterDataSourceRegenerate: "मॉडल के अपने उत्तर (धीमा, बेहतर)",
|
||||
drafterMaxExamples: "उदाहरण",
|
||||
drafterEpochs: "एपॉक",
|
||||
drafterLearningRate: "लर्निंग रेट",
|
||||
drafterLearningRateDefault: "डिफ़ॉल्ट",
|
||||
drafterDraftSteps: "ड्राफ्ट टोकन",
|
||||
maxSteps: "अधिकतम स्टेप्स",
|
||||
epochs: "एपॉक",
|
||||
useMaxSteps: "अधिकतम स्टेप्स का उपयोग करें",
|
||||
|
|
@ -3965,6 +3980,7 @@ export const hi = {
|
|||
configuring: "कॉन्फ़िगर हो रहा है",
|
||||
training: "ट्रेनिंग हो रही है",
|
||||
finalizing: "मॉडल सेव हो रहा है",
|
||||
trainingDrafter: "ड्राफ्टर ट्रेन हो रहा है",
|
||||
completed: "पूर्ण",
|
||||
error: "त्रुटि",
|
||||
stopped: "रोका गया",
|
||||
|
|
|
|||
|
|
@ -3670,6 +3670,21 @@ export const it = {
|
|||
"Usato nei nomi delle cartelle di output, nei valori predefiniti di esportazione e nella cronologia.",
|
||||
loraSettings: "Impostazioni LoRA",
|
||||
trainingHyperparameters: "Iperparametri di addestramento",
|
||||
drafterSettings: "Drafter per decodifica speculativa",
|
||||
drafterTrain: "Addestra un drafter per decodifica speculativa",
|
||||
drafterTrainTooltip: "Addestra una piccola testa di bozza dopo il fine-tuning così l'inferenza è più veloce in llama.cpp e vLLM; gli output non cambiano.",
|
||||
drafterChecking: "Verifica del modello...",
|
||||
drafterUnavailable: "Non disponibile per questo modello: {reason}",
|
||||
drafterRetrainMtp: "Riaddestra la testa MTP di questo modello",
|
||||
drafterEagle3: "Addestra un drafter EAGLE-3 (questo modello non ha una testa MTP)",
|
||||
drafterDataSource: "Dati di addestramento",
|
||||
drafterDataSourceDataset: "Risposte del dataset",
|
||||
drafterDataSourceRegenerate: "Risposte del modello stesso (più lento, migliore)",
|
||||
drafterMaxExamples: "Esempi",
|
||||
drafterEpochs: "Epoche",
|
||||
drafterLearningRate: "Learning rate",
|
||||
drafterLearningRateDefault: "Predefinito",
|
||||
drafterDraftSteps: "Token di bozza",
|
||||
maxSteps: "Step massimi",
|
||||
epochs: "Epoche",
|
||||
useMaxSteps: "Usa gli step massimi",
|
||||
|
|
@ -4029,6 +4044,7 @@ export const it = {
|
|||
configuring: "Configurazione",
|
||||
training: "Addestramento",
|
||||
finalizing: "Salvataggio del modello",
|
||||
trainingDrafter: "Addestramento del drafter",
|
||||
completed: "Completato",
|
||||
error: "Errore",
|
||||
stopped: "Fermato",
|
||||
|
|
|
|||
|
|
@ -3570,6 +3570,21 @@ export const ja = {
|
|||
projectNameDescription: "トレーニング出力フォルダ名、エクスポートのデフォルト値、および履歴で使用されます。",
|
||||
loraSettings: "LoRA 設定",
|
||||
trainingHyperparameters: "トレーニングハイパーパラメーター",
|
||||
drafterSettings: "投機的デコーディング用ドラフター",
|
||||
drafterTrain: "投機的デコーディング用ドラフターをトレーニング",
|
||||
drafterTrainTooltip: "ファインチューニング後に小さなドラフトヘッドをトレーニングし、llama.cpp と vLLM での推論を高速化します。出力は変わりません。",
|
||||
drafterChecking: "モデルを確認中...",
|
||||
drafterUnavailable: "このモデルでは利用できません: {reason}",
|
||||
drafterRetrainMtp: "このモデルの MTP ヘッドを再トレーニングします",
|
||||
drafterEagle3: "EAGLE-3 ドラフターをトレーニングします (このモデルには MTP ヘッドがありません)",
|
||||
drafterDataSource: "トレーニングデータ",
|
||||
drafterDataSourceDataset: "データセットの回答",
|
||||
drafterDataSourceRegenerate: "モデル自身の回答 (遅いがより良い)",
|
||||
drafterMaxExamples: "サンプル数",
|
||||
drafterEpochs: "エポック",
|
||||
drafterLearningRate: "学習率",
|
||||
drafterLearningRateDefault: "デフォルト",
|
||||
drafterDraftSteps: "ドラフトトークン数",
|
||||
maxSteps: "最大ステップ数",
|
||||
epochs: "エポック数",
|
||||
useMaxSteps: "最大ステップ数を使用",
|
||||
|
|
@ -3901,6 +3916,7 @@ export const ja = {
|
|||
configuring: "構成中",
|
||||
training: "トレーニング中",
|
||||
finalizing: "モデルを保存中",
|
||||
trainingDrafter: "ドラフターをトレーニング中",
|
||||
completed: "完了",
|
||||
error: "エラー",
|
||||
stopped: "停止",
|
||||
|
|
|
|||
|
|
@ -3597,6 +3597,21 @@ export const ko = {
|
|||
"학습 출력 폴더 이름, 내보내기 기본값 및 기록에 사용됩니다.",
|
||||
loraSettings: "LoRA 설정",
|
||||
trainingHyperparameters: "학습 하이퍼파라미터",
|
||||
drafterSettings: "추측 디코딩 드래프터",
|
||||
drafterTrain: "추측 디코딩 드래프터 학습",
|
||||
drafterTrainTooltip: "파인튜닝 후 작은 드래프트 헤드를 학습해 llama.cpp와 vLLM에서 추론을 더 빠르게 합니다. 출력은 바뀌지 않습니다.",
|
||||
drafterChecking: "모델 확인 중...",
|
||||
drafterUnavailable: "이 모델에서는 사용할 수 없음: {reason}",
|
||||
drafterRetrainMtp: "이 모델의 MTP 헤드를 다시 학습합니다",
|
||||
drafterEagle3: "EAGLE-3 드래프터를 학습합니다 (이 모델에는 MTP 헤드가 없음)",
|
||||
drafterDataSource: "학습 데이터",
|
||||
drafterDataSourceDataset: "데이터셋 답변",
|
||||
drafterDataSourceRegenerate: "모델 자체 답변 (느리지만 더 좋음)",
|
||||
drafterMaxExamples: "예제 수",
|
||||
drafterEpochs: "에포크",
|
||||
drafterLearningRate: "학습률",
|
||||
drafterLearningRateDefault: "기본값",
|
||||
drafterDraftSteps: "드래프트 토큰",
|
||||
maxSteps: "최대 스텝",
|
||||
epochs: "에포크",
|
||||
useMaxSteps: "최대 스텝 사용",
|
||||
|
|
@ -3943,6 +3958,7 @@ export const ko = {
|
|||
configuring: "구성 중",
|
||||
training: "학습 중",
|
||||
finalizing: "모델 저장 중",
|
||||
trainingDrafter: "드래프터 학습 중",
|
||||
completed: "완료됨",
|
||||
error: "오류",
|
||||
stopped: "중지됨",
|
||||
|
|
|
|||
|
|
@ -3635,6 +3635,21 @@ export const ptBR = {
|
|||
"Usado nos nomes das pastas de saída do treinamento, nos padrões de exportação e no histórico.",
|
||||
loraSettings: "Configurações do LoRA",
|
||||
trainingHyperparameters: "Hiperparâmetros de Treinamento",
|
||||
drafterSettings: "Drafter de decodificação especulativa",
|
||||
drafterTrain: "Treinar um drafter de decodificação especulativa",
|
||||
drafterTrainTooltip: "Treina uma pequena cabeça de rascunho após o fine-tuning para a inferência ficar mais rápida no llama.cpp e no vLLM; as saídas não mudam.",
|
||||
drafterChecking: "Verificando este modelo...",
|
||||
drafterUnavailable: "Indisponível para este modelo: {reason}",
|
||||
drafterRetrainMtp: "Retreina a cabeça MTP deste modelo",
|
||||
drafterEagle3: "Treina um drafter EAGLE-3 (este modelo não tem cabeça MTP)",
|
||||
drafterDataSource: "Dados de treinamento",
|
||||
drafterDataSourceDataset: "Respostas do dataset",
|
||||
drafterDataSourceRegenerate: "Respostas do próprio modelo (mais lento, melhor)",
|
||||
drafterMaxExamples: "Exemplos",
|
||||
drafterEpochs: "Épocas",
|
||||
drafterLearningRate: "Taxa de aprendizado",
|
||||
drafterLearningRateDefault: "Padrão",
|
||||
drafterDraftSteps: "Tokens de rascunho",
|
||||
maxSteps: "Passos Máximos (Max Steps)",
|
||||
epochs: "Épocas (Epochs)",
|
||||
useMaxSteps: "Usar Passos Máximos",
|
||||
|
|
@ -3987,6 +4002,7 @@ export const ptBR = {
|
|||
configuring: "Configurando",
|
||||
training: "Treinando",
|
||||
finalizing: "Salvando modelo",
|
||||
trainingDrafter: "Treinando drafter",
|
||||
completed: "Concluído",
|
||||
error: "Erro",
|
||||
stopped: "Interrompido",
|
||||
|
|
|
|||
|
|
@ -3635,6 +3635,21 @@ export const ru = {
|
|||
"Используется в именах папок вывода обучения, значениях экспорта по умолчанию и истории.",
|
||||
loraSettings: "Настройки LoRA",
|
||||
trainingHyperparameters: "Гиперпараметры обучения",
|
||||
drafterSettings: "Драфтер для спекулятивного декодирования",
|
||||
drafterTrain: "Обучить драфтер для спекулятивного декодирования",
|
||||
drafterTrainTooltip: "После дообучения обучает небольшую черновую голову, чтобы инференс в llama.cpp и vLLM работал быстрее; ответы не меняются.",
|
||||
drafterChecking: "Проверка модели...",
|
||||
drafterUnavailable: "Недоступно для этой модели: {reason}",
|
||||
drafterRetrainMtp: "Переобучает MTP-голову этой модели",
|
||||
drafterEagle3: "Обучает драфтер EAGLE-3 (у этой модели нет MTP-головы)",
|
||||
drafterDataSource: "Данные для обучения",
|
||||
drafterDataSourceDataset: "Ответы из датасета",
|
||||
drafterDataSourceRegenerate: "Собственные ответы модели (медленнее, лучше)",
|
||||
drafterMaxExamples: "Примеры",
|
||||
drafterEpochs: "Эпохи",
|
||||
drafterLearningRate: "Скорость обучения",
|
||||
drafterLearningRateDefault: "По умолчанию",
|
||||
drafterDraftSteps: "Черновые токены",
|
||||
maxSteps: "Макс. шагов",
|
||||
epochs: "Эпохи",
|
||||
useMaxSteps: "Использовать макс. шаги",
|
||||
|
|
@ -3984,6 +3999,7 @@ export const ru = {
|
|||
configuring: "Настройка",
|
||||
training: "Обучение",
|
||||
finalizing: "Сохранение модели",
|
||||
trainingDrafter: "Обучение драфтера",
|
||||
completed: "Завершено",
|
||||
error: "Ошибка",
|
||||
stopped: "Остановлено",
|
||||
|
|
|
|||
|
|
@ -3839,6 +3839,21 @@ export const sv = {
|
|||
"Används i namn på träningsutdatakataloger, exportstandardvärden och historik.",
|
||||
loraSettings: "LoRA-inställningar",
|
||||
trainingHyperparameters: "Träningshyperparametrar",
|
||||
drafterSettings: "Drafter för spekulativ avkodning",
|
||||
drafterTrain: "Träna en drafter för spekulativ avkodning",
|
||||
drafterTrainTooltip: "Tränar ett litet utkasthuvud efter finjusteringen så att inferensen går snabbare i llama.cpp och vLLM; utdata ändras inte.",
|
||||
drafterChecking: "Kontrollerar modellen...",
|
||||
drafterUnavailable: "Inte tillgängligt för den här modellen: {reason}",
|
||||
drafterRetrainMtp: "Tränar om modellens MTP-huvud",
|
||||
drafterEagle3: "Tränar en EAGLE-3-drafter (modellen saknar MTP-huvud)",
|
||||
drafterDataSource: "Träningsdata",
|
||||
drafterDataSourceDataset: "Svar från datasetet",
|
||||
drafterDataSourceRegenerate: "Modellens egna svar (långsammare, bättre)",
|
||||
drafterMaxExamples: "Exempel",
|
||||
drafterEpochs: "Epoker",
|
||||
drafterLearningRate: "Inlärningstakt",
|
||||
drafterLearningRateDefault: "Standard",
|
||||
drafterDraftSteps: "Utkasttokens",
|
||||
maxSteps: "Maxsteg",
|
||||
epochs: "Epoker",
|
||||
useMaxSteps: "Använd maxsteg",
|
||||
|
|
@ -4191,6 +4206,7 @@ export const sv = {
|
|||
configuring: "Konfigurerar",
|
||||
training: "Tränar",
|
||||
finalizing: "Sparar modell",
|
||||
trainingDrafter: "Tränar drafter",
|
||||
completed: "Slutförd",
|
||||
error: "Fel",
|
||||
stopped: "Stoppad",
|
||||
|
|
|
|||
|
|
@ -3529,6 +3529,21 @@ export const zhCN = {
|
|||
projectNameDescription: "用于训练输出文件夹名称、导出默认值和历史记录。",
|
||||
loraSettings: "LoRA 设置",
|
||||
trainingHyperparameters: "训练超参数",
|
||||
drafterSettings: "推测解码草稿模型",
|
||||
drafterTrain: "训练推测解码草稿模型",
|
||||
drafterTrainTooltip: "微调后训练一个小型草稿头,使 llama.cpp 和 vLLM 中的推理更快;输出保持不变。",
|
||||
drafterChecking: "正在检查模型...",
|
||||
drafterUnavailable: "此模型不可用:{reason}",
|
||||
drafterRetrainMtp: "重新训练此模型的 MTP 头",
|
||||
drafterEagle3: "训练 EAGLE-3 草稿模型(此模型没有 MTP 头)",
|
||||
drafterDataSource: "训练数据",
|
||||
drafterDataSourceDataset: "数据集答案",
|
||||
drafterDataSourceRegenerate: "模型自身的回答(更慢,效果更好)",
|
||||
drafterMaxExamples: "样本数",
|
||||
drafterEpochs: "轮数",
|
||||
drafterLearningRate: "学习率",
|
||||
drafterLearningRateDefault: "默认",
|
||||
drafterDraftSteps: "草稿 token 数",
|
||||
maxSteps: "最大步数",
|
||||
epochs: "轮数",
|
||||
useMaxSteps: "使用最大步数",
|
||||
|
|
@ -3857,6 +3872,7 @@ export const zhCN = {
|
|||
configuring: "配置中",
|
||||
training: "训练中",
|
||||
finalizing: "正在保存模型",
|
||||
trainingDrafter: "正在训练草稿模型",
|
||||
completed: "已完成",
|
||||
error: "错误",
|
||||
stopped: "已停止",
|
||||
|
|
|
|||
|
|
@ -68,7 +68,7 @@ test("migration preserves tuned values while protecting them from model defaults
|
|||
16,
|
||||
);
|
||||
|
||||
assert.equal(TRAINING_CONFIG_PERSISTENCE_VERSION, 22);
|
||||
assert.equal(TRAINING_CONFIG_PERSISTENCE_VERSION, 23);
|
||||
assert.equal(migrated.learningRate, 0.000031);
|
||||
assert.equal(migrated.loraRank, 48);
|
||||
assert.equal(migrated.modelDefaultsAppliedFor, "org/model");
|
||||
|
|
|
|||
209
studio/frontend/tests/training-start-payload-drafter.test.ts
Normal file
209
studio/frontend/tests/training-start-payload-drafter.test.ts
Normal file
|
|
@ -0,0 +1,209 @@
|
|||
// SPDX-License-Identifier: AGPL-3.0-only
|
||||
// Copyright 2026-present the Unsloth AI Inc. team. All rights reserved. See /studio/LICENSE.AGPL-3.0
|
||||
|
||||
import assert from "node:assert/strict";
|
||||
import test from "node:test";
|
||||
|
||||
import { registerBundlerResolver } from "./helpers/kit.ts";
|
||||
|
||||
import type { DrafterCapability } from "../src/features/training/types/api.ts";
|
||||
import type { TrainingConfigState } from "../src/features/training/types/config.ts";
|
||||
|
||||
registerBundlerResolver();
|
||||
const { buildTrainingStartPayload } =
|
||||
await import("../src/features/training/api/mappers.ts");
|
||||
const { initialTrainingConfigState } =
|
||||
await import("../src/features/training/stores/training-config-policy.ts");
|
||||
const {
|
||||
TRAINING_CONFIG_PERSISTENCE_VERSION,
|
||||
migrateTrainingConfig,
|
||||
partializeTrainingConfig,
|
||||
} =
|
||||
await import("../src/features/training/stores/training-config-persistence.ts");
|
||||
const { parseYamlConfig, serializeConfigToYaml } =
|
||||
await import("../src/features/training/lib/yaml-config.ts");
|
||||
const { drafterStateFrom } =
|
||||
await import("../src/features/training/lib/drafter-config.ts");
|
||||
const { phaseColors } =
|
||||
await import("../src/features/studio/sections/progress-section-lib.ts");
|
||||
|
||||
const MODEL = "unsloth/Qwen3-1.7B";
|
||||
|
||||
function capability(patch: Partial<DrafterCapability> = {}): DrafterCapability {
|
||||
return {
|
||||
model_name: MODEL,
|
||||
has_native_mtp: false,
|
||||
strategy: "eagle3",
|
||||
supported: true,
|
||||
reason: null,
|
||||
vllm: true,
|
||||
llama_cpp: true,
|
||||
...patch,
|
||||
};
|
||||
}
|
||||
|
||||
function config(patch: Partial<TrainingConfigState> = {}): TrainingConfigState {
|
||||
return {
|
||||
...initialTrainingConfigState,
|
||||
modelType: "text",
|
||||
selectedModel: MODEL,
|
||||
datasetSource: "huggingface",
|
||||
dataset: "unsloth/test",
|
||||
...patch,
|
||||
};
|
||||
}
|
||||
|
||||
const ON = {
|
||||
drafterEnabled: true,
|
||||
drafterStrategy: "auto",
|
||||
drafterDataSource: "regenerate",
|
||||
drafterMaxExamples: 1500,
|
||||
drafterEpochs: 2,
|
||||
drafterLearningRate: 0.0002,
|
||||
drafterDraftSteps: 4,
|
||||
} as const;
|
||||
|
||||
test("drafter training is off by default and the payload has no drafter key", () => {
|
||||
assert.equal(initialTrainingConfigState.drafterEnabled, false);
|
||||
const payload = buildTrainingStartPayload(config(), null);
|
||||
assert.equal(Object.hasOwn(payload, "drafter"), false);
|
||||
});
|
||||
|
||||
test("a capability check still pending or for another model does not drop a ticked drafter", () => {
|
||||
for (const patch of [
|
||||
{ ...ON },
|
||||
{ ...ON, drafterCapability: capability({ model_name: "other/model" }) },
|
||||
// The probe could not run: the backend re-checks before the drafter phase.
|
||||
{
|
||||
...ON,
|
||||
drafterCapability: capability({ supported: false, inconclusive: true }),
|
||||
},
|
||||
]) {
|
||||
const payload = buildTrainingStartPayload(config(patch), null);
|
||||
assert.equal(Object.hasOwn(payload, "drafter"), true);
|
||||
}
|
||||
});
|
||||
|
||||
test("settings the request cannot carry leave the payload exactly as without the feature", () => {
|
||||
const off = buildTrainingStartPayload(config(), null);
|
||||
const cases: Partial<TrainingConfigState>[] = [
|
||||
// Settings edited but the box unticked.
|
||||
{ ...ON, drafterEnabled: false, drafterCapability: capability() },
|
||||
// Ticked, but the backend said this model cannot train one.
|
||||
{ ...ON, drafterCapability: capability({ supported: false, reason: "x" }) },
|
||||
// Run types without a drafter phase.
|
||||
{ ...ON, drafterCapability: capability(), trainingMethod: "cpt" },
|
||||
{ ...ON, drafterCapability: capability(), isEmbeddingModel: true },
|
||||
];
|
||||
for (const patch of cases) {
|
||||
const payload = buildTrainingStartPayload(config(patch), null);
|
||||
if (patch.trainingMethod === "cpt" || patch.isEmbeddingModel) {
|
||||
assert.equal(Object.hasOwn(payload, "drafter"), false);
|
||||
} else {
|
||||
assert.deepEqual(payload, off);
|
||||
}
|
||||
}
|
||||
const mlx = buildTrainingStartPayload(
|
||||
config({ ...ON, drafterCapability: capability() }),
|
||||
null,
|
||||
{ device_backend: "mlx" } as never,
|
||||
);
|
||||
assert.equal(Object.hasOwn(mlx, "drafter"), false);
|
||||
// Image / audio fine-tunes have no drafter phase; the same models on a text dataset do.
|
||||
for (const patch of [
|
||||
{ isVisionModel: true, isDatasetImage: true },
|
||||
{ isAudioModel: true, isDatasetAudio: true },
|
||||
]) {
|
||||
const media = buildTrainingStartPayload(
|
||||
config({ ...ON, drafterCapability: capability(), ...patch }),
|
||||
null,
|
||||
);
|
||||
assert.equal(Object.hasOwn(media, "drafter"), false);
|
||||
}
|
||||
const text = buildTrainingStartPayload(
|
||||
config({
|
||||
...ON,
|
||||
drafterCapability: capability(),
|
||||
isVisionModel: true,
|
||||
isDatasetImage: false,
|
||||
}),
|
||||
null,
|
||||
);
|
||||
assert.equal(Object.hasOwn(text, "drafter"), true);
|
||||
});
|
||||
|
||||
test("an enabled drafter on a supported model adds only the drafter block", () => {
|
||||
const off = buildTrainingStartPayload(config(), null);
|
||||
const on = buildTrainingStartPayload(
|
||||
config({ ...ON, drafterCapability: capability() }),
|
||||
null,
|
||||
);
|
||||
const { drafter, ...rest } = on;
|
||||
assert.deepEqual(rest, off);
|
||||
assert.deepEqual(drafter, {
|
||||
enabled: true,
|
||||
strategy: "auto",
|
||||
data_source: "regenerate",
|
||||
max_examples: 1500,
|
||||
epochs: 2,
|
||||
learning_rate: 0.0002,
|
||||
draft_steps: 4,
|
||||
});
|
||||
});
|
||||
|
||||
test("half-typed fields are clamped into the backend's bounds", () => {
|
||||
const sent = (patch: Partial<TrainingConfigState>) =>
|
||||
buildTrainingStartPayload(
|
||||
config({ ...ON, drafterCapability: capability(), ...patch }),
|
||||
null,
|
||||
).drafter;
|
||||
assert.equal(sent({ drafterMaxExamples: 3 })?.max_examples, 16);
|
||||
assert.equal(sent({ drafterMaxExamples: 1e9 })?.max_examples, 100000);
|
||||
assert.equal(sent({ drafterEpochs: 0 })?.epochs, 0.1);
|
||||
assert.equal(sent({ drafterDraftSteps: 2.7 })?.draft_steps, 2);
|
||||
assert.equal(sent({ drafterDraftSteps: Number.NaN })?.draft_steps, 3);
|
||||
assert.equal(sent({ drafterLearningRate: -1 })?.learning_rate, null);
|
||||
});
|
||||
|
||||
test("persisted state from before drafter training migrates to the feature off", () => {
|
||||
assert.equal(TRAINING_CONFIG_PERSISTENCE_VERSION, 23);
|
||||
const migrated = migrateTrainingConfig(
|
||||
{ selectedModel: MODEL, trainingMethod: "lora" },
|
||||
22,
|
||||
) as unknown as TrainingConfigState;
|
||||
assert.equal(migrated.drafterEnabled, false);
|
||||
assert.equal(migrated.drafterStrategy, "auto");
|
||||
assert.equal(migrated.drafterMaxExamples, 2000);
|
||||
assert.equal(migrated.drafterLearningRate, null);
|
||||
const malformed = migrateTrainingConfig(
|
||||
{ drafterEnabled: "yes", drafterStrategy: "medusa", drafterDraftSteps: 99 },
|
||||
22,
|
||||
) as unknown as TrainingConfigState;
|
||||
assert.equal(malformed.drafterEnabled, false);
|
||||
assert.equal(malformed.drafterStrategy, "auto");
|
||||
assert.equal(malformed.drafterDraftSteps, 8);
|
||||
});
|
||||
|
||||
test("the capability answer is never persisted, the settings are", () => {
|
||||
const persisted = partializeTrainingConfig({
|
||||
...config({ ...ON, drafterCapability: capability() }),
|
||||
} as never);
|
||||
assert.equal(Object.hasOwn(persisted, "drafterCapability"), false);
|
||||
assert.equal(persisted.drafterEnabled, true);
|
||||
assert.equal(persisted.drafterDataSource, "regenerate");
|
||||
});
|
||||
|
||||
test("YAML round trip keeps drafter settings, and leaves files without it unchanged", () => {
|
||||
const offYaml = serializeConfigToYaml(config(), false);
|
||||
assert.equal(
|
||||
Object.hasOwn(parseYamlConfig(offYaml).training ?? {}, "drafter"),
|
||||
false,
|
||||
);
|
||||
const onYaml = serializeConfigToYaml(config({ ...ON }), false);
|
||||
const restored = drafterStateFrom(parseYamlConfig(onYaml).training?.drafter);
|
||||
assert.deepEqual(restored, { ...ON });
|
||||
});
|
||||
|
||||
test("the drafter phase has a progress colour (labels are typed exhaustively)", () => {
|
||||
assert.ok(phaseColors.training_drafter);
|
||||
});
|
||||
|
|
@ -248,6 +248,15 @@ def __getattr__(name):
|
|||
_zoo_speculative()
|
||||
from unsloth_zoo.speculative import trainer
|
||||
return getattr(trainer, name)
|
||||
if name in ("UnslothEagle3Trainer", "Eagle3TrainingArguments"):
|
||||
speculative = _zoo_speculative()
|
||||
try:
|
||||
return getattr(speculative, name)
|
||||
except AttributeError as error:
|
||||
raise ImportError(
|
||||
"Unsloth: EAGLE-3 drafter training needs a newer unsloth_zoo. "
|
||||
"Update via `pip install --upgrade --no-cache-dir unsloth_zoo`."
|
||||
) from error
|
||||
if name in ("UnslothDSparkTrainer", "DSparkTrainingArguments", "Qwen3DSparkDrafter"):
|
||||
_zoo_speculative()
|
||||
from unsloth_zoo.speculative import dspark
|
||||
|
|
|
|||
Loading…
Add table
Add a link
Reference in a new issue