mirror of
https://github.com/kvcache-ai/ktransformers.git
synced 2026-10-19 02:07:20 +00:00
[docs]: refresh kt inference and sft entry points
Refresh README entry points and add KT SFT Quick Start.
This commit is contained in:
 Peilin Li
 GitHub
parent
24b1941b85
commit
8c634d5dca
4 changed files with 261 additions and 47 deletions
44
README.md
44
README.md
|
|
@ -8,15 +8,16 @@
|
|||
|
||||
</p>
|
||||
<h3>A Flexible Framework for Experiencing Cutting-edge LLM Inference/Fine-tune Optimizations</h3>
|
||||
<strong><a href="#-overview">🎯 Overview</a> | <a href="#-kt-kernel---high-performance-inference-kernels">🚀 kt-kernel</a> | <a href="#-kt-sft---fine-tuning-framework">🎓 kt-sft</a> | <a href="#-citation">🔥 Citation</a> | <a href="https://github.com/kvcache-ai/ktransformers/issues/1921">🚀 Roadmap(2026Q2)</a> </strong>
|
||||
<strong><a href="#-overview">🎯 Overview</a> | <a href="#-inference---high-performance-kt-kernel-serving">🚀 Inference</a> | <a href="#-sft---fine-tuning-with-llama-factory">🎓 SFT</a> | <a href="#-citation">🔥 Citation</a> | <a href="https://github.com/kvcache-ai/ktransformers/issues/1921">🚀 Roadmap(2026Q2)</a> </strong>
|
||||
</div>
|
||||
|
||||
## 🎯 Overview
|
||||
|
||||
KTransformers is a research project focused on efficient inference and fine-tuning of large language models through CPU-GPU heterogeneous computing. The project has evolved into **two core modules**: [kt-kernel](https://github.com/kvcache-ai/ktransformers/tree/main/kt-kernel/) and [kt-sft](https://github.com/kvcache-ai/ktransformers/tree/main/kt-sft).
|
||||
KTransformers is a research project focused on efficient inference and fine-tuning of large language models through CPU-GPU heterogeneous computing. The project now exposes two user-facing capabilities from the kt-kernel source tree: [Inference](./kt-kernel/README.md) and [SFT](./doc/en/SFT/KTransformers-Fine-Tuning_Quick-Start.md).
|
||||
|
||||
## 🔥 Updates
|
||||
* **May 6, 2026**: KTransformers at [GOSIM Paris 2026](https://paris2026.gosim.org/zh/schedule/) — "Agentic AI on Edge" track. We'll present KT's inference performance on consumer hardware.
|
||||
* **Apr 30, 2026**: KTransformers v0.6.1 refreshes kt-kernel inference and SFT docs with separate [Inference](./kt-kernel/README.md) and [SFT Quick Start](./doc/en/SFT/KTransformers-Fine-Tuning_Quick-Start.md) entry points.
|
||||
* **Mar 26, 2026**: Support AVX2-only CPU backend for KT-Kernel inference. ([Tutorial](./doc/en/kt-kernel/AVX2-Tutorial.md))
|
||||
* **Feb 13, 2026**: MiniMax-M2.5 Day0 Support! ([Tutorial](./doc/en/MiniMax-M2.5.md))
|
||||
* **Feb 12, 2026**: GLM-5 Day0 Support! ([Tutorial](./doc/en/kt-kernel/GLM-5-Tutorial.md))
|
||||
|
|
@ -51,9 +52,9 @@ KTransformers is a research project focused on efficient inference and fine-tuni
|
|||
|
||||
---
|
||||
|
||||
## 📦 Core Modules
|
||||
## 📦 Capabilities
|
||||
|
||||
### 🚀 [kt-kernel](./kt-kernel/) - High-Performance Inference Kernels
|
||||
### 🚀 [Inference](./kt-kernel/README.md) - High-Performance kt-kernel Serving
|
||||
|
||||
CPU-optimized kernel operations for heterogeneous LLM inference.
|
||||
|
||||
|
|
@ -87,36 +88,37 @@ pip install .
|
|||
|
||||
---
|
||||
|
||||
### 🎓 [kt-sft](./doc/en/SFT/KTransformers-Fine-Tuning_User-Guide.md) - Fine-Tuning Framework
|
||||
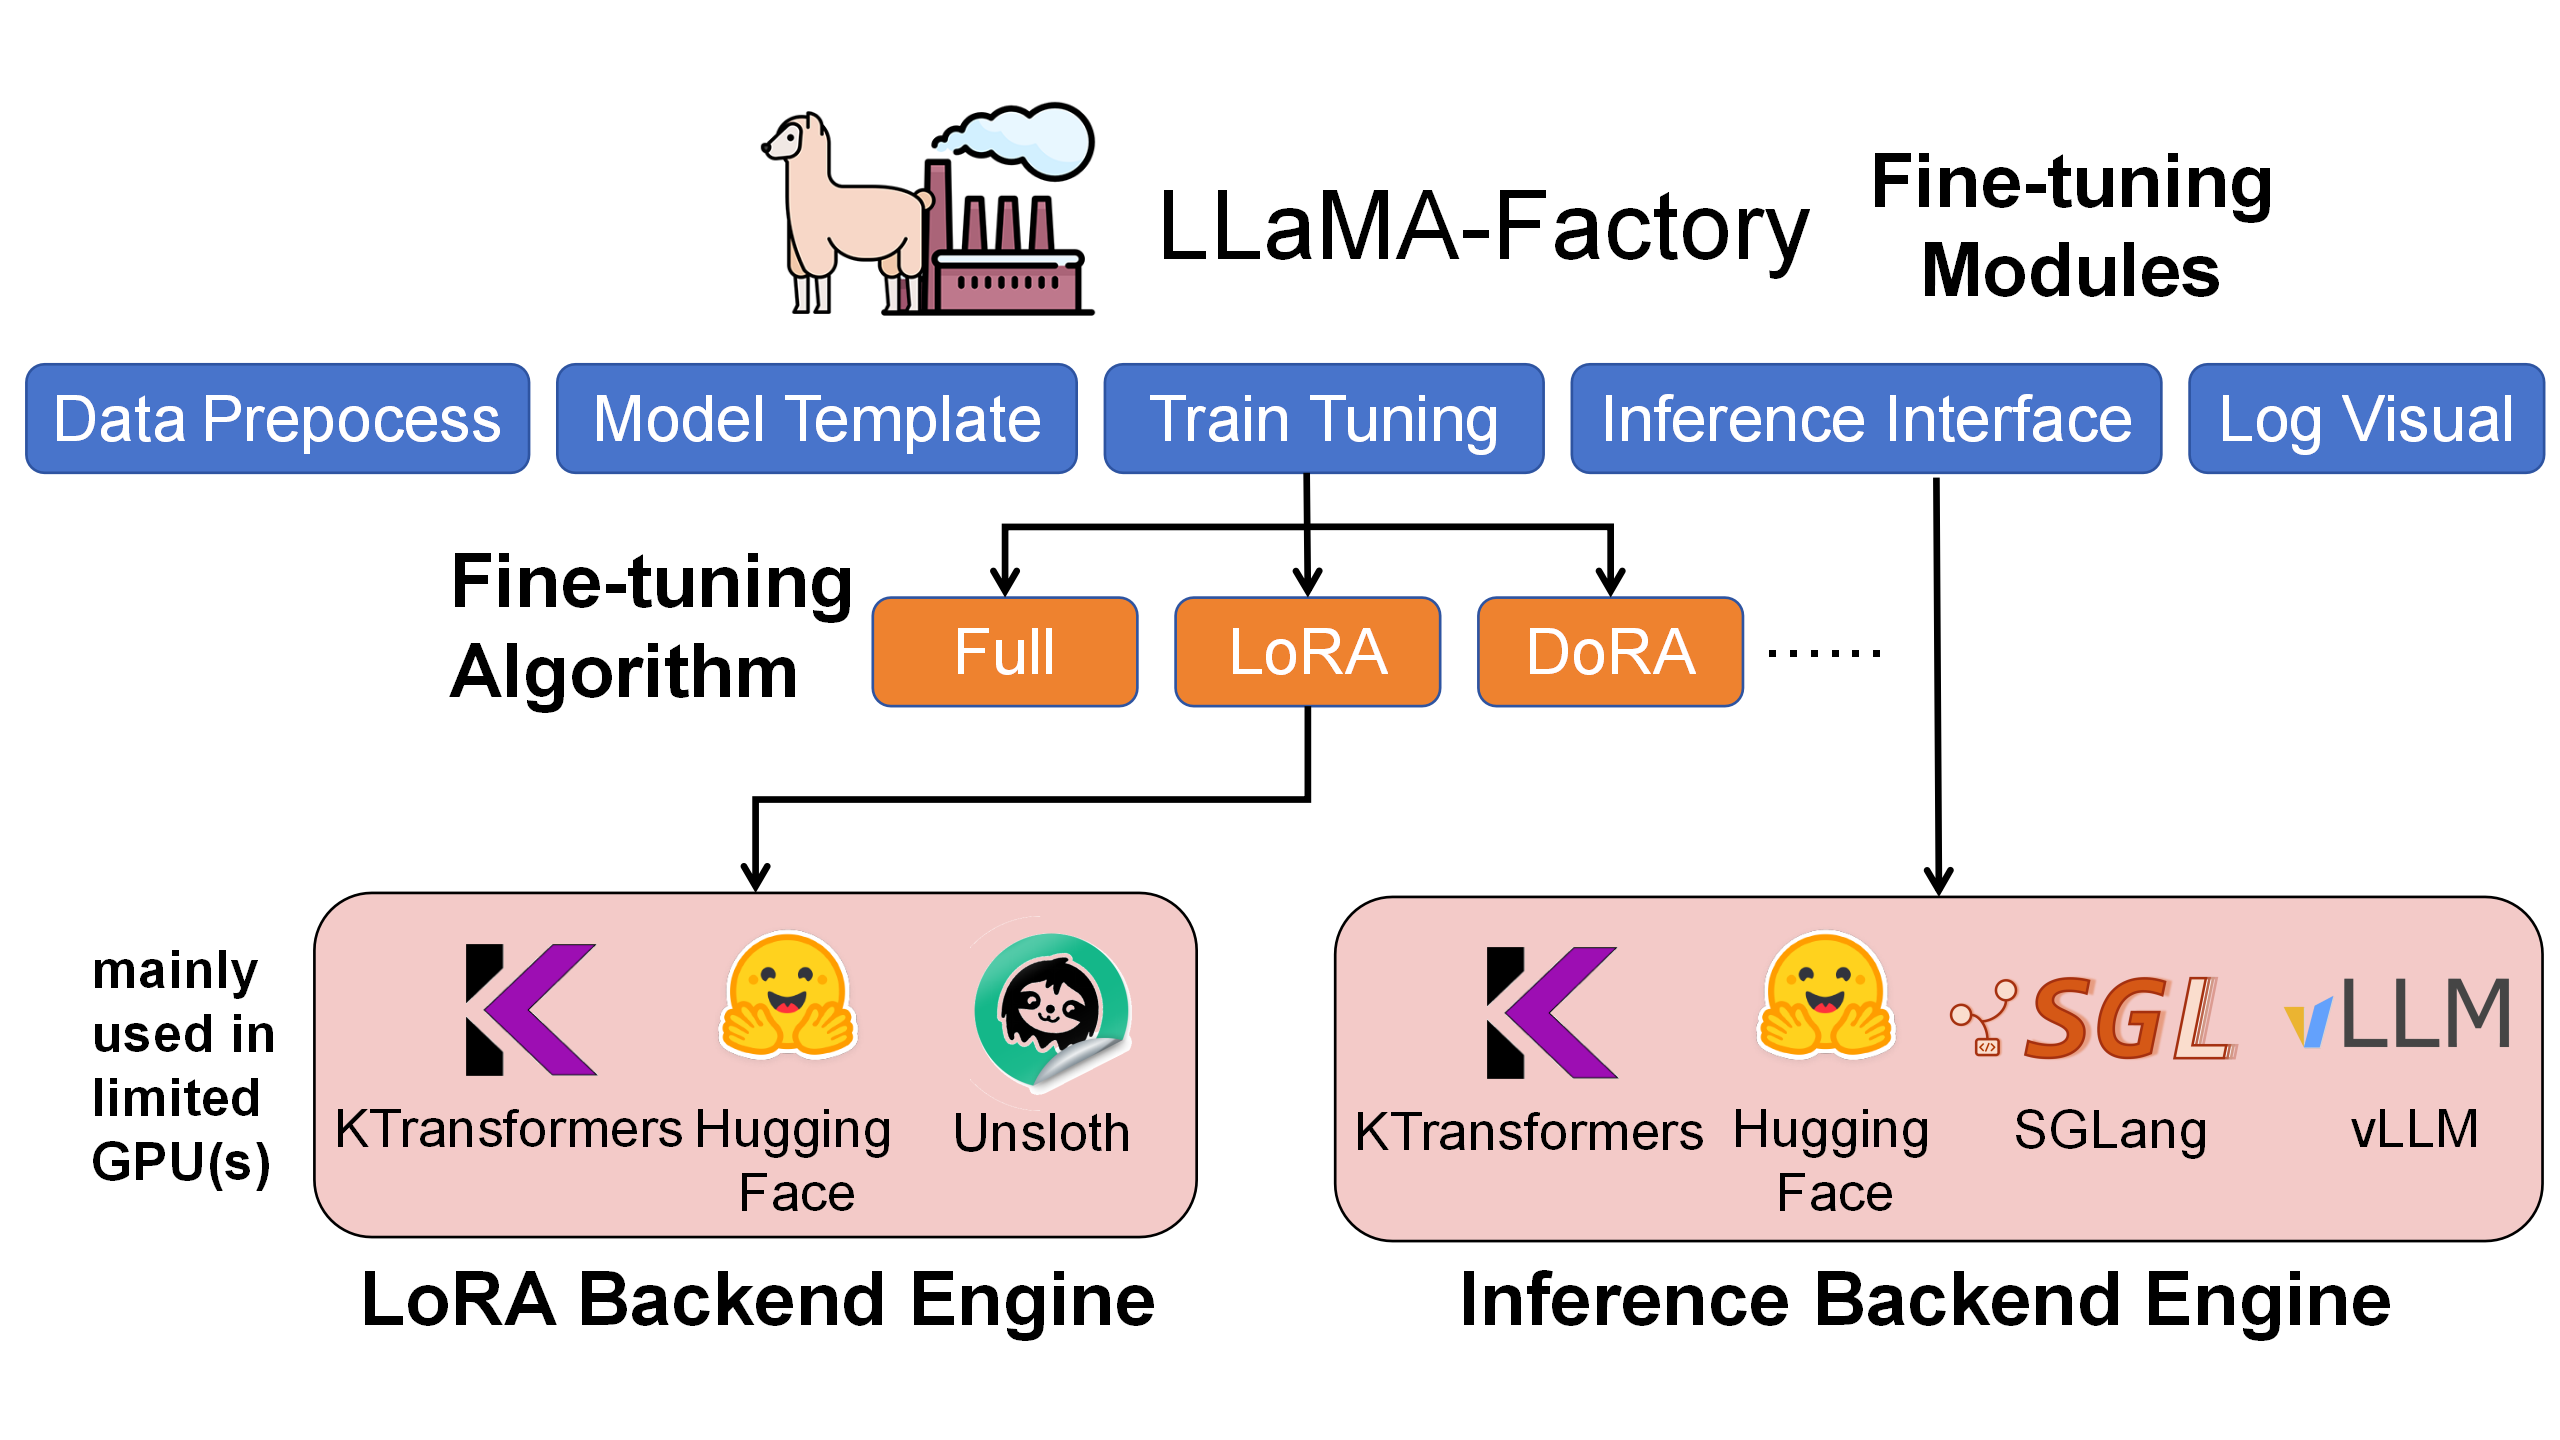
### 🎓 [SFT](./doc/en/SFT/KTransformers-Fine-Tuning_Quick-Start.md) - Fine-Tuning with LLaMA-Factory
|
||||
|
||||
KTransformers × LLaMA-Factory integration for ultra-large MoE model fine-tuning.
|
||||
|
||||
|
||||

|
||||
|
||||
**Key Features:**
|
||||
|
||||
- **Resource Efficient**: Fine-tune 671B DeepSeek-V3 with just **70GB GPU memory** + 1.3TB RAM
|
||||
- **LoRA Support**: Full LoRA fine-tuning with heterogeneous acceleration
|
||||
- **Multi-Backend Support**: CPU/GPU hybrid fine-tuning with INT8/INT4 quantization
|
||||
- **Ultra-Large MoE Support**: Fine-tune models like DeepSeek-V3/R1 on limited GPU memory
|
||||
- **Faster than ZeRO-Offload**: 6-12x training speedup in benchmarked MoE SFT workloads
|
||||
- **Lower CPU Memory**: About half the CPU memory of the previous KT SFT path in the benchmarked setup
|
||||
- **LLaMA-Factory Integration**: Seamless integration with popular fine-tuning framework
|
||||
- **Production Ready**: Chat, batch inference, and metrics evaluation
|
||||
|
||||
**Performance Examples:**
|
||||
|
||||
| Model | Configuration | Throughput | GPU Memory |
|
||||
|-------|--------------|------------|------------|
|
||||
| DeepSeek-V3 (671B) | LoRA + AMX | ~40 tokens/s | 70GB (multi-GPU) |
|
||||
| DeepSeek-V2-Lite (14B) | LoRA + AMX | ~530 tokens/s | 6GB |
|
||||
| Model | GPU Memory | Training Speed | Hardware |
|
||||
|-------|------------|----------------|----------|
|
||||
| DeepSeek-V3 | ~80GB total | 3.7 it/s | 4x RTX 4090 |
|
||||
| DeepSeek-R1 | ~80GB total | 3.7 it/s | 4x RTX 4090 |
|
||||
| Qwen3-30B-A3B | ~24GB total | 8+ it/s | 1x RTX 4090 |
|
||||
|
||||
**Quick Start:**
|
||||
```bash
|
||||
cd /path/to/LLaMA-Factory
|
||||
pip install -e .
|
||||
pip install "ktransformers[sft]"
|
||||
USE_KT=1 ACCELERATE_USE_KT=true \
|
||||
accelerate launch --config_file examples/ktransformers/accelerate/fsdp2_kt_bf16.yaml \
|
||||
-m llamafactory.cli train examples/ktransformers/train_lora/deepseek_v3_lora_sft_kt.yaml
|
||||
pip install -r requirements/ktransformers.txt
|
||||
CUDA_VISIBLE_DEVICES=0,1,2,3 accelerate launch \
|
||||
--config_file examples/ktransformers/accelerate/fsdp2_kt_int8.yaml \
|
||||
src/train.py \
|
||||
examples/ktransformers/train_lora/qwen3_5moe_lora_sft_kt.yaml
|
||||
```
|
||||
|
||||
👉 **[Quick Start →](./doc/en/SFT/KTransformers-Fine-Tuning_Quick-Start.md)**
|
||||
👉 **[Full Documentation →](./doc/en/SFT/KTransformers-Fine-Tuning_User-Guide.md)**
|
||||
|
||||
---
|
||||
|
|
@ -151,7 +153,7 @@ We welcome contributions! Please feel free to submit issues and pull requests.
|
|||
|
||||
## 📦 KT original Code
|
||||
|
||||
The original integrated KTransformers framework has been archived to the [`archive/`](./archive/) directory for reference. The project now focuses on the two core modules above for better modularity and maintainability.
|
||||
The original integrated KTransformers framework has been archived to the [`archive/`](./archive/) directory for reference. The project now organizes the two capabilities above from the kt-kernel source tree for clearer documentation and maintenance.
|
||||
|
||||
For the original documentation with full quick-start guides and examples, see:
|
||||
- [archive/README.md](./archive/README.md) (English)
|
||||
|
|
|
|||
52
README_ZH.md
52
README_ZH.md
|
|
@ -8,15 +8,16 @@
|
|||
|
||||
</p>
|
||||
<h3>一个用于体验尖端 LLM 推理/微调优化的灵活框架</h3>
|
||||
<strong><a href="#-概览">🎯 概览</a> | <a href="#-kt-kernel---高性能推理内核">🚀 kt-kernel</a> | <a href="#-kt-sft---微调框架">🎓 kt-sft</a> | <a href="#-引用">🔥 引用</a> </strong>
|
||||
<strong><a href="#-概览">🎯 概览</a> | <a href="#-推理---kt-kernel-高性能推理">🚀 推理</a> | <a href="#-sft---llama-factory-微调">🎓 SFT</a> | <a href="#-引用">🔥 引用</a> </strong>
|
||||
</div>
|
||||
|
||||
## 🎯 概览
|
||||
|
||||
KTransformers 是一个专注于通过 CPU-GPU 异构计算实现大语言模型高效推理和微调的研究项目。该项目已发展为**两个核心模块**:[kt-kernel](./kt-kernel/) 和 [kt-sft](./doc/en/SFT/KTransformers-Fine-Tuning_User-Guide.md)。
|
||||
KTransformers 是一个专注于通过 CPU-GPU 异构计算实现大语言模型高效推理和微调的研究项目。目前两个面向用户的能力都来自 kt-kernel 源码目录:[推理](./kt-kernel/README.md) 和 [SFT](./doc/en/SFT/KTransformers-Fine-Tuning_Quick-Start.md)。
|
||||
|
||||
## 🔥 更新
|
||||
|
||||
* **2026 年 4 月 30 日**:KTransformers v0.6.1 更新 kt-kernel 推理和 SFT 文档,提供独立的[推理](./kt-kernel/README.md)和 [SFT Quick Start](./doc/en/SFT/KTransformers-Fine-Tuning_Quick-Start.md)入口。
|
||||
* **2025 年 12 月 5 日**:支持原生 Kimi-K2-Thinking 推理([教程](./doc/en/kt-kernel/Kimi-K2-Thinking-Native.md))
|
||||
* **2025 年 11 月 6 日**:支持 Kimi-K2-Thinking 推理([教程](./doc/en/Kimi-K2-Thinking.md))和微调([教程](./doc/en/SFT_Installation_Guide_KimiK2.md))
|
||||
* **2025 年 11 月 4 日**:KTransformers 微调 × LLaMA-Factory 集成([教程](./doc/en/SFT/KTransformers-Fine-Tuning_User-Guide.md))
|
||||
|
|
@ -44,9 +45,9 @@ KTransformers 是一个专注于通过 CPU-GPU 异构计算实现大语言模型
|
|||
|
||||
---
|
||||
|
||||
## 📦 核心模块
|
||||
## 📦 功能入口
|
||||
|
||||
### 🚀 [kt-kernel](./kt-kernel/) - 高性能推理内核
|
||||
### 🚀 [推理](./kt-kernel/README.md) - kt-kernel 高性能推理
|
||||
|
||||
用于异构 LLM 推理的 CPU 优化内核操作。
|
||||
|
||||
|
|
@ -79,36 +80,37 @@ pip install .
|
|||
|
||||
---
|
||||
|
||||
### 🎓 [kt-sft](./doc/en/SFT/KTransformers-Fine-Tuning_User-Guide.md) - 微调框架
|
||||
### 🎓 [SFT](./doc/en/SFT/KTransformers-Fine-Tuning_Quick-Start.md) - LLaMA-Factory 微调
|
||||
|
||||
KTransformers × LLaMA-Factory 集成,用于超大型 MoE 模型微调。
|
||||
KTransformers × LLaMA-Factory 集成,面向超大 MoE 模型微调。
|
||||
|
||||

|
||||

|
||||
|
||||
**主要特性:**
|
||||
**主要特性:**
|
||||
- **多后端支持**: CPU/GPU 混合微调,支持 INT8/INT4 量化
|
||||
- **超大 MoE 支持**: 在有限 GPU 内存下微调 DeepSeek-V3/R1 等模型
|
||||
- **相对 ZeRO-Offload 加速**: 在基准 MoE SFT 任务中训练速度提升 6-12 倍
|
||||
- **降低 CPU 内存**: 相比上一版 KT SFT 路径,基准配置下 CPU 内存约降至 1/2
|
||||
- **LLaMA-Factory 集成**: 与流行微调框架无缝集成
|
||||
|
||||
- **资源高效**:仅需 **70GB GPU 显存** + 1.3TB 内存即可微调 671B DeepSeek-V3
|
||||
- **LoRA 支持**:完整的 LoRA 微调,带有异构加速
|
||||
- **LLaMA-Factory 集成**:与流行的微调框架无缝集成
|
||||
- **生产就绪**:聊天、批量推理和指标评估
|
||||
| 模型 | GPU 内存 | 训练速度 | 硬件 |
|
||||
|-------|------------|----------------|----------|
|
||||
| DeepSeek-V3 | ~80GB 总计 | 3.7 it/s | 4x RTX 4090 |
|
||||
| DeepSeek-R1 | ~80GB 总计 | 3.7 it/s | 4x RTX 4090 |
|
||||
| Qwen3-30B-A3B | ~24GB 总计 | 8+ it/s | 1x RTX 4090 |
|
||||
|
||||
**性能示例:**
|
||||
|
||||
| 模型 | 配置 | 吞吐量 | GPU 显存 |
|
||||
|-------|--------------|------------|--------------|
|
||||
| DeepSeek-V3 (671B) | LoRA + AMX | ~40 tokens/s | 70GB(多 GPU)|
|
||||
| DeepSeek-V2-Lite (14B) | LoRA + AMX | ~530 tokens/s | 6GB |
|
||||
|
||||
**快速开始:**
|
||||
**快速开始:**
|
||||
```bash
|
||||
cd /path/to/LLaMA-Factory
|
||||
pip install -e .
|
||||
pip install "ktransformers[sft]"
|
||||
USE_KT=1 ACCELERATE_USE_KT=true \
|
||||
accelerate launch --config_file examples/ktransformers/accelerate/fsdp2_kt_bf16.yaml \
|
||||
-m llamafactory.cli train examples/ktransformers/train_lora/deepseek_v3_lora_sft_kt.yaml
|
||||
pip install -r requirements/ktransformers.txt
|
||||
CUDA_VISIBLE_DEVICES=0,1,2,3 accelerate launch \
|
||||
--config_file examples/ktransformers/accelerate/fsdp2_kt_int8.yaml \
|
||||
src/train.py \
|
||||
examples/ktransformers/train_lora/qwen3_5moe_lora_sft_kt.yaml
|
||||
```
|
||||
|
||||
👉 **[Quick Start →](./doc/en/SFT/KTransformers-Fine-Tuning_Quick-Start.md)**
|
||||
👉 **[完整文档 →](./doc/en/SFT/KTransformers-Fine-Tuning_User-Guide.md)**
|
||||
|
||||
---
|
||||
|
|
@ -142,7 +144,7 @@ USE_KT=1 ACCELERATE_USE_KT=true \
|
|||
|
||||
## 📦 KT原仓库
|
||||
|
||||
原始的集成 KTransformers 框架已归档到 [`archive/`](./archive/) 目录以供参考。该项目现在专注于上述两个核心模块,以获得更好的模块化和可维护性。
|
||||
原始的集成 KTransformers 框架已归档到 [`archive/`](./archive/) 目录以供参考。该项目现在围绕 kt-kernel 源码树中的上述两个能力入口组织文档和维护。
|
||||
|
||||
有关原始文档以及完整的快速入门指南和示例,请参见:
|
||||
- [archive/README.md](./archive/README.md)(英文)
|
||||
|
|
|
|||
204
doc/en/SFT/KTransformers-Fine-Tuning_Quick-Start.md
Normal file
204
doc/en/SFT/KTransformers-Fine-Tuning_Quick-Start.md
Normal file
|
|
@ -0,0 +1,204 @@
|
|||
# KTransformers v0.6.1 KT SFT Quick Start
|
||||
|
||||
Last updated: 2026-04-30
|
||||
|
||||
This Quick Start is for LLaMA-Factory users who want to run KTransformers-backed MoE LoRA SFT. KTransformers has supported fine-tuning since v0.4.1 and later releases; v0.6.1 refactors and upgrades the existing KT SFT path with a pip-installable package entry, a cleaner dependency boundary, and LLaMA-Factory-compatible examples.
|
||||
|
||||
## 1. Scope
|
||||
|
||||
- Task: MoE LoRA SFT
|
||||
- Training entry: LLaMA-Factory `src/train.py` and YAML configs
|
||||
- KT package entry: `ktransformers[sft]`
|
||||
- Example models: Qwen3 MoE / Qwen3.5 MoE
|
||||
- Recommended baseline: Python 3.11 and `torch==2.9.1`
|
||||
|
||||
KT inference uses a separate SGLang-KT package path. See [KT Inference Packages](#7-kt-inference-packages).
|
||||
|
||||
## 2. Environment Setup
|
||||
|
||||
Start from a clean environment:
|
||||
|
||||
```bash
|
||||
conda create -n kt-sft python=3.11 -y
|
||||
conda activate kt-sft
|
||||
```
|
||||
|
||||
Install the PyTorch baseline:
|
||||
|
||||
```bash
|
||||
pip install \
|
||||
--extra-index-url https://download.pytorch.org/whl/cu130 \
|
||||
torch==2.9.1 \
|
||||
torchvision==0.24.1 \
|
||||
torchaudio==2.9.1
|
||||
```
|
||||
|
||||
If you already have a working `torch==2.9.1` environment, you can reuse it. Plain PyPI or mirror installs usually resolve `torch==2.9.1` to a CUDA 12.8 wheel; the PyTorch `cu130` index resolves to the CUDA 13.0 wheel. In both cases, the Python package version remains `torch==2.9.1`.
|
||||
|
||||
## 3. Install LLaMA-Factory and KT SFT
|
||||
|
||||
Use a LLaMA-Factory checkout that contains the KT examples and `requirements/ktransformers.txt`. Related integration PR:
|
||||
|
||||
https://github.com/hiyouga/LLaMA-Factory/pull/10430
|
||||
|
||||
Confirm the checkout contains:
|
||||
|
||||
- `requirements/ktransformers.txt`
|
||||
- `examples/ktransformers/`
|
||||
|
||||
Install in this order:
|
||||
|
||||
```bash
|
||||
cd /path/to/LLaMA-Factory
|
||||
pip install -e .
|
||||
pip install -r requirements/ktransformers.txt
|
||||
```
|
||||
|
||||
`requirements/ktransformers.txt` should contain one line:
|
||||
|
||||
```text
|
||||
ktransformers[sft]
|
||||
```
|
||||
|
||||
This entry installs the KT SFT stack:
|
||||
|
||||
- `ktransformers`
|
||||
- `kt-kernel`
|
||||
- `transformers-kt`
|
||||
- `accelerate-kt`
|
||||
|
||||
If your LLaMA-Factory checkout does not yet provide `requirements/ktransformers.txt`, you can install the KT SFT package entry directly:
|
||||
|
||||
```bash
|
||||
pip install "ktransformers[sft]"
|
||||
```
|
||||
|
||||
For LLaMA-Factory users, the requirements file is preferred because it keeps the examples and optional dependency flow together.
|
||||
|
||||
## 4. Post-Install Check
|
||||
|
||||
```bash
|
||||
python - <<'PY'
|
||||
import importlib.metadata as md
|
||||
import torch
|
||||
import transformers
|
||||
import accelerate
|
||||
import kt_kernel
|
||||
import ktransformers
|
||||
from accelerate.utils.dataclasses import KTransformersPlugin
|
||||
|
||||
print("torch =", torch.__version__)
|
||||
print("transformers =", transformers.__version__)
|
||||
print("accelerate =", accelerate.__version__)
|
||||
print("kt_kernel =", kt_kernel.__version__)
|
||||
print("ktransformers =", ktransformers.__version__)
|
||||
print("transformers-kt dist =", md.version("transformers-kt"))
|
||||
print("accelerate-kt dist =", md.version("accelerate-kt"))
|
||||
print("KTransformersPlugin =", KTransformersPlugin.__name__)
|
||||
PY
|
||||
```
|
||||
|
||||
Expected values should be close to:
|
||||
|
||||
- `torch = 2.9.1+cu128` or `2.9.1+cu130`
|
||||
- `transformers = 5.6.0`
|
||||
- `accelerate = 1.14.0`
|
||||
- `kt_kernel = 0.6.1`
|
||||
- `ktransformers = 0.6.1`
|
||||
- `KTransformersPlugin = KTransformersPlugin`
|
||||
|
||||
## 5. Run Qwen3.5 MoE LoRA SFT
|
||||
|
||||
Reference configs:
|
||||
|
||||
- accelerate config: `examples/ktransformers/accelerate/fsdp2_kt_int8.yaml`
|
||||
- train yaml: `examples/ktransformers/train_lora/qwen3_5moe_lora_sft_kt.yaml`
|
||||
- starting point for resource planning: 4 x 24GB GPU + 512GB CPU memory; real requirements depend on model, context length, batch size, and LoRA config.
|
||||
|
||||
Before running, open the train YAML and adjust these fields for your local setup:
|
||||
|
||||
- `model_name_or_path`
|
||||
- `dataset`
|
||||
- `output_dir`
|
||||
- `cutoff_len`
|
||||
- `max_steps`
|
||||
|
||||
Run:
|
||||
|
||||
```bash
|
||||
cd /path/to/LLaMA-Factory
|
||||
CUDA_VISIBLE_DEVICES=0,1,2,3 accelerate launch \
|
||||
--config_file examples/ktransformers/accelerate/fsdp2_kt_int8.yaml \
|
||||
src/train.py \
|
||||
examples/ktransformers/train_lora/qwen3_5moe_lora_sft_kt.yaml
|
||||
```
|
||||
|
||||
## 6. Other MoE Examples
|
||||
|
||||
| Model path | accelerate config | train yaml |
|
||||
| --- | --- | --- |
|
||||
| Qwen3 MoE BF16 | `examples/ktransformers/accelerate/fsdp2_kt_bf16.yaml` | `examples/ktransformers/train_lora/qwen3moe_lora_sft_kt.yaml` |
|
||||
| Qwen3.5 MoE INT8 | `examples/ktransformers/accelerate/fsdp2_kt_int8.yaml` | `examples/ktransformers/train_lora/qwen3_5moe_lora_sft_kt.yaml` |
|
||||
| DeepSeek-V2 MoE | `examples/ktransformers/accelerate/` KT configs | `examples/ktransformers/train_lora/deepseek_v2_lora_sft_kt.yaml` |
|
||||
| DeepSeek-V3 MoE | `examples/ktransformers/accelerate/` KT configs | `examples/ktransformers/train_lora/deepseek_v3_lora_sft_kt.yaml` |
|
||||
|
||||
Start from the example `kt_config`, `use_kt: true`, and LoRA settings, then adjust model paths and resource-related fields for your hardware.
|
||||
|
||||
## 7. KT Inference Packages
|
||||
|
||||
KT inference uses the SGLang-KT path:
|
||||
|
||||
```bash
|
||||
pip install kt-kernel sglang-kt
|
||||
```
|
||||
|
||||
LLaMA-Factory KT SFT continues to use:
|
||||
|
||||
```bash
|
||||
pip install -r requirements/ktransformers.txt
|
||||
```
|
||||
|
||||
with:
|
||||
|
||||
```text
|
||||
ktransformers[sft]
|
||||
```
|
||||
|
||||
Keep `sglang-kt` out of LLaMA-Factory SFT requirements.
|
||||
|
||||
## 8. Troubleshooting
|
||||
|
||||
### `ValueError: unknown keys (['kt_config'])`
|
||||
|
||||
This usually means the environment is still using upstream `accelerate`. Reinstall in this order from the LLaMA-Factory checkout:
|
||||
|
||||
```bash
|
||||
pip install -e .
|
||||
pip install -r requirements/ktransformers.txt
|
||||
```
|
||||
|
||||
Then rerun the post-install check and confirm `accelerate = 1.14.0` and `KTransformersPlugin` imports successfully.
|
||||
|
||||
### `kt_kernel` or `ktransformers` is missing
|
||||
|
||||
Confirm that the KT SFT dependency step was run from the LLaMA-Factory checkout:
|
||||
|
||||
```bash
|
||||
pip install -r requirements/ktransformers.txt
|
||||
```
|
||||
|
||||
### CPU or GPU memory is insufficient
|
||||
|
||||
Try the following first:
|
||||
|
||||
- reduce `cutoff_len`
|
||||
- reduce batch size
|
||||
- start from INT8 / INT4 KT configs
|
||||
- increase CPU memory or reduce other concurrent workloads
|
||||
|
||||
## 9. Related Links
|
||||
|
||||
- KTransformers: https://github.com/kvcache-ai/ktransformers
|
||||
- KTransformers v0.6.1 Release: https://github.com/kvcache-ai/ktransformers/releases/tag/v0.6.1
|
||||
- LLaMA-Factory KT PR: https://github.com/hiyouga/LLaMA-Factory/pull/10430
|
||||
- KTransformers docs: https://ktransformers.net/docs
|
||||
|
|
@ -1 +1,7 @@
|
|||
# kt-sft Docs
|
||||
# KTransformers SFT Docs
|
||||
|
||||
- [v0.6.1 Quick Start](./KTransformers-Fine-Tuning_Quick-Start.md)
|
||||
- [Fine-Tuning User Guide](./KTransformers-Fine-Tuning_User-Guide.md)
|
||||
- [Developer Technical Notes](./KTransformers-Fine-Tuning_Developer-Technical-Notes.md)
|
||||
- [DPO Tutorial](./DPO_tutorial.md)
|
||||
- [Injection Tutorial](./injection_tutorial.md)
|
||||
|
|
|
|||
Loading…
Add table
Add a link
Reference in a new issue