 c0fd786264 * common : resolve <quant>-<sidecar> download tags and list cached sidecars A Q4_0-mtp style tag now resolves the sidecar file when no model file matches it, so a solo draft or mmproj download actually pulls the file. Cached sidecar files list as their own entries so the state survives a restart, and removing such a tag deletes only the sidecar. Assisted-by: pi:zai-org/GLM-5.3 * ui : optional sanitized raw HTML in markdown Add an allowHtml prop to MarkdownContent: raw HTML found in the markdown is rendered after DOMPurify sanitization instead of being escaped as literal text. Default stays escaped. Assisted-by: pi:GLM-5.3-Flash * ui : add the discover models components The Discover surface: the curated-catalog list with its search and skeletons, the details pane with its readme, metadata, Hub stats and download options, and the standalone download progress bar that replaces the plain one. The quant download button sizes its select with a new xs trigger, so the select gains that size and the muted box look. The store stays incomplete when a repo fails, so the next mount retries it. Assisted-by: pi:llama.cpp/DeepSeek-V4.1-Flash * ui : put the discover view in the models manager The manager dialog gains its second view: the Discover Models call to action fades the table out, slides the title with its compass mark, and fades the discover surface in; the arrow button returns to the table. Assisted-by: pi:llama.cpp/DeepSeek-V4.1-Flash # Conflicts: # tools/ui/src/lib/components/ui/button/button.svelte * ui : add the Enable Discover Models setting The flag gates browsing and downloading HuggingFace GGUF models, so it is declared on the discover layer; the repo-tree lookup in the manager layer above reads it from here. Assisted-by: pi:llama.cpp/DeepSeek-V4.1-Flash * ui : resume model downloads from the pause point A stopped download keeps its partial file instead of deleting it, so re-posting the tag resumes from disk. The first progress record now carries the resume offset, the paused snapshot survives into the resumed entry, and a pause settles as soon as it is requested. Assisted-by: pi * ui : lead the discover list with downloads The discover sidebar lists running downloads above the suggested models, and steps aside while a query is active. A paused download stays in the manager table, where it is resumed or dropped. Assisted-by: pi * ui : make resuming a paused download work Re-posting the tag of a paused download hit the router's "already exists" check, because a paused download parks its entry as DOWNLOADED until the next reload: a download entry that is not running is now replaced and resumed. The UI keeps the paused row when the request still fails, instead of dropping it and looking finished. Assisted-by: pi * ui : remember unfinished model downloads A partial file is named after its content hash, so nothing on disk says which model it belongs to once the router restarts. The router now keeps the tags of the downloads it started, clears a tag when the download finishes or is deleted, and lists what is left as still downloading without starting anything. The UI adopts those tags as paused on every list fetch, so a refresh or a fresh open shows an incomplete download and can resume it from the files already on disk. Assisted-by: pi * ui : show a paused download's state on its chip A paused quant chip reads as paused at rest, the way a running one shows its spinner, and offers the resume action on hover. The selector's download row gets a View in Discover action beside its cancel. Assisted-by: pi * ui : collapse the download options by default The copyable download command starts collapsed so the option rows lead; expanding it stays one click away. Assisted-by: pi * ui : keep decision models out of the hub lists Decision models answer with calibrated probabilities instead of text, so llama-ui cannot run them: the hub data layer drops them from the catalog and every search, keyed by the decision-model tag or a text-classification pipeline. Assisted-by: pi * ui : read download tags as quant and sidecar A `<repo>:<quant>-<sidecar>` tag now parses into its quant and sidecar instead of one opaque quant token, and ModelsService.draftSidecarsByRepo collects the router listing's sidecar-only entries per repo, replacing the inline copy in the models store. Assisted-by: pi * ui : cluster draft downloads under their main model Tracked downloads group by repo: the main weights lead and the draft sidecars ride inside their item as compact sub-lines, on the selector, the discover list and the manager table. The main model's controls pause, resume and cancel the whole cluster, and the manager's download rows select into the configuration pane. Assisted-by: pi * ui : act on tracked downloads from the table rows The table passes its clusters' draft sub-lines to the model rows. A row's actions cascade pause and resume, an in-flight row offers Cancel download while a paused one keeps Delete from disk, and the confirm dialog's copy follows the state. Assisted-by: pi * ui : give downloads a configuration pane of their own Selecting a tracked download opens the pane in a download mode: live progress with pause, resume and cancel, and See in Discover, instead of metadata and load actions that a model without files cannot offer. Assisted-by: pi * ui : make the discover details self-fetching and responsive ModelsDiscoverDetailsContainer owns the details, tree and readme fetches so hosts outside the discover view can render the pane, and the details layout adapts to narrow panes with container queries instead of viewport breakpoints. Assisted-by: pi * ui : download a matching draft with the main model A main quant download now pulls the quant-matched draft of the most preferred kind the repo ships (DFlash before MTP), fire-and-forget, so speculative decoding is ready when the main lands. Manual draft chips stay available; the options row also collapses to one column in narrow panes. Assisted-by: pi * ui : keep discover off by default and couple it with the hub setting Discover Models starts unchecked. Enabling it turns the Hugging Face Hub setting on and disabling it turns it back off, so the checkbox never lies; with discover off the hub setting stays available on its own for the display data. Stored and reset state are corrected the same way on load. Assisted-by: pi * ui : open the manage models dialog on the manager view The dialog now opens on the manager instead of returning to the last view, discover entries still land on the discover view while the setting allows it, and the discover surfaces follow the setting's state. Assisted-by: pi * ui : give the discover search room for its focus ring The sticky search bar insets from the panel edges so the focus ring stays inside the scroll container, and rows scroll behind an opaque bar instead of through it. Assisted-by: pi * common: settle sidecar names on the listing and drop unfinished partials An infix or trailing sidecar token is ambiguous: draft heads use it (Model-MTP-BF16.gguf), so do full models with embedded heads (Model-Q8D-MTP.gguf). Such a name is a sidecar only next to token-free main weights of the same family, while mmproj or imatrix anywhere in the name, or a leading token, decides alone (mmproj_f16.gguf). A quant tag always carries its bit count, so a sidecar named after no quant (mtp-Model-it.gguf) gets the bare tag: the listing, the plan and remove all use it. An imatrix tag resolves into a plan slot of its own, downloaded but never wired into the params. remove resolves the tag the way a download does and deletes the partial files of every planned blob, so cancelling a running download or dropping one left unfinished by an earlier run leaves nothing on disk. The router passes its token and releases its lock around the call, and records the unfinished downloads with an atomic write. llama download succeeds on a sidecar-only plan and prints its paths. * ui : move dialog views and draft states into enums and constants The models dialog's views become the ModelsDialogView enum, the draft subline's states join ModelRowDownloadState, the view fade and the copy-feedback reset move to ui constants, and the dialog's compass marks come from DISCOVER_ICON. Assisted-by: pi * ui : drop the unused discover surface The dead openDiscoverModels twin, the commented-out command divider, the details pane's unused onClose and its header's close button, and a redundant type cast leave; the command's copy feedback joins the shared reset constant. Assisted-by: pi * ui : trim the download option comments and highlight the chat template The comment verbosity the options panel and its chips carried shrinks to the non-obvious why, and the chat template dialog renders through SyntaxHighlightedCode as jinja instead of a plain pre block. Assisted-by: pi * common: only a .gguf file is a sidecar, and mmproj/imatrix as whole words A non-GGUF file named like a sidecar (quantization-mmproj-Q8_0.json) is picked as the mmproj, and a sidecar word inside a longer word of a model name (Phi-2-OmniMatrix.i1-Q4_K_M.gguf) drops the model. * ui: dedupe draft sidecar badges per quant The draft sidecar badges deduped by kind and repo without the quant, so with a draft cached at two quants only one badge survived, and a delete of the other main quant found no badge to remove its sidecar with. Also restores the getDownloadEntries doc lost when the clusters method landed above it. Assisted-by: pi (zai-org/GLM-5.3-Flash) * ui: adopt the incomplete download status and drop the paused-ids registry The store inferred an unfinished download from a downloading entry it held no local state for, which misread a download running in another tab as paused and offered a resume the server rejects. The listing carries the "incomplete" status now, so the adoption keys off it directly. The paused ids no longer need to survive in localStorage: the server remembers them across restarts, and the progress snapshot was stale after a reload anyway. The stale localStorage key is removed. Assisted-by: pi (zai-org/GLM-5.3-Flash) * ui: quant-match the pause and cancel cascades Pause, resume and cancel cascaded to every draft sidecar of the repo while delete only took the quant-matched ones, so canceling a Q4_0 download also killed a Q8_0 draft that belongs to another quant's main. Every cascade acts on the quant-matched drafts now, matching what a delete takes with it. Assisted-by: pi (zai-org/GLM-5.3-Flash) * ui: collapse the duplicated draft subline markup The downloaded and in-flight branches repeated the identical connector, label and badge markup; one block with a conditional tail keeps the two states in sync. Assisted-by: pi (zai-org/GLM-5.3-Flash) * ui: scrub positioned styles out of sanitized model card html The style attribute stays allowed for the KaTeX output, which let a third party card draw a fixed overlay over the app. The sanitize hook drops position:fixed and position:absolute values and leaves the KaTeX layout styles alone. Assisted-by: pi (zai-org/GLM-5.3-Flash) * ui: run the discover mount fetch once and reuse the shared repoOf helper fetch() toggles its loading flag synchronously inside the mount effect, which re-ran the fetch on every toggle and retried failed catalog repos endlessly; the effect now untracks the call. The local repoOf copy and the duplicate services import give way to the shared helpers. Assisted-by: pi (zai-org/GLM-5.3-Flash) * ui: narrow the spec-type map to the draft sidecars SPEC_TYPE carried empty entries for the aux sidecars it is never indexed with; the map and the command component now type the badge as a draft sidecar through a draftBadgeOf helper instead of a cast. Assisted-by: pi (zai-org/GLM-5.3-Flash) * ui: name the decision-model tags and markdown cache keys The decision-model hub tag and pipeline tag move into the huggingface constants next to the other pipeline tags, and the markdown transform cache prefixes get names instead of bare one-letter tokens. Assisted-by: pi (zai-org/GLM-5.3-Flash) * ui: read the discover setting through one truthiness check Three places read the setting with !== false and one with Boolean(); all four read it the same way now. Assisted-by: pi (zai-org/GLM-5.3-Flash) * ui: compare the models dialog view against its enum The template compared the view state against the 'manage' literal in three spots while the script used the enum. Assisted-by: pi (zai-org/GLM-5.3-Flash) * nit: Remove `+` before draft sidecar badge * server: list unfinished downloads as incomplete A download that never finished was reported as "downloading", the same status a live download carries, so a client could not tell a running download from a dead one. The tags remembered in unfinished-downloads now list under a dedicated "incomplete" status, without an instance. Assisted-by: pi (zai-org/GLM-5.3-Flash) * server: download a model with its sidecars as -hf does Resolution goes back to master. POST /models takes the sidecar kinds to pull with the model (mmproj by default) and the download child gets them as -hf flags, so the server picks the files. /models lists real models only, each with the sidecars it has on disk, and incomplete downloads keep their sidecars across restarts. A stopped download keeps its partial files for the next attempt, and DELETE purges them through the same plan the download follows. * ui: download sidecars as parameters of their model The download options keep their chips, but a chip no longer posts a sidecar tag: the store maps it to its model and the sidecar kinds to pull, the quant chip takes its companion draft in the same download, and draft badges come from the sidecars each cached model lists. The server adds the sidecars a cached model lacks when it is posted again, and DELETE removes a single sidecar of a cached model. * ui : mirror the server's sidecar lookup in draft badges The server resolves a sidecar by the case-sensitive `<kind>-` token in the same directory as the weights. The UI matched the token loosely, so a badge could offer a draft the server never pulls. Assisted-by: DeepSeek-V4.1-Flash * ui : post the model's sidecar kinds with its download The store keeps one download per model: the chip's kinds ride along with the model's own sidecars, and a download row no longer expands into one row per sidecar. Draft badges carry no quant of their own yet, so a sidecar of a cached model is never labelled with the model's quant. Assisted-by: DeepSeek-V4.1-Flash * ui : join a quant's draft into its download chip One chip per quant, its draft badged inside it and its size covering both files. The draft is the file the server would pick: the same directory, the exact quant, else the closest bit depth, so a 4-bit model can pair with a 16-bit head. Assisted-by: DeepSeek-V4.1-Flash * ui : drop the draft download rows from the manager and selector A download is one row per model again: the drafts ride with it, and the rows read the sidecars on disk off the listing instead of pairing sidecar entries with their model. Pause, resume and cancel act on the model's own download. Assisted-by: DeepSeek-V4.1-Flash * ui : keep the discover download list one row per model The list leads with one row per downloading model, its sidecars as sub-lines. A row badges only the draft kinds the server can resolve, so a badge never outlives the file its lookup would pick. Assisted-by: DeepSeek-V4.1-Flash * ui : keep the discover chips readable in dark mode The metadata chips, the chat template button and the View on Hugging Face link carried a faint border and no surface over the dialog background, so they were near invisible. They take the tertiary button surface now, and their icons size with size-* so the variant's base rule leaves them alone. Assisted-by: DeepSeek-V4.1-Flash * ui : carry the draft through the download options One chip per main quant, its draft badged on it and the chip's downloaded state covering both files. The drafts sit behind an opt-in checkbox with an inline type pick, and each row opens its own command: it pins the row's quant and only names the draft type, so -hfd is gone. Assisted-by: DeepSeek-V4.1-Flash * ui : line the details skeleton up with the loaded pane Same root padding and container context as the loaded view, so the container queries resolve alike. The download options card pads its blocks instead of itself, the readme gets its card, and a description line stands in for the catalog paragraph. Assisted-by: DeepSeek-V4.1-Flash * common : drop the partials of a removed sidecar Removing a sidecar alone left the .downloadInProgress files of the sidecars a download had planned in blobs/. The removal purges them through the same plan the download follows, and the test covers a finished draft beside an unfinished one, whose partial goes while the model keeps its files. Assisted-by: DeepSeek-V4.1-Flash * server : name why a download is refused A model that is already downloading, or that is running, answered "already exists". It now says which: "is already downloading", or "is running, unload it first", both before the resumable check. The router test covers the two. Assisted-by: DeepSeek-V4.1-Flash * ui : post a download once per click Two quick clicks on the same chip posted twice, and the second answer was "already exists". The store tracks the model as pending, returns early while it is pending or in flight, and reads it as in flight before the server answers, so the chip shows the download at once. The new client test pins the flows: one POST per double click, the chip reading downloaded once the list reports the model, a resume keeping its sidecars, a cancel dropping the whole download, and a reload restoring the paused state. Assisted-by: DeepSeek-V4.1-Flash * ui : keep a plain download row the height of the others The sub-lines wrapper of a download row was rendered even with nothing in it, so its padding made the row taller than a plain one and the overlaid progress bar sat in that empty strip. It renders only with sub-lines now, in the selector and in the discover list, and the selector row takes the phone padding its neighbours have. Assisted-by: DeepSeek-V4.1-Flash * ui : badge a repo's draft once The args of a loaded model and the listing of a cached one report the same draft in different words, one with the file's quant and one with the kind alone, so the merge kept both and a repo row showed the same kind twice. The badges merge per kind now, the args one winning as it knows the quant, and the test pins both sources of a real repo. Assisted-by: DeepSeek-V4.1-Flash * server : report the sidecars of a preset or a download on its way A model the preset also names is registered as a preset, so its drafts were never reported and no row could badge them. A download on its way reported none either, though the record of the kinds it pulls is right there: those win over the plan now, the plan resolves through the preset's hf-repo, and a models dir stays out of it. Assisted-by: DeepSeek-V4.1-Flash * ui : badge a download's drafts and open its model from the row A draft still coming down badges the model id now, the way a landed one does, while an on-disk draft keeps its checked sub-line. The row itself opens the model, the status slot beside it pauses or resumes, and the manager resolves a focus on a download row so its panel opens. Assisted-by: DeepSeek-V4.1-Flash * common : report a removed sidecar that only had a partial Removing a sidecar alone dropped the result of the partial purge, so a sidecar that only ever landed as a .downloadInProgress blob answered false and the UI had no reason to refetch. The purge result is folded into the return now, and the test covers a partial-only removal. Assisted-by: DeepSeek-V4.1-Flash * ui : ignore a pause while the download POST is still on its way The chip reads as downloading before the server answers, so a quick second click unloaded a model that had not started and left the store neither in flight nor paused. A pause returns early while the POST is pending, before it touches the feed or the paused marker. The client test holds the POST open and pins it. Assisted-by: DeepSeek-V4.1-Flash * ui : offer a missing draft as its own chip A model already on disk without its draft had no way to add it: the quant chip carried the draft, so it read as a download of both. The quant chip keeps to its own state now, its joined draft shows only while it rides along or is on disk, and a downloaded quant missing its draft gets a chip of its own - badge, size, download - that posts the model with that kind, so the server keeps the files already there and pulls the draft. Assisted-by: DeepSeek-V4.1-Flash * server : list a paused sidecar download by the files on disk A model on disk whose sidecar download stops keeps its unfinished record, and the listing reported the kinds that record plans as if they were on disk: the UI checked a draft that never landed and offered no way to add it. The planned kinds now stand in only while the download runs. * chore: Clean up comments * server : list sidecars only for a model that resolves from a HF repo A preset on a local file has no HF repo, yet the listing resolved its name as one: the plan threw on the invalid repo format and GET /models failed for every model. The sidecars now come from the repo a preset names or a cached model is listed under, and a local file lists without them. * common : fix download cancel regression Signed-off-by: Adrien Gallouët <angt@huggingface.co> * common : preserve model partials when removing sidecars Signed-off-by: Adrien Gallouët <angt@huggingface.co> * server : one sidecar table and an unfinished downloads class Address review from @ggerganov. The sidecar kinds live in one table in common/download, mapping each name to its download option and plan file; the server validates, builds its options and lists cached sidecars through it instead of its own lists. The unfinished downloads move into server_unfinished_downloads, a record with its own mutex and a struct per entry, and server_models exposes them through unfinished_downloads_get and unfinished_downloads_remove. * common: one sidecar table, and removals that keep shared files The resolution, the cached listing and the removal follow a single table of sidecar kinds, so a kind is declared once with its file keyword, whether it is a draft, its option and its plan file. The server reads the same table for the kinds it accepts, the default sidecars and the child flags. Removing a tag keeps the files another cached tag still loads, such as an mmproj named after the removed quant. A sidecar removed on its own goes for every tag that resolves it. An unfinished download records the exact paths of its partials when it starts. A removal deletes those without asking the hub, and keeps a partial another recorded download also writes. The record is taken once the child is spawned, and the files go under the models lock, so a download of the same tag cannot start while they are removed. * server: drop stale partials and refuse a tag that resolves nothing Recording a download again deletes the partials of the earlier record that the new plan no longer writes, such as those of an older hub revision or of a sidecar the new request leaves out. A posted tag that resolves no file of the repo is refused before the download starts. Removing a model follows a single path, whether the reload erased its entry during the wait or not. * server: fix the CI race between the router download tests The pytest workers run in parallel on one shared cache, so a download test could find the file another test had just fetched and see no progress, or start from the unfinished downloads record another test wrote. Each download test now runs on an empty cache of its own. * server: refuse a DELETE of an unknown name and decide downloads in load() A DELETE of a name that is neither a model nor a recorded download went to common_download_remove, and without a tag it wiped the whole repo cache, including the files of a loaded quant or of a download on its way. Such a name is now not found, as it was before. A POST that downloads over an existing entry checked its state outside the lock, so a load of the same model in between got its instance killed. The checks now run in load(), under the lock, right before the spawn. The fake load time of the tests applies to model loads only, since a download worker loads none. * server: add incomplete_sidecars to the /models API A sidecar added to a cached model and then paused kept its record, but the listing showed only the complete model, so a fresh UI lost the pause. The model entry now carries incomplete_sidecars, the kinds its unfinished download has not written yet; a POST with the kind resumes one and a DELETE with it drops its partial. * common : drop a kept partial when a resume gets 416 Now that partials survive between attempts, an old or complete partial makes every retry fail with the same 416. Delete it so the next attempt can start over from zero. Signed-off-by: Adrien Gallouët <angt@huggingface.co> * common: drop a kept partial when a resume gets 200 A server that ignores the range answers 200 to a resume, and the kept partial then fails every attempt the same way a 416 does. Drop it as well, so the next attempt starts over without a range. * server: refuse a download that shares a partial with one on its way Two downloads of quants that share a file, the mmproj or an mtp picked by the closest bits, appended to the same partial and renamed a file with interleaved bytes. A download whose plan writes a partial that a running download also writes is now refused until that one is done. * common : check the saved etag before resuming a partial download Before resuming, compare the etag saved with the partial to the one the server now serves. If it is missing or different, start over, so a resumed download never mixes bytes from two versions of the file. Signed-off-by: Adrien Gallouët <angt@huggingface.co> --------- Signed-off-by: Adrien Gallouët <angt@huggingface.co> Co-authored-by: Pascal <admin@serveurperso.com> Co-authored-by: Adrien Gallouët <angt@huggingface.co> |
||
|---|---|---|
| .. | ||
| bench | ||
| tests | ||
| CMakeLists.txt | ||
| main.cpp | ||
| README-dev.md | ||
| README.md | ||
| server-chat.cpp | ||
| server-chat.h | ||
| server-common.cpp | ||
| server-common.h | ||
| server-context.cpp | ||
| server-context.h | ||
| server-cors-proxy.h | ||
| server-decision.cpp | ||
| server-decision.h | ||
| server-http.cpp | ||
| server-http.h | ||
| server-mcp.cpp | ||
| server-mcp.h | ||
| server-models.cpp | ||
| server-models.h | ||
| server-queue.cpp | ||
| server-queue.h | ||
| server-schema.cpp | ||
| server-schema.h | ||
| server-stream.cpp | ||
| server-stream.h | ||
| server-task.cpp | ||
| server-task.h | ||
| server-tools.cpp | ||
| server-tools.h | ||
| server.cpp | ||
LLaMA.cpp HTTP Server
Fast, lightweight, pure C/C++ HTTP server based on httplib, nlohmann::json and llama.cpp.
Set of LLM REST APIs and a web UI to interact with llama.cpp.
Features:
- LLM inference of F16 and quantized models on GPU and CPU
- OpenAI API compatible chat completions, responses, and embeddings routes
- Anthropic Messages API compatible chat completions
- Reranking endpoint (https://github.com/ggml-org/llama.cpp/pull/9510)
- Parallel decoding with multi-user support
- Continuous batching
- Multimodal (documentation) / with OpenAI-compatible API support
- Monitoring endpoints
- Schema-constrained JSON response format
- Prefilling of assistant messages similar to the Claude API
- Function calling / tool use for ~any model
- Speculative decoding
- Easy-to-use web UI
For the full list of features, please refer to server's changelog
Usage
Common params
| Argument | Explanation |
|---|---|
-h, --help, --usage |
print usage and exit |
--version |
show version and build info |
-cl, --cache-list |
show list of models in cache |
--completion-bash |
print source-able bash completion script for llama.cpp |
-t, --threads N |
number of CPU threads to use during generation (default: -1) (env: LLAMA_ARG_THREADS) |
-tb, --threads-batch N |
number of threads to use during batch and prompt processing (default: same as --threads) |
-C, --cpu-mask M |
CPU affinity mask: arbitrarily long hex. Complements cpu-range (default: "") |
-Cr, --cpu-range lo-hi |
range of CPUs for affinity. Complements --cpu-mask |
--cpu-strict <0|1> |
use strict CPU placement (default: 0) |
--prio N |
set process/thread priority : low(-1), normal(0), medium(1), high(2), realtime(3) (default: 0) |
--poll <0...100> |
use polling level to wait for work (0 - no polling, default: 50) |
-Cb, --cpu-mask-batch M |
CPU affinity mask: arbitrarily long hex. Complements cpu-range-batch (default: same as --cpu-mask) |
-Crb, --cpu-range-batch lo-hi |
ranges of CPUs for affinity. Complements --cpu-mask-batch |
--cpu-strict-batch <0|1> |
use strict CPU placement (default: same as --cpu-strict) |
--prio-batch N |
set process/thread priority : 0-normal, 1-medium, 2-high, 3-realtime (default: 0) |
--poll-batch <0|1> |
use polling to wait for work (default: same as --poll) |
-c, --ctx-size N |
size of the prompt context (default: 0, 0 = loaded from model) (env: LLAMA_ARG_CTX_SIZE) |
-n, --predict, --n-predict N |
number of tokens to predict (default: -1, -1 = infinity) (env: LLAMA_ARG_N_PREDICT) |
-b, --batch-size N |
logical maximum batch size (default: 2048) (env: LLAMA_ARG_BATCH) |
-ub, --ubatch-size N |
physical maximum batch size (default: 512) (env: LLAMA_ARG_UBATCH) |
--keep N |
number of tokens to keep from the initial prompt (default: 0, -1 = all) |
--swa-full |
use full-size SWA cache (default: false) (more info) (env: LLAMA_ARG_SWA_FULL) |
-fa, --flash-attn [on|off|auto] |
set Flash Attention use ('on', 'off', or 'auto', default: 'auto') (env: LLAMA_ARG_FLASH_ATTN) |
--perf, --no-perf |
whether to enable internal libllama performance timings (default: false) (env: LLAMA_ARG_PERF) |
-e, --escape, --no-escape |
whether to process escapes sequences (\n, \r, \t, ', ", \) (default: true) |
--rope-scaling {none,linear,yarn} |
RoPE frequency scaling method, defaults to linear unless specified by the model (env: LLAMA_ARG_ROPE_SCALING_TYPE) |
--rope-scale N |
RoPE context scaling factor, expands context by a factor of N (env: LLAMA_ARG_ROPE_SCALE) |
--rope-freq-base N |
RoPE base frequency, used by NTK-aware scaling (default: loaded from model) (env: LLAMA_ARG_ROPE_FREQ_BASE) |
--rope-freq-scale N |
RoPE frequency scaling factor, expands context by a factor of 1/N (env: LLAMA_ARG_ROPE_FREQ_SCALE) |
--yarn-orig-ctx N |
YaRN: original context size of model (default: 0 = model training context size) (env: LLAMA_ARG_YARN_ORIG_CTX) |
--yarn-ext-factor N |
YaRN: extrapolation mix factor (default: -1.00, 0.0 = full interpolation) (env: LLAMA_ARG_YARN_EXT_FACTOR) |
--yarn-attn-factor N |
YaRN: scale sqrt(t) or attention magnitude (default: -1.00) (env: LLAMA_ARG_YARN_ATTN_FACTOR) |
--yarn-beta-slow N |
YaRN: high correction dim or alpha (default: -1.00) (env: LLAMA_ARG_YARN_BETA_SLOW) |
--yarn-beta-fast N |
YaRN: low correction dim or beta (default: -1.00) (env: LLAMA_ARG_YARN_BETA_FAST) |
-kvo, --kv-offload, -nkvo, --no-kv-offload |
whether to enable KV cache offloading (default: enabled) (env: LLAMA_ARG_KV_OFFLOAD) |
--repack, -nr, --no-repack |
whether to enable weight repacking (default: enabled) (env: LLAMA_ARG_REPACK) |
--no-host |
bypass host buffer allowing extra buffers to be used (env: LLAMA_ARG_NO_HOST) |
-ctk, --cache-type-k TYPE |
KV cache data type for K allowed values: f32, f16, bf16, q8_0, q4_0, q4_1, iq4_nl, q5_0, q5_1 (default: f16) (env: LLAMA_ARG_CACHE_TYPE_K) |
-ctv, --cache-type-v TYPE |
KV cache data type for V allowed values: f32, f16, bf16, q8_0, q4_0, q4_1, iq4_nl, q5_0, q5_1 (default: f16) (env: LLAMA_ARG_CACHE_TYPE_V) |
-dt, --defrag-thold N |
KV cache defragmentation threshold (DEPRECATED) (env: LLAMA_ARG_DEFRAG_THOLD) |
--rpc SERVERS |
comma-separated list of RPC servers (host:port) (env: LLAMA_ARG_RPC) |
-lm, --load-mode MODE |
model loading mode (default: auto) - auto: mmap, unless a device does not support it - none: no special loading mode - mmap: memory-map model (if mmap disabled, slower load but may reduce pageouts if not using mlock) - mlock: force system to keep model in RAM rather than swapping or compressing - mmap+mlock: mmap + force system to keep model in RAM rather than swapping or compressing - dio: use DirectIO if available (env: LLAMA_ARG_LOAD_MODE) |
-lzm, --lazy-mode MODE |
on-demand reading of certain tensors, for example per-layer embeddings (default: auto) - on: read the rows of such tensors from disk on demand instead of keeping them resident (requires mmap) - auto: on, but only for tensors larger than 4 GiB - off: always keep them resident (env: LLAMA_ARG_LAZY_MODE) |
--numa TYPE |
attempt optimizations that help on some NUMA systems - distribute: spread execution evenly over all nodes - isolate: only spawn threads on CPUs on the node that execution started on - numactl: use the CPU map provided by numactl if run without this previously, it is recommended to drop the system page cache before using this see https://github.com/ggml-org/llama.cpp/issues/1437 (env: LLAMA_ARG_NUMA) |
-dev, --device <dev1,dev2,..> |
comma-separated list of devices to use for offloading (none = don't offload) use --list-devices to see a list of available devices (env: LLAMA_ARG_DEVICE) |
--list-devices |
print list of available devices and exit |
-ot, --override-tensor <tensor name pattern>=<buffer type>,... |
override tensor buffer type (env: LLAMA_ARG_OVERRIDE_TENSOR) |
-cmoe, --cpu-moe |
keep all Mixture of Experts (MoE) weights in the CPU (env: LLAMA_ARG_CPU_MOE) |
-ncmoe, --n-cpu-moe N |
keep the Mixture of Experts (MoE) weights of the first N layers in the CPU (env: LLAMA_ARG_N_CPU_MOE) |
--moe-cache-mib N |
GPU cache size in MiB for the MoE experts kept in the CPU. with multiple GPUs, it is split among them like the layers (--tensor-split) (default: 0, disabled) (env: LLAMA_ARG_MOE_CACHE_MIB) |
-ncffn, --n-cpu-ffn N |
keep the dense FFN weights of the first N layers in the CPU (dense models; for MoE expert weights use --n-cpu-moe) (env: LLAMA_ARG_N_CPU_FFN) |
-ngl, --gpu-layers, --n-gpu-layers N |
max. number of layers to store in VRAM, either an exact number, 'auto', or 'all' (default: auto) (env: LLAMA_ARG_N_GPU_LAYERS) |
-sm, --split-mode {none,layer,row,tensor} |
how to split the model across multiple GPUs, one of: - none: use one GPU only - layer (default): split layers and KV across GPUs (pipelined) - row: split weight across GPUs by rows (parallelized) - tensor: split weights and KV across GPUs (parallelized, EXPERIMENTAL) (env: LLAMA_ARG_SPLIT_MODE) |
-ts, --tensor-split N0,N1,N2,... |
fraction of the model to offload to each GPU, comma-separated list of proportions, e.g. 3,1 (env: LLAMA_ARG_TENSOR_SPLIT) |
-mg, --main-gpu INDEX |
the GPU to use for the model (with split-mode = none), or for intermediate results and KV (with split-mode = row) (default: 0) (env: LLAMA_ARG_MAIN_GPU) |
-fit, --fit [on|off] |
whether to adjust unset arguments to fit in device memory ('on' or 'off', default: 'on') (env: LLAMA_ARG_FIT) |
-fitt, --fit-target MiB0,MiB1,MiB2,... |
target margin per device for --fit, comma-separated list of values, single value is broadcast across all devices, default: 1024 (env: LLAMA_ARG_FIT_TARGET) |
-fitc, --fit-ctx N |
minimum ctx size that can be set by --fit option, default: 4096 (env: LLAMA_ARG_FIT_CTX) |
--check-tensors |
check model tensor data for invalid values (default: false) |
--override-kv KEY=TYPE:VALUE,... |
advanced option to override model metadata by key. to specify multiple overrides, either use comma-separated values. types: int, float, bool, str. example: --override-kv tokenizer.ggml.add_bos_token=bool:false,tokenizer.ggml.add_eos_token=bool:false |
--op-offload, --no-op-offload |
whether to offload host tensor operations to device (default: true) |
--lora FNAME |
path to LoRA adapter (use comma-separated values to load multiple adapters) |
--lora-scaled FNAME:SCALE,... |
path to LoRA adapter with user defined scaling (format: FNAME:SCALE,...) note: use comma-separated values |
--control-vector FNAME |
add a control vector note: use comma-separated values to add multiple control vectors |
--control-vector-scaled FNAME:SCALE,... |
add a control vector with user defined scaling SCALE note: use comma-separated values (format: FNAME:SCALE,...) |
--control-vector-layer-range START END |
layer range to apply the control vector(s) to, start and end inclusive |
-m, --model FNAME |
model path to load (env: LLAMA_ARG_MODEL) |
-mu, --model-url MODEL_URL |
model download url (default: unused) (env: LLAMA_ARG_MODEL_URL) |
-dr, --docker-repo [<repo>/]<model>[:quant] |
Docker Hub model repository. repo is optional, default to ai/. quant is optional, default to :latest. example: gemma3 (default: unused) (env: LLAMA_ARG_DOCKER_REPO) |
-hf, -hfr, --hf-repo <user>/<model>[:quant] |
Hugging Face model repository; quant is optional, case-insensitive, default to Q4_K_M, or falls back to the first file in the repo if Q4_K_M doesn't exist. mmproj is also downloaded automatically if available. to disable, add --no-mmproj example: ggml-org/GLM-4.7-Flash-GGUF:Q4_K_M (default: unused) (env: LLAMA_ARG_HF_REPO) |
-hff, --hf-file FILE |
Hugging Face model file. If specified, it will override the quant in --hf-repo (default: unused) (env: LLAMA_ARG_HF_FILE) |
-hft, --hf-token TOKEN |
Hugging Face access token (default: value from HF_TOKEN environment variable) (env: HF_TOKEN) |
--log-disable |
Log disable |
--log-file FNAME |
Log to file (env: LLAMA_ARG_LOG_FILE) |
--log-jsonl, --no-log-jsonl |
Log as JSONL (one JSON object per line) to stdout, this also disables colored logging (default: disabled) (env: LLAMA_ARG_LOG_JSONL) |
--log-colors [on|off|auto] |
Set colored logging ('on', 'off', or 'auto', default: 'auto') 'auto' enables colors when output is to a terminal (env: LLAMA_ARG_LOG_COLORS) |
-v, --verbose, --log-verbose |
Set verbosity level to infinity (i.e. log all messages, useful for debugging) |
--offline |
Offline mode: forces use of cache, prevents network access (env: LLAMA_ARG_OFFLINE) |
-lv, --verbosity, --log-verbosity N |
Set the verbosity threshold. Messages with a higher verbosity will be ignored. Values: - 0: generic output - 1: error - 2: warning - 3: info - 4: trace (more info) - 5: debug (default: 3) (env: LLAMA_ARG_LOG_VERBOSITY) |
--log-prefix, --no-log-prefix |
Enable prefix in log messages (env: LLAMA_ARG_LOG_PREFIX) |
--log-timestamps, --no-log-timestamps |
Enable timestamps in log messages (env: LLAMA_ARG_LOG_TIMESTAMPS) |
--spec-draft-type-k, -ctkd, --cache-type-k-draft TYPE |
KV cache data type for K for the draft model allowed values: f32, f16, bf16, q8_0, q4_0, q4_1, iq4_nl, q5_0, q5_1 (default: f16) (env: LLAMA_ARG_SPEC_DRAFT_CACHE_TYPE_K) |
--spec-draft-type-v, -ctvd, --cache-type-v-draft TYPE |
KV cache data type for V for the draft model allowed values: f32, f16, bf16, q8_0, q4_0, q4_1, iq4_nl, q5_0, q5_1 (default: f16) (env: LLAMA_ARG_SPEC_DRAFT_CACHE_TYPE_V) |
Sampling params
| Argument | Explanation |
|---|---|
--samplers SAMPLERS |
samplers that will be used for generation in the order, separated by ';' (default: penalties;dry;top_n_sigma;top_k;typ_p;top_p;min_p;xtc;temperature) |
-s, --seed SEED |
RNG seed (default: -1, use random seed for -1) |
--sampler-seq, --sampling-seq SEQUENCE |
simplified sequence for samplers that will be used (default: edskypmxt) |
--ignore-eos |
ignore end of stream token and continue generating (implies --logit-bias EOS-inf) |
--temp, --temperature N |
temperature (default: 0.80) (env: LLAMA_ARG_TEMPERATURE) |
--top-k N |
top-k sampling (default: 40, 0 = disabled) (env: LLAMA_ARG_TOP_K) |
--top-p N |
top-p sampling (default: 0.95, 1.0 = disabled) (env: LLAMA_ARG_TOP_P) |
--min-p N |
min-p sampling (default: 0.05, 0.0 = disabled) (env: LLAMA_ARG_MIN_P) |
--top-nsigma, --top-n-sigma N |
top-n-sigma sampling (default: -1.00, -1.0 = disabled) |
--xtc-probability N |
xtc probability (default: 0.00, 0.0 = disabled) |
--xtc-threshold N |
xtc threshold (default: 0.10, 1.0 = disabled) |
--typical, --typical-p N |
locally typical sampling, parameter p (default: 1.00, 1.0 = disabled) |
--repeat-last-n N |
last n tokens to consider for penalize (default: 64, 0 = disabled) |
--repeat-penalty N |
penalize repeat sequence of tokens (default: 1.00, 1.0 = disabled) (env: LLAMA_ARG_REPEAT_PENALTY) |
--presence-penalty N |
repeat alpha presence penalty (default: 0.00, 0.0 = disabled) (env: LLAMA_ARG_PRESENCE_PENALTY) |
--frequency-penalty N |
repeat alpha frequency penalty (default: 0.00, 0.0 = disabled) (env: LLAMA_ARG_FREQUENCY_PENALTY) |
--dry-multiplier N |
set DRY sampling multiplier (default: 0.00, 0.0 = disabled) |
--dry-base N |
set DRY sampling base value (default: 1.75) |
--dry-allowed-length N |
set allowed length for DRY sampling (default: 2) |
--dry-penalty-last-n N |
set DRY penalty for the last n tokens (default: 64, 0 = disable) |
--dry-sequence-breaker STRING |
add sequence breaker for DRY sampling, clearing out default breakers ('\n', ':', '"', '*') in the process; use "none" to not use any sequence breakers |
--adaptive-target N |
adaptive-p: select tokens near this probability (valid range 0.0 to 1.0; negative = disabled) (default: -1.00) (more info) |
--adaptive-decay N |
adaptive-p: decay rate for target adaptation over time. lower values are more reactive, higher values are more stable. (valid range 0.0 to 0.99) (default: 0.90) |
--dynatemp-range N |
dynamic temperature range (default: 0.00, 0.0 = disabled) |
--dynatemp-exp N |
dynamic temperature exponent (default: 1.00) |
--mirostat N |
use Mirostat sampling. Top K, Nucleus and Locally Typical samplers are ignored if used. (default: 0, 0 = disabled, 1 = Mirostat, 2 = Mirostat 2.0) |
--mirostat-lr N |
Mirostat learning rate, parameter eta (default: 0.10) |
--mirostat-ent N |
Mirostat target entropy, parameter tau (default: 5.00) |
-l, --logit-bias TOKEN_ID(+/-)BIAS |
modifies the likelihood of token appearing in the completion, i.e. --logit-bias 15043+1 to increase likelihood of token ' Hello',or --logit-bias 15043-1 to decrease likelihood of token ' Hello' |
--grammar GRAMMAR |
BNF-like grammar to constrain generations (see samples in grammars/ dir) |
--grammar-file FNAME |
file to read grammar from |
-j, --json-schema SCHEMA |
JSON schema to constrain generations (https://json-schema.org/), e.g. {"type": "object"} for any JSON object |
-jf, --json-schema-file FILE |
File containing a JSON schema to constrain generations (https://json-schema.org/), e.g. {"type": "object"} for any JSON object |
-bs, --backend-sampling |
enable backend sampling (experimental) (default: disabled) (env: LLAMA_ARG_BACKEND_SAMPLING) |
Server-specific params
| Argument | Explanation |
|---|---|
-lcs, --lookup-cache-static FNAME |
path to static lookup cache to use for lookup decoding (not updated by generation) |
-lcd, --lookup-cache-dynamic FNAME |
path to dynamic lookup cache to use for lookup decoding (updated by generation) |
--kv-unified-per-slot N |
context limit per parallel slot (default: unset, behavior unchanged). when set without -c/--ctx-size, the shared KV pool is sized to n_parallel*N (env: LLAMA_ARG_KV_UNIFIED_PER_SLOT) |
-ctxcp, --ctx-checkpoints, --swa-checkpoints N |
max number of context checkpoints to create per slot (default: 32)(more info) (env: LLAMA_ARG_CTX_CHECKPOINTS) |
-cms, --checkpoint-min-step N |
minimum spacing between context checkpoints in tokens (default: 8192, 0 = no minimum) (env: LLAMA_ARG_CHECKPOINT_MIN_SPACING_NT) |
-cram, --cache-ram N |
set the maximum cache size in MiB (default: 8192, 0 for decision models, -1 - no limit, 0 - disable)(more info) (env: LLAMA_ARG_CACHE_RAM) |
-kvu, --kv-unified, -no-kvu, --no-kv-unified |
use single unified KV buffer shared across all sequences (default: enabled if number of slots is auto) (env: LLAMA_ARG_KV_UNIFIED) |
--cache-idle-slots, --no-cache-idle-slots |
save idle slots to the prompt cache on new task, and clear them when using unified KV (default: enabled, requires cache-ram) (env: LLAMA_ARG_CACHE_IDLE_SLOTS) |
--context-shift, --no-context-shift |
whether to use context shift on infinite text generation (default: disabled) (env: LLAMA_ARG_CONTEXT_SHIFT) |
-r, --reverse-prompt PROMPT |
halt generation at PROMPT, return control in interactive mode |
-sp, --special |
special tokens output enabled (default: false) |
--warmup, --no-warmup |
whether to perform warmup with an empty run (default: enabled) |
--spm-infill |
use Suffix/Prefix/Middle pattern for infill (instead of Prefix/Suffix/Middle) as some models prefer this. (default: disabled) |
--pooling {none,mean,cls,last,rank} |
pooling type for embeddings, use model default if unspecified (env: LLAMA_ARG_POOLING) |
-np, --parallel N |
number of server slots (default: -1, -1 = auto) (env: LLAMA_ARG_N_PARALLEL) |
-cb, --cont-batching, -nocb, --no-cont-batching |
whether to enable continuous batching (a.k.a dynamic batching) (default: enabled) (env: LLAMA_ARG_CONT_BATCHING) |
-mm, --mmproj FILE |
path to a multimodal projector file. see tools/mtmd/README.md note: if -hf is used, this argument can be omitted (env: LLAMA_ARG_MMPROJ) |
-mmu, --mmproj-url URL |
URL to a multimodal projector file. see tools/mtmd/README.md (env: LLAMA_ARG_MMPROJ_URL) |
--mmproj-auto, --no-mmproj, --no-mmproj-auto |
whether to use multimodal projector file (if available), useful when using -hf (default: enabled) (env: LLAMA_ARG_MMPROJ_AUTO) |
--mmproj-offload, --no-mmproj-offload |
whether to enable GPU offloading for multimodal projector (default: enabled) (env: LLAMA_ARG_MMPROJ_OFFLOAD) |
-mmdev, --mmproj-device DEVICE |
device to use for multimodal projector (none = don't offload, default: follows --device) use --list-devices to see a list of available devices (env: MTMD_BACKEND_DEVICE) |
--image-min-tokens N |
minimum number of tokens each image can take, only used by vision models with dynamic resolution (default: read from model) (env: LLAMA_ARG_IMAGE_MIN_TOKENS) |
--image-max-tokens N |
maximum number of tokens each image can take, only used by vision models with dynamic resolution (default: read from model) (env: LLAMA_ARG_IMAGE_MAX_TOKENS) |
--mtmd-batch-max-tokens N |
maximum number of image tokens per batch when encoding images (default: 1024) (env: LLAMA_ARG_MTMD_BATCH_MAX_TOKENS) |
--video-fps N |
target video frame rate (default: 4.0) (env: LLAMA_ARG_VIDEO_FPS) |
--video-timestamp-interval N |
interval in milliseconds between text timestamps (default: 5000) (env: LLAMA_ARG_VIDEO_TIMESTAMP_INTERVAL) |
--video-ffmpeg-dir DIR |
path to the directory containing ffmpeg and ffprobe (default: search in PATH) (env: LLAMA_ARG_VIDEO_FFMPEG_DIR) |
-a, --alias STRING |
set model name aliases, comma-separated (to be used by API) (env: LLAMA_ARG_ALIAS) |
--tags STRING |
set model tags, comma-separated (informational, not used for routing) (env: LLAMA_ARG_TAGS) |
--embd-normalize N |
normalisation for embeddings (default: 2) (-1=none, 0=max absolute int16, 1=taxicab, 2=euclidean, >2=p-norm) |
--host HOST |
IP addresses to listen on, comma-separated, or UNIX socket paths ending in .sock; with multiple TCP addresses, :: binds IPv6 only; overlapping addresses result in undefined behavior (default: 127.0.0.1) (env: LLAMA_ARG_HOST) |
--port PORT |
port to listen (default: 9931) (env: LLAMA_ARG_PORT) |
--reuse-port |
allow multiple sockets to bind to the same port (default: disabled) (env: LLAMA_ARG_REUSE_PORT) |
--path PATH |
path to serve static files from (default: ) (env: LLAMA_ARG_STATIC_PATH) |
--cors-origins ORIGINS |
comma-separated list of allowed origins for CORS (default: *) if set to special value 'localhost', reflect the Origin header only if it is localhost (env: LLAMA_ARG_CORS_ORIGINS) |
--cors-methods METHODS |
comma-separated list of allowed methods for CORS (default: GET, POST, DELETE, OPTIONS) (env: LLAMA_ARG_CORS_METHODS) |
--cors-headers HEADERS |
comma-separated list of allowed headers for CORS (default: *) (env: LLAMA_ARG_CORS_HEADERS) |
--cors-credentials, --no-cors-credentials |
whether to allow credentials for CORS (default: enabled) note: if this is enabled and --cors-origins is set to * (default), the Origin header will be echoed back, and credentials will always be allowed (env: LLAMA_ARG_CORS_CREDENTIALS) |
--api-prefix PREFIX |
prefix path the server serves from, without the trailing slash (default: ) (env: LLAMA_ARG_API_PREFIX) |
--ui-config, --webui-config JSON |
JSON that provides default UI settings (overrides UI defaults) (env: LLAMA_ARG_UI_CONFIG) |
--ui-config-file, --webui-config-file PATH |
JSON file that provides default UI settings (overrides UI defaults) (env: LLAMA_ARG_UI_CONFIG_FILE) |
--ui-mcp-proxy, --webui-mcp-proxy, --no-ui-mcp-proxy, --no-webui-mcp-proxy |
experimental: whether to enable MCP CORS proxy - do not enable in untrusted environments (default: disabled) (env: LLAMA_ARG_UI_MCP_PROXY) |
--tools TOOL1,TOOL2,... |
experimental: whether to enable built-in tools for AI agents - do not enable in untrusted environments (default: no tools) specify "all" to enable all tools available tools: read_file, file_glob_search, grep_search, exec_shell_command, write_file, edit_file, get_info note: for security reasons, this will limit --cors-origins to localhost by default (env: LLAMA_ARG_TOOLS) |
--tools-runtime OPTION |
experimental: run tools in a separate runtime environment (default: none, use host environment) available options: 'docker:', 'podman:': spin up a new container and reuse it for all invocations, clean up on server exit 'docker-container:', 'podman-container:': use an existing container by ID, won't stop on server exit 'ssh:': run tools on a remote POSIX host over SSH, key-based auth and a trusted host key are required (env: LLAMA_ARG_TOOLS_RUNTIME) |
--mcp-servers-config PATH |
experimental: path to JSON file with MCP server definitions (Cursor-compatible format) - do not enable in untrusted environments (default: none) note: for security reasons, this will limit --cors-origins to localhost by default (env: LLAMA_ARG_MCP_SERVERS_CONFIG) |
--mcp-servers-json JSON |
experimental: inline JSON with MCP server definitions (Cursor-compatible format) - do not enable in untrusted environments (default: none) note: for security reasons, this will limit --cors-origins to localhost by default (env: LLAMA_ARG_MCP_SERVERS_JSON) |
-ag, --agent, -no-ag, --no-agent |
whether to enable CORS proxy and all built-in tools - do not enable in untrusted environments (default: disabled) note: for security reasons, this will limit --cors-origins to localhost by default (env: LLAMA_ARG_AGENT) |
--ui, --webui, --no-ui, --no-webui |
whether to enable the Web UI (default: enabled) (env: LLAMA_ARG_UI) |
--embedding, --embeddings |
restrict to only support embedding use case; use only with dedicated embedding models (default: disabled) (env: LLAMA_ARG_EMBEDDINGS) |
--rerank, --reranking |
enable reranking endpoint on server (default: disabled) (env: LLAMA_ARG_RERANKING) |
--api-key KEY |
API key to use for authentication, multiple keys can be provided as a comma-separated list (default: none) (env: LLAMA_API_KEY) |
--api-key-file FNAME |
path to file containing API keys, one per line; lines starting with a hash are treated as comments (default: none) (env: LLAMA_ARG_API_KEY_FILE) |
--ssl-key-file FNAME |
path to file a PEM-encoded SSL private key (env: LLAMA_ARG_SSL_KEY_FILE) |
--ssl-cert-file FNAME |
path to file a PEM-encoded SSL certificate (env: LLAMA_ARG_SSL_CERT_FILE) |
--chat-template-kwargs STRING |
sets additional params for the json template parser, must be a valid json object string, e.g. '{"key1":"value1","key2":"value2"}' (env: LLAMA_ARG_CHAT_TEMPLATE_KWARGS) |
-to, --timeout N |
server read/write timeout in seconds (default: 3600) (env: LLAMA_ARG_TIMEOUT) |
--sse-ping-interval N |
server SSE ping interval in seconds (-1 = disabled, default: 30) (env: LLAMA_ARG_SSE_PING_INTERVAL) |
--threads-http N |
number of threads used to process HTTP requests (default: -1) (env: LLAMA_ARG_THREADS_HTTP) |
--cache-prompt, --no-cache-prompt |
whether to enable prompt caching (default: enabled) (env: LLAMA_ARG_CACHE_PROMPT) |
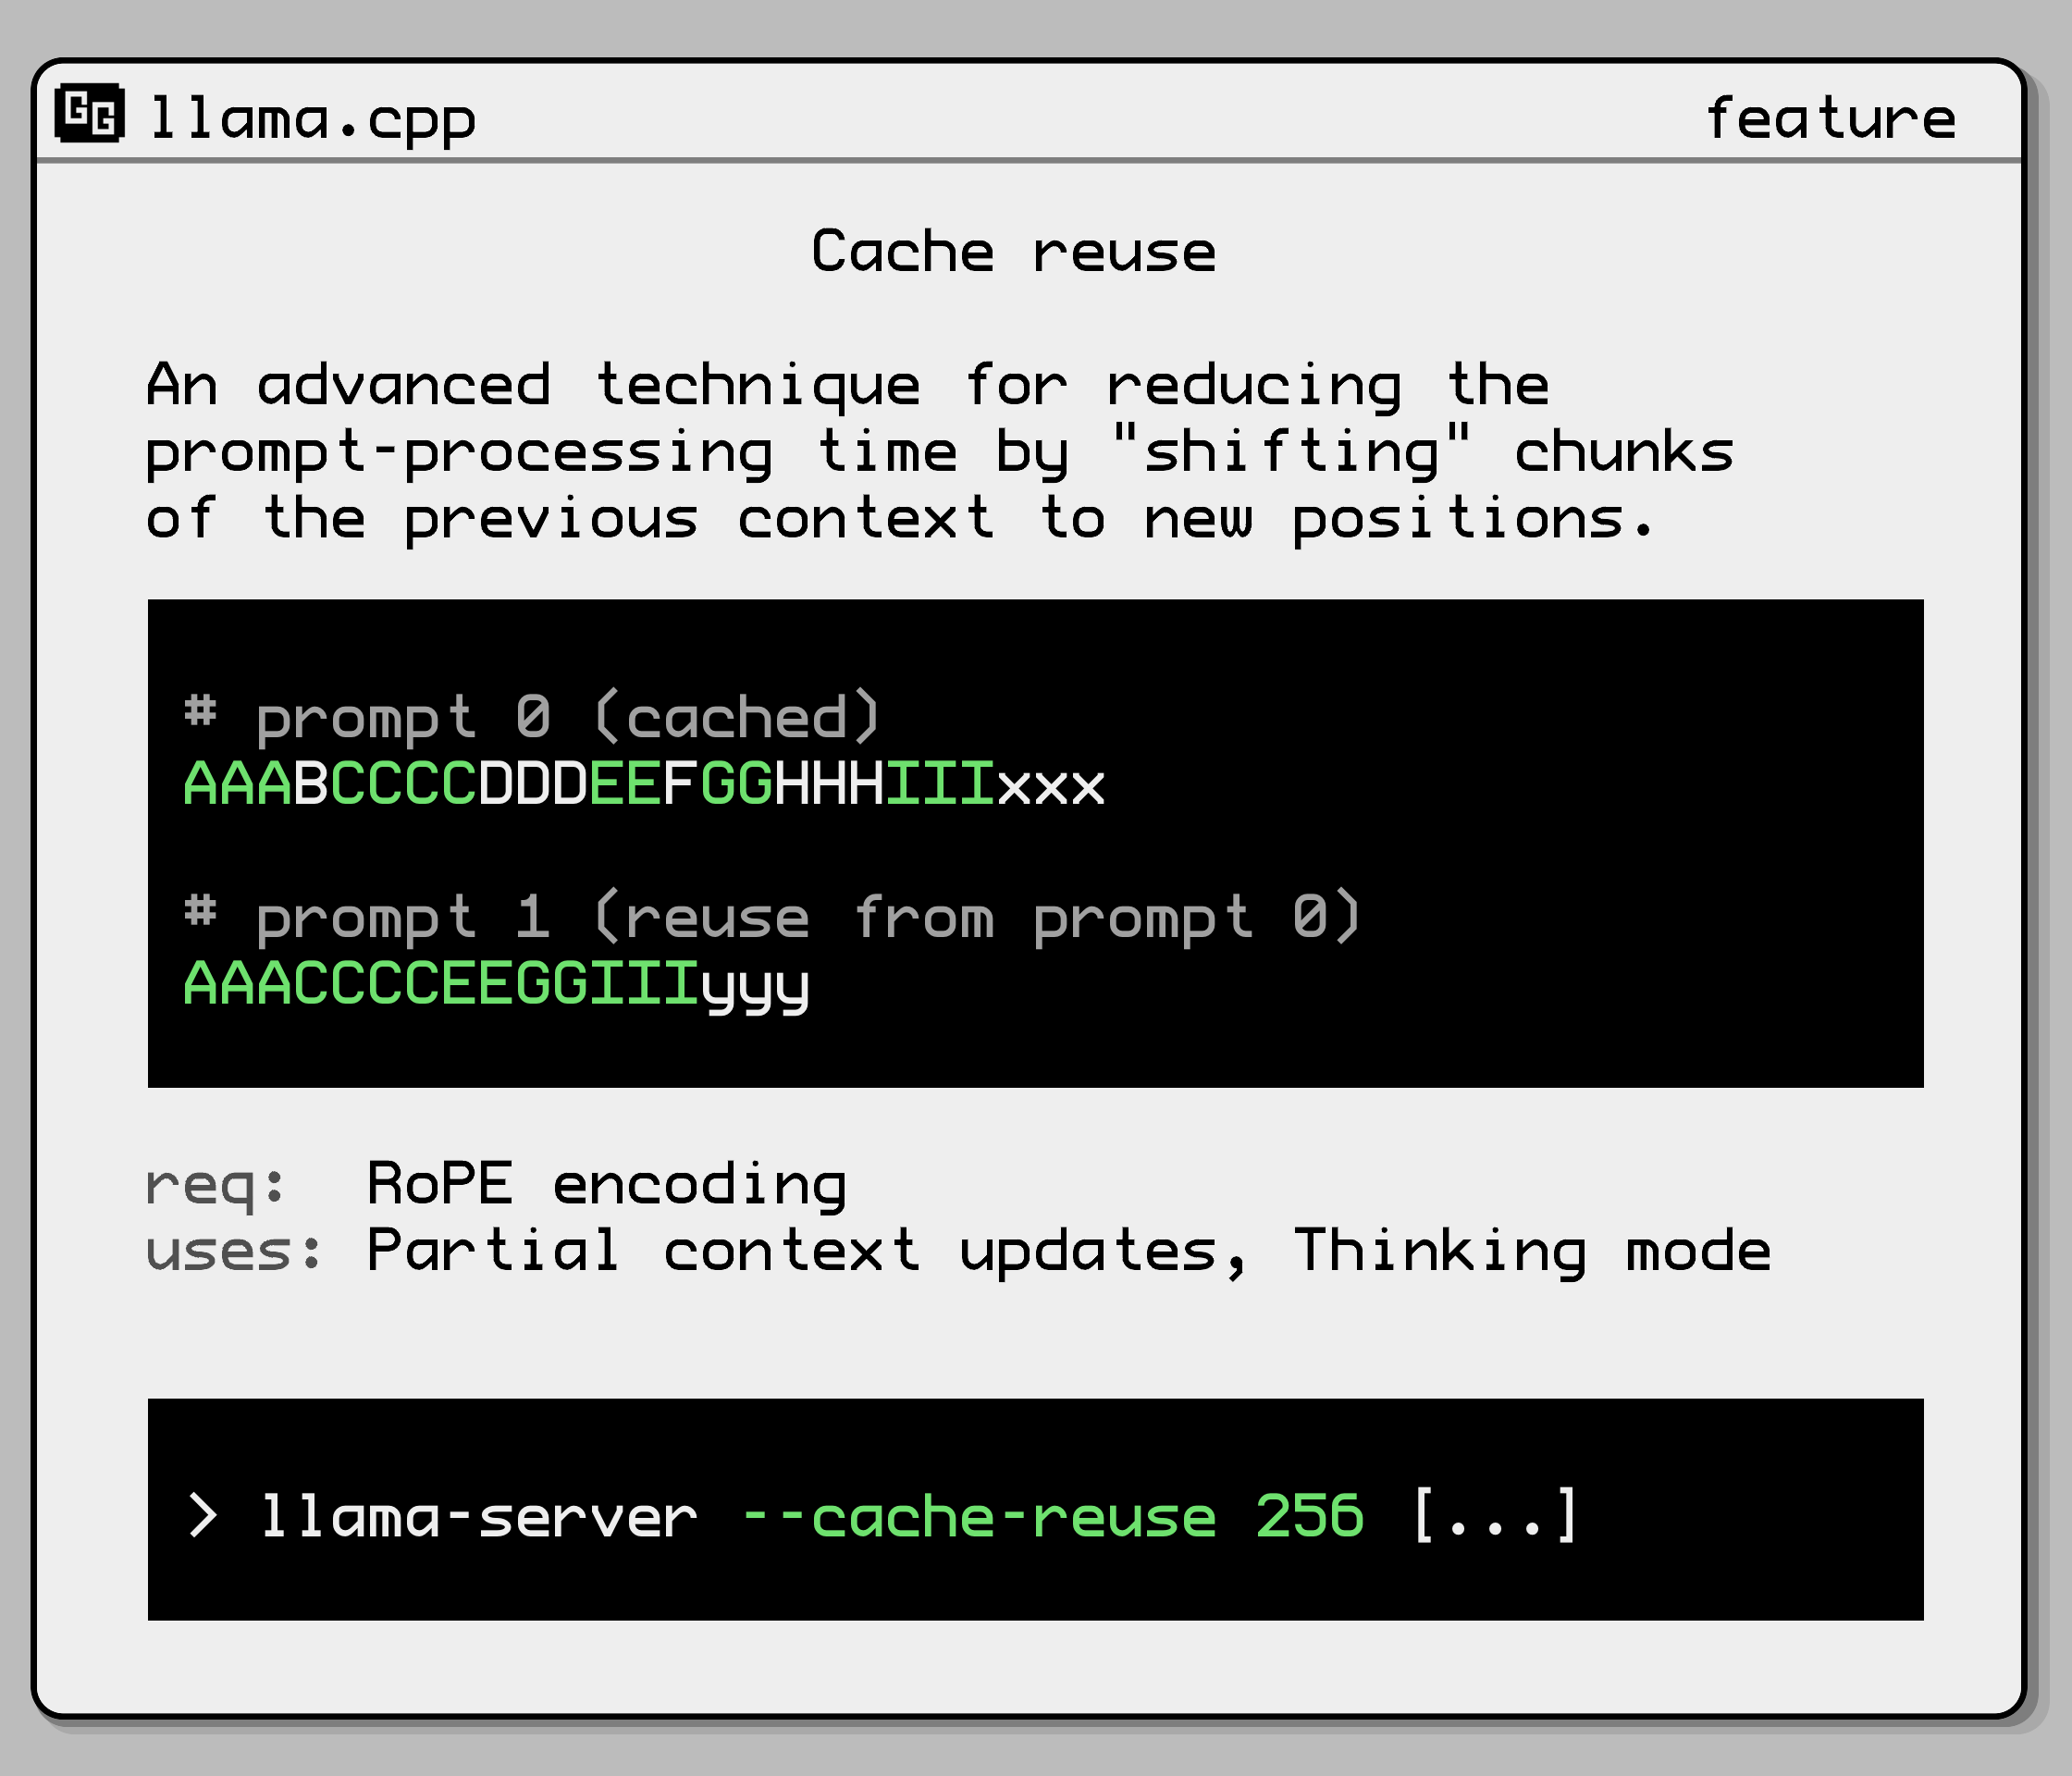
--cache-reuse N |
min chunk size to attempt reusing from the cache via KV shifting, requires prompt caching to be enabled (default: 0) (card) (env: LLAMA_ARG_CACHE_REUSE) |
--metrics |
enable prometheus compatible metrics endpoint (default: disabled) (env: LLAMA_ARG_ENDPOINT_METRICS) |
--props |
enable changing global properties via POST /props (default: disabled) (env: LLAMA_ARG_ENDPOINT_PROPS) |
--slots, --no-slots |
expose slots monitoring endpoint (default: enabled) (env: LLAMA_ARG_ENDPOINT_SLOTS) |
--slot-save-path PATH |
path to save slot kv cache (default: disabled) (env: LLAMA_ARG_SLOT_SAVE_PATH) |
--media-path PATH |
directory for loading local media files; files can be accessed via file:// URLs using relative paths (default: disabled) |
--models-dir PATH |
directory containing models for the router server (default: disabled) (env: LLAMA_ARG_MODELS_DIR) |
--models-preset PATH |
path to INI file containing model presets for the router server (default: disabled) (env: LLAMA_ARG_MODELS_PRESET) |
--models-max N |
for router server, maximum number of models to load simultaneously (default: 4, 0 = unlimited) (env: LLAMA_ARG_MODELS_MAX) |
--models-autoload, --no-models-autoload |
for router server, whether to automatically load models (default: enabled) (env: LLAMA_ARG_MODELS_AUTOLOAD) |
--jinja, --no-jinja |
whether to use jinja template engine for chat (default: enabled) (env: LLAMA_ARG_JINJA) |
--reasoning-format FORMAT |
controls whether thought tags are allowed and/or extracted from the response, and in which format they're returned; one of: - none: leaves thoughts unparsed in message.content- deepseek: puts thoughts in message.reasoning_content- deepseek-legacy: keeps <think> tags in message.content while also populating message.reasoning_content(default: auto) (env: LLAMA_ARG_THINK) |
-rea, --reasoning [on|off|auto] |
Use reasoning/thinking in the chat ('on', 'off', or 'auto', default: 'auto' (detect from template)) (env: LLAMA_ARG_REASONING) |
--reasoning-effort LEVEL |
reasoning effort level given to the chat template: 'default' to keep the template default, or a level such as 'minimal', 'low', 'medium', 'high', 'xhigh' or 'max' (default: default) (env: LLAMA_ARG_REASONING_EFFORT) |
--reasoning-budget N |
token budget for thinking: -1 for unrestricted, 0 for immediate end, N>0 for token budget (default: -1) (env: LLAMA_ARG_THINK_BUDGET) |
--reasoning-budget-message MESSAGE |
message injected before the end-of-thinking tag when reasoning budget is exhausted (default: none) (env: LLAMA_ARG_THINK_BUDGET_MESSAGE) |
--reasoning-preserve, --no-reasoning-preserve |
preserve reasoning trace in the full history, not just the last assistant message (default: enabled) compatible with certain templates having 'supports_preserve_reasoning' capability example: https://docs.z.ai/guides/capabilities/thinking-mode#preserved-thinking (env: LLAMA_ARG_REASONING_PRESERVE) |
--chat-template JINJA_TEMPLATE |
set custom jinja chat template (default: template taken from model's metadata) if suffix/prefix are specified, template will be disabled only commonly used templates are accepted (unless --jinja is set before this flag): list of built-in templates: bailing, bailing-think, bailing2, chatglm3, chatglm4, chatml, command-r, deepseek, deepseek-ocr, deepseek2, deepseek3, exaone-moe, exaone3, exaone4, falcon3, gemma, gigachat, glmedge, gpt-oss, granite, granite-4.0, granite-4.1, grok-2, hunyuan-dense, hunyuan-moe, hunyuan-vl, kimi-k2, llama2, llama2-sys, llama2-sys-bos, llama2-sys-strip, llama3, llama4, megrez, minicpm, mistral-v1, mistral-v3, mistral-v3-tekken, mistral-v7, mistral-v7-tekken, monarch, openchat, orion, pangu-embedded, phi3, phi4, rwkv-world, seed_oss, smolvlm, solar-open, vicuna, vicuna-orca, yandex, zephyr (env: LLAMA_ARG_CHAT_TEMPLATE) |
--chat-template-file JINJA_TEMPLATE_FILE |
set custom jinja chat template file (default: template taken from model's metadata) if suffix/prefix are specified, template will be disabled only commonly used templates are accepted (unless --jinja is set before this flag): list of built-in templates: bailing, bailing-think, bailing2, chatglm3, chatglm4, chatml, command-r, deepseek, deepseek-ocr, deepseek2, deepseek3, exaone-moe, exaone3, exaone4, falcon3, gemma, gigachat, glmedge, gpt-oss, granite, granite-4.0, granite-4.1, grok-2, hunyuan-dense, hunyuan-moe, hunyuan-vl, kimi-k2, llama2, llama2-sys, llama2-sys-bos, llama2-sys-strip, llama3, llama4, megrez, minicpm, mistral-v1, mistral-v3, mistral-v3-tekken, mistral-v7, mistral-v7-tekken, monarch, openchat, orion, pangu-embedded, phi3, phi4, rwkv-world, seed_oss, smolvlm, solar-open, vicuna, vicuna-orca, yandex, zephyr (env: LLAMA_ARG_CHAT_TEMPLATE_FILE) |
--skip-chat-parsing, --no-skip-chat-parsing |
force a pure content parser, even if a Jinja template is specified; model will output everything in the content section, including any reasoning and/or tool calls (default: disabled) (env: LLAMA_ARG_SKIP_CHAT_PARSING) |
--prefill-assistant, --no-prefill-assistant |
whether to prefill the assistant's response if the last message is an assistant message (default: prefill enabled) when this flag is set, if the last message is an assistant message then it will be treated as a full message and not prefilled (env: LLAMA_ARG_PREFILL_ASSISTANT) |
-sps, --slot-prompt-similarity SIMILARITY |
how much the prompt of a request must match the prompt of a slot in order to use that slot (default: 0.10, 0.0 = disabled) |
--lora-init-without-apply |
load LoRA adapters without applying them (apply later via POST /lora-adapters) (default: disabled) |
--sleep-idle-seconds SECONDS |
number of seconds of idleness after which the server will sleep (default: -1; -1 = disabled) |
--log-prompts-dir PATH |
Log prompts to directory (auto-created if not present; only used for debugging, default: disabled) |
--spec-draft-hf, -hfd, -hfrd, --hf-repo-draft <user>/<model>[:quant] |
Same as --hf-repo, but for the draft model (default: unused) (env: LLAMA_ARG_SPEC_DRAFT_HF_REPO) |
--spec-draft-threads, -td, --threads-draft N |
number of threads to use during generation (default: same as --threads) |
--spec-draft-threads-batch, -tbd, --threads-batch-draft N |
number of threads to use during batch and prompt processing (default: same as --threads-draft) |
--spec-draft-cpu-mask, -Cd, --cpu-mask-draft M |
Draft model CPU affinity mask. Complements cpu-range-draft (default: same as --cpu-mask) |
--spec-draft-cpu-range, -Crd, --cpu-range-draft lo-hi |
Ranges of CPUs for affinity. Complements --cpu-mask-draft |
--spec-draft-cpu-strict, --cpu-strict-draft <0|1> |
Use strict CPU placement for draft model (default: same as --cpu-strict) |
--spec-draft-prio, --prio-draft N |
set draft process/thread priority : 0-normal, 1-medium, 2-high, 3-realtime (default: 0) |
--spec-draft-poll, --poll-draft <0|1> |
Use polling to wait for draft model work (default: same as --poll) |
--spec-draft-cpu-mask-batch, -Cbd, --cpu-mask-batch-draft M |
Draft model CPU affinity mask. Complements cpu-range-draft (default: same as --cpu-mask) |
--spec-draft-cpu-strict-batch, --cpu-strict-batch-draft <0|1> |
Use strict CPU placement for draft model (default: --cpu-strict-draft) |
--spec-draft-prio-batch, --prio-batch-draft N |
set draft process/thread priority : 0-normal, 1-medium, 2-high, 3-realtime (default: 0) |
--spec-draft-poll-batch, --poll-batch-draft <0|1> |
Use polling to wait for draft model work (default: --poll-draft) |
--spec-draft-override-tensor, -otd, --override-tensor-draft <tensor name pattern>=<buffer type>,... |
override tensor buffer type for draft model |
--spec-draft-cpu-moe, -cmoed, --cpu-moe-draft |
keep all Mixture of Experts (MoE) weights in the CPU for the draft model (env: LLAMA_ARG_SPEC_DRAFT_CPU_MOE) |
--spec-draft-n-cpu-moe, --spec-draft-ncmoe, -ncmoed, --n-cpu-moe-draft N |
keep the Mixture of Experts (MoE) weights of the first N layers in the CPU for the draft model (env: LLAMA_ARG_SPEC_DRAFT_N_CPU_MOE) |
--spec-draft-n-max N |
number of tokens to draft for speculative decoding (default: 3) (env: LLAMA_ARG_SPEC_DRAFT_N_MAX) |
--spec-draft-n-min N |
minimum number of draft tokens to use for speculative decoding (default: 0) (env: LLAMA_ARG_SPEC_DRAFT_N_MIN) |
--spec-draft-n-ubatch N |
physical maximum batch size of the draft context, use a smaller value to spare VRAM (default: 0 - same as --n-ubatch) (env: LLAMA_ARG_SPEC_DRAFT_N_UBATCH) |
--spec-synth-len L |
target mean synthetic acceptance length, including the target token (benchmarking only) (env: LLAMA_ARG_SPEC_SYNTH_LEN) |
--spec-synth-rates P0,P1,... |
comma-separated unconditional per-position synthetic acceptance probabilities (benchmarking only) (env: LLAMA_ARG_SPEC_SYNTH_RATES) |
--spec-draft-p-split, --draft-p-split P |
speculative decoding split probability (default: 0.10) (env: LLAMA_ARG_SPEC_DRAFT_P_SPLIT) |
--spec-draft-p-min, --draft-p-min P |
minimum speculative decoding probability (greedy) (default: 0.00) (env: LLAMA_ARG_SPEC_DRAFT_P_MIN) |
--spec-draft-backend-sampling, --no-spec-draft-backend-sampling |
offload draft sampling to the backend (default: enabled) (env: LLAMA_ARG_SPEC_DRAFT_BACKEND_SAMPLING) |
--spec-draft-sampling {greedy,probabilistic} |
how the draft is sampled: greedy takes its argmax, probabilistic samples it and has the target verify by rejection sampling (default: greedy) (env: LLAMA_ARG_SPEC_DRAFT_SAMPLING) |
--spec-draft-device, -devd, --device-draft <dev1,dev2,..> |
comma-separated list of devices to use for offloading the draft model (none = don't offload, default: follows --device) use --list-devices to see a list of available devices |
--spec-draft-ngl, -ngld, --gpu-layers-draft, --n-gpu-layers-draft N |
max. number of draft model layers to store in VRAM, either an exact number, 'auto', or 'all' (default: auto) (env: LLAMA_ARG_N_GPU_LAYERS_DRAFT) |
--spec-draft-model, -md, --model-draft FNAME |
draft model for speculative decoding (default: unused) (env: LLAMA_ARG_SPEC_DRAFT_MODEL) |
--spec-type none,draft-simple,draft-eagle3,draft-mtp,draft-dflash,draft-dspark,ngram-simple,ngram-map-k,ngram-map-k4v,ngram-mod,ngram-cache |
comma-separated list of types of speculative decoding to use (default: none) (env: LLAMA_ARG_SPEC_TYPE) |
--spec-ngram-mod-n-min N |
minimum number of ngram tokens to use for ngram-based speculative decoding (default: 48) |
--spec-ngram-mod-n-max N |
maximum number of ngram tokens to use for ngram-based speculative decoding (default: 64) |
--spec-ngram-mod-n-match N |
ngram-mod lookup length (default: 24) |
--spec-ngram-simple-size-n N |
ngram size N for ngram-simple speculative decoding, length of lookup n-gram (default: 12) |
--spec-ngram-simple-size-m N |
ngram size M for ngram-simple speculative decoding, length of draft m-gram (default: 48) |
--spec-ngram-simple-min-hits N |
minimum hits for ngram-simple speculative decoding (default: 1) |
--spec-ngram-map-k-size-n N |
ngram size N for ngram-map-k speculative decoding, length of lookup n-gram (default: 12) |
--spec-ngram-map-k-size-m N |
ngram size M for ngram-map-k speculative decoding, length of draft m-gram (default: 48) |
--spec-ngram-map-k-min-hits N |
minimum hits for ngram-map-k speculative decoding (default: 1) |
--spec-ngram-map-k4v-size-n N |
ngram size N for ngram-map-k4v speculative decoding, length of lookup n-gram (default: 12) |
--spec-ngram-map-k4v-size-m N |
ngram size M for ngram-map-k4v speculative decoding, length of draft m-gram (default: 48) |
--spec-ngram-map-k4v-min-hits N |
minimum hits for ngram-map-k4v speculative decoding (default: 1) |
--draft, --draft-n, --draft-max N |
the argument has been removed. use --spec-draft-n-max or --spec-ngram-mod-n-max (env: LLAMA_ARG_DRAFT_MAX) |
--draft-min, --draft-n-min N |
the argument has been removed. use --spec-draft-n-min or --spec-ngram-mod-n-min (env: LLAMA_ARG_DRAFT_MIN) |
--spec-ngram-size-n N |
the argument has been removed. use the respective --spec-ngram-*-size-n or --spec-ngram-mod-n-match |
--spec-ngram-size-m N |
the argument has been removed. use the respective --spec-ngram-*-size-m |
--spec-ngram-min-hits N |
the argument has been removed. use the respective --spec-ngram-*-min-hits |
--embd-gemma-default |
use default EmbeddingGemma model (note: can download weights from the internet) |
--fim-qwen-1.5b-default |
use default Qwen 2.5 Coder 1.5B (note: can download weights from the internet) |
--fim-qwen-3b-default |
use default Qwen 2.5 Coder 3B (note: can download weights from the internet) |
--fim-qwen-7b-default |
use default Qwen 2.5 Coder 7B (note: can download weights from the internet) |
--fim-qwen-7b-spec |
use Qwen 2.5 Coder 7B + 0.5B draft for speculative decoding (note: can download weights from the internet) |
--fim-qwen-14b-spec |
use Qwen 2.5 Coder 14B + 0.5B draft for speculative decoding (note: can download weights from the internet) |
--fim-qwen-30b-default |
use default Qwen 3 Coder 30B A3B Instruct (note: can download weights from the internet) |
--gpt-oss-20b-default |
use gpt-oss-20b (note: can download weights from the internet) |
--gpt-oss-120b-default |
use gpt-oss-120b (note: can download weights from the internet) |
--vision-gemma-4b-default |
use Gemma 3 4B QAT (note: can download weights from the internet) |
--vision-gemma-12b-default |
use Gemma 3 12B QAT (note: can download weights from the internet) |
--spec-default |
enable default speculative decoding config |
Note: If both command line argument and environment variable are both set for the same param, the argument will take precedence over env var.
For string options like --load-mode, the environment variable is handled as shown in this example:
LLAMA_ARG_LOAD_MODE=autosets the loading mode to auto (default)LLAMA_ARG_LOAD_MODE=nonedisables special loadingLLAMA_ARG_LOAD_MODE=mmapenables memory-mappingLLAMA_ARG_LOAD_MODE=mlocklocks the model in RAMLLAMA_ARG_LOAD_MODE=mmap+mlockenables memory-mapping and locks in RAMLLAMA_ARG_LOAD_MODE=diouses DirectIO if available
For boolean options like --kv-offload:
LLAMA_ARG_KV_OFFLOAD=truemeans enabled, other accepted values are:1,on,enabledLLAMA_ARG_KV_OFFLOAD=falsemeans disabled, other accepted values are:0,off,disabled
Example usage of docker compose with environment variables:
services:
  llamacpp-server:
    image: ghcr.io/ggml-org/llama.cpp:server
    ports:
      - 8080:8080
    volumes:
      - ./models:/models
    environment:
      # alternatively, you can use "LLAMA_ARG_MODEL_URL" to download the model
      LLAMA_ARG_MODEL: /models/my_model.gguf
      LLAMA_ARG_CTX_SIZE: 4096
      LLAMA_ARG_N_PARALLEL: 2
      LLAMA_ARG_ENDPOINT_METRICS: 1
      LLAMA_ARG_PORT: 8080
Multimodal support
Multimodal support was added in #12898 and is currently an experimental feature. It is currently available in the following endpoints:
- The OAI-compatible chat endpoint.
- The non-OAI-compatible completions endpoint.
- The non-OAI-compatible embeddings endpoint.
For more details, please refer to multimodal documentation
Server tools support
The server includes a set of server tools that enable the LLM to access the local file system directly from the Web UI.
To use this feature, start the server with --tools all. You can also enable only specific tools by passing a comma-separated list: --tools name1,name2,.... Run --help for the full list of available tool names.
MCP servers
Besides the built-in tools, the server can expose tools coming from MCP servers, added in #26062. Only the stdio transport is supported: such a server is a child process reading JSON-RPC messages on its stdin and writing replies on its stdout, so nothing has to be started or maintained outside llama-server.
Servers are declared in a Cursor-compatible JSON file:
{
  "mcpServers": {
    "example": { "command": "/path/to/server", "args": [] }
  }
}
llama-server -m model.gguf --mcp-servers-config mcp.json
The same JSON can be passed inline with --mcp-servers-json. Each entry under mcpServers accepts:
| Key | Explanation |
|---|---|
command |
executable to spawn, required, entries without it are skipped |
args |
array of arguments |
env |
object merged over the parent environment |
cwd |
working directory of the child process |
timeout_ms |
per-tool-call timeout (default: 30000) |
Every server is spawned once at startup to list its tools, then stopped, and respawned on demand when one of its tools is called. Tools are exposed as <server>_<tool> alongside the built-in ones: they show up in the Web UI and in GET /tools, and the model calls them like any other tool. A name colliding with an already registered tool is skipped. This is independent of --tools, MCP servers can be the only tools available.
The child process runs with the same privileges as the server, so only declare commands you trust. As with --tools, --cors-origins then defaults to localhost.
Note: --ui-mcp-proxy is unrelated, it only lets the Web UI reach remote MCP servers from the browser.
Any server written against the MCP specification works as is, whether it uses an official SDK or not: the transport is one JSON-RPC message per line on stdio, so a script wrapping an existing program is a valid server too.
CORS
By default the server reflects any Origin header back with credentials allowed. This matches the old, always-on * behavior and is fine as long as the server only exposes stateless, read-only endpoints.
Enabling --tools or --agent exposes file read/write over the API, so in that case --cors-origins defaults to localhost instead: only pages served from localhost can reach the server. Pass --cors-origins explicitly to override either default.
Recommended --cors-origins setting, depending on where the server runs:
| Deployment | Recommendation |
|---|---|
| Public | set an API key, put the server behind a reverse proxy, --cors-origins optional |
| Local network | set --cors-origins to your frontend's origin |
| Same machine | --cors-origins localhost (default once --agent is set) |
Related flags: --cors-origins, --cors-methods, --cors-headers, --cors-credentials / --no-cors-credentials. Background and rationale: #25655.
Running behind a proxy
If your host reaches the internet through a corporate proxy, export HTTP_PROXY and HTTPS_PROXY before running commands that download models (e.g. export HTTPS_PROXY=http://proxy.example.com:8080). Hosts listed in NO_PROXY and loopback addresses are contacted directly.
Build
llama-server is built alongside everything else from the root of the project
-
Using
CMake:cmake -B build cmake --build build --config Release -t llama-serverBinary is at
./build/bin/llama-server
Build with SSL
llama-server can also be built with SSL support using OpenSSL 3
-
Using
CMake:cmake -B build -DLLAMA_OPENSSL=ON cmake --build build --config Release -t llama-server
Quick Start
To get started right away, run the following command, making sure to use the correct path for the model you have:
Unix-based systems (Linux, macOS, etc.)
./llama-server -m models/7B/ggml-model.gguf -c 2048
Windows
llama-server.exe -m models\7B\ggml-model.gguf -c 2048
The above command will start a server that by default listens on 127.0.0.1:9931.
You can consume the endpoints with Postman or NodeJS with axios library. You can visit the web front end at the same url.
Docker
docker run -p 8080:8080 -v /path/to/models:/models ghcr.io/ggml-org/llama.cpp:server -m models/7B/ggml-model.gguf -c 512 --host 0.0.0.0 --port 8080

# or, with CUDA:
docker run -p 8080:8080 -v /path/to/models:/models --gpus all ghcr.io/ggml-org/llama.cpp:server-cuda -m models/7B/ggml-model.gguf -c 512 --host 0.0.0.0 --port 8080 --n-gpu-layers 99
Using with CURL
Using curl. On Windows, curl.exe should be available in the base OS.
curl --request POST \
    --url http://localhost:9931/completion \
    --header "Content-Type: application/json" \
    --data '{"prompt": "Building a website can be done in 10 simple steps:","n_predict": 128}'
API Endpoints
GET /health: Returns health check result
This endpoint is public (no API key check). /v1/health also works.
Response format
- HTTP status code 503
- Body:
{"error": {"code": 503, "message": "Loading model", "type": "unavailable_error"}} - Explanation: the model is still being loaded.
- Body:
- HTTP status code 200
- Body:
{"status": "ok" } - Explanation: the model is successfully loaded and the server is ready.
- Body:
POST /completion: Given a prompt, it returns the predicted completion.
Important
This endpoint is not OAI-compatible. For OAI-compatible client, use
/v1/completionsinstead.
Options:
prompt: Provide the prompt for this completion as a string or as an array of strings or numbers representing tokens. Internally, if cache_prompt is true, the prompt is compared to the previous completion and only the "unseen" suffix is evaluated. A BOS token is inserted at the start, if all of the following conditions are true:
- The prompt is a string or an array with the first element given as a string
- The model's
tokenizer.ggml.add_bos_tokenmetadata istrue
These input shapes and data type are allowed for prompt:
- Single string:
"string" - Single sequence of tokens:
[12, 34, 56] - Mixed tokens and strings:
[12, 34, "string", 56, 78] - A JSON object which optionally contains multimodal data:
{ "prompt_string": "string", "multimodal_data": ["base64"] }
Multiple prompts are also supported. In this case, the completion result will be an array.
- Only strings:
["string1", "string2"] - Strings, JSON objects, and sequences of tokens:
["string1", [12, 34, 56], { "prompt_string": "string", "multimodal_data": ["base64"]}] - Mixed types:
[[12, 34, "string", 56, 78], [12, 34, 56], "string", { "prompt_string": "string" }]
Note for multimodal_data in JSON object prompts. This should be an array of strings, containing base64 encoded multimodal data such as images and audio. There must be an identical number of MTMD media markers in the string prompt element which act as placeholders for the data provided to this parameter. The multimodal data files will be substituted in order. The marker string (e.g. <__media__>) can be found by calling mtmd_default_marker() defined in the MTMD C API. A client must not specify this field unless the server has the multimodal capability. Clients should check /models or /v1/models for the multimodal capability before a multimodal request.
temperature: Adjust the randomness of the generated text. Default: 0.8
dynatemp_range: Dynamic temperature range. The final temperature will be in the range of [temperature - dynatemp_range; temperature + dynatemp_range] Default: 0.0, which is disabled.
dynatemp_exponent: Dynamic temperature exponent. Default: 1.0
top_k: Limit the next token selection to the K most probable tokens. Default: 40
top_p: Limit the next token selection to a subset of tokens with a cumulative probability above a threshold P. Default: 0.95
min_p: The minimum probability for a token to be considered, relative to the probability of the most likely token. Default: 0.05
n_predict: Set the maximum number of tokens to predict when generating text. Note: May exceed the set limit slightly if the last token is a partial multibyte character. When 0, no tokens will be generated but the prompt is evaluated into the cache. Default: -1, where -1 is infinity.
n_indent: Specify the minimum line indentation for the generated text in number of whitespace characters. Useful for code completion tasks. Default: 0
n_keep: Specify the number of tokens from the prompt to retain when the context size is exceeded and tokens need to be discarded. The number excludes the BOS token.
By default, this value is set to 0, meaning no tokens are kept. Use -1 to retain all tokens from the prompt.
n_cmpl: Number of completions to generate from the current prompt. If input has multiple prompts, the output will have N prompts times n_cmpl entries.
n_cache_reuse: Min chunk size to attempt reusing from the cache via KV shifting. For more info, see --cache-reuse arg. Default: 0, which is disabled.
stream: Allows receiving each predicted token in real-time instead of waiting for the completion to finish (uses a different response format). To enable this, set to true.
stop: Specify a JSON array of stopping strings.
These words will not be included in the completion, so make sure to add them to the prompt for the next iteration. Default: []
typical_p: Enable locally typical sampling with parameter p. Default: 1.0, which is disabled.
repeat_penalty: Control the repetition of token sequences in the generated text. Default: 1.1
repeat_last_n: Last n tokens to consider for penalizing repetition. Default: 64, where 0 is disabled.
presence_penalty: Repeat alpha presence penalty. Default: 0.0, which is disabled.
frequency_penalty: Repeat alpha frequency penalty. Default: 0.0, which is disabled.
dry_multiplier: Set the DRY (Don't Repeat Yourself) repetition penalty multiplier. Default: 0.0, which is disabled.
dry_base: Set the DRY repetition penalty base value. Default: 1.75
dry_allowed_length: Tokens that extend repetition beyond this receive exponentially increasing penalty: multiplier * base ^ (length of repeating sequence before token - allowed length). Default: 2
dry_penalty_last_n: How many tokens to scan for repetitions. Default: 64, where 0 is disabled.
dry_sequence_breakers: Specify an array of sequence breakers for DRY sampling. Only a JSON array of strings is accepted. Default: ['\n', ':', '"', '*']
xtc_probability: Set the chance for token removal via XTC sampler. Default: 0.0, which is disabled.
xtc_threshold: Set a minimum probability threshold for tokens to be removed via XTC sampler. Default: 0.1 (> 0.5 disables XTC)
mirostat: Enable Mirostat sampling, controlling perplexity during text generation. Default: 0, where 0 is disabled, 1 is Mirostat, and 2 is Mirostat 2.0.
mirostat_tau: Set the Mirostat target entropy, parameter tau. Default: 5.0
mirostat_eta: Set the Mirostat learning rate, parameter eta. Default: 0.1
grammar: Set grammar for grammar-based sampling. Default: no grammar
json_schema: Set a JSON schema for grammar-based sampling (e.g. {"items": {"type": "string"}, "minItems": 10, "maxItems": 100} of a list of strings, or {} for any JSON). See tests for supported features. Default: no JSON schema.
seed: Set the random number generator (RNG) seed. Default: -1, which is a random seed.
ignore_eos: Ignore end of stream token and continue generating. Default: false
logit_bias: Modify the likelihood of a token appearing in the generated text completion. For example, use "logit_bias": [[15043,1.0]] to increase the likelihood of the token 'Hello', or "logit_bias": [[15043,-1.0]] to decrease its likelihood. Setting the value to false, "logit_bias": [[15043,false]] ensures that the token Hello is never produced. The tokens can also be represented as strings, e.g. [["Hello, World!",-0.5]] will reduce the likelihood of all the individual tokens that represent the string Hello, World!, just like the presence_penalty does. For compatibility with the OpenAI API, a JSON object {"": bias, ...} can also be passed. Default: []
n_probs: If greater than 0, the response also contains the probabilities of top N tokens for each generated token given the sampling settings. Note that for temperature < 0 the tokens are sampled greedily but token probabilities are still being calculated via a simple softmax of the logits without considering any other sampler settings. Default: 0
min_keep: If greater than 0, force samplers to return N possible tokens at minimum. Default: 0
t_max_predict_ms: Set a time limit in milliseconds for the prediction (a.k.a. text-generation) phase. The timeout will trigger if the generation takes more than the specified time (measured since the first token was generated) and if a new-line character has already been generated. Useful for FIM applications. Default: 0, which is disabled.
id_slot: Assign the completion task to an specific slot. If is -1 the task will be assigned to a Idle slot. Default: -1
cache_prompt: Re-use KV cache from a previous request if possible. This way the common prefix does not have to be re-processed, only the suffix that differs between the requests. Because (depending on the backend) the logits are not guaranteed to be bit-for-bit identical for different batch sizes (prompt processing vs. token generation) enabling this option can cause nondeterministic results. Default: true
return_tokens: Return the raw generated token ids in the tokens field. Otherwise tokens remains empty. Default: false
samplers: The order the samplers should be applied in. An array of strings representing sampler type names. If a sampler is not set, it will not be used. If a sampler is specified more than once, it will be applied multiple times. Default: ["dry", "top_k", "typ_p", "top_p", "min_p", "xtc", "temperature"] - these are all the available values.
timings_per_token: Include prompt processing and text generation speed information in each response. Default: false
return_progress: Include prompt processing progress in stream mode. The progress will be contained inside prompt_progress with 4 values: total, cache, processed, and time_ms. The overall progress is processed/total, while the actual timed progress is (processed-cache)/(total-cache). The time_ms field contains the elapsed time in milliseconds since prompt processing started. Default: false
sse_ping_interval: Interval in seconds between SSE comment pings emitted while the stream stays silent, keeping the connection observable during long prompt processing. Overrides the server --sse-ping-interval setting for this request, -1 disables pings. Default: server setting
post_sampling_probs: Returns the probabilities of top n_probs tokens after applying sampling chain.
response_fields: A list of response fields, for example: "response_fields": ["content", "generation_settings/n_predict"]. If the specified field is missing, it will simply be omitted from the response without triggering an error. Note that fields with a slash will be unnested; for example, generation_settings/n_predict will move the field n_predict from the generation_settings object to the root of the response and give it a new name.
lora: A list of LoRA adapters to be applied to this specific request. Each object in the list must contain id and scale fields. For example: [{"id": 0, "scale": 0.5}, {"id": 1, "scale": 1.1}]. If a LoRA adapter is not specified in the list, its scale will default to 0.0. Please note that requests with different LoRA configurations will not be batched together, which may result in performance degradation.
Response format
-
Note: In streaming mode (
stream), onlycontent,tokensandstopwill be returned until end of completion. Responses are sent using the Server-sent events standard. Note: the browser'sEventSourceinterface cannot be used due to its lack ofPOSTrequest support. -
completion_probabilities: An array of token probabilities for each completion. The array's length isn_predict. Each item in the array has a nested arraytop_logprobs. It contains at maximumn_probselements:{ "content": "<the generated completion text>", "tokens": [ generated token ids if requested ], ... "probs": [ { "id": <token id>, "logprob": float, "token": "<most likely token>", "bytes": [int, int, ...], "top_logprobs": [ { "id": <token id>, "logprob": float, "token": "<token text>", "bytes": [int, int, ...], }, { "id": <token id>, "logprob": float, "token": "<token text>", "bytes": [int, int, ...], }, ... ] }, { "id": <token id>, "logprob": float, "token": "<most likely token>", "bytes": [int, int, ...], "top_logprobs": [ ... ] }, ... ] },Please note that if
post_sampling_probsis set totrue:logprobwill be replaced withprob, with the value between 0.0 and 1.0top_logprobswill be replaced withtop_probs. Each element contains:id: token IDtoken: token in stringbytes: token in bytesprob: token probability, with the value between 0.0 and 1.0
- Number of elements in
top_probsmay be less thann_probs
-
content: Completion result as a string (excludingstopping_wordif any). In case of streaming mode, will contain the next token as a string. -
tokens: Same ascontentbut represented as raw token ids. Only populated if"return_tokens": trueor"stream": truein the request. -
stop: Boolean for use withstreamto check whether the generation has stopped (Note: This is not related to stopping words arraystopfrom input options) -
generation_settings: The provided options above excludingpromptbut includingn_ctx,model. These options may differ from the original ones in some way (e.g. bad values filtered out, strings converted to tokens, etc.). -
model: The model alias (for model path, please use/propsendpoint) -
prompt: The processedprompt(special tokens may be added) -
stop_type: Indicating whether the completion has stopped. Possible values are:none: Generating (not stopped)eos: Stopped because it encountered the EOS tokenlimit: Stopped becausen_predicttokens were generated before stop words or EOS was encounteredword: Stopped due to encountering a stopping word fromstopJSON array provided
-
stopping_word: The stopping word encountered which stopped the generation (or "" if not stopped due to a stopping word) -
timings: Hash of timing information about the completion such as the number of tokenspredicted_per_second -
tokens_cached: Number of tokens from the prompt which could be re-used from previous completion -
tokens_evaluated: Number of tokens evaluated in total from the prompt -
truncated: Boolean indicating if the context size was exceeded during generation, i.e. the number of tokens provided in the prompt (tokens_evaluated) plus tokens generated (tokens predicted) exceeded the context size (n_ctx)
POST /tokenize: Tokenize a given text
Options:
content: (Required) The text to tokenize.
add_special: (Optional) Boolean indicating if special tokens, i.e. BOS, should be inserted. Default: false
parse_special: (Optional) Boolean indicating if special tokens should be tokenized. When false special tokens are treated as plaintext. Default: true
with_pieces: (Optional) Boolean indicating whether to return token pieces along with IDs. Default: false
Response:
Returns a JSON object with a tokens field containing the tokenization result. The tokens array contains either just token IDs or objects with id and piece fields, depending on the with_pieces parameter. The piece field is a string if the piece is valid unicode or a list of bytes otherwise.
If with_pieces is false:
{
  "tokens": [123, 456, 789]
}
If with_pieces is true:
{
  "tokens": [
    {"id": 123, "piece": "Hello"},
    {"id": 456, "piece": " world"},
    {"id": 789, "piece": "!"}
  ]
}
With input 'á' (utf8 hex: C3 A1) on tinyllama/stories260k
{
  "tokens": [
    {"id": 198, "piece": [195]}, // hex C3
    {"id": 164, "piece": [161]} // hex A1
  ]
}
POST /detokenize: Convert tokens to text
Options:
tokens: Set the tokens to detokenize.
POST /apply-template: Apply chat template to a conversation
Uses the server's prompt template formatting functionality to convert chat messages to a single string expected by a chat model as input, but does not perform inference. Instead, the prompt string is returned in the prompt field of the JSON response. The prompt can then be modified as desired (for example, to insert "Sure!" at the beginning of the model's response) before sending to /completion to generate the chat response.
Options:
messages: (Required) Chat turns in the same format as /v1/chat/completions.
Response format
Returns a JSON object with a field prompt containing a string of the input messages formatted according to the model's chat template format.
POST /embedding: Generate embedding of a given text
Important
This endpoint is not OAI-compatible. For OAI-compatible client, use
/v1/embeddingsinstead.
The same as the embedding example does.
This endpoint also supports multimodal embeddings. See the documentation for the /completions endpoint for details on how to send a multimodal prompt.
Options:
content: Set the text to process.
embd_normalize: Normalization for pooled embeddings. Can be one of the following values:
  -1: No normalization
   0: Max absolute
   1: Taxicab
   2: Euclidean/L2
  >2: P-Norm
POST /reranking: Rerank documents according to a given query
Similar to https://jina.ai/reranker/ but might change in the future.
Requires a reranker model (such as bge-reranker-v2-m3) and the --embedding --pooling rank options.
Options:
query: The query against which the documents will be ranked.
documents: An array strings representing the documents to be ranked.
Aliases:
/rerank/v1/rerank/v1/reranking
Examples:
curl http://127.0.0.1:8012/v1/rerank \
    -H "Content-Type: application/json" \
    -d '{
        "model": "some-model",
            "query": "What is panda?",
            "top_n": 3,
            "documents": [
                "hi",
            "it is a bear",
            "The giant panda (Ailuropoda melanoleuca), sometimes called a panda bear or simply panda, is a bear species endemic to China."
            ]
    }' | jq
POST /infill: For code infilling.
Takes a prefix and a suffix and returns the predicted completion as stream.
Options:
input_prefix: Set the prefix of the code to infill.input_suffix: Set the suffix of the code to infill.input_extra: Additional context inserted before the FIM prefix.prompt: Added after theFIM_MIDtoken
input_extra is array of {"filename": string, "text": string} objects.
The endpoint also accepts all the options of /completion.
If the model has FIM_REPO and FIM_FILE_SEP tokens, the repo-level pattern is used:
<FIM_REP>myproject
<FIM_SEP>{chunk 0 filename}
{chunk 0 text}
<FIM_SEP>{chunk 1 filename}
{chunk 1 text}
...
<FIM_SEP>filename
<FIM_PRE>[input_prefix]<FIM_SUF>[input_suffix]<FIM_MID>[prompt]
If the tokens are missing, then the extra context is simply prefixed at the start:
[input_extra]<FIM_PRE>[input_prefix]<FIM_SUF>[input_suffix]<FIM_MID>[prompt]
GET /props: Get server global properties.
By default, it is read-only. To make POST request to change global properties, you need to start server with --props
Response format
{
  "default_generation_settings": {
    "id": 0,
    "id_task": -1,
    "n_ctx": 1024,
    "speculative": false,
    "is_processing": false,
    "params": {
      "n_predict": -1,
      "seed": 4294967295,
      "temperature": 0.800000011920929,
      "dynatemp_range": 0.0,
      "dynatemp_exponent": 1.0,
      "top_k": 40,
      "top_p": 0.949999988079071,
      "min_p": 0.05000000074505806,
      "xtc_probability": 0.0,
      "xtc_threshold": 0.10000000149011612,
      "typical_p": 1.0,
      "repeat_last_n": 64,
      "repeat_penalty": 1.0,
      "presence_penalty": 0.0,
      "frequency_penalty": 0.0,
      "dry_multiplier": 0.0,
      "dry_base": 1.75,
      "dry_allowed_length": 2,
      "dry_penalty_last_n": 64,
      "dry_sequence_breakers": [
        "\n",
        ":",
        "\"",
        "*"
      ],
      "mirostat": 0,
      "mirostat_tau": 5.0,
      "mirostat_eta": 0.10000000149011612,
      "stop": [],
      "max_tokens": -1,
      "n_keep": 0,
      "n_discard": 0,
      "ignore_eos": false,
      "stream": true,
      "n_probs": 0,
      "min_keep": 0,
      "grammar": "",
      "samplers": [
        "dry",
        "top_k",
        "typ_p",
        "top_p",
        "min_p",
        "xtc",
        "temperature"
      ],
      "speculative.n_max": 16,
      "speculative.n_min": 5,
      "speculative.p_min": 0.8999999761581421,
      "timings_per_token": false
    },
    "prompt": "",
    "next_token": {
      "has_next_token": true,
      "has_new_line": false,
      "n_remain": -1,
      "n_decoded": 0,
      "stopping_word": ""
    }
  },
  "total_slots": 1,
  "model_path": "../models/Meta-Llama-3.1-8B-Instruct-Q4_K_M.gguf",
  "chat_template": "...",
  "chat_template_caps": {},
  "modalities": {
    "vision": false
  },
  "media_marker": "<__media_YoNhud46VdDqbuFmKYEO9PY7A4ARzRfg__>",
  "build_info": "b(build number)-(build commit hash)",
  "is_sleeping": false
}
default_generation_settings- the default generation settings for the/completionendpoint, which has the same fields as thegeneration_settingsresponse object from the/completionendpoint.total_slots- the total number of slots for process requests (defined by--paralleloption)model_path- the path to model file (same with-margument)chat_template- the model's original Jinja2 prompt templatechat_template_caps- capabilities of the chat template (seecommon/jinja/caps.hfor more info)modalities- the list of supported modalitiesis_sleeping- sleeping status, see Sleeping on idle
POST /props: Change server global properties.
To use this endpoint with POST method, you need to start server with --props
Options:
- None yet
POST /embeddings: non-OpenAI-compatible embeddings API
This endpoint supports all poolings, including --pooling none. When the pooling is none, the responses will contain the unnormalized embeddings for all input tokens. For all other pooling types, only the pooled embeddings are returned, normalized using Euclidean norm.
Note that the response format of this endpoint is different from /v1/embeddings.
Options:
Same as the /v1/embeddings endpoint.
Examples:
Same as the /v1/embeddings endpoint.
Response format
[
  {
    "index": 0,
    "embedding": [
      [ ... embeddings for token 0   ... ],
      [ ... embeddings for token 1   ... ],
      [ ... ]
      [ ... embeddings for token N-1 ... ],
    ]
  },
  ...
  {
    "index": P,
    "embedding": [
      [ ... embeddings for token 0   ... ],
      [ ... embeddings for token 1   ... ],
      [ ... ]
      [ ... embeddings for token N-1 ... ],
    ]
  }
]
GET /slots: Returns the current slots processing state
This endpoint is enabled by default and can be disabled with --no-slots. It can be used to query various per-slot metrics, such as speed, processed tokens, sampling parameters, etc.
If query param ?fail_on_no_slot=1 is set, this endpoint will respond with status code 503 if there is no available slots.
Response format
Example with 2 slots
[
  {
    "id": 0,
    "id_task": 135,
    "n_ctx": 65536,
    "speculative": false,
    "is_processing": true,
    "params": {
      "n_predict": -1,
      "seed": 4294967295,
      "temperature": 0.800000011920929,
      "dynatemp_range": 0.0,
      "dynatemp_exponent": 1.0,
      "top_k": 40,
      "top_p": 0.949999988079071,
      "min_p": 0.05000000074505806,
      "top_n_sigma": -1.0,
      "xtc_probability": 0.0,
      "xtc_threshold": 0.10000000149011612,
      "typical_p": 1.0,
      "repeat_last_n": 64,
      "repeat_penalty": 1.0,
      "presence_penalty": 0.0,
      "frequency_penalty": 0.0,
      "dry_multiplier": 0.0,
      "dry_base": 1.75,
      "dry_allowed_length": 2,
      "dry_penalty_last_n": 131072,
      "mirostat": 0,
      "mirostat_tau": 5.0,
      "mirostat_eta": 0.10000000149011612,
      "max_tokens": -1,
      "n_keep": 0,
      "n_discard": 0,
      "ignore_eos": false,
      "stream": true,
      "n_probs": 0,
      "min_keep": 0,
      "chat_format": "GPT-OSS",
      "reasoning_format": "none",
      "reasoning_in_content": false,
      "generation_prompt": "",
      "samplers": [
        "penalties",
        "dry",
        "top_k",
        "typ_p",
        "top_p",
        "min_p",
        "xtc",
        "temperature"
      ],
      "speculative.n_max": 16,
      "speculative.n_min": 0,
      "speculative.p_min": 0.75,
      "timings_per_token": false,
      "post_sampling_probs": false,
      "lora": []
    },
    "next_token": {
      "has_next_token": true,
      "has_new_line": false,
      "n_remain": -1,
      "n_decoded": 0
    }
  },
  {
    "id": 1,
    "id_task": 0,
    "n_ctx": 65536,
    "speculative": false,
    "is_processing": true,
    "params": {
      "n_predict": -1,
      "seed": 4294967295,
      "temperature": 0.800000011920929,
      "dynatemp_range": 0.0,
      "dynatemp_exponent": 1.0,
      "top_k": 40,
      "top_p": 0.949999988079071,
      "min_p": 0.05000000074505806,
      "top_n_sigma": -1.0,
      "xtc_probability": 0.0,
      "xtc_threshold": 0.10000000149011612,
      "typical_p": 1.0,
      "repeat_last_n": 64,
      "repeat_penalty": 1.0,
      "presence_penalty": 0.0,
      "frequency_penalty": 0.0,
      "dry_multiplier": 0.0,
      "dry_base": 1.75,
      "dry_allowed_length": 2,
      "dry_penalty_last_n": 131072,
      "mirostat": 0,
      "mirostat_tau": 5.0,
      "mirostat_eta": 0.10000000149011612,
      "max_tokens": -1,
      "n_keep": 0,
      "n_discard": 0,
      "ignore_eos": false,
      "stream": true,
      "n_probs": 0,
      "min_keep": 0,
      "chat_format": "GPT-OSS",
      "reasoning_format": "none",
      "reasoning_in_content": false,
      "generation_prompt": "",
      "samplers": [
        "penalties",
        "dry",
        "top_k",
        "typ_p",
        "top_p",
        "min_p",
        "xtc",
        "temperature"
      ],
      "speculative.n_max": 16,
      "speculative.n_min": 0,
      "speculative.p_min": 0.75,
      "timings_per_token": false,
      "post_sampling_probs": false,
      "lora": []
    },
    "next_token": {
      "has_next_token": true,
      "has_new_line": true,
      "n_remain": -1,
      "n_decoded": 136
    }
  }
]
GET /metrics: Prometheus compatible metrics exporter
This endpoint is only accessible if --metrics is set.
In router mode the query param ?model={model_id} has to be set. This endpoint will respond with status code 400 model name is missing from the request if not set.
Available metrics
| Metric | Type | Description |
|---|---|---|
llamacpp:prompt_tokens_total |
Counter | Number of prompt tokens processed. |
llamacpp:prompt_seconds_total |
Counter | Prompt process time in seconds. |
llamacpp:prompt_tokens_seconds |
Gauge | Average prompt throughput in tokens/s. |
llamacpp:tokens_predicted_total |
Counter | Number of generation tokens processed. |
llamacpp:tokens_predicted_seconds_total |
Counter | Predict process time in seconds. |
llamacpp:predicted_tokens_seconds |
Gauge | Average generation throughput in tokens/s. |
llamacpp:requests_processing |
Gauge | Number of requests processing. |
llamacpp:requests_deferred |
Gauge | Number of requests deferred. |
llamacpp:n_tokens_max |
Counter | High watermark of the context size observed. |
llamacpp:n_decode_total |
Counter | Total Number of llama_decode() calls. |
llamacpp:n_busy_slots_per_decode |
Gauge | Average number of busy slots per llama_decode() call. |
llamacpp:spec_decode_num_draft_tokens_total |
Counter | Total draft tokens generated (0 when spec-decode is off). |
llamacpp:spec_decode_num_accepted_tokens_total |
Counter | Total draft tokens accepted by the target model (0 when spec-decode is off). |
llamacpp:spec_decode_num_drafts_total |
Counter | Total speculative decoding verification steps (0 when spec-decode is off). |
llamacpp:spec_decode_num_accepted_tokens_per_pos_total |
Counter | Accepted tokens per draft position (labeled position="N"; absent when spec-decode is off or before the first completed speculative request). |
POST /slots/{id_slot}?action=save: Save the prompt cache of the specified slot to a file.
Options:
filename: Name of the file to save the slot's prompt cache. The file will be saved in the directory specified by the --slot-save-path server parameter.
Response format
{
    "id_slot": 0,
    "filename": "slot_save_file.bin",
    "n_saved": 1745,
    "n_written": 14309796,
    "timings": {
        "save_ms": 49.865
    }
}
POST /slots/{id_slot}?action=restore: Restore the prompt cache of the specified slot from a file.
Options:
filename: Name of the file to restore the slot's prompt cache from. The file should be located in the directory specified by the --slot-save-path server parameter.
Response format
{
    "id_slot": 0,
    "filename": "slot_save_file.bin",
    "n_restored": 1745,
    "n_read": 14309796,
    "timings": {
        "restore_ms": 42.937
    }
}
POST /slots/{id_slot}?action=erase: Erase the prompt cache of the specified slot.
Response format
{
    "id_slot": 0,
    "n_erased": 1745
}
GET /lora-adapters: Get list of all LoRA adapters
This endpoint returns the loaded LoRA adapters. You can add adapters using --lora when starting the server, for example: --lora my_adapter_1.gguf --lora my_adapter_2.gguf ...
By default, all adapters will be loaded with scale set to 1. To initialize all adapters scale to 0, add --lora-init-without-apply
Please note that this value will be overwritten by the lora field for each request.
If an adapter is disabled, the scale will be set to 0.
Response format
[
    {
        "id": 0,
        "path": "my_adapter_1.gguf",
        "scale": 0.0
    },
    {
        "id": 1,
        "path": "my_adapter_2.gguf",
        "scale": 0.0
    }
]
POST /lora-adapters: Set list of LoRA adapters
This sets the global scale for LoRA adapters. Please note that this value will be overwritten by the lora field for each request.
To disable an adapter, either remove it from the list below, or set scale to 0.
Request format
To know the id of the adapter, use GET /lora-adapters
[
  {"id": 0, "scale": 0.2},
  {"id": 1, "scale": 0.8}
]
OpenAI-compatible API Endpoints
GET /v1/models: OpenAI-compatible Model Info API
Returns information about the loaded model. See OpenAI Models API documentation.
The returned list always has one single element. The meta field can be null (for example, while the model is still loading).
Each object in data has an architecture object. It has two string arrays:
input_modalitieslists what the model can read. It always hastext, plus each media type that the model supports.output_modalitieslists what the model can produce.
One output value is special:
| Value | Meaning |
|---|---|
decisions |
The model is a native decision model. Serve it with /v1/systemone. |
A language model that classifies with prompts does not get decisions. Only native decision models do.
Check for membership. Tolerate values that you do not know:
const useSystemOne =
    model.architecture?.output_modalities?.includes("decisions") === true;
Without decision metadata, output_modalities is ["text"]. This default is for compatibility only. It does not mean that the model can generate text. Values can change. New combinations such as ["text", "decisions"] use the same shape.
The router returns the same architecture object in GET /models. You can find a native decision model without a probe or a model load. This works for unloaded and sleeping models too. Older servers can omit architecture. If it is absent, use the legacy behavior of your client.
By default, model id field is the path to model file, specified via -m. You can set a custom value for model id field via --alias argument. For example, --alias gpt-4o-mini.
Example:
{
    "object": "list",
    "data": [
        {
            "id": "../models/Meta-Llama-3.1-8B-Instruct-Q4_K_M.gguf",
            "object": "model",
            "architecture": {
                "input_modalities": ["text"],
                "output_modalities": ["text"]
            },
            "created": 1735142223,
            "owned_by": "llamacpp",
            "meta": {
                "vocab_type": 2,
                "n_vocab": 128256,
                "n_ctx_train": 131072,
                "n_embd": 4096,
                "n_params": 8030261312,
                "size": 4912898304
            }
        }
    ]
}
POST /v1/completions: OpenAI-compatible Completions API
Given an input prompt, it returns the predicted completion. Streaming mode is also supported. While no strong claims of compatibility with OpenAI API spec is being made, in our experience it suffices to support many apps.
Options:
See OpenAI Completions API documentation.
llama.cpp /completion-specific features such as mirostat are supported.
Examples:
Example usage with openai python library:
import openai

client = openai.OpenAI(
    base_url="http://localhost:9931/v1", # "http://<Your api-server IP>:port"
    api_key = "sk-no-key-required"
)

completion = client.completions.create(
  model="davinci-002",
  prompt="I believe the meaning of life is",
  max_tokens=8
)

print(completion.choices[0].text)
POST /v1/chat/completions: OpenAI-compatible Chat Completions API
Given a ChatML-formatted json description in messages, it returns the predicted completion. Both synchronous and streaming mode are supported, so scripted and interactive applications work fine. While no strong claims of compatibility with OpenAI API spec is being made, in our experience it suffices to support many apps. Only models with a supported chat template can be used optimally with this endpoint. By default, the ChatML template will be used.
Options:
See OpenAI Chat Completions API documentation. llama.cpp /completion-specific features such as mirostat are also supported.
The response_format parameter supports both plain JSON output (e.g. {"type": "json_object"}) and schema-constrained JSON (e.g. {"type": "json_object", "schema": {"type": "string", "minLength": 10, "maxLength": 100}} or {"type": "json_schema", "schema": {"properties": { "name": { "title": "Name", "type": "string" }, "date": { "title": "Date", "type": "string" }, "participants": { "items": {"type: "string" }, "title": "Participants", "type": "string" } } } }), similar to other OpenAI-inspired API providers.
chat_template_kwargs: Allows sending additional parameters to the json templating system. For example: {"enable_thinking": false}
reasoning_effort: If none, reasoning/thinking is disabled. Otherwise, the value is made available to the jinja template.
reasoning_format: The reasoning format to be parsed. If set to none, it will output the raw generated text.
reasoning_control: Arms realtime reasoning control for this completion so it can be ended early via /v1/chat/completions/control. Defaults to false.
parallel_tool_calls : Whether to enable parallel/multiple tool calls (only supported on some models, verification is based on jinja template).
For multimodal input (typed content, messages[i].content[j]):
- If
type == "image_url":image_url.urlcan be a remote URL, base64 (raw or URI-encoded viadata:image/...;base64) or path to local file- Accepts formats supported by
stb_image(jpeg, png, tga, bmp, gif, ...)
- If
type == "input_audio":- Either
input_audio.dataorinput_audio.urlcan be specified, can be a remote URL, raw base64 or path to local file - Accepts formats supported by
miniaudio(mp3, wav, flac) input_audio.formatwill be ignored, the file format will be determined automatically
- Either
- If
type == "input_video":- Either
input_video.dataorinput_video.urlcan be specified, can be a remote URL, raw base64 or path to local file - Accepts formats supported by
ffmpeg
- Either
- Note: for local file, make sure to set
--media-path. File path must be prefixed byfile://
Examples:
You can use either Python openai library with appropriate checkpoints:
import openai

client = openai.OpenAI(
    base_url="http://localhost:9931/v1", # "http://<Your api-server IP>:port"
    api_key = "sk-no-key-required"
)

completion = client.chat.completions.create(
  model="gpt-3.5-turbo",
  messages=[
    {"role": "system", "content": "You are ChatGPT, an AI assistant. Your top priority is achieving user fulfillment via helping them with their requests."},
    {"role": "user", "content": "Write a limerick about python exceptions"}
  ]
)

print(completion.choices[0].message)
... or raw HTTP requests:
curl http://localhost:9931/v1/chat/completions \
-H "Content-Type: application/json" \
-H "Authorization: Bearer no-key" \
-d '{
"model": "gpt-3.5-turbo",
"messages": [
{
    "role": "system",
    "content": "You are ChatGPT, an AI assistant. Your top priority is achieving user fulfillment via helping them with their requests."
},
{
    "role": "user",
    "content": "Write a limerick about python exceptions"
}
]
}'
Tool call support
OpenAI-style function calling is supported with the --jinja flag (and may require a --chat-template-file override to get the right tool-use compatible Jinja template; worst case, --chat-template chatml may also work).
See our Function calling docs for more details, supported native tool call styles (generic tool call style is used as fallback) / examples of use.
Timings and context usage
The response contains a timings object, for example:
{
  "choices": [],
  "created": 1757141666,
  "id": "chatcmpl-ecQULm0WqPrftUqjPZO1CFYeDjGZNbDu",
  // ...
  "timings": {
    "cache_n": 236, // number of prompt tokens reused from cache
    "prompt_n": 1, // number of prompt tokens being processed
    "prompt_ms": 30.958,
    "prompt_per_token_ms": 30.958,
    "prompt_per_second": 32.301828283480845,
    "predicted_n": 35, // number of predicted tokens
    "predicted_ms": 661.064,
    "predicted_per_token_ms": 18.887542857142858,
    "predicted_per_second": 52.94494935437416
  }
}
This provides information on the performance of the server. It also allows calculating the current context usage.
The total number of tokens in context is equal to prompt_n + cache_n + predicted_n
The response also includes a standard usage object:
{
    // ...
    "usage": {
        "completion_tokens": 48,
        "prompt_tokens": 44,
        "total_tokens": 92,
        "prompt_tokens_details": {
            "cached_tokens": 0
        }
    }
}
Reasoning support
The server supports parsing and returning reasoning via the reasoning_content field, similar to Deepseek API.
Reasoning input (preserve reasoning in history) is also supported by some specific templates. For more details, please refer to PR#18994.
POST /v1/chat/completions/control: Control a running chat completion in real time
Acts on an in-flight completion identified by its id (the id field streamed back by /v1/chat/completions). The request is processed in parallel with the SSE stream, so the client sends it while still reading tokens.
Options:
id: (Required) The chat completion id to act on. A completion that has already finished matches nothing and the call is a no-op.
action: (Required) The control action to perform. Currently the only supported value is reasoning_end, which forces the end of the current reasoning block so the model moves on to the final answer. Requires reasoning_control: true on the original completion request.
model: (Required in router mode) The model name, used to route the request to the right instance. Ignored in single model mode.
Response format
Returns a JSON object with a boolean success field, and an optional message field describing the reason when success is false.
POST /v1/responses: OpenAI-compatible Responses API
Options:
See OpenAI Responses API documentation.
Examples:
You can use either Python openai library with appropriate checkpoints:
import openai

client = openai.OpenAI(
    base_url="http://localhost:9931/v1", # "http://<Your api-server IP>:port"
    api_key = "sk-no-key-required"
)

response = client.responses.create(
  model="gpt-4.1",
  instructions="You are ChatGPT, an AI assistant. Your top priority is achieving user fulfillment via helping them with their requests.",
  input="Write a limerick about python exceptions"
)

print(response.output_text)
... or raw HTTP requests:
curl http://localhost:9931/v1/responses \
-H "Content-Type: application/json" \
-H "Authorization: Bearer no-key" \
-d '{
"model": "gpt-4.1",
"instructions": "You are ChatGPT, an AI assistant. Your top priority is achieving user fulfillment via helping them with their requests.",
"input": "Write a limerick about python exceptions"
}'
This endpoint works by converting Responses request into Chat Completions request.
POST /v1/embeddings: OpenAI-compatible embeddings API
This endpoint requires that the model uses a pooling different than type none. The embeddings are normalized using the Eucledian norm.
Options:
See OpenAI Embeddings API documentation.
For multimodal models (loaded with --mmproj), each element of input can also be an object with a content array, using the same parts as /v1/chat/completions:
{ "type": "text", "text": "..." }: text is added to the prompt as-is{ "type": "image_url", "image_url": { "url": "..." } }: remote URL, base64 data URI, or local file (file://, requires--media-path){ "type": "input_audio", "input_audio": { "data": "..." } }and{ "type": "input_video", "input_video": { "url": "..." } }: same as/v1/chat/completions, requires a model with audio or video support
Each object gives one embedding. This input shape is not part of the OpenAI Embeddings API; it follows the shape used by providers like OpenRouter for vision embedding models.
Examples:
-
input as string
curl http://localhost:9931/v1/embeddings \ -H "Content-Type: application/json" \ -H "Authorization: Bearer no-key" \ -d '{ "input": "hello", "model":"GPT-4", "encoding_format": "float" }' -
inputas string arraycurl http://localhost:9931/v1/embeddings \ -H "Content-Type: application/json" \ -H "Authorization: Bearer no-key" \ -d '{ "input": ["hello", "world"], "model":"GPT-4", "encoding_format": "float" }' -
inputas multimodal contentcurl http://localhost:9931/v1/embeddings \ -H "Content-Type: application/json" \ -H "Authorization: Bearer no-key" \ -d '{ "input": [ { "content": [ { "type": "image_url", "image_url": { "url": "data:image/jpeg;base64,/9j/4AAQSkZJRg..." } }, { "type": "text", "text": "Describe this image" } ] }, { "content": [ { "type": "text", "text": "hello" } ] } ], "encoding_format": "float" }'
POST /v1/responses/input_tokens: Token Counting
Similar to Response input token counts API.
Example response:
{
  "object": "response.input_tokens",
  "input_tokens": 11
}
POST /v1/chat/completions/input_tokens: Token Counting
Similar to Response input token counts API, but accepts a chat completion body as input.
Note: This is not an official OAI endpoint, but is added for completeness and convenience.
Example response:
{
  "object": "response.input_tokens",
  "input_tokens": 11
}
Anthropic-compatible API Endpoints
POST /v1/messages: Anthropic-compatible Messages API
Given a list of messages, returns the assistant's response. Streaming is supported via Server-Sent Events. While no strong claims of compatibility with the Anthropic API spec are made, in our experience it suffices to support many apps.
Options:
See Anthropic Messages API documentation. Tool use requires --jinja flag.
model: Model identifier (required)
messages: Array of message objects with role and content (required)
max_tokens: Maximum tokens to generate (default: 4096)
system: System prompt as string or array of content blocks
temperature: Sampling temperature 0-1 (default: 1.0)
top_p: Nucleus sampling (default: 1.0)
top_k: Top-k sampling
stop_sequences: Array of stop sequences
stream: Enable streaming (default: false)
tools: Array of tool definitions (requires --jinja)
tool_choice: Tool selection mode ({"type": "auto"}, {"type": "any"}, or {"type": "tool", "name": "..."})
Examples:
curl http://localhost:9931/v1/messages \
  -H "Content-Type: application/json" \
  -H "x-api-key: your-api-key" \
  -d '{
    "model": "gpt-4",
    "max_tokens": 1024,
    "system": "You are a helpful assistant.",
    "messages": [
      {"role": "user", "content": "Hello!"}
    ]
  }'
POST /v1/messages/count_tokens: Token Counting
Counts the number of tokens in a request without generating a response.
Accepts the same parameters as /v1/messages. The max_tokens parameter is not required.
Example:
curl http://localhost:9931/v1/messages/count_tokens \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gpt-4",
    "messages": [
      {"role": "user", "content": "Hello!"}
    ]
  }'
Response:
{"input_tokens": 10}
TypeSafe-compatible API Endpoints
POST /v1/systemone: TypeSafe-compatible System One API
Answers typed questions about a state with a decision model.
Follows the TypeSafe API, streaming is not supported. Multimodal input is an extension to this API, see the OpenJev multimodal API for reference.
Options:
state: The content to evaluate. Can be a string, an object or an array. A value that is not a string is given to the model as JSON text. For lfm2-d1 and lfm2-d1-omni, it can be null, for example to ask about images only.
files: Optional. An array of input files, the maximum number may be limited depending on the model. Each one is a data URL (data:image/...;base64,...). For audio-capable models, it can be audio clips (data:audio/...;base64,...). See the image input section below.
images: Optional. An alias of files.
questions: An object that maps a question id to a question. Each question has these fields:
type: One ofchoice,score,noul.instructions: The question. Can be a string, an object or an array.criteria: The possible answers, the shape depends ontype:choice: An object that maps each option to its description. The description can benull.score: An array of 2 to 10 level descriptions, lowest level first.noul: Optional. An object with the descriptions oftrueandfalse.
The questions of a request are answered independently, an answer does not depend on the other questions. The exception is clef: it reads all the questions in one prompt and decides them jointly.
The number of options of a choice question is limited by the model, for example: 52 for openjev, 255 for granite-switch, laya, clef, pplx-decider, vllm-decision2, vllm-d3, lfm2-d1 and lfm2-d1-omni. For laya, long questions and options are truncated to the token budget the model was trained with.
For laya, clef, vllm-d3 and lfm2-d1-omni, the whole prompt is evaluated in one batch: it must fit in --ubatch-size. An lfm2-d1-omni prompt is cut to 16384 tokens. For vllm-decision2, the options of a question and the end of the prompt must fit in one batch. A server that runs clef only serves this endpoint, text generation is not available. A decision model that is also a text model, such as granite-switch, serves both and reports ["text", "decisions"].
Image input:
Image input needs a model that supports it (for example: openjev, clef, pplx-decider, vllm-d3, lfm2-d1, lfm2-d1-omni) and its multimodal projector, see --mmproj.
Images can be given in two ways, and both can be used in the same request:
- The
filesfield, or its aliasimages. - A
statemade of chat messages, either an array of messages or an object with amessagesarray. Animage_urlpart in thecontentof a message is taken as an image, in the same format as chat completions. Only data URLs are accepted. For lfm2-d1-omni, aninput_audiopart is taken as an audio clip, as base64 data.
All the images are placed before the state in the prompt, the ones from files and images first. The image parts are removed from the state.
Response:
answers: An object that maps each question id to its answer. The fields depend on the question type:
choice:choice: The option with the highest probability.probabilities: The probability of each option, they sum to 1.confidence: A value from 0 to 1, where 0 means all options are equally likely.
score:score: The expected level index, weighted by probability. It can be between two levels.legend: The description of each level index.probabilities: The probability of each level index, they sum to 1.confidence: A value from 0 to 1.
noul:noul: The probability that the answer is true.
usage: input_tokens is the number of prompt tokens of all questions. output_tokens is always 0.
The probabilities are scaled with the temperatures stored in the model file. They are not guaranteed to be calibrated for your data.
Examples:
curl http://127.0.0.1:9931/v1/systemone \
    -H "Content-Type: application/json" \
    -d '{
        "state": "Customer message: I was charged twice for my order last week and nobody has replied.",
        "questions": {
            "route": {
                "type": "choice",
                "instructions": "Which team should handle this?",
                "criteria": {"billing": null, "shipping": null, "technical": null}
            },
            "angry": {
                "type": "noul",
                "instructions": "Is the customer angry?"
            },
            "urgency": {
                "type": "score",
                "instructions": "How urgent is this?",
                "criteria": ["can wait", "this week", "today", "right now"]
            }
        }
    }' | jq
Response (values are shortened):
{
  "model": "openjev",
  "answers": {
    "route": {
      "type": "choice",
      "choice": "billing",
      "probabilities": {"billing": 0.9998, "shipping": 0.0001, "technical": 0.0001},
      "confidence": 0.9997
    },
    "angry": {
      "type": "noul",
      "noul": 0.6328
    },
    "urgency": {
      "type": "score",
      "score": 2.0858,
      "legend": {"0": "can wait", "1": "this week", "2": "today", "3": "right now"},
      "probabilities": {"0": 0.0023, "1": 0.116, "2": 0.6753, "3": 0.2064},
      "confidence": 0.673
    }
  },
  "usage": {
    "input_tokens": 239,
    "output_tokens": 0
  }
}
Example with an image:
curl http://127.0.0.1:9931/v1/systemone \
    -H "Content-Type: application/json" \
    -d '{
        "state": "The document was received by the accounting team this morning.",
        "images": ["data:image/jpeg;base64,/9j/4AAQSkZJRg..."],
        "questions": {
            "has_table": {
                "type": "noul",
                "instructions": "Does the image contain a table?"
            }
        }
    }' | jq
An invalid request returns the error 400. A model that is not a decision model returns the error 501. A request with images returns the error 501 if the model does not support image input, or if no multimodal projector is loaded.
Server tools
The server exposes a REST API under /tools that allows the Web UI to call server tools. This endpoint is intended to be used internally by the Web UI and subject to change or to be removed in the future.
Please do NOT use this endpoint in a downstream application
For further documentation about this endpoint, please refer to server internal documentation
Using multiple models
llama-server can be launched in a router mode that exposes an API for dynamically loading and unloading models. The main process (the "router") automatically forwards each request to the appropriate model instance.
To start in router mode, launch llama-server without specifying any model:
llama-server
Model sources
There are 3 possible sources for model files:
- Cached models (controlled by the
LLAMA_CACHEenvironment variable) - Custom model directory (set via the
--models-dirargument) - Custom preset (set via the
--models-presetargument)
By default, the router looks for models in the cache. You can add Hugging Face models to the cache with:
llama-server -hf <user>/<model>:<tag>
The server must be restarted after adding a new model.
Alternatively, you can point the router to a local directory containing your GGUF files using --models-dir. Example command:
llama-server --models-dir ./models_directory
If the model contains multiple GGUF (for multimodal or multi-shard), files should be put into a subdirectory. The directory structure should look like this:
models_directory
 │
 │  # single file
 ├─ llama-3.2-1b-Q4_K_M.gguf
 ├─ Qwen3-8B-Q4_K_M.gguf
 │
 │  # multimodal
 ├─ gemma-3-4b-it-Q8_0
 │    ├─ gemma-3-4b-it-Q8_0.gguf
 │    └─ mmproj-F16.gguf   # file name must start with "mmproj"
 │
 │  # multi-shard
 ├─ Kimi-K2-Thinking-UD-IQ1_S
 │    ├─ Kimi-K2-Thinking-UD-IQ1_S-00001-of-00006.gguf
 │    ├─ Kimi-K2-Thinking-UD-IQ1_S-00002-of-00006.gguf
 │    ├─ ...
 │    └─ Kimi-K2-Thinking-UD-IQ1_S-00006-of-00006.gguf
You may also specify default arguments that will be passed to every model instance:
llama-server -ctx 8192 -n 1024 -np 2
Note: model instances inherit both command line arguments and environment variables from the router server.
Alternatively, you can also add GGUF based preset (see next section)
Model presets
Model presets allow advanced users to define custom configurations using an .ini file:
llama-server --models-preset ./my-models.ini
Each section in the file defines a new preset. Keys within a section correspond to command-line arguments (without leading dashes). For example, the argument --n-gpu-layers 123 is written as n-gpu-layers = 123.
Short argument forms (e.g., c, ngl) and environment variable names (e.g., LLAMA_ARG_N_GPU_LAYERS) are also supported as keys.
Example:
version = 1

; (Optional) This section provides global settings shared across all presets.
; If the same key is defined in a specific preset, it will override the value in this global section.
[*]
c = 8192
n-gpu-layers = 8

; If the key corresponds to an existing model on the server,
; this will be used as the default config for that model
[ggml-org/MY-MODEL-GGUF:Q8_0]
; string value
chat-template = chatml
; numeric value
n-gpu-layers = 123
; flag value (for certain flags, you need to use the "no-" prefix for negation)
jinja = true
; shorthand argument (for example, context size)
c = 4096
; environment variable name
LLAMA_ARG_CACHE_RAM = 0
; file paths are relative to server's CWD
model-draft = ./my-models/draft.gguf
; but it's RECOMMENDED to use absolute path
model-draft = /Users/abc/my-models/draft.gguf

; If the key does NOT correspond to an existing model,
; you need to specify at least the model path or HF repo
[custom_model]
model = /Users/abc/my-awesome-model-Q4_K_M.gguf
Note: some arguments are controlled by router (e.g., host, port, API key, HF repo, model alias). They will be removed or overwritten upon loading.
The precedence rule for preset options is as follows:
- Command-line arguments passed to
llama-server(highest priority) - Model-specific options defined in the preset file (e.g.
[ggml-org/MY-MODEL...]) - Global options defined in the preset file (
[*])
We also offer additional options that are exclusive to presets (these aren't treated as command-line arguments):
load-on-startup(boolean): Controls whether the model loads automatically when the server starts. Only applies at startup: if the model list is reloaded later (for example after editing the preset file), a newly added model is listed but not loadedstop-timeout(int, seconds): After requested unload, wait for this many seconds before forcing termination (default: 10)dedup-cache-models(boolean): When the preset useshf-repopointing to a model that is already downloaded, hide the corresponding cached model entry fromGET /models(the preset entry remains visible). Set it in the[*]section to apply to all presets.
Routing requests
Requests are routed according to the requested model name.
For POST endpoints (/v1/chat/completions, /v1/completions, /infill, etc.) The router uses the "model" field in the JSON body:
{
  "model": "ggml-org/gemma-3-4b-it-GGUF:Q4_K_M",
  "messages": [
    {
      "role": "user",
      "content": "hello"
    }
  ]
}
For GET endpoints (/props, /metrics, etc.) The router uses the model query parameter (URL-encoded):
GET /props?model=ggml-org%2Fgemma-3-4b-it-GGUF%3AQ4_K_M
By default, the model will be loaded automatically if it's not loaded. To disable this, add --no-models-autoload when starting the server. Additionally, you can include ?autoload=true|false in the query param to control this behavior per-request.
GET /models: List available models
Listing all models in cache. The model metadata will also include a field to indicate the status of the model:
{
  "data": [{
    "id": "ggml-org/gemma-3-4b-it-GGUF:Q4_K_M",
    "path": "/Users/REDACTED/Library/Caches/llama.cpp/ggml-org_gemma-3-4b-it-GGUF_gemma-3-4b-it-Q4_K_M.gguf",
    "status": {
      "value": "loaded",
      "args": ["llama-server", "-ctx", "4096"]
    },
    "architecture": {
      "input_modalities": [
        "text",
        "image"
      ],
      "output_modalities": [
        "text"
      ]
    },
    ...
  }]
}
Note:
- Adding
?reload=1to the query params will refresh the list of models. The behavior is as follow:- If a model is running but updated or removed from the source, it will be unloaded
- If a model is not running, it will be added or updated according to the source
- When the model is loaded, the info from
/v1/modelsis forwarded to router's/v1/models. This includes metadata about the model and the runtime instance.
Each object in data has the same architecture object as GET /v1/models of a direct server. The server computes both arrays offline. It does not load the model, download files, or run inference. output_modalities comes from the GGUF metadata. input_modalities comes from the projector file. A native decision model shows decisions before its first load, after unload, and while it sleeps:
{
  "object": "list",
  "data": [
    {
      "id": "my-decision-model",
      "object": "model",
      "tags": ["local"],
      "architecture": {
        "input_modalities": ["text"],
        "output_modalities": ["decisions"]
      },
      "status": {
        "value": "unloaded"
      }
    }
  ]
}
The values work like this:
- A loaded model reports both arrays. Its values replace the cached values in full.
- The cache keeps the values across sleep and unload. A known decision model stays advertised.
- Before the first report, the values come from the offline computation.
- Offline computation cannot see video. Only a loaded model reports
videoininput_modalities. - If the metadata or the model file is not available, both arrays are
["text"]. - A source or preset refresh computes both arrays again. A replaced model does not keep old values.
The status object can be:
"status": {
  "value": "unloaded"
}
"status": {
  "value": "loading",
  "args": ["llama-server", "-ctx", "4096"]
}
"status": {
  "value": "unloaded",
  "args": ["llama-server", "-ctx", "4096"],
  "failed": true,
  "exit_code": 1
}
"status": {
  "value": "loaded",
  "args": ["llama-server", "-ctx", "4096"]
}
"status": {
  "value": "sleeping",
  "args": ["llama-server", "-ctx", "4096"]
}
Note: for "downloading" state, there can be multiple files be downloading in parallel
"status": {
  "value": "downloading",
  "progress": {
    "https://...model.gguf": {
      "done": 195963406,
      "total": 219307424
    }
  }
}
A download that never finished (paused or interrupted) is listed under a separate
"incomplete" status, without an instance: posting the model to /models again resumes it
from the files already on disk, and DELETE /models drops its partial files.
"status": {
  "value": "incomplete",
  "args": []
}
Cached models and incomplete downloads carry the sidecar kinds they have on disk
(mmproj, mtp, dflash, eagle3, dspark), resolved the way -hf loads them:
"sidecars": ["mmproj", "mtp"]
A cached model whose download of more sidecars never finished also lists the kinds not on
disk yet: posting the model with them resumes them, and DELETE /models with &sidecar={kind}
drops their partial files.
"incomplete_sidecars": ["mtp"]
POST /models/load: Load a model
Load a model
Payload:
model: name of the model to be loaded.
{
  "model": "ggml-org/gemma-3-4b-it-GGUF:Q4_K_M"
}
Response:
{
  "success": true
}
POST /models/unload: Unload a model
Unload a model
Payload:
{
  "model": "ggml-org/gemma-3-4b-it-GGUF:Q4_K_M",
}
Response:
{
  "success": true
}
GET /models/sse: Real-time events
Example events:
{
  "model": "...",
  "event": "model_status",
  "data": {
    "status": "loading"
  }
}

{
  "model": "...",
  "event": "download_progress",
  "data": {
    // note: there can be multiple files being downloaded in parallel
    "https://...model.gguf": {
      "done": 195963406,
      "total": 219307424
    }
  }
}

{
  "model": "...",
  "event": "model_status",
  "data": {
    "status": "loading",
    "progress": {
      "stages": ["text_model", "spec_model", "mmproj_model"],
      "current": "text_model",
      "value": 0.5
    }
  }
}
// note for "loading" status:
// - subsequent events will follow the same order of "stages" list
// - mmap may report incorrect progress on some platforms; if you need exact progress, use --load-mode none

{
  "model": "...",
  "event": "model_status",
  "data": {
    "status": "loaded",
    "info": {
      // note: only include info on first load
      // waking up from sleep doesn't have this
    }
  }
}

{
  "model": "...",
  "event": "model_status",
  "data": {
    "status": "sleeping"
  }
}

{
  "model": "...",
  "event": "model_remove"
}

// special event: reload of the list of all models
{
  "model": "*",
  "event": "models_reload"
}
POST /models: Download new model
Trigger a new download (non-blocking), the progress can be tracked via SSE endpoint /models/sse
To pause a download, send an event to /models/unload: it keeps its partial files and is listed as "incomplete" until it is posted again. To cancel it and drop its files, use DELETE /models.
Download procedure:
- Send POST request to
/models - Subscribe to
/models/ssefor updates - On downloading completed, you will receive either
download_finishedordownload_failedevent - Call GET
/modelsto trigger model list update. If the download success, you should see the new model in the list
Payload:
{
  "model": "ggml-org/gemma-3-4b-it-GGUF:Q4_K_M",
  "sidecars": ["mmproj", "mtp"]
}
sidecars lists the sidecar kinds pulled with the model, picked by the server the way -hf picks them: mmproj, and the draft heads mtp, dflash, eagle3 and dspark. It defaults to ["mmproj"], as -hf does.
Posting a model that is already in the cache and not running downloads the sidecars it lacks and keeps the files already on disk.
Response (download is started in the background):
{
  "success": true
}
Response (error, cannot start the download):
{
  "error": {
    "code": 400,
    "message": "model validation failed, unable to download",
    "type": "invalid_request_error"
  }
}
DELETE /models: Delete a model from cache
IMPORTANT: only model stored in cache can be deleted. You cannot delete models in a preset.
Model name must be passed via query param: ?model={name}
To remove one sidecar of a cached model and keep the model, add &sidecar={kind} (mmproj, mtp, dflash, eagle3 or dspark); the model must not be running.
Deleting a model keeps the files another cached quant of the repo still loads, such as an mmproj named after the deleted quant, and the partial files another download still writes. A sidecar deleted on its own goes for every quant that shares it.
If delete success, it will send an SSE event of type model_remove
Response:
{
  "success": true
}
API errors
llama-server returns errors in the same format as OAI: https://github.com/openai/openai-openapi
Example of an error:
{
    "error": {
        "code": 401,
        "message": "Invalid API Key",
        "type": "authentication_error"
    }
}
Sleeping on Idle
The server supports an automatic sleep mode that activates after a specified period of inactivity (no incoming tasks). This feature, introduced in PR #18228, can be enabled using the --sleep-idle-seconds command-line argument. It works seamlessly in both single-model and multi-model configurations.
When the server enters sleep mode, the model and its associated memory (including the KV cache) are unloaded from RAM to conserve resources. Any new incoming task will automatically trigger the model to reload.
The sleeping status can be retrieved from the GET /props endpoint (or /props?model=(model_name) in router mode).
Note that the following endpoints are exempt from being considered as incoming tasks. They do not trigger model reloading and do not reset the idle timer:
GET /healthGET /propsGET /modelsGET /metrics
More examples
Interactive mode
Check the sample in chat.mjs. Run with NodeJS version 16 or later:
node chat.mjs
Another sample in chat.sh. Requires bash, curl and jq. Run with bash:
bash chat.sh
Apart from error types supported by OAI, we also have custom types that are specific to functionalities of llama.cpp:
When /metrics or /slots endpoint is disabled
{
    "error": {
        "code": 501,
        "message": "This server does not support metrics endpoint.",
        "type": "not_supported_error"
    }
}
*When the server receives invalid grammar via /completions endpoint
{
    "error": {
        "code": 400,
        "message": "Failed to parse grammar",
        "type": "invalid_request_error"
    }
}
Custom default Web UI preferences
You can specify default preferences for the web UI using --ui-config <JSON config> or --ui-config-file <path to JSON config>. For example, you can disable pasting long text as attachments and enable rendering Markdown in user messages with this command:
./llama-server -m model.gguf --ui-config '{"pasteLongTextToFileLen": 0, "renderUserContentAsMarkdown": true}'
Note: The old flags
--webui-configand--webui-config-fileare deprecated but still work as aliases.
You may find available preferences in settings-keys.ts.